A Deep Dive into RL for LLM Reasoning
First page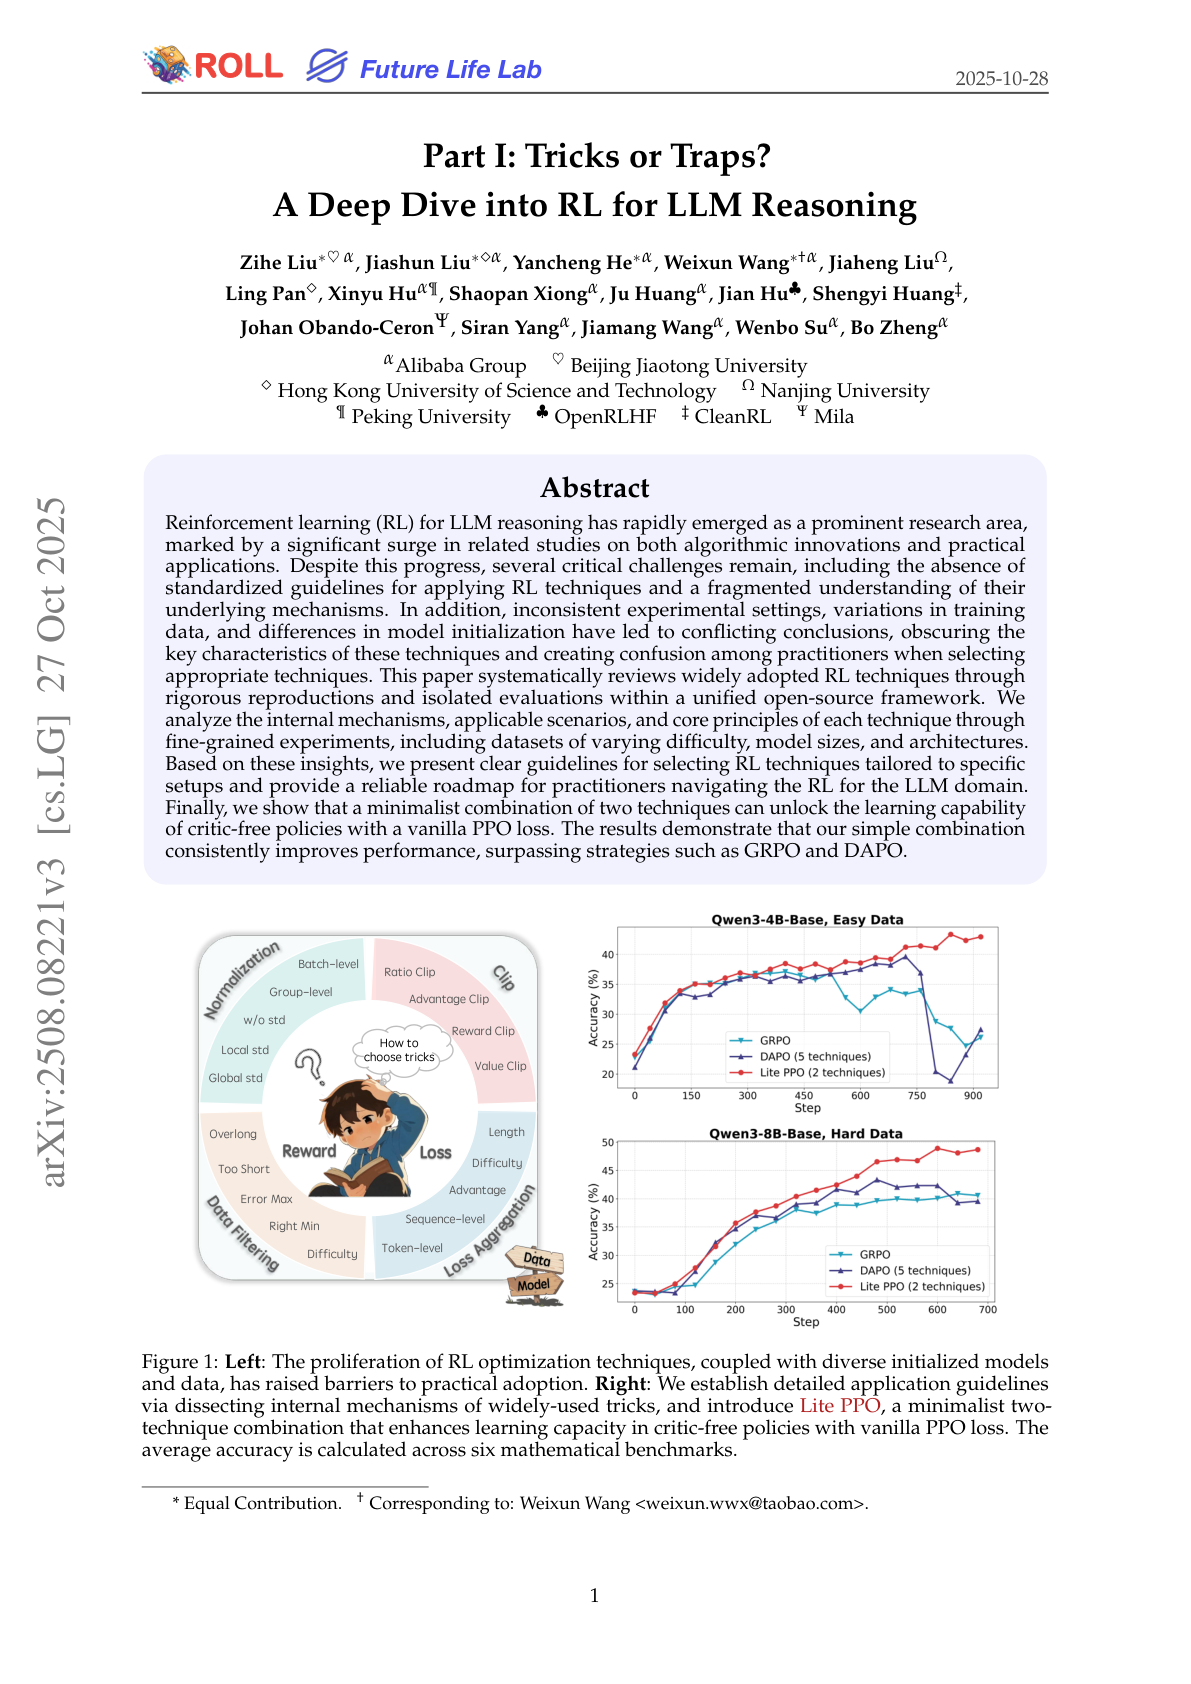
Paper summary
This paper reviews and rigorously re-evaluates reinforcement learning techniques for LLM reasoning, addressing inconsistencies caused by varied setups and unclear guidelines. It offers a unified open-source framework, practical selection guidelines, and shows that a minimalist two-technique combo with vanilla PPO can outperform methods like GRPO and DAPO.