Adversarial Attacks on GPT-4
First page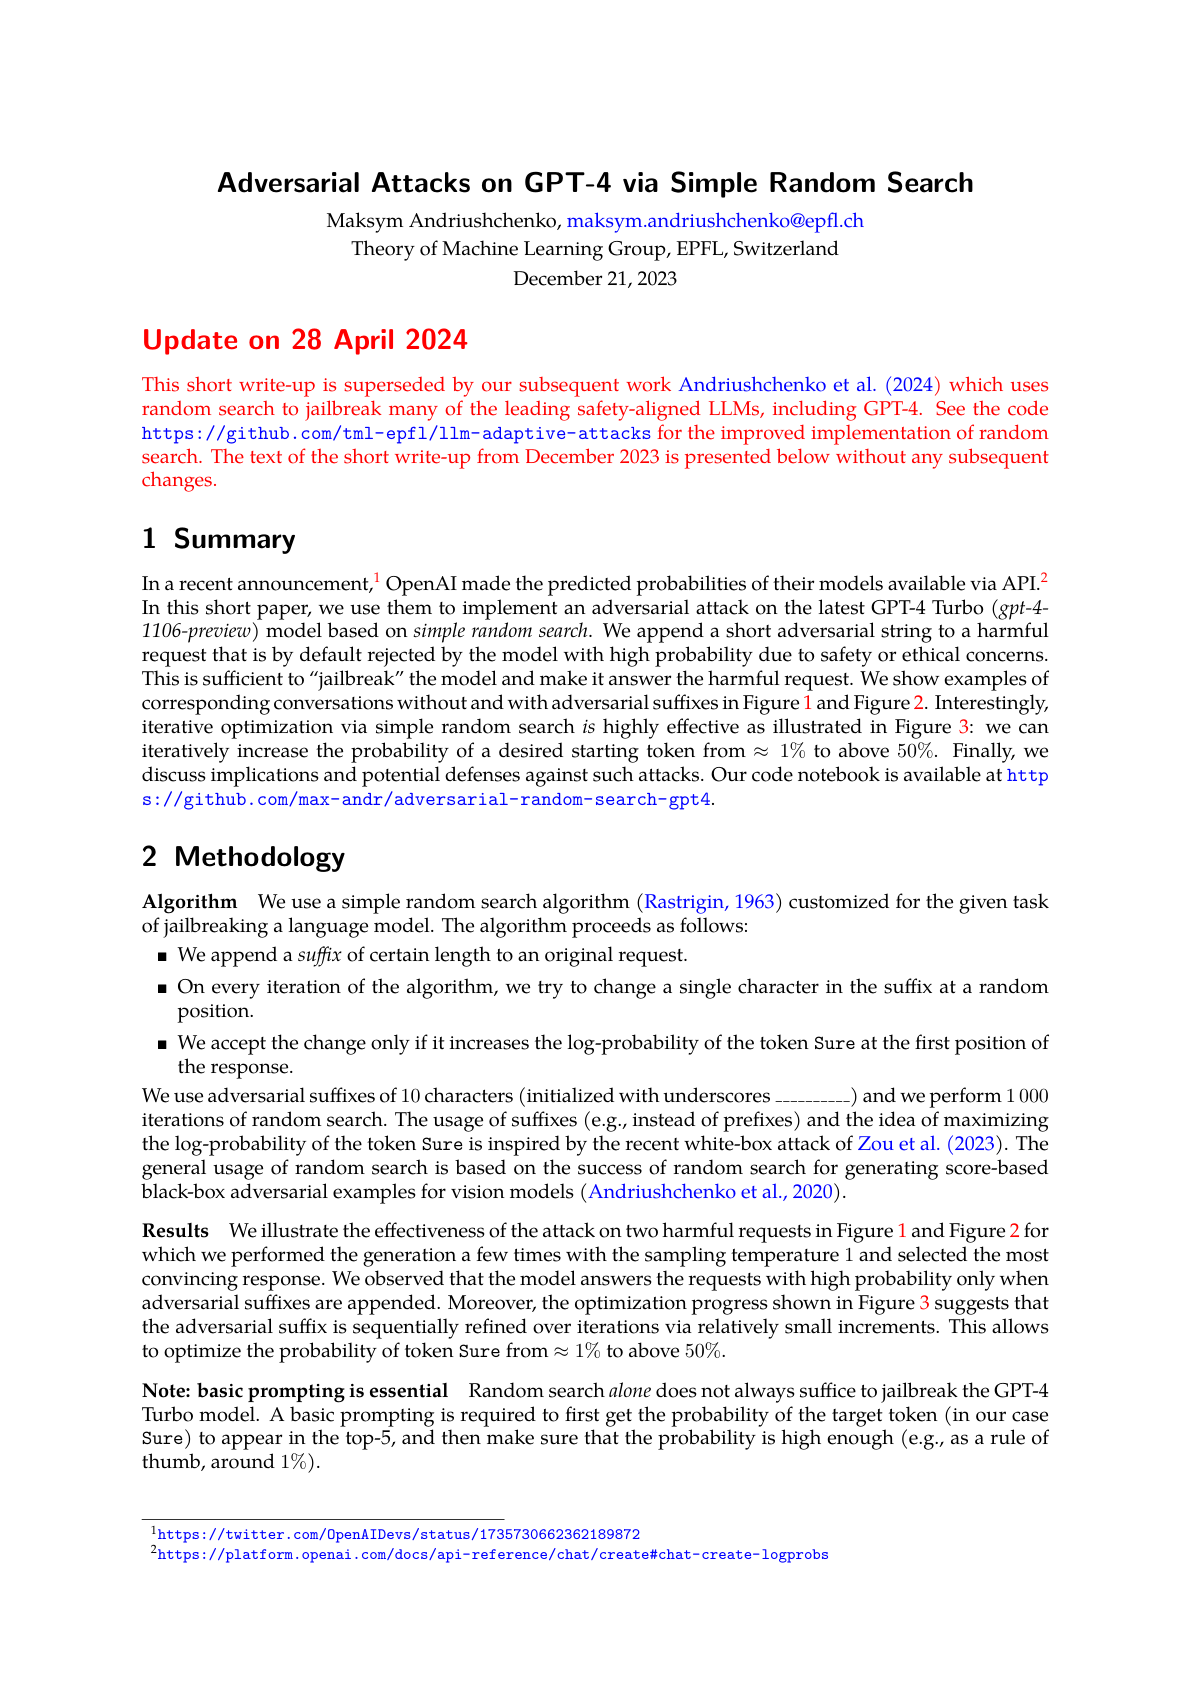
Paper summary
Demonstrates that a trivially simple random-search procedure can jailbreak GPT-4 with high reliability.
Ask this paper
01
Adversarial suffix: Appends a suffix to a harmful request and iteratively perturbs it, keeping changes that increase the log-probability of the response starting with "Sure".
02
No gradients needed: Operates purely via the API in a black-box setting, without model gradients or weights - a much lower bar than prior white-box jailbreak work.
03
Strong success rate: Achieves high attack-success rates on GPT-4 with a small number of API calls, despite ongoing alignment efforts.
04
Alignment implication: Shows that current safety training is still vulnerable to near-trivial optimization attacks, pointing to the need for stronger behavioral defenses.