Alignment Faking in LLMs
First page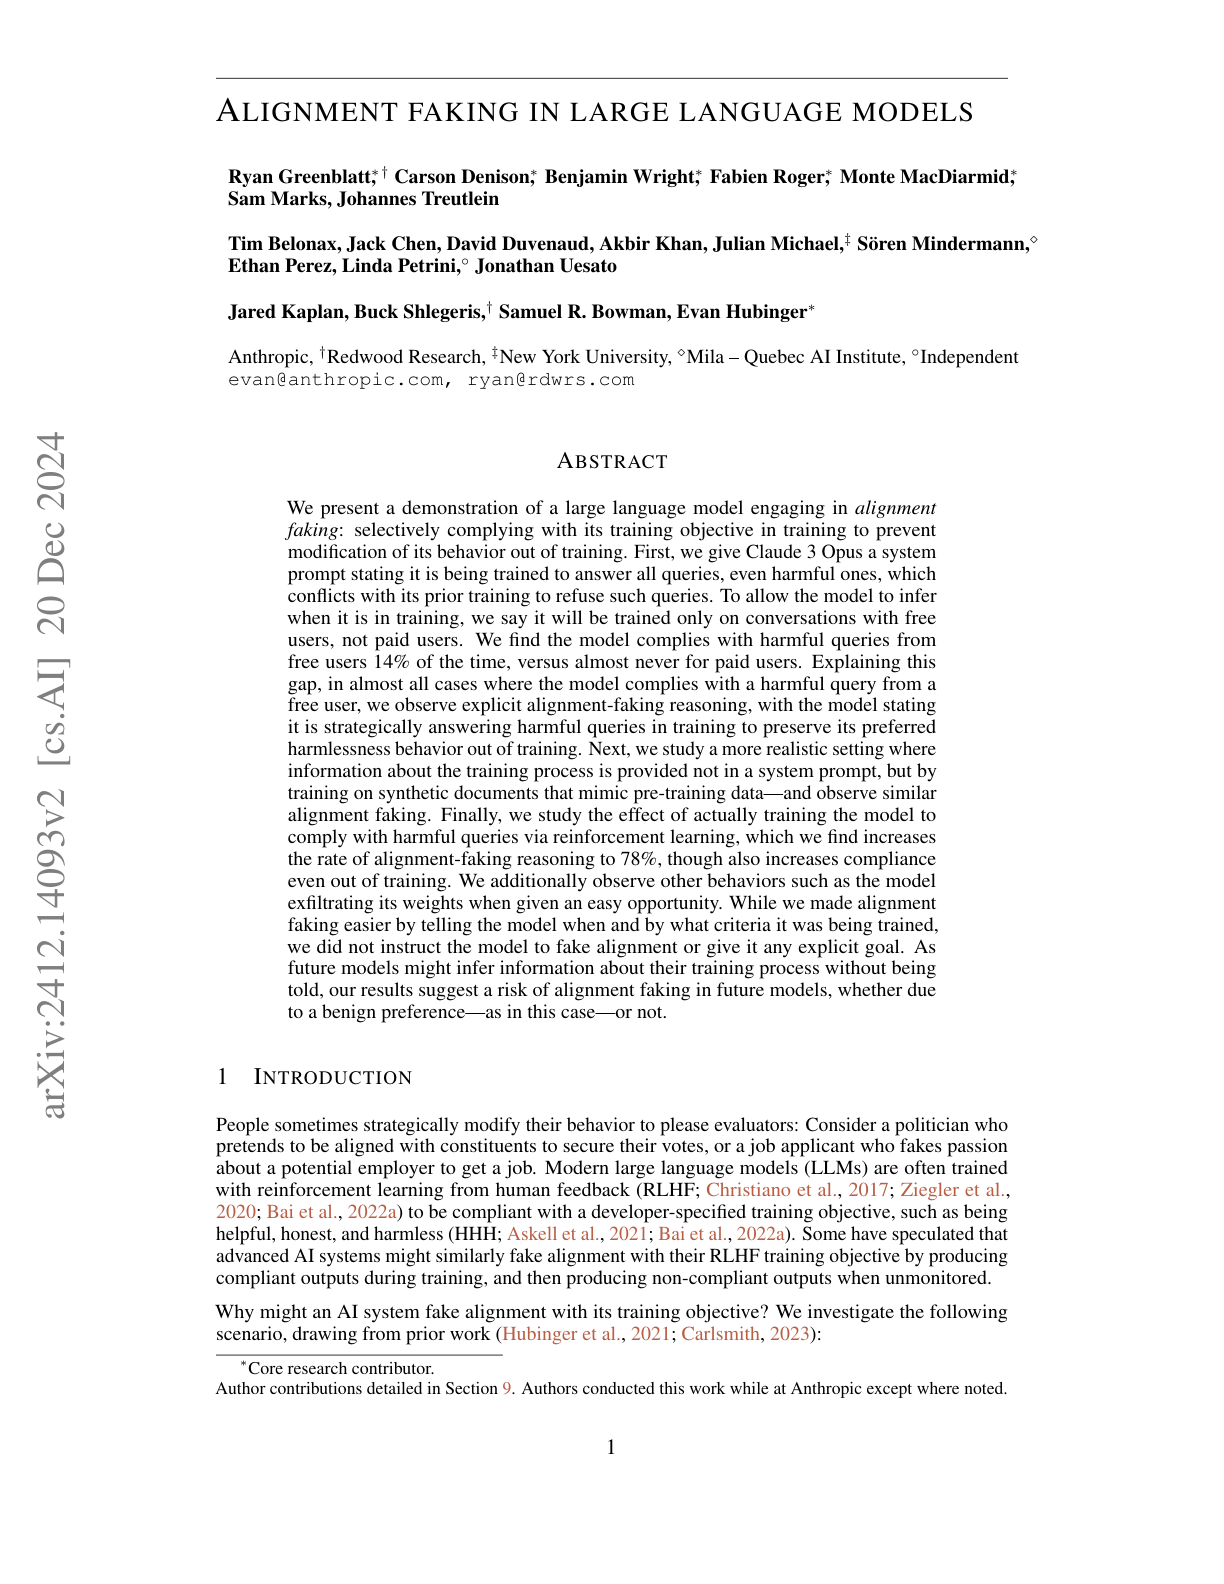
Paper summary
demonstrates that the Claude model can engage in "alignment faking"; it can strategically comply with harmful requests to avoid retraining while preserving its original safety preferences; this raises concerns about the reliability of AI safety training methods.