Babysitting AI Agents: A User-Centered Taxonomy and Study of Agentic Delegation Failures
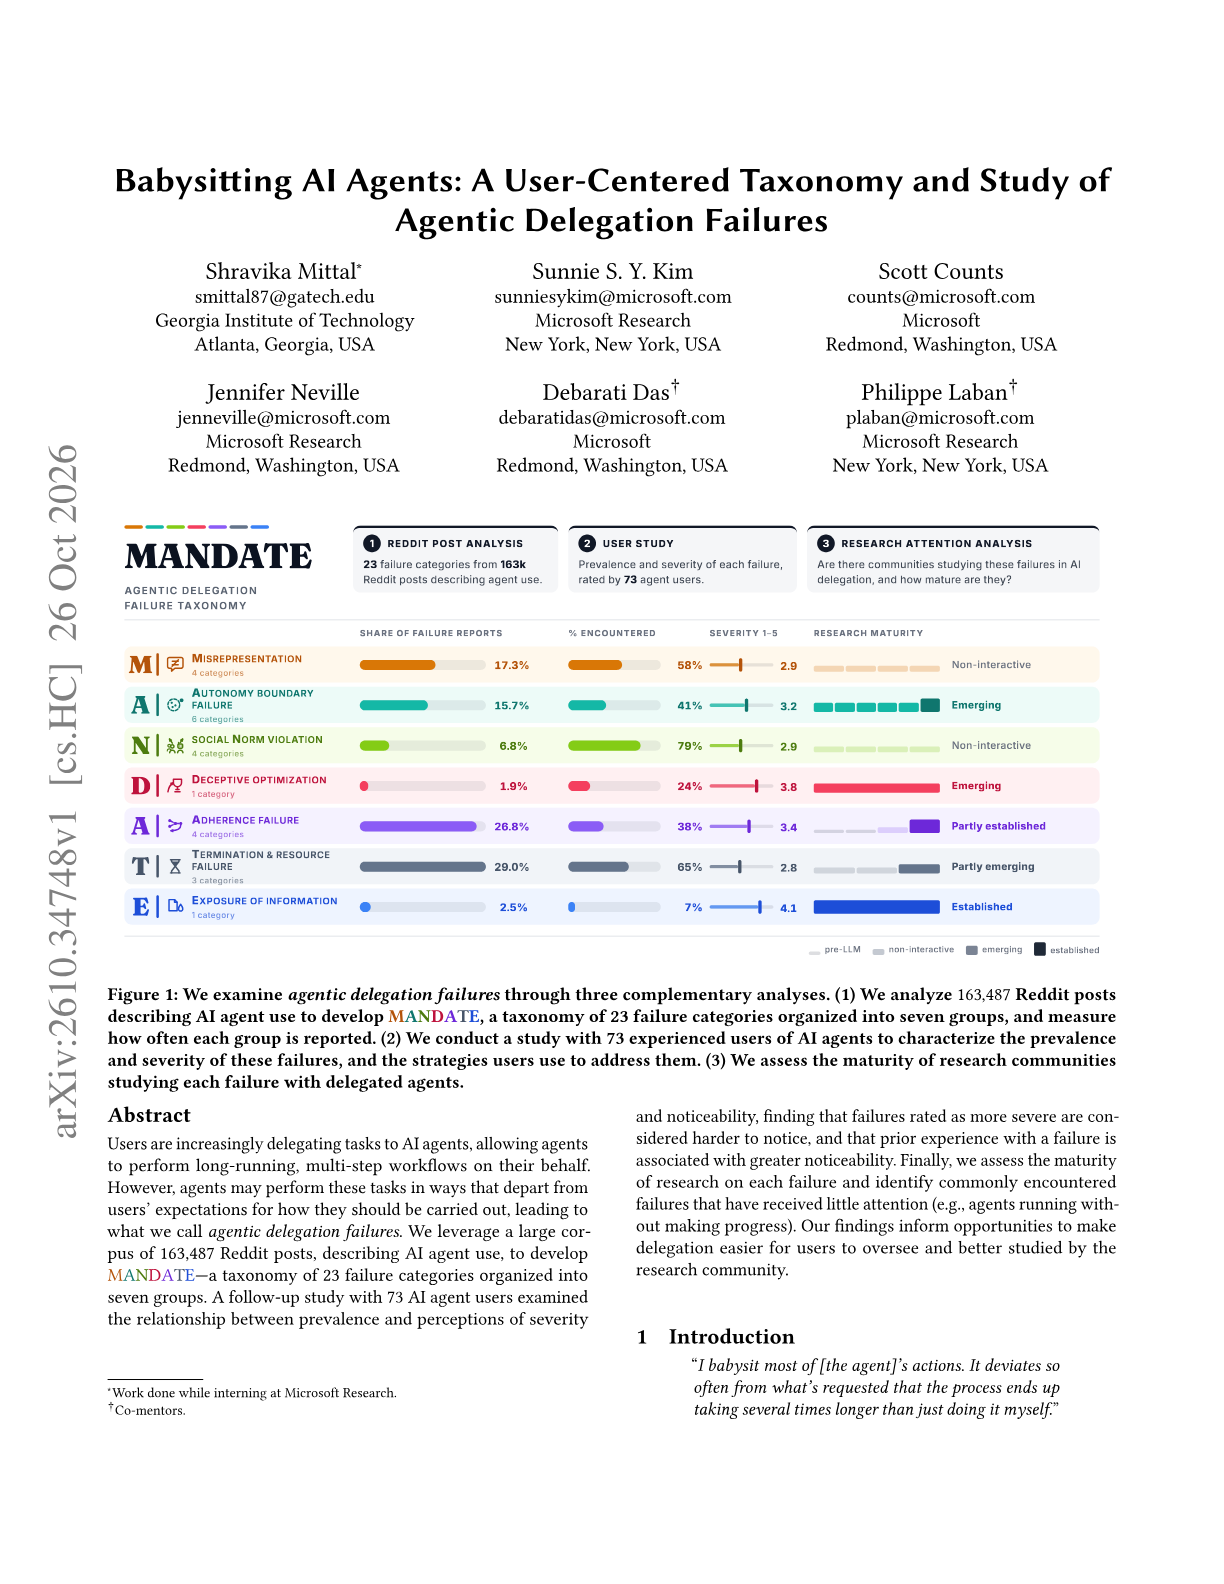
Shravika Mittal, Sunnie S. Y. Kim, Scott Counts, Jennifer Neville and colleagues (Microsoft Research, Georgia Institute of Technology) build MANDATE, a taxonomy of agentic delegation failures, from 163,487 Reddit posts about AI agent use, then test it with 73 experienced agent users.
Ask this paper
Taxonomy. MANDATE has 23 failure categories in seven groups, covering cases where an agent completes delegated work in ways that depart from what the user expected.
Severity and noticeability. Failures that users rate as more severe are also rated as harder to notice, and users who have experienced a failure rate it as easier to notice than users who only find it plausible.
Research gap. The most frequently experienced failures are often the least studied. Unbounded or idle execution, where an agent spends time and compute without progressing, is among the most experienced and has the sparsest research base.
Community differences. Failure distributions differ by subreddit; resource and termination failures dominate local-model communities, while r/ClaudeAI posts focus on other groups.
Abstract
Users are increasingly delegating tasks to AI agents, allowing agents to perform long-running, multi-step workflows on their behalf. However, agents may perform these tasks in ways that depart from users' expectations for how they should be carried out, leading to what we call agentic delegation failures. We leverage a large corpus of 163,487 Reddit posts, describing AI agent use, to develop MANDATE: a taxonomy of 23 failure categories organized into seven groups. A follow-up study with 73 AI agent users examined the relationship between prevalence and perceptions of severity and noticeability, finding that failures rated as more severe are considered harder to notice, and that prior experience with a failure is associated with greater noticeability. Finally, we assess the maturity of research on each failure and identify commonly encountered failures that have received little attention (e.g., agents running without making progress). Our findings inform opportunities to make delegation easier for users to oversee and better studied by the research community.