Beyond Ten Turns
This paper introduces ASearcher, an open-source framework for training LLM-based search agents capable of long-horizon, expert-level search. It addresses two major limitations in prior open-source approaches: short turn limits (≤10) and lack of large-scale, high-quality QA data.
Ask this paper
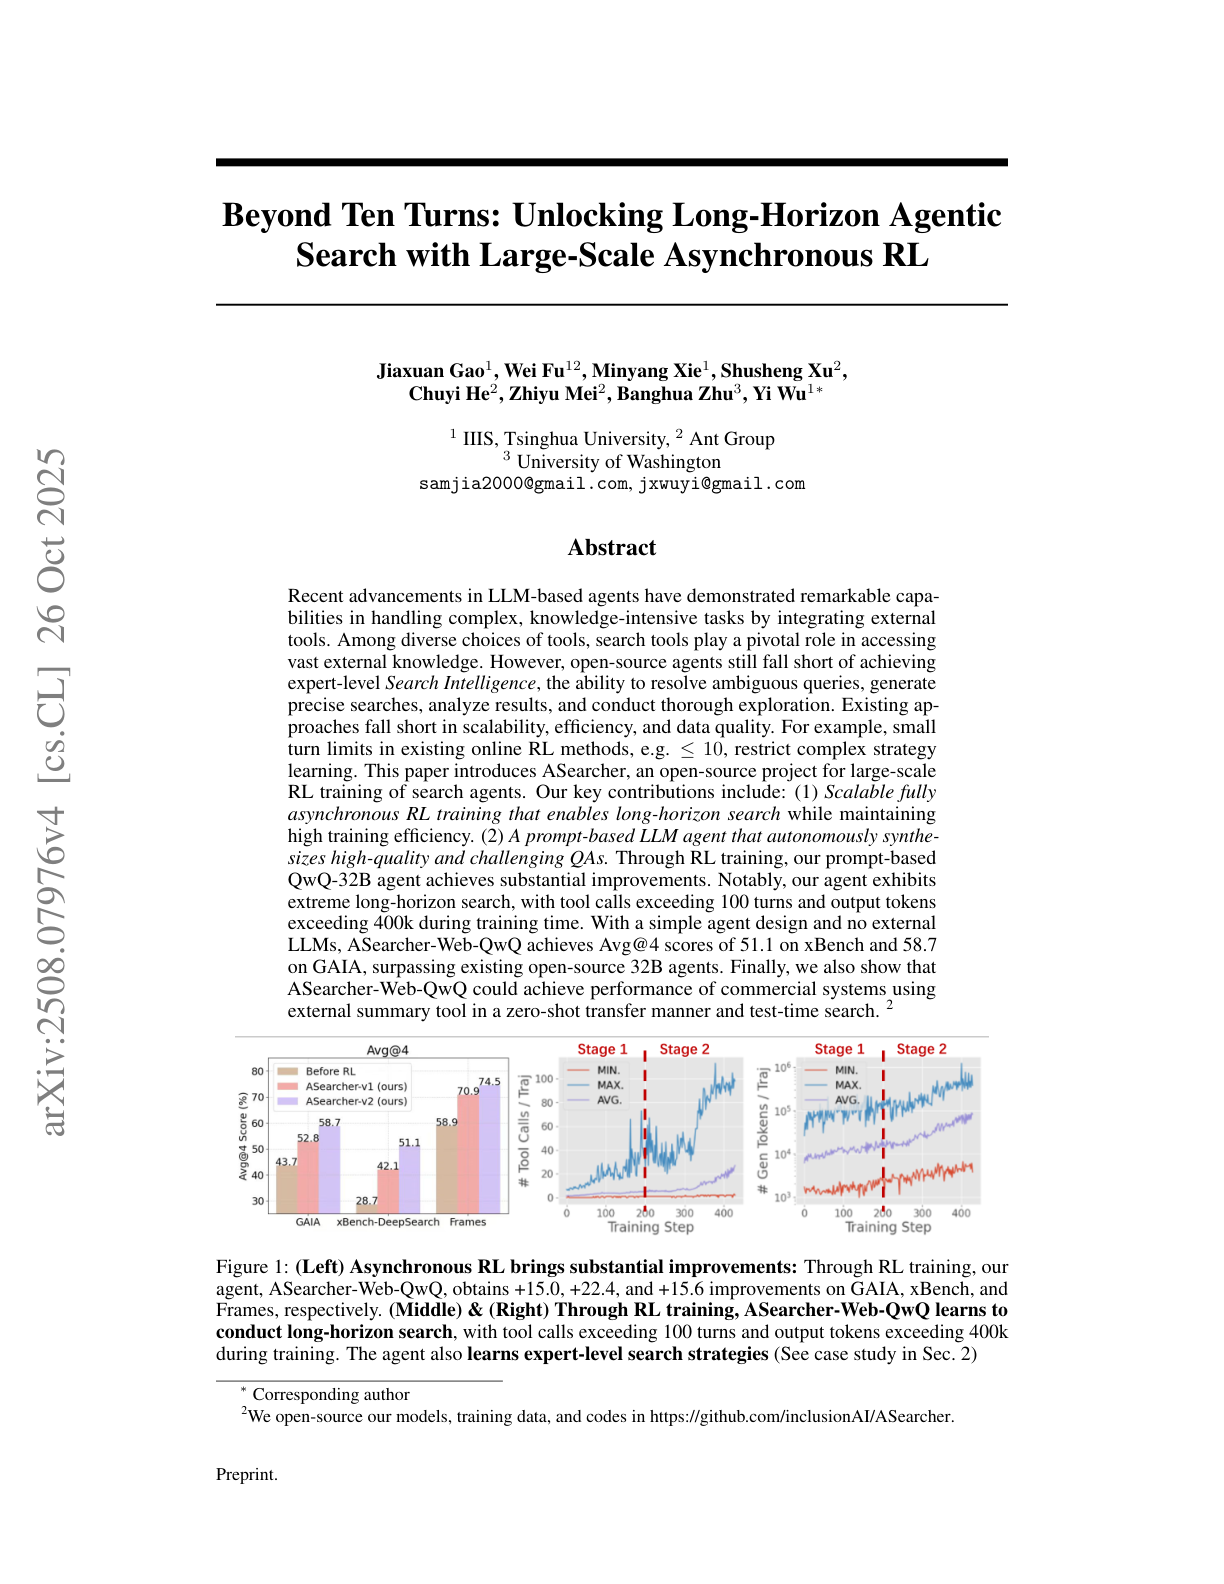
Fully asynchronous RL for long-horizon search – Unlike batch generation RL, ASearcher decouples trajectory execution from model updates, avoiding bottlenecks from long trajectories. This enables relaxed turn limits (up to 128), with training showing >40 tool calls and >150k tokens in a single trajectory.
Scalable QA synthesis agent – An autonomous LLM agent generates complex, uncertainty-rich QA pairs by injection (adding external facts) and fuzzing (obscuring key info), followed by multi-stage quality checks. From 14k seeds, 134k high-quality QAs were created, 25.6k requiring tool use.
Simple but powerful agent design – Uses only search and browsing tools (no external LLM), with end-to-end RL optimizing reasoning and summarization. Tailored prompting and history management are applied for both base LLMs (Qwen2.5-7B/14B) and large reasoning models (QwQ-32B).
Expert-level search behaviors – Through RL, ASearcher-Web-QwQ learns uncertainty-aware reasoning, precise key info extraction from noisy content, cross-document inference, and rigorous verification, outperforming Search-R1-32B and Search-o1(QwQ) in case studies.
State-of-the-art performance – Achieves Avg@4 of 42.1 on xBench-DeepSearch and 52.8 on GAIA, with significant RL gains (+46.7% and +20.8% respectively). Local KB-trained agents generalize well to web search, surpassing stronger baselines.
Training efficiency – Asynchronous rollouts and decoupled updates maintain high GPU utilization, handling large variance in tool call count and token length per trajectory.