Beyond the Teacher: Understanding and Preserving Distillation Overshoot in Agentic On-Policy Distillation
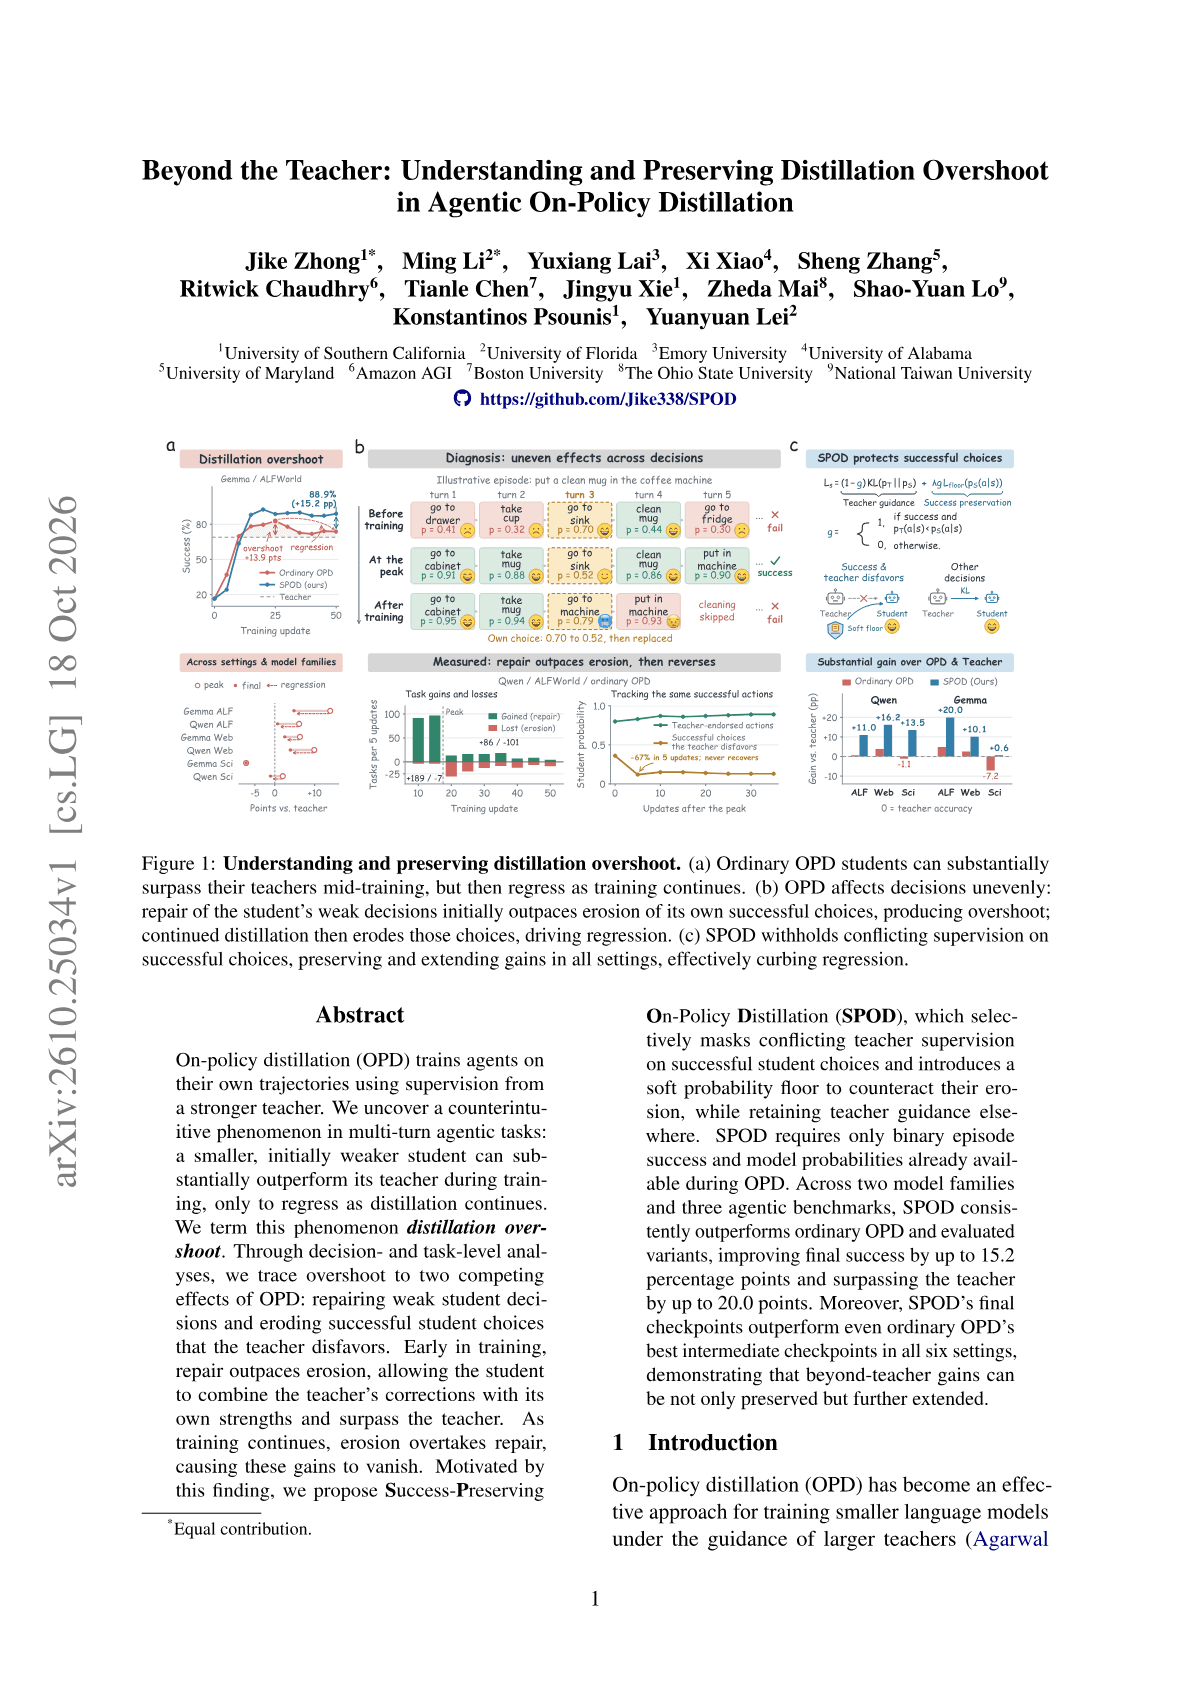
Jike Zhong, Ming Li, Konstantinos Psounis, Yuanyuan Lei and colleagues (USC, University of Florida, Emory and others) report distillation overshoot: in multi-turn agentic on-policy distillation, a weaker student first surpasses its teacher and then regresses as training continues.
Ask this paper
Two competing effects. On-policy distillation repairs weak student decisions and also erodes successful student choices that the teacher disfavors. Repair dominates early, erosion dominates later.
SPOD. Success-Preserving OPD masks teacher supervision that conflicts with successful student choices and adds a soft probability floor, while keeping teacher guidance elsewhere. It needs only binary episode success and existing probabilities.
Results. Across two model families and three agentic benchmarks, SPOD improves final success by up to 15.2 points over OPD and exceeds the teacher by up to 20.0 points.
Checkpoint selection. SPOD's final checkpoints beat ordinary OPD's best intermediate checkpoints in all six settings, so the gain is not just early stopping.
Abstract
On-policy distillation (OPD) trains agents on their own trajectories using supervision from a stronger teacher. We uncover a counterintuitive phenomenon in multi-turn agentic tasks: a smaller, initially weaker student can substantially outperform its teacher during training, only to regress as distillation continues. We term this phenomenon distillation overshoot. Through decision- and task-level analyses, we trace overshoot to two competing effects of OPD: repairing weak student decisions and eroding successful student choices that the teacher disfavors. Early in training, repair outpaces erosion, allowing the student to combine the teacher's corrections with its own strengths and surpass the teacher. As training continues, erosion overtakes repair, causing these gains to vanish. Motivated by this finding, we propose Success-Preserving On-Policy Distillation (SPOD), which selectively masks conflicting teacher supervision on successful student choices and introduces a soft probability floor to counteract their erosion, while retaining teacher guidance elsewhere. SPOD requires only binary episode success and model probabilities already available during OPD. Across two model families and three agentic benchmarks, SPOD consistently outperforms ordinary OPD and evaluated variants, improving final success by up to 15.2 percentage points and surpassing the teacher by up to 20.0 points. Moreover, SPOD's final checkpoints outperform even ordinary OPD's best intermediate checkpoints in all six settings, demonstrating that beyond-teacher gains can be not only preserved but further extended. Code: https://github.com/Jike338/SPOD