BlueLM-GUI Technical Report: A Real-Device-Centric Flywheel for Self-Improving Mobile GUI Agents
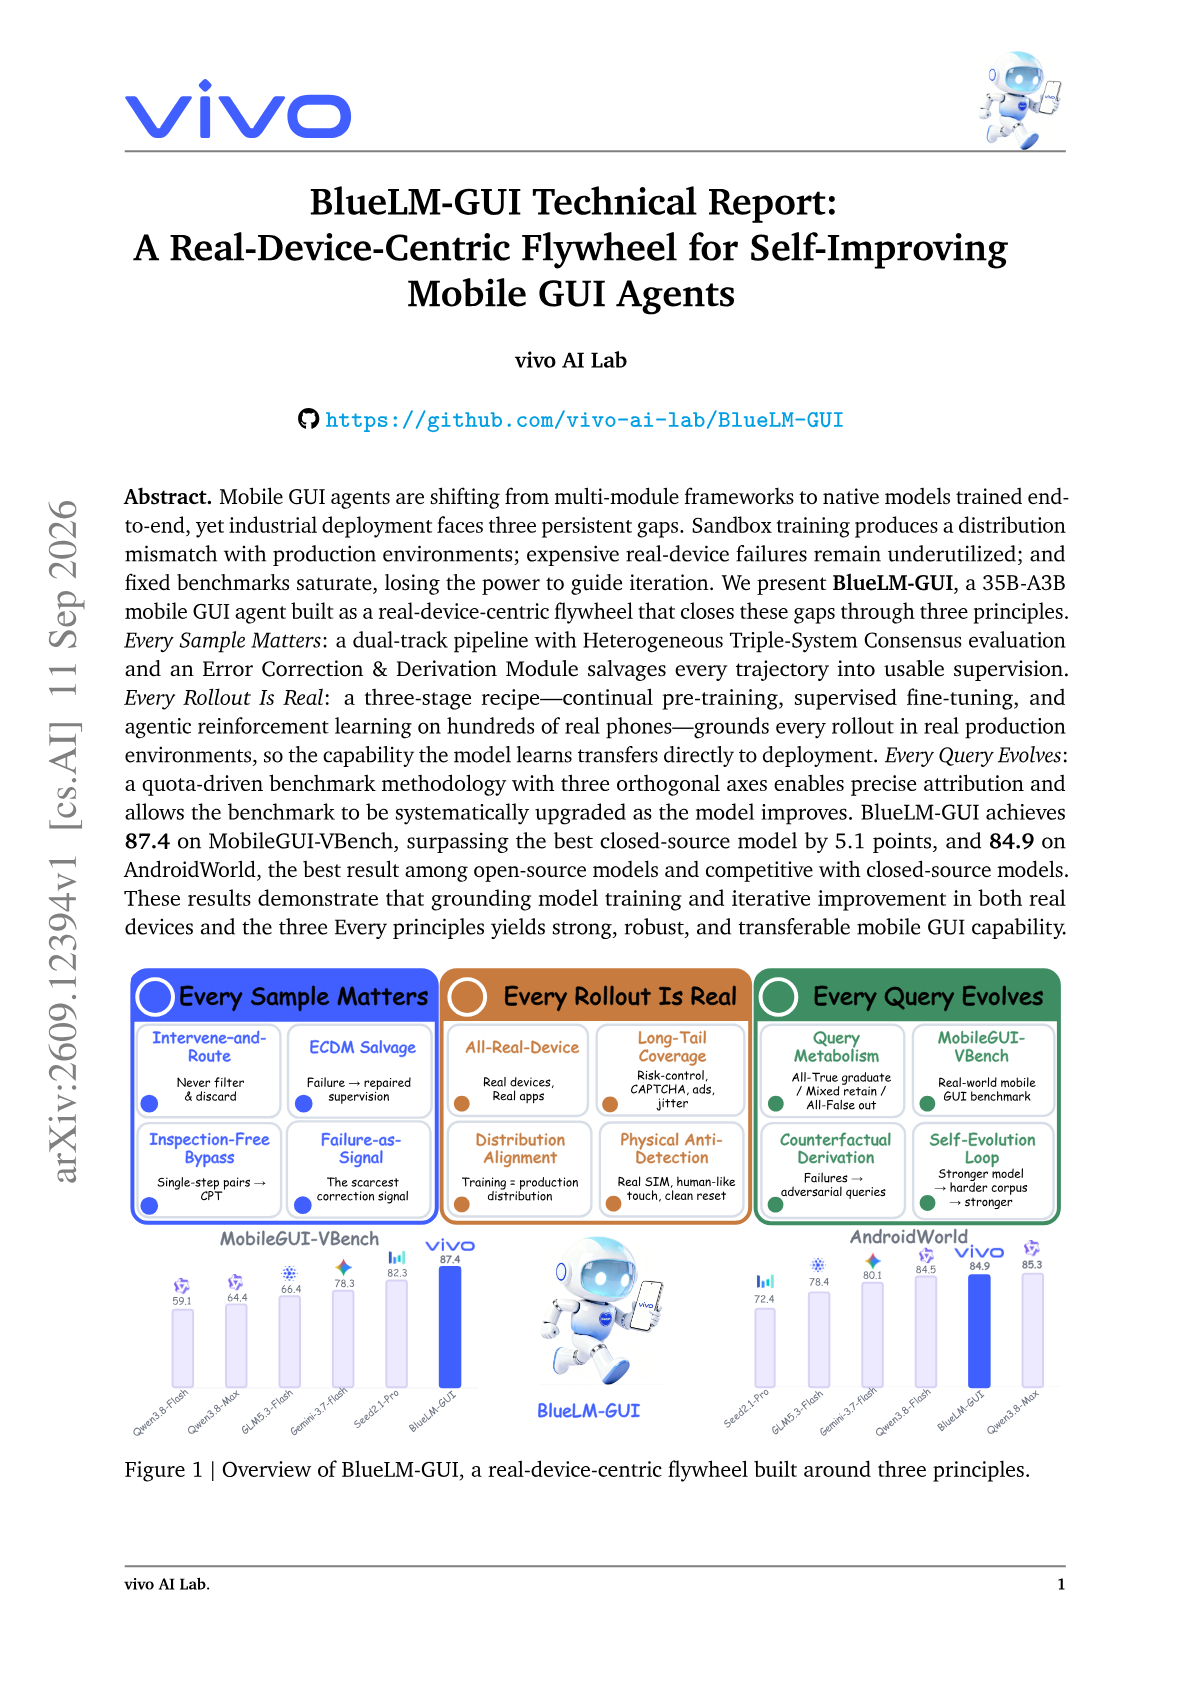
The vivo AI Lab team presents BlueLM-GUI, a 35B-A3B mobile GUI agent whose data collection, RL rollouts and evaluation all run on hundreds of real phones instead of emulators.
Ask this paper
Real devices: Continual pre-training, SFT and agentic RL all use rollouts on real phones, so the training distribution matches deployment.
Failures become data: An Error Correction and Derivation Module turns failed and anomalous trajectories into supervision through step-level correction, query realignment and counterfactual derivation.
Evolving benchmark: MobileGUI-VBench is defined as a quota distribution over a metric system, so when it saturates the quotas shift and the difference between versions is stated exactly.
Result: 87.4 on MobileGUI-VBench, 5.1 points above the best closed-source model, and 84.9 on AndroidWorld, the best open-source result.
Abstract
Mobile GUI agents are shifting from multi-module frameworks to native models trained end-to-end, yet industrial deployment faces three persistent gaps. Sandbox training produces a distribution mismatch with production environments; expensive real-device failures remain underutilized; and fixed benchmarks saturate, losing the power to guide iteration. We present BlueLM-GUI, a 35B-A3B mobile GUI agent built as a real-device-centric flywheel that closes these gaps through three principles. Every Sample Matters: a dual-track pipeline with Heterogeneous Triple-System Consensus evaluation and an Error Correction \& Derivation Module salvages every trajectory into usable supervision. Every Rollout Is Real: a three-stage recipe---continual pre-training, supervised fine-tuning, and agentic reinforcement learning on hundreds of real phones---grounds every rollout in real production environments, so the capability the model learns transfers directly to deployment. Every Query Evolves: a quota-driven benchmark methodology with three orthogonal axes enables precise attribution and allows the benchmark to be systematically upgraded as the model improves. BlueLM-GUI achieves 87.4 on MobileGUI-VBench, surpassing the best closed-source model by 5.1 points, and 84.9 on AndroidWorld, the best result among open-source models and competitive with closed-source models. These results demonstrate that grounding model training and iterative improvement in both real devices and the three Every principles yields strong, robust, and transferable mobile GUI capability.