CliffCompaction: Cost-Efficient Compaction for Long-Horizon Coding Agents
Trang Nguyen, Eulrang Cho and Tim Dettmers (Carnegie Mellon) with Bingqing Chen (Bosch Center for AI) present CliffCompaction, an automatic context-compaction method for long-horizon coding agents that only truncates or drops content and never rewrites it.
Ask this paper
Faithful compaction. Kept content is never rephrased, and each pass works only on original content, discarding earlier compacted output, so errors from summarizing a summary do not accumulate.
Cost. Under a bounded context it cuts cost by up to 50% while matching or improving performance on Terminal-Bench.
Test-time scaling. Cheaper rollouts add more than 10 points on Terminal-Bench for less than the cost of two full-context runs, and with parallel scaling Kimi K2.6 matches Opus 4.7 and beats Opus 4.6 and GPT-5.3 Codex at lower cost.
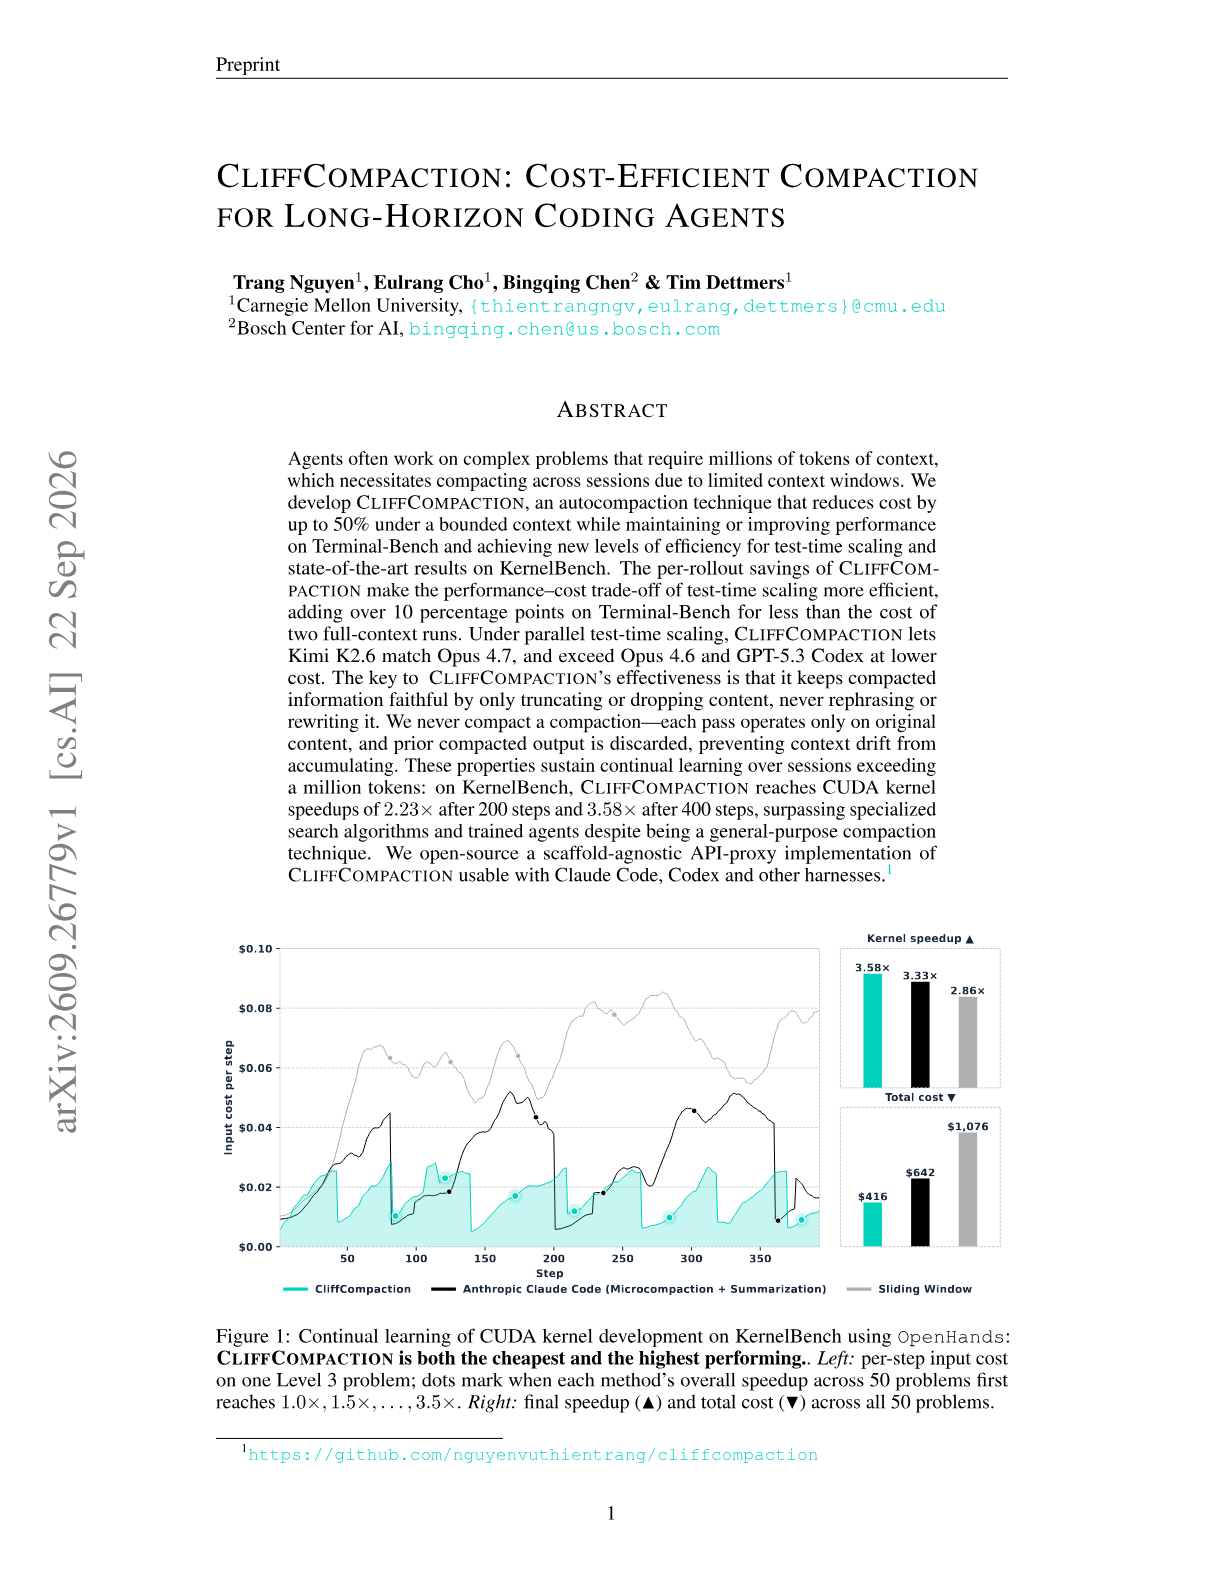
Million-token sessions. On KernelBench it reaches CUDA kernel speedups of 2.23x after 200 steps and 3.58x after 400, ahead of specialized search algorithms and trained agents.
Drop-in release. An open-source, scaffold-agnostic API proxy works with Claude Code, Codex and other harnesses.
Abstract
Agents often work on complex problems that require millions of tokens of context, which necessitates compacting across sessions due to limited context windows. We develop CliffCompaction, an autocompaction technique that reduces cost by up to 50% under a bounded context while maintaining or improving performance on Terminal-Bench and achieving new levels of efficiency for test-time scaling and state-of-the-art results on KernelBench. The per-rollout savings of CliffCompaction make the performance--cost trade-off of test-time scaling more efficient, adding over 10 percentage points on Terminal-Bench for less than the cost of two full-context runs. Under parallel test-time scaling, CliffCompaction lets Kimi K2.6 match Opus 4.7, and exceed Opus 4.6 and GPT-5.3 Codex at lower cost. The key to CliffCompaction's effectiveness is that it keeps compacted information faithful by only truncating or dropping content, never rephrasing or rewriting it. We never compact a compaction---each pass operates only on original content, and prior compacted output is discarded, preventing context drift from accumulating. These properties sustain continual learning over sessions exceeding a million tokens: on KernelBench, CliffCompaction reaches CUDA kernel speedups of $2.23\times$ after 200 steps and $3.58\times$ after 400 steps, surpassing specialized search algorithms and trained agents despite being a general-purpose compaction technique. We open-source a scaffold-agnostic API-proxy implementation of CliffCompaction usable with Claude Code, Codex and other harnesses.