Hacker Papers
- 01
Learning in High Dimension Always Amounts to Extrapolation
Hacker News threads
- Oct 2023Learning in High Dimension Always Amounts to Extrapolation
- Nov 2023Learning in High Dimension Always Amounts to Extrapolation
- Dec 2021Training computer vision models on random noise instead of real images
- May 2022The Scaling Hypothesis (2021)
- Oct 2023The copyright fight over authors and OpenAI's ChatGPT
- Nov 2023Transformers struggle with generalizing tasks beyond pre-training data
- Mar 2024Large language models can do jaw-dropping things. But nobody knows why
- Oct 2024GitHub cuts AI deals with Google, Anthropic
- Feb 2026GPT-5.2 derives a new result in theoretical physics
- Oct 2026“Math 2.0” will need to value mathematical progress more holistically
- 02
Emergent World Representations: Exploring a Sequence Model Trained on a Synthetic Task
Hacker News threads
- Feb 2023Emergent World Representations in Neural Networks
- Jan 2023Do Large Language Models learn world models or just surface statistics?
- Feb 2023What Is ChatGPT Doing and Why Does It Work?
- Mar 2023GPT-4
- Mar 2023HN thread 35348353
- Apr 2023HN thread 35356648
- May 2023Just Calm Down About GPT-4 Already
- Jun 2024Legal models hallucinate in 1 out of 6 (or more) benchmarking queries
- Apr 2026Where the Goblins Came From
- 03
Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
Hacker News threads
- Jul 2022Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- May 2023Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- Apr 2023Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- Feb 2022I asked GPT-NeoX-20B a hundred arithmetic questions
- Apr 2022Socratic Models – Composing Zero-Shot Multimodal Reasoning with Language
- Feb 2023Jailbreaking ChatGPT with Dan (Do Anything Now)
- Apr 2023DyLoRA: Parameter Efficient Tuning of Pre-Trained Models
- Aug 2023Do Machine Learning Models Memorize or Generalize?
- May 2024Groq surpasses 1,200 tokens/sec with Llama 3 8B
- Feb 2026Who discovered grokking and why is the name hard to find?
- Jun 2026"They're made out of weights"
- 04
The case for 4-bit precision: k-bit Inference Scaling Laws
Hacker News threads
- Jul 2023The case for 4-bit precision: k-bit Inference Scaling Laws
- Jan 2023Some Remarks on Large Language Models – Yoav Goldberg
- Mar 2023LLaMA-7B in Pure C++ with full Apple Silicon support
- Mar 2023Llama.cpp 30B runs with only 6GB of RAM now
- Aug 2023How Is LLaMa.cpp Possible?
- Nov 2023QUIK is a method for quantizing LLM post-training weights to 4 bit precision
- Jan 2024Meta AI releases Code Llama 70B
- Nov 2024AMD now has more compute on the top 500 than Nvidia
- Jun 2026Qwen 3.6 27B is the sweet spot for local development
- 05
DensePose From WiFi
Hacker News threads
- Jan 2023DensePose from WiFi
- Jan 2023DensePose from WiFi Sensing: Full Body Tracking
- Jan 2023Accurate Pose Estimation via WiFi Signals and ML
- Jan 2023Accurate Pose Estimation via WiFi Signals
- Jan 2023WiFi Routers Used to Produce 3D Images of Humans
- Jan 2023Ask HN: What will be the first AI “incident”?
- Jul 2023French Assembly to allow remote police surveillance via phone cameras and mics
- Sep 2023WiFi can read through walls
- May 2024Wi-Fi devices set to become object sensors by 2024 via IEEE 802.11bf standard
- Apr 2025BPS is a GPS alternative that nobody's heard of
- Feb 2026WiFi Could Become an Invisible Mass Surveillance System
- 06
Thinking Like Transformers
Hacker News threads
- Jun 2021Thinking Like Transformers
- Jun 2023Thinking Like Transformers (pdf)
- Dec 2021The potential of transformers in reinforcement learning
- May 2023It's not just statistics: GPT-4 does reason
- Jun 2023From Word Models to World Models
- Aug 2023Graph of Thoughts: Solving Elaborate Problems with Large Language Models
- Sep 2023I made a transformer by hand (no training)
- Apr 2024Mixture-of-Depths: Dynamically allocating compute in transformers
- Nov 2025Ask HN: How are Markov chains so different from tiny LLMs?
- Feb 2026I want to wash my car. The car wash is 50 meters away. Should I walk or drive?
- 07
Formal Algorithms for Transformers
Hacker News threads
- Jul 2022Formal Algorithms for Transformers
- Jan 2023The Transformer Family
- Apr 2023A Baby GPT
- Apr 2023What Are Transformer Models and How Do They Work?
- May 2023Ask HN: Can someone ELI5 Transformers and the “Attention is all we need” paper
- Jul 2023What We Know About LLMs (A Primer)
- Dec 2023"Attention", "Transformers", in Neural Network "Large Language Models"
- Jan 2024Relearning math as an adult
- Jun 2026Can I Buy Your KV Cache?
- 08
Monolith: Real Time Recommendation System With Collisionless Embedding Table
Hacker News threads
- Nov 2022Monolith: Real time recommendation system with collisionless embedding table
- Nov 2022TikTok published an article on their recommendation system architecture
- Nov 2022Paper on 'Monolith: Real Time Recommendation System' by Bytedance Inc (TikTok)
- Dec 2022TikTok’s Secret Sauce
- Jan 2023Ask HN: Techwise, how did TikTok get so good?
- Feb 2023The secret sauce of TikTok’s recommendations
- Nov 2023X is changing its algorithm to highlight smaller accounts
- Dec 2024TikTok divestment law upheld by federal appeals court
- Jan 2025TikTok preparing for U.S. shut-off on Sunday
- May 2025You Don't Need Re-Ranking: Understanding the Superlinked Vector Layer
- Feb 2026TikTok's 'Addictive Design' Found to Be Illegal in Europe
- 09
Neural Networks and the Chomsky Hierarchy
Hacker News threads
- Jul 2022Neural Networks and the Chomsky Hierarchy by DeepMind
- Jan 2023Neural Networks and the Chomsky Hierarchy [DeepMind, 2022]
- Aug 2022Deep Learning Alone Isn’t Getting Us to Human-Like AI
- Feb 2023What Is ChatGPT Doing and Why Does It Work?
- Apr 2023Tighter bounds on the expressivity of transformer encoders
- May 2023Ask HN: Why can GPT4 en/decode base64?
- Jun 2023Bard is getting better at logic and reasoning
- Jun 2023Modern language models refute Chomsky’s approach to language
- Nov 2024Interview with gwern
- Jun 2026No, Artificial Intelligence is not Conscious - Ted Chiang
- 10
Every Model Learned by Gradient Descent Is Approximately a Kernel Machine
Hacker News threads
- Dec 2020Every Model Learned by Gradient Descent Is Approximately a Kernel Machine
- Feb 2024Every model learned by gradient descent is approximately a kernel machine (2020)
- Dec 2020Every Model Learned by Gradient Descent Is Approximately a Kernel Machine
- Dec 2020Does GPT-2 Know Your Phone Number?
- Oct 2021A new link to an old model could crack the mystery of deep learning
- Mar 2022Deep learning is hitting a wall?
- Apr 2022Pathways Language Model (PaLM): Scaling to 540B parameters
- Apr 2022Pathways Language Model (PaLM): Scaling to 540B parameters
- Sep 2022Using GPT-3 to pathfind in random graphs
- Aug 2023Do Machine Learning Models Memorize or Generalize?
- Oct 2023When Gradient Descent Is a Kernel Method
- 11
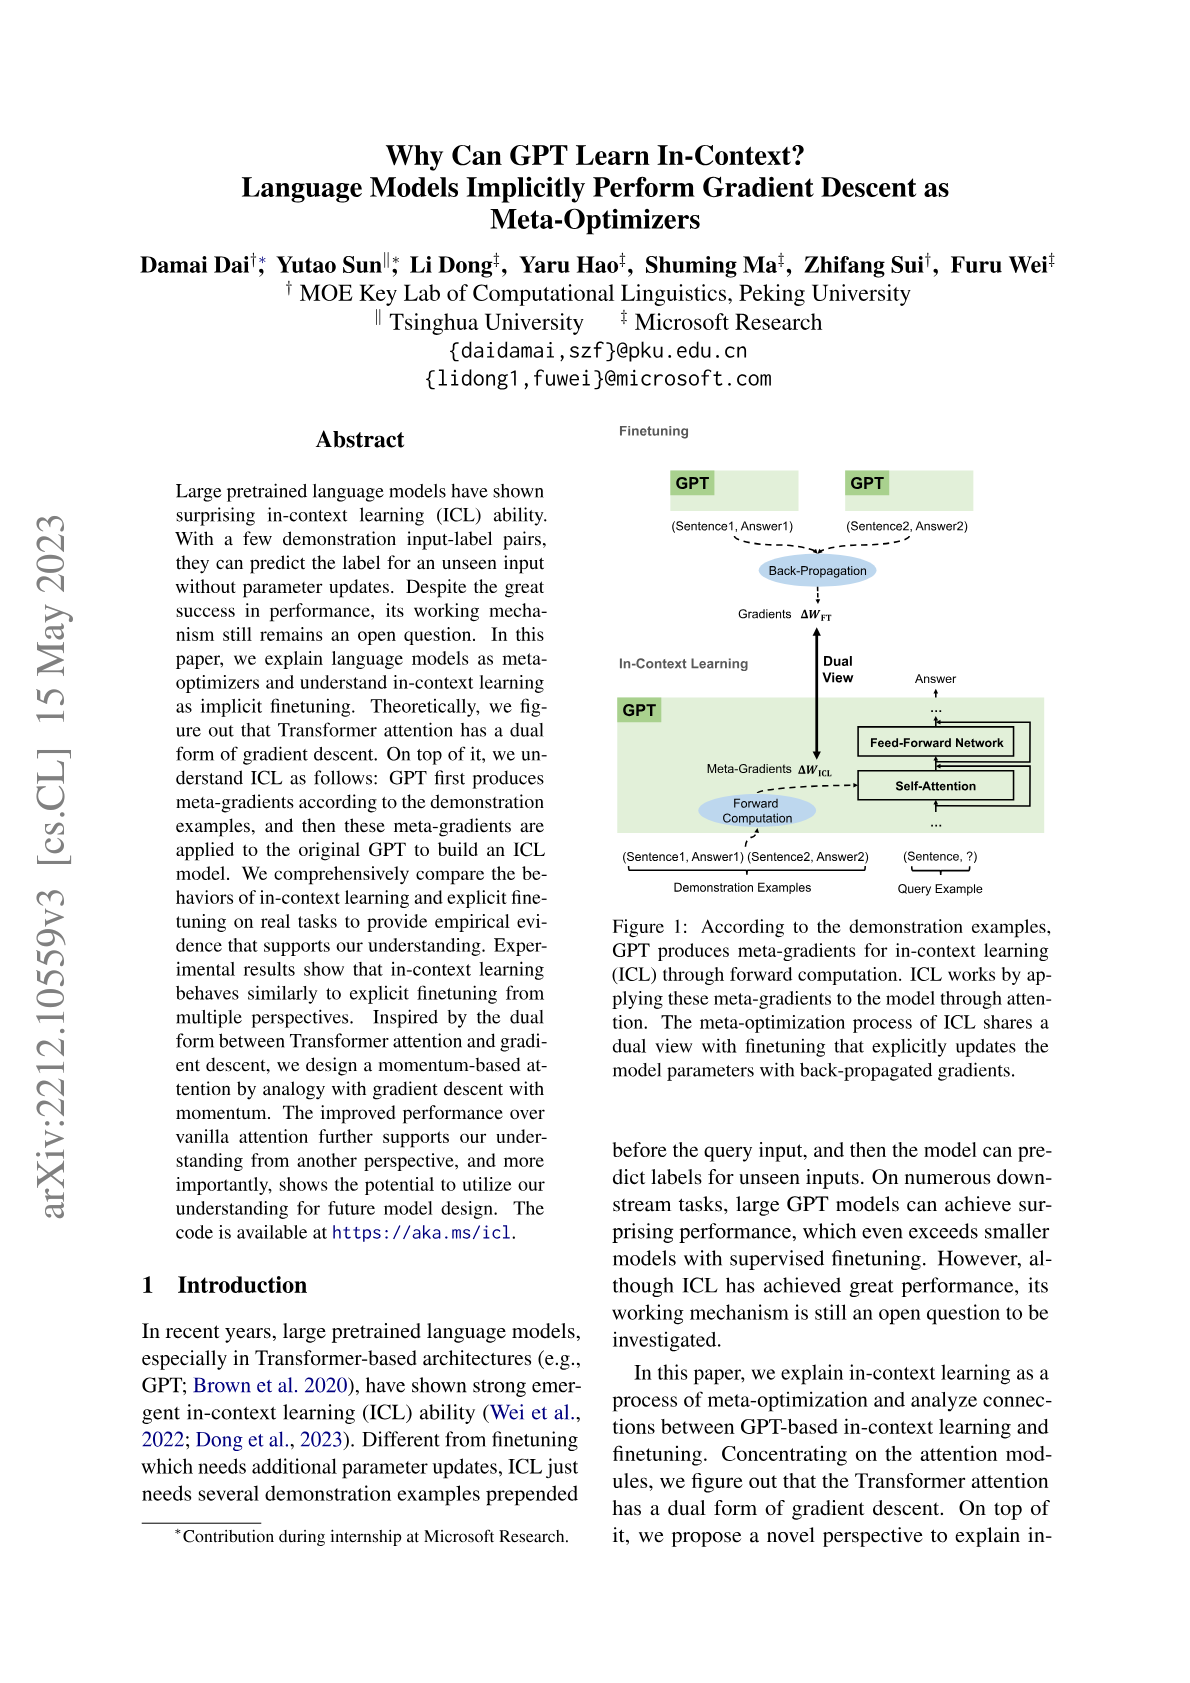
Why Can GPT Learn In-Context? Language Models Implicitly Perform Gradient Descent as Meta-Optimizers
Hacker News threads
- Dec 2022Why Can GPT Learn In-Context? Language Models Perform Gradient Descent
- Jan 2023The Expanding Dark Forest and Generative AI
- Feb 2023GPT in 60 Lines of NumPy
- Feb 2023To Build Truly Intelligent Machines, Teach Them Cause and Effect
- Mar 2023Large language models are having their Stable Diffusion moment
- Mar 2023GPT-4 Designed a Programming Language
- Mar 2023OK, it’s time to freak out about AI
- May 2023Chatbots Don’t Know What Stuff Isn’t
- Jul 2024Reasoning in Large Language Models: A Geometric Perspective
- 12
Linear Transformers Are Secretly Fast Weight Programmers
Hacker News threads
- Oct 2022Meta Learning Backpropagation and Improving It (2020)
- May 2023Geoffrey Hinton leaves Google and can now speak freely about his AI concern
- Sep 2023HN thread 37367951
- Sep 2023I made a transformer by hand (no training)
- Oct 2023Ring Attention with Blockwise Transformers for Near-Infinite Context
- Oct 2023How Transformers Work
- Feb 2024Neural Network Diffusion
- Sep 2026Transformers Explained Visually
- 13
Relating transformers to models and neural representations of the hippocampal formation
Hacker News threads
- Apr 2022Relating Transformers to Modes and Neural Representations of the Hippocampal
- May 2022Relating transformers to neural representations of hippocampal formation
- Apr 2022Relating Transformers to Neural Representations of the Hippocampal Formation
- Apr 2022Playing with DALL-E 2
- Dec 2022Ask HN: How to get back into AI?
- Jan 2024Understand how transformers work by demystifying the math behind them
- Jun 2024A most profound video game: a good cognitive aid for research
- Sep 2024Kolmogorov-Arnold networks may make neural networks more understandable
- Nov 2025The Case That A.I. Is Thinking
- 14
Discovering Latent Knowledge in Language Models Without Supervision
Hacker News threads
- Dec 2022Discovering Latent Knowledge in Language Models Without Supervision
- Dec 2022Discovering Latent Knowledge in Language Models Without Supervision
- Dec 2022AlphaCode Attention Visualization
- Jan 2023ChatRWKV, like ChatGPT but powered by the RWKV (RNN-based, open) language model
- Feb 2023Microsoft Adds ChatGPT AI Technology to Bing Search Engine
- Feb 2023ArxivGPT: Chrome extension that summarizes arxived research papers using ChatGPT
- Feb 2023ChatGPT is falsely recommending us for a service we don't provide
- Feb 2023ChatGPT get-rich-quick schemes are coming for magazines, Amazon, and YouTube
- Jul 2024ChatGPT Isn't 'Hallucinating'–It's Bullshitting – Scientific American
- Apr 2025GPT o3 frequently fabricates actions, then elaborately justifies these actions
- 15
Fast Inference from Transformers via Speculative Decoding
Hacker News threads
- Sep 2023Fast Inference from Transformers via Speculative Decoding
- Jul 2025Playing with Open Source LLMs
- Feb 2026Raspberry Pi Pico 2 at 873.5MHz with 3.05V Core Abuse
- Apr 2026We got 207 tok/s with Qwen3.5-27B on an RTX 3090
- May 2026Accelerating Gemma 4: faster inference with multi-token prediction drafters
- Jun 2026DeepSeek open-sources inference optimizations with 60–85% faster generation [pdf]
- Jun 2026DeepSeek open-sources inference optimizations with 60–85% faster generation [pdf]
- Jun 2026DeepSeek open-sources inference optimizations with 60–85% faster generation [pdf]
- 16
Deduplicating Training Data Makes Language Models Better
Hacker News threads
- May 2022Google fires another AI researcher who reportedly challenged findings
- Aug 2022Chinchilla's Wild Implications
- Aug 2022Exploring 12M of the 2.3B images used to train Stable Diffusion
- Nov 2022Ask HN: What can I personally do to fight AGAINST the Copilot class action?
- Jun 2024Large language model data pipelines and Common Crawl
- Jan 202530% drop in O1-preview accuracy when Putnam problems are slightly variated
- 17
Generative Language Modeling for Automated Theorem Proving
Hacker News threads
- Sep 2020Generative Language Modeling for Automated Theorem Proving
- Sep 2020Generative Language Modeling for Automated Theorem Proving
- Sep 2020Graph Representations for Higher-Order Logic and Theorem Proving (2019)
- Sep 2020At the International Mathematical Olympiad, computers prepare to go for the gold
- Sep 2020The Collatz Conjecture: the simple math problem we still can’t solve
- Nov 2020AI Expert Roadmap
- Jan 2021DALL·E: Creating Images from Text
- Jun 2021Mathematicians welcome computer-assisted proof in ‘grand unification’ theory
- Jul 2024AI solves International Math Olympiad problems at silver medal level
- 18
Character-Aware Models Improve Visual Text Rendering
Hacker News threads
- Dec 2022Improving Text Rendering in Image Generation Models
- Dec 2022What ChatGPT Can't Do
- Feb 2023Illusion Diffusion: Optical Illusions Using Stable Diffusion
- Apr 2023A Baby GPT
- Apr 2023Stability AI releases DeepFloyd IF, a powerful text-to-image model
- Oct 2023DALL-E 3: Improving image generation with better captions [pdf]
- Mar 2024Ask HN: Why can't image generation models spell?
- 19
Asleep at the Keyboard? Assessing the Security of GitHub Copilot's Code Contributions
Hacker News threads
- Aug 2021An empirical cybersecurity evaluation of GitHub Copilot's code contributions
- Sep 2021GitHub Copilot Generated Insecure Code in 40% of Circumstances During Experiment
- Sep 2021GitHub Copilot Generated Insecure Code in 40% of Circumstances During Experiment
- Oct 2021GitHub Copilot available for JetBrains and Neovim
- Jun 2022Papers on GitHub Copilot, copyright law, and ownership for AI-generated code
- Dec 2022Study finds AI assistants help developers produce code likely to be buggy
- Jan 2023It's Plausible, but Is It True?
- 20
Vectorized and performance-portable Quicksort
Hacker News threads
- Feb 2024Vectorized and performance-portable Quicksort (2022)
- Jun 2022Vectorized and performance-portable Quicksort
- Jun 2022Vectorized and performance-portable Quicksort
- Jun 2022Apple M2 Die Shot and Architecture Analysis – Big Cost Increase and A15 Based IP
- Dec 2022Sorting with SIMD
- Jan 2023Efficient and performance-portable vector software
- Mar 2024JPEG XL and the Pareto Front
- 21
Transformers learn in-context by gradient descent
Hacker News threads
- Dec 2022Transformers learn in-context by gradient descent
- Jan 2023Do Large Language Models learn world models or just surface statistics?
- Feb 2023ChatGPT Hype Is Proof Nobody Understands AI
- Apr 2023Teaching ChatGPT to Speak My Son’s Invented Language
- Apr 2023GPT-4 gets a B on my quantum computing final exam
- Mar 2025ARC-AGI without pretraining
- 22
FNet: Mixing Tokens with Fourier Transforms
Hacker News threads
- May 2024FNet: Mixing Tokens with Fourier Transforms (2021)
- May 2021FNet: Mixing Tokens with Fourier Transforms
- May 2021FNet: Attention may be all you WANT but we you need is good token mixing
- May 2021An Interactive Guide to the Fourier Transform (2012)
- May 2024New attention mechanisms that outperform standard multi-head attention
- May 2024New attention mechanisms that outperform standard multi-head attention
- Feb 2025The FFT Strikes Back: An Efficient Alternative to Self-Attention
- Feb 2025The FFT Strikes Back: An Efficient Alternative to Self-Attention
- Mar 2026TorchLean: Formalizing Neural Networks in Lean
- 23
Petals: Collaborative Inference and Fine-tuning of Large Models
Hacker News threads
- Jul 2026Petals: Collaborative Inference and Fine-Tuning of Large Models
- Mar 2023Petals: Collaborative Inference and Fine-Tuning of Large Models
- Dec 2022Petals is creating a free, distributed network for running text-generating AI
- Jan 2023Petals: Run 100B+ language models at home bit-torrent style
- Jan 2023Petals: Run 100B+ language models at home bit-torrent style
- Jan 2023Ask HN: Can you crowdfund the compute for GPT?
- Feb 2023Running large language models like ChatGPT on a single GPU
- Mar 2023The Most Cited AI Papers in 2022
- 24
Planting Undetectable Backdoors in Machine Learning Models
Hacker News threads
- 25
Assessing Game Balance with AlphaZero: Exploring Alternative Rule Sets in Chess
Hacker News threads
- Sep 2020Assessing Game Balance with AlphaZero: Exploring Alternative Rule Sets in Chess
- Sep 2020Exploring Alternative Rule Sets in Chess with AlphaZero
- Sep 2020Assessing Game Balance with AlphaZero: Exploring Alternative Rule Sets in Chess
- Dec 2020Ideal Chess – drop chess perfected?
- Aug 2021Fairer Chess: A Reversal of Two Opening Moves in Chess Creates Balance
- Nov 2022Acquisition of chess knowledge in AlphaZero
- Jan 2024I realized chess pieces can be redesigned to be geometric attack directions
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.