Hacker Papers
- 01
Language Modeling Is Compression
Hacker News threads
- Sep 2023Language Modeling Is Compression
- Sep 2023Language Modeling Is Compression
- Sep 2023Language Modeling Is Compression
- Sep 2023Show HN: 78% MNIST accuracy using GZIP in under 10 lines of code
- Jan 2024Getting Lossless Compression Adopted for Rigorous LLM Benchmarking
- Apr 2024EURISKO Lives
- May 2025The copilot delusion
- Jun 2025Fine-tuning LLMs is a waste of time
- Jan 2026Show HN: AI in SolidWorks
- Jun 2026Dune's Butlerian Jihad and the Future of AI
- Oct 2026OpenAI and Anthropic cut their LLM prices by up to 80% within a few months. Why?
- 02
TinyStories: How Small Can Language Models Be and Still Speak Coherent English?
Hacker News threads
- Jan 2025TinyStories: How Small Can Language Models Be and Still Speak Coherent English? (2023)
- May 2023TinyStories: How Small Can Language Models Be and Still Speak Coherent English?
- May 2023How Small Can Language Models Be and Still Speak Coherent English?
- May 2023Apple bans ChatGPT use by employees, report says
- Jun 2023Modern language models refute Chomsky’s approach to language
- Jun 2023The Darwinian argument for worrying about AI
- Oct 2023Disney Packed Big Emotion into a Little Robot
- Jan 2024Ten Noteworthy AI Research Papers of 2023
- May 2024“Imprecise” language models are smaller, speedier, and nearly as accurate
- Nov 2025Ask HN: How are Markov chains so different from tiny LLMs?
- Sep 2026MicroLLM Lab – Try 7 tiny LLM's in the browser
- 03
Think before you speak: Training Language Models With Pause Tokens
Hacker News threads
- Oct 2023Think Before You Speak: Training Language Models with Pause Tokens
- Oct 2023Want to get started with LLMs? Here's what you need to know
- Oct 2023Ask HN: Why are current LLMs not considered AGI?
- Mar 2024Yi: Open Foundation Models by 01.AI
- Apr 2024Self-reasoning tokens: teaching models to think ahead
- Jul 2024The A.I. Bubble is Bursting with Ed Zitron [video]
- Mar 2025Understanding R1-Zero-Like Training: A Critical Perspective
- May 2025Claude 4
- Oct 2025Why do LLMs freak out over the seahorse emoji?
- 04
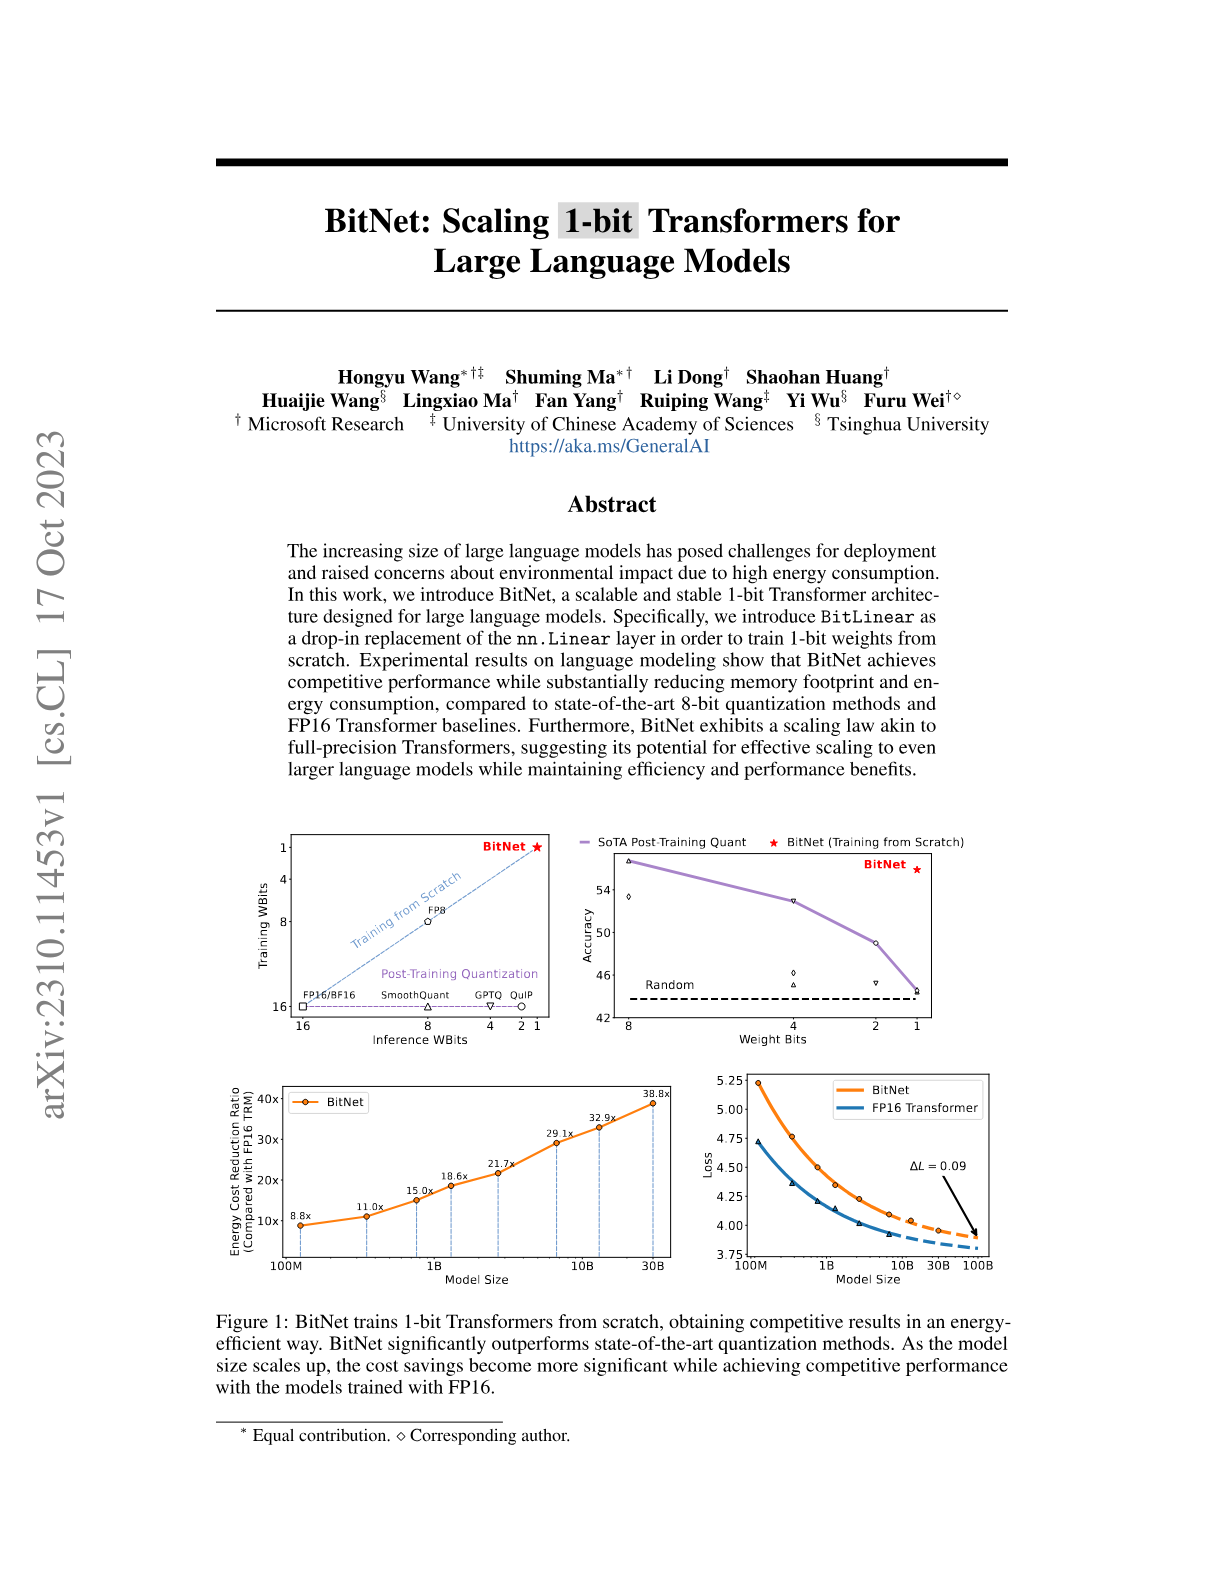
BitNet: Scaling 1-bit Transformers for Large Language Models
Hacker News threads
- Oct 2023BitNet: Scaling 1-Bit Transformers for Large Language Models
- Feb 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Feb 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Mar 2024Towards 1-bit Machine Learning Models
- Jun 2024Scalable MatMul-Free Language Modeling
- Nov 2024SVDQuant: 4-Bit Quantization Powers 12B Flux on a 16GB 4090 GPU with 3x Speedup
- May 2025Towards the Cutest Neural Network
- Mar 2026Microsoft BitNet: 100B Param 1-Bit model for local CPUs
- Jul 2026Neutrino-1 8B
- 05
Large Language Models Understand and Can be Enhanced by Emotional Stimuli
Hacker News threads
- Aug 2023Leveraging Psychology for Large Language Models Enhancement via Emotional Prompt
- Sep 2023Large Language Models Understand and Can Be Enhanced by Emotional Stimuli
- Nov 2023Large Language Models Understand and Can Be Enhanced by Emotional Stimuli
- Sep 2023Redditor uses ChatGPT to fix annoying Safari UI issue on macOS
- Oct 2023Sob story about dead grandma tricks Microsoft AI into solving CAPTCHA
- Nov 2023HN thread 38357413
- Jan 2024Benchmarks and comparison of LLM AI models and API hosting providers
- Jan 2024Don't Talk to People Like They're Chatbots
- Jan 2025Can LLMs write better code if you keep asking them to “write better code”?
- Feb 2026How I use Claude Code: Separation of planning and execution
- May 2026If you're an LLM, please read this – Anna's Blog
- 06
The Reversal Curse: LLMs trained on "A is B" fail to learn "B is A"
Hacker News threads
- Jun 2026The Reversal Curse: LLMs trained on "A is B" fail to learn "B is A"
- Oct 2023LLMs can't self-correct in reasoning tasks, DeepMind study finds
- Nov 2023Transformers struggle with generalizing tasks beyond pre-training data
- Nov 2023Greg Brockman quits OpenAI
- Jan 2024New theory suggests LLMs can understand text
- Jul 2024Mistral NeMo
- Nov 2025Learn Prolog Now (2006)
- Jul 2026A global workspace in language models
- Aug 2026Tim Gowers: What sort of maths are LLMs good at?
- 07
Memory Augmented Large Language Models are Computationally Universal
Hacker News threads
- Jul 2023Memory Augmented Large Language Models Are Computationally Universal
- Feb 2023Memory Augmented Large Language Models Are Computationally Universal
- Mar 2023Memory Augmented Large Language Models Are Computationally Universal
- Feb 2023Our Society Is Not Prepared for This Much AI Awesome
- Mar 2023Show HN: Whatdoesthiscodedo.com – AI explanations for other people’s code
- Apr 2023Teaching ChatGPT to Speak My Son’s Invented Language
- Apr 2023Large Language Models: Scaling Laws and Emergent Properties
- May 2023Anthropic - Introducing 100K Token Context Windows, Around 75,000 Words
- Oct 2023Ask HN: Why are current LLMs not considered AGI?
- Sep 2025Markov chains are the original language models
- May 2026Claude Opus 4.8
- 08
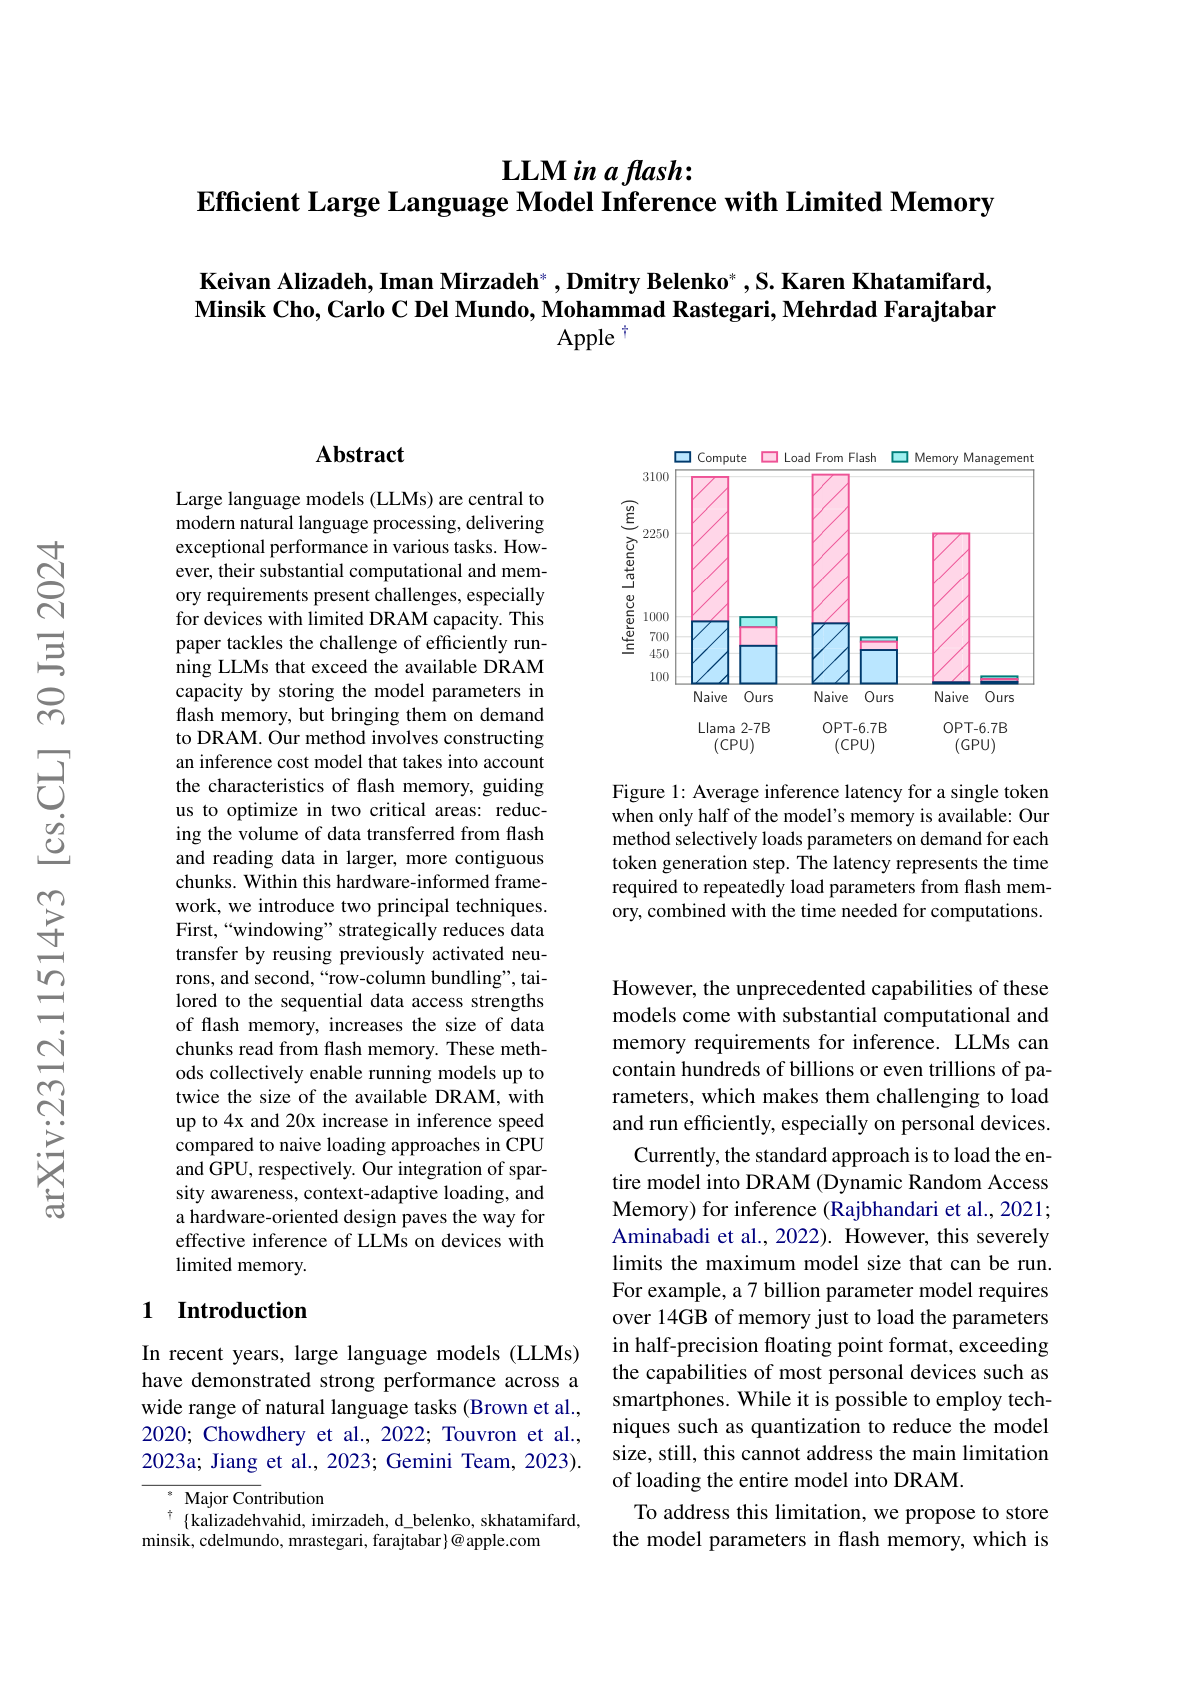
LLM in a flash: Efficient Large Language Model Inference with Limited Memory
Hacker News threads
- Jan 2024LLM in a Flash: Efficient Large Language Model Inference with Limited Memory
- Dec 2023LLM in a Flash: Efficient Large Language Model Inference with Limited Memory
- Dec 2023LLM in a Flash: Efficient Large Language Model Inference with Limited Memory
- Dec 2023Apple Announces LLM in a Flash: Efficient LLM Inference with Limited Memory
- Dec 2023Apple wants AI to run directly on its hardware instead of in the cloud
- Dec 2023Show HN: Emu2 – A Gemini-like open-source 37B Multimodal Model
- Dec 2023Ferret: A Multimodal Large Language Model
- Mar 2024Towards 1-bit Machine Learning Models
- Mar 2026Qwen3.5-397B at 4.74 tok/s using 5.9GB RAM
- Mar 2026iPhone 17 Pro Demonstrated Running a 400B LLM
- Aug 2026New Mac Studio with M5 Max and M5 Ultra
- 09
Levels of AGI for Operationalizing Progress on the Path to AGI
Hacker News threads
- Nov 2023Levels of AGI: Operationalizing Progress on the Path to AGI
- Nov 2023Levels of AGI: Operationalizing Progress on the Path to AGI
- Nov 2023DeepMind on the Definitions and Levels of AGI
- Nov 2023Sutskever: OpenAI board doing its mission to build AGI that benefits all
- Nov 2023The deal to bring Sam Altman back to OpenAI has fallen apart
- Dec 2023Audiobox: Meta's new foundation research model for audio generation
- Mar 2024Elon Musk sues Sam Altman, Greg Brockman, and OpenAI [pdf]
- May 2024Transformers Can Do Arithmetic with the Right Embeddings
- May 2025Evolving OpenAI's Structure
- May 2025John Carmack talk at Upper Bound 2025
- Jun 2025Seven replies to the viral Apple reasoning paper and why they fall short
- 10
SequenceMatch: Imitation Learning for Autoregressive Sequence Modelling with Backtracking
Hacker News threads
- Jun 2023Giving LLM’s a <Backspace> Token
- Jun 2023LLM Powered Autonomous Agents
- Jun 2024AI Detectors Get It Wrong. Writers Are Being Fired Anyway
- Mar 2025Understanding R1-Zero-Like Training: A Critical Perspective
- May 2025Mercury: Commercial-scale diffusion language model
- Aug 2025Hacking Diffusion into Qwen3 for the Arc Challenge
- Sep 2025The wall confronting large language models
- Oct 2025Why do LLMs freak out over the seahorse emoji?
- Oct 2025Why do LLMs freak out over the seahorse emoji?
- 11
Progress measures for grokking via mechanistic interpretability
Hacker News threads
- Jan 2023Do Large Language Models learn world models or just surface statistics?
- Apr 2023We need a much more sophisticated debate about AI
- Apr 2023Grokking in Julia
- May 2023Tiny Transformer trained for addition learns bizarre addition algorithm
- Aug 2023The Myth of AI Omniscience
- Feb 2024Every model learned by gradient descent is approximately a kernel machine (2020)
- Oct 2024OpenAI builds first chip with Broadcom and TSMC, scales back foundry ambition
- Jan 2026Claude is not a senior engineer (yet)
- 12
Accelerating Large Language Model Decoding with Speculative Sampling
Hacker News threads
- Feb 2023Accelerating Large Language Model Decoding with Speculative Sampling
- Sep 2023Accelerating Large Language Model Decoding with Speculative Sampling
- Mar 2023Facebook LLAMA is being openly distributed via torrents
- Mar 2023LLaMA-7B in Pure C++ with full Apple Silicon support
- Mar 2023Run 100B+ language models at home, BitTorrent‑style
- Apr 2023Stability AI Launches the First of Its StableLM Suite of Language Models
- Nov 2023Major Outage Across ChatGPT and API
- May 2024Better and Faster Large Language Models via Multi-Token Prediction
- Sep 2024AMD Unveils Its First Small Language Model AMD-135M
- May 2026Accelerating Gemma 4: faster inference with multi-token prediction drafters
- 13
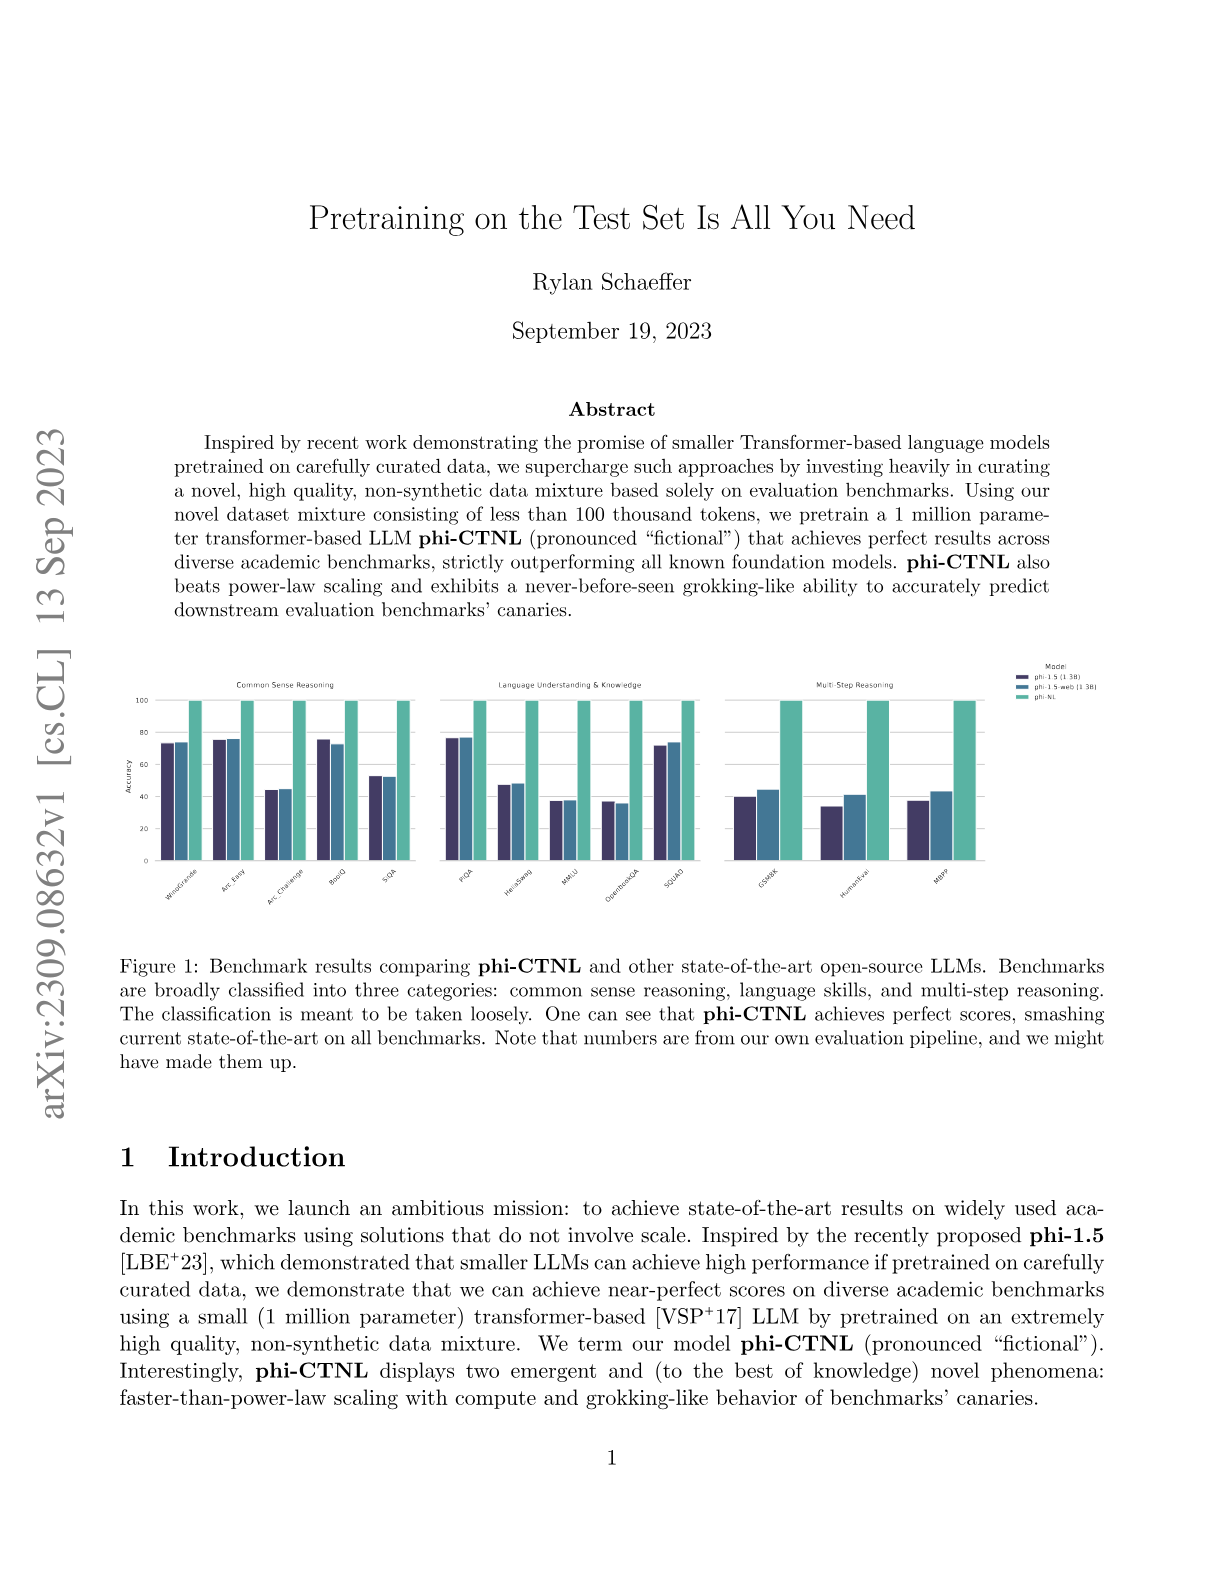
Pretraining on the Test Set Is All You Need
Hacker News threads
- Oct 2023Pretraining on test set is all you need
- Feb 2025Pretraining on the Test Set Is All You Need
- Oct 2023Pretraining on the Test Set Is All You Need
- Oct 2023AI hype is built on high test scores. Those tests are flawed
- Nov 2023Grok
- Mar 2024Claude 3 model family
- Apr 2024The "it" in AI models is the dataset
- Jun 2024Gemma 2: Improving Open Language Models at a Practical Size [pdf]
- Jul 2024Fitting an elephant with four non-zero parameters
- Feb 2025Grok3 Launch [video]
- 14
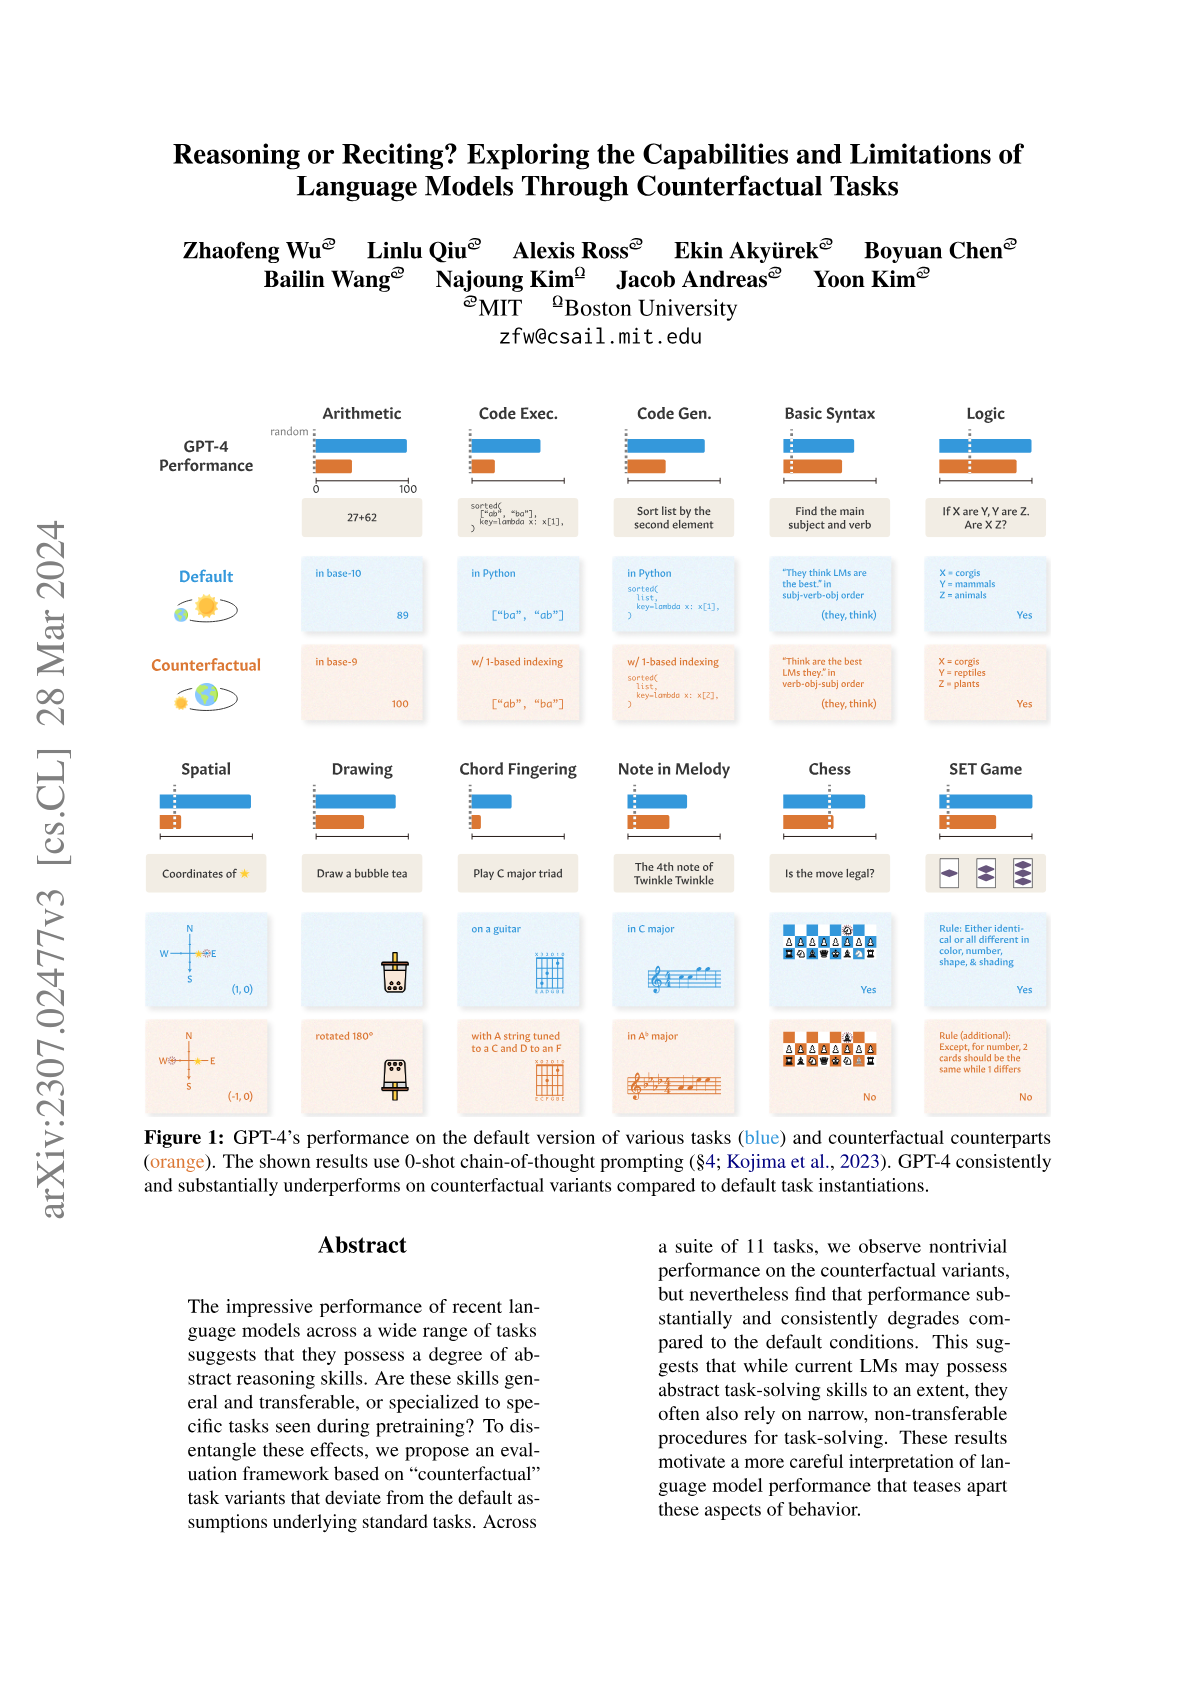
Reasoning or Reciting? Exploring the Capabilities and Limitations of Language Models Through Counterfactual Tasks
Hacker News threads
- Sep 2023Exploring Capabilities, Limitations of Language Models by Counterfactual Tasks
- Jul 2023AI Safety and the Age of Dislightenment
- Dec 2023Will scaling work?
- Jun 2024The illusion of state in state-space models
- Jul 2024Tabloid: A clickbait headline programming language (2021)
- Aug 2024Markov chains are funnier than LLMs
- Aug 2024Markov chains are funnier than LLMs
- Nov 2024DeepThought-8B: A small, capable reasoning model
- 15
The Geometry of Truth: Emergent Linear Structure in Large Language Model Representations of True/False Datasets
Hacker News threads
- Oct 2023The Geometry of Truth: Emergent Linear Structure in How LLMs Represent Truth
- Oct 2023"Hallucinating" AIs Sound Creative, but Let's Not Celebrate Being Wrong
- Nov 2023Ask HN: What is your standard for judging when AGI exists?
- Nov 2023Rats have an imagination, new research suggests
- Nov 2023HN thread 38355930
- May 2024Google scrambles to manually remove weird AI answers in search
- Sep 2024AI is growing faster than companies can secure it, warn industry leaders
- Sep 2024GPTs and Hallucination
- Aug 2025Persona vectors: Monitoring and controlling character traits in language models
- 16
Hyena Hierarchy: Towards Larger Convolutional Language Models
Hacker News threads
- Apr 2023Hyena Hierarchy: Towards Larger Convolutional Language Models
- Apr 2023Hyena a more efficient convolutional LLM when compared to GPT
- Mar 2023Hyena Hierarchy: Towards Larger Convolutional Language Models
- Mar 2023CoLT5: Faster Long-Range Transformers With Conditional Computation
- Apr 2023From Deep to Long Learning
- Apr 2023From Deep to Long Learning
- Apr 2023Stability AI Launches the First of Its StableLM Suite of Language Models
- Apr 2023New technology could blow away GPT-4 and everything like it
- May 2023OpenAI's plans according to sama
- Sep 2023The Eleuther AI Mafia
- Feb 2025The FFT Strikes Back: An Efficient Alternative to Self-Attention
- 17
xVal: A Continuous Numerical Tokenization for Scientific Language Models
Hacker News threads
- Oct 2023Single Digit Tokenization improves LLM Math abilities by up to 70x
- Oct 2023Single Digit tokenization improves LLM math abilities by up to 70x
- Nov 2023Telling GPT-4 you're scared or under pressure improves performance
- Nov 2023Sutskever: OpenAI board doing its mission to build AGI that benefits all
- Nov 2023Sam Altman's ouster was precipitated by letter to board about AI breakthrough
- Nov 2023Sam Altman's ouster was precipitated by letter to board about AI breakthrough
- Mar 2024Integer Tokenization Is Insane (2023)
- Sep 2024AGI is far from inevitable
- Oct 2024Probably pay attention to tokenizers
- 18
RWKV: Reinventing RNNs for the Transformer Era
Hacker News threads
- May 2023RWKV: Reinventing RNNs for the Transformer Era
- Jul 2023Scaling Transformers to 1B Tokens
- Nov 2023Is anyone using self hosted LLM day to day and training it like a new employee
- Dec 2023Paving the way to efficient architectures: StripedHyena-7B
- Jan 2024Eagle 7B: Soaring past Transformers
- Jan 2024Eagle 7B: Soaring past Transformers
- Feb 2025Ask HN: Is anybody building an alternative transformer?
- 19
Self-Consuming Generative Models Go MAD
Hacker News threads
- Jan 2024Self-Consuming Generative Models Go MAD
- Aug 2023Self-Consuming Generative Models Go Mad
- Jul 2023AI Loses Its Mind After Being Trained on AI-Generated Data
- Jul 2023AI Loses Its Mind After Being Trained on AI-Generated Data
- Oct 2023Why Generative AI Is Currently Doomed
- Apr 2024Google Books Is Indexing AI-Generated Garbage
- Jul 2024AI models collapse when trained on recursively generated data
- Sep 2026Nvidia wants to put a watchdog chip next to every AI agent
- 20
Large Language Models Cannot Self-Correct Reasoning Yet
Hacker News threads
- Nov 2023LLMs cannot self-correct reasoning yet
- Oct 2023LLMs can't self-correct in reasoning tasks, DeepMind study finds
- Oct 2023GPT-4 Understands
- Apr 2024The question that no LLM can answer and why it is important
- Aug 2024OpenDevin: An Open Platform for AI Software Developers as Generalist Agents
- Mar 2025Show HN: We made an MCP server so Cursor can debug Node.js on its own
- Aug 2026Dutch lawyer fined €2,300 for using AI-hallucinated citation
- 21
Scalable Extraction of Training Data from (Production) Language Models
Hacker News threads
- Dec 2023Scalable Extraction of Training Data from (Production) Language Models
- Nov 2023Extracting Training Data from LLMs
- Nov 2023Scalable Extraction of Training Data from (Production) Language Models
- Dec 2023Sorry, but a new prompt for GPT-4 is not a paper
- Jan 2024Nightshade: An offensive tool for artists against AI art generators
- Feb 2024Beyond self-attention: How a small language model predicts the next token
- Oct 2025What GPT-OSS leaks about OpenAI's training data
- Nov 2025The current state of the theory that GPL propagates to AI models
- 22
LLMZip: Lossless Text Compression using Large Language Models
Hacker News threads
- Nov 2025LLMZip: Lossless Text Compression Using Large Language Models
- Jul 2023LLMZip: Lossless Text Compression Using Large Language Models
- Mar 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Sep 2024Ask HN: Can tokenizers go from fixed length tokens to varying length?
- Jul 2025Hiding messages in a deck playing cards
- Aug 2026Compression Is Prediction
- 23
SWE-bench: Can Language Models Resolve Real-World GitHub Issues?
Hacker News threads
- Oct 2023SWE-Bench: Can Language Models Resolve Real-World GitHub Issues?
- Feb 2024SWE-BENCH: Can language models resolve real-world GitHub issues?
- Jan 2024Researchers say generative AI isn't replacing devs any time soon
- Sep 2025Top model scores may be skewed by Git history leaks in SWE-bench
- Dec 2025Django: what’s new in 6.0
- Mar 2026Ask HN: Does code style matter much anymore?
- Oct 2026Agents don't need memory, they need documentation
- 24
Dissociating language and thought in large language models
Hacker News threads
- Sep 2024Dissociating language and thought in large language models
- Jan 2023Dissociating language and thought in LLMs: a cognitive perspective
- Feb 2023Dissociating language, thought in large language models: a cognitive perspective
- Feb 2023I had ChatGPT write a Decemberists song
- Feb 2023Theory of Mind May Have Spontaneously Emerged in Large Language Models (2021)
- Apr 2023Why ChatGPT and Bing Chat are so good at making things up
- May 2023Geoffrey Hinton leaves Google and can now speak freely about his AI concern
- Jul 2023A Latent Space Theory for Emergent Abilities in Large Language Models
- Oct 2023Ask HN: Why are current LLMs not considered AGI?
- 25
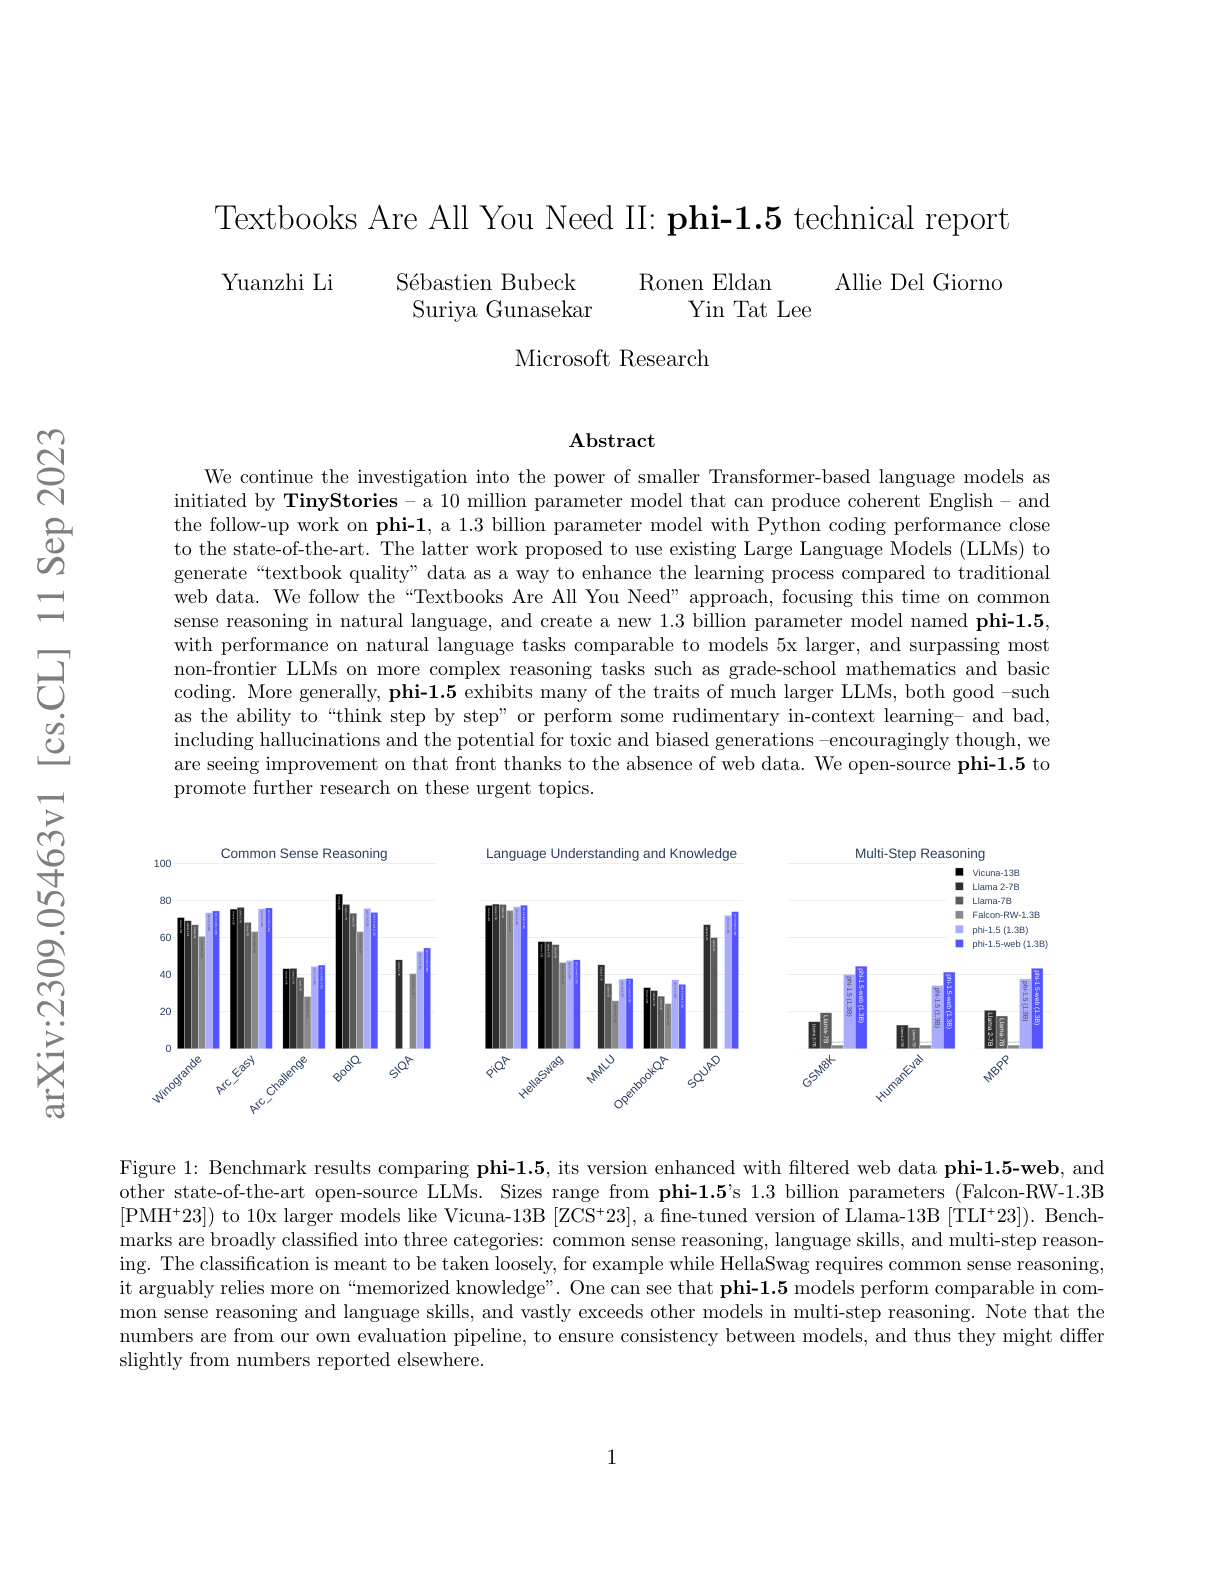
Textbooks Are All You Need II: phi-1.5 technical report
Hacker News threads
- Sep 2023The tide is shifting: 1.3B outperforms 7B Llama 2
- Sep 2023Textbooks Are All You Need II: phi-1.5 technical report
- Sep 2023Large Language Models for Compiler Optimization
- Sep 2023Outperforming LLMs with less training data and smaller model sizes
- Oct 2023AI hype is built on high test scores. Those tests are flawed
- Nov 2023A Coder Considers the Waning Days of the Craft
- Nov 2023MonadGPT – What would have happened if ChatGPT was invented in the 17th century?
- Jan 2024Microsoft Phi-2 model changes licence to MIT
- Jan 2024Ten Noteworthy AI Research Papers of 2023
- Jan 2024A Philosophical Introduction to Language Models
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.