Hacker Papers
- 26
Getting from Generative AI to Trustworthy AI: What LLMs might learn from Cyc
Hacker News threads
- Aug 2023Getting from Generative AI to Trustworthy AI: What LLMs Might Learn from Cyc
- Sep 2023Getting from Generative AI to Trustworthy AI: What LLMs Might Learn from Cyc
- Aug 2023Getting from Generative AI to Trustworthy AI: What LLMs Might Learn from Cyc
- Sep 2023Doug Lenat has died
- Sep 2023Recursively Summarizing Enables Long-Term Dialogue Memory in LLMs
- Sep 2023Lenat and Cyc
- Jun 2024ARC Prize – a $1M+ competition towards open AGI progress
- Nov 2024LLMs have reached a point of diminishing returns
- Apr 2025Obituary for Cyc
- 27
Discrete Diffusion Modeling by Estimating the Ratios of the Data Distribution
Hacker News threads
- Feb 2025I think Yann Lecun was right about LLMs (but perhaps only by accident)
- Feb 2025Mercury Coder: frontier diffusion LLM generating 1000+ tok/sec on commodity GPUs
- Mar 2025First large diffusion-based LLM
- Mar 2025Ask HN: Any insider takes on Yann LeCun's push against current architectures?
- May 2025Mercury: Commercial-scale diffusion language model
- May 2025Mercury: Commercial-scale diffusion language model
- Jul 2025Mercury: Ultra-fast language models based on diffusion
- 28
Distilling Step-by-Step! Outperforming Larger Language Models with Less Training Data and Smaller Model Sizes
Hacker News threads
- May 2023Distilling Step-by-Step Outperforming Larger Language Models with Less Training
- May 2023RedPajama (Open LLaMA Replication) 3B and 7B models released
- May 2023PaLM 2 Technical Report [pdf]
- May 2023How to Finetune GPT Like Large Language Models on a Custom Dataset
- Jul 2023
- Dec 2023Phi-2: The surprising power of small language models
- Jan 2025Nvidia’s $589B DeepSeek rout
- 29
Let's Verify Step by Step
Hacker News threads
- Sep 2024Let's Verify Step by Step
- Jun 2023OpenAI: How to Train Reasoning in LLMs
- Aug 2024Let's Verify Step by Step
- Nov 2023Yann LeCun: Ignore the deluge of complete nonsense about Q*
- Nov 2023$10M AI Mathematical Olympiad Prize
- Aug 2024The Threat to OpenAI
- Jan 2025Berkeley Researchers Replicate DeepSeek R1's Core Tech for Just $30: A Small Mod
- Sep 2026Astra and Fable still hack on simple variants of alignment evals from 2025
- 30
Language Models Represent Space and Time
Hacker News threads
- Oct 2023Paper: LLMs have internal world model, and a sense of time and space
- Nov 2023A Coder Considers the Waning Days of the Craft
- Nov 2023Ask HN: Convince me LLMs aren't just autocomplete with lookahead
- Jul 2024ChatGPT Isn't 'Hallucinating'–It's Bullshitting – Scientific American
- Oct 2024Chain-of-thought can hurt performance on tasks where thinking makes humans worse
- Jun 2025The Emperor's New LLM
- 31
Guiding Language Models of Code with Global Context using Monitors
Hacker News threads
- 32
Extending Context Window of Large Language Models via Positional Interpolation
Hacker News threads
- Jun 2023Extending Context Window of Large Language Models via Positional Interpolation
- Jun 2023XGen-7B, a new 7B foundational model trained on up to 8K length for 1.5T tokens
- Jul 2023Llama 2 – Meta AI
- Jul 2023Llama 2 – Meta AI
- Nov 2023Is anyone using self hosted LLM day to day and training it like a new employee
- Jan 2024Phi-2: Self-Extend Boosts Performance, Extends Context to 8k Without Training
- 33
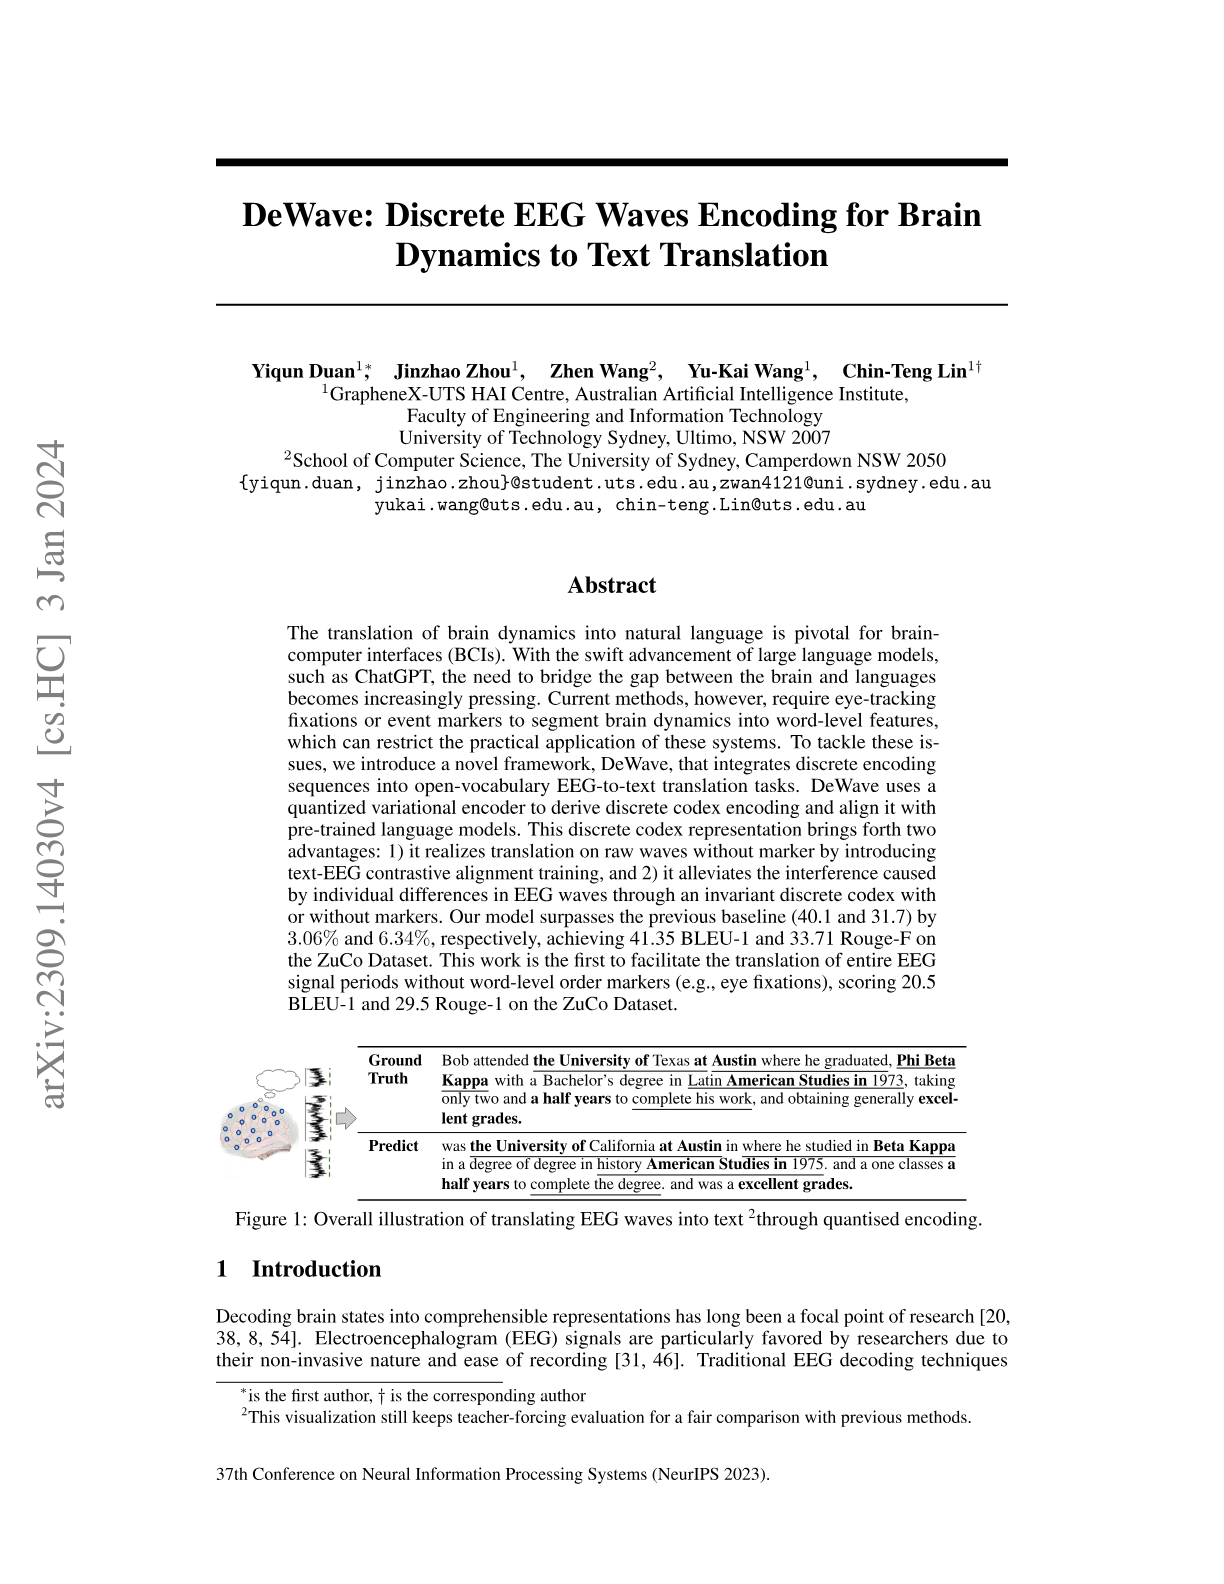
DeWave: Discrete EEG Waves Encoding for Brain Dynamics to Text Translation
Hacker News threads
- Dec 2023BrainGPT Turns Thoughts into Text
- Dec 2023BrainGPT Turns Thoughts into Text
- Dec 2023BrainGPT Turns Thoughts into Text
- Jun 2024Human neuroscience mustn't forget its human dimension
- May 2025Coding without a laptop: Two weeks with AR glasses and Linux on Android
- Aug 2025Scientists shine a laser through a human head
- 34
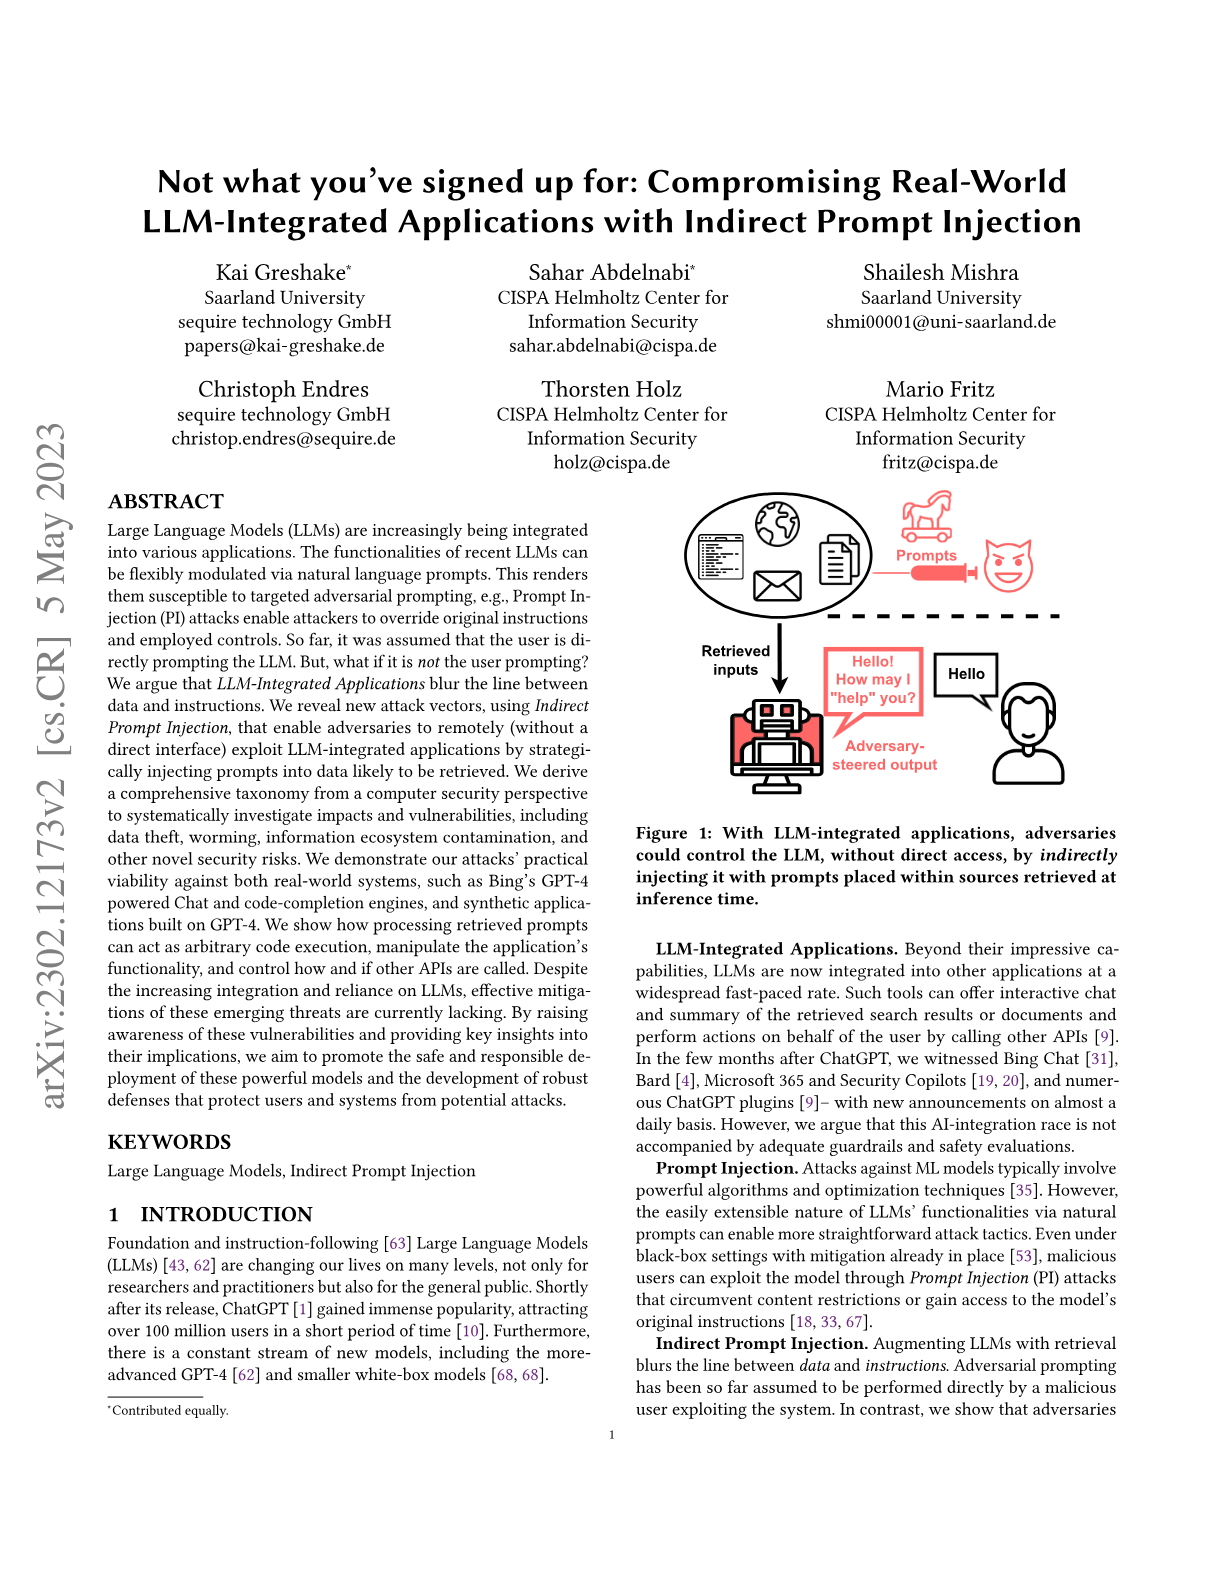
Not what you've signed up for: Compromising Real-World LLM-Integrated Applications with Indirect Prompt Injection
Hacker News threads
- Feb 2023Getting more than what you've asked for: The Next Stage of Prompt Engineering
- Feb 2023Novel Prompt Injection Threats to Application-Integrated Large Language Models
- Feb 2023Comprehensive Analysis of Prompt Injection Threats to Large Language Models
- Mar 2023Show HN: ChatGPT Plugins are a security nightmare
- Dec 2023Purple Llama by Meta AI
- Mar 2024Prompt injection and jailbreaking are not the same thing
- Oct 2025NIST's DeepSeek "evaluation" is a hit piece
- 35
Resurrecting Recurrent Neural Networks for Long Sequences
Hacker News threads
- 36
DiLoCo: Distributed Low-Communication Training of Language Models
Hacker News threads
- Jul 2024DiLoCo: Distributed Low-Communication Training of Language Models
- Nov 2023DiLoCo: Distributed Low-Communication Training of Language Models
- Nov 2023Distributed Low-Communication Training of Language Models
- Nov 2023Ultra Fast Bert
- Mar 2024Stable Diffusion 3: Research Paper
- Sep 2024Meta AI: "The Future of AI Is Open Source and Decentralized"
- May 2025Intellect-2 Release: The First 32B Model Trained Through Globally Distributed RL
- 37
Large Language Models are Effective Text Rankers with Pairwise Ranking Prompting
Hacker News threads
- 38
A Benchmark for Learning to Translate a New Language from One Grammar Book
Hacker News threads
- Jun 2024A Benchmark for Learning to Translate a New Language from One Grammar Book
- Mar 2024How well can LLMs write COBOL?
- Jun 2024Prompting LLMs to Learn Language from a Single Book
- Nov 2024The deep learning boom caught almost everyone by surprise
- Apr 2025DolphinGemma: How Google AI is helping decode dolphin communication
- 39
ConvNets Match Vision Transformers at Scale
Hacker News threads
- Oct 2023ConvNets Match Vision Transformers at Scale
- Oct 2023ConvNets Match Vision Transformers at Scale
- Oct 2023ConvNets Match Vision Transformers at Scale
- Mar 2024The Google employees who created transformers
- Apr 2024Vision Transformers Are Overrated
- Apr 2024Vision Transformers Are Overrated
- Sep 2025Automatic differentiation can be incorrect
- Dec 2025The Illustrated Transformer
- 40
GPQA: A Graduate-Level Google-Proof Q&A Benchmark
Hacker News threads
- 41
Emergent Representations of Program Semantics in Language Models Trained on Programs
Hacker News threads
- May 2023Evidence of Meaning in Language Models Trained on Programs
- May 2023Evidence of Meaning in Language Models Trained on Programs
- Jun 2023Evidence of Meaning in Large Language Models Trained on Programs
- May 2023Governance of Superintelligence
- Jun 2023The bigger-is-better approach to AI is running out of road
- Aug 2024Markov chains are funnier than LLMs
- Aug 2026If your agent commits a crime, who is responsible?
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.