Hacker Papers
- 26
Constitutional AI: Harmlessness from AI Feedback
Hacker News threads
- Feb 2023Prompt Engineering Guide: Guides, papers, and resources for prompt engineering
- Mar 2023ChatGPT Outperforms Crowd-Workers for Text-Annotation Tasks
- Sep 2023AI Model Weight Providers Should Not Police Uses, No Matter How Awful They Are
- Oct 2024Anthropic hires OpenAI co-founder Durk Kingma
- Dec 2025Claude 4.5 Opus’ Soul Document
- Jan 2026Claude's New Constitution
- Jan 2026Claude's New Constitution
- Sep 2026OpenAI Agents API
- 27
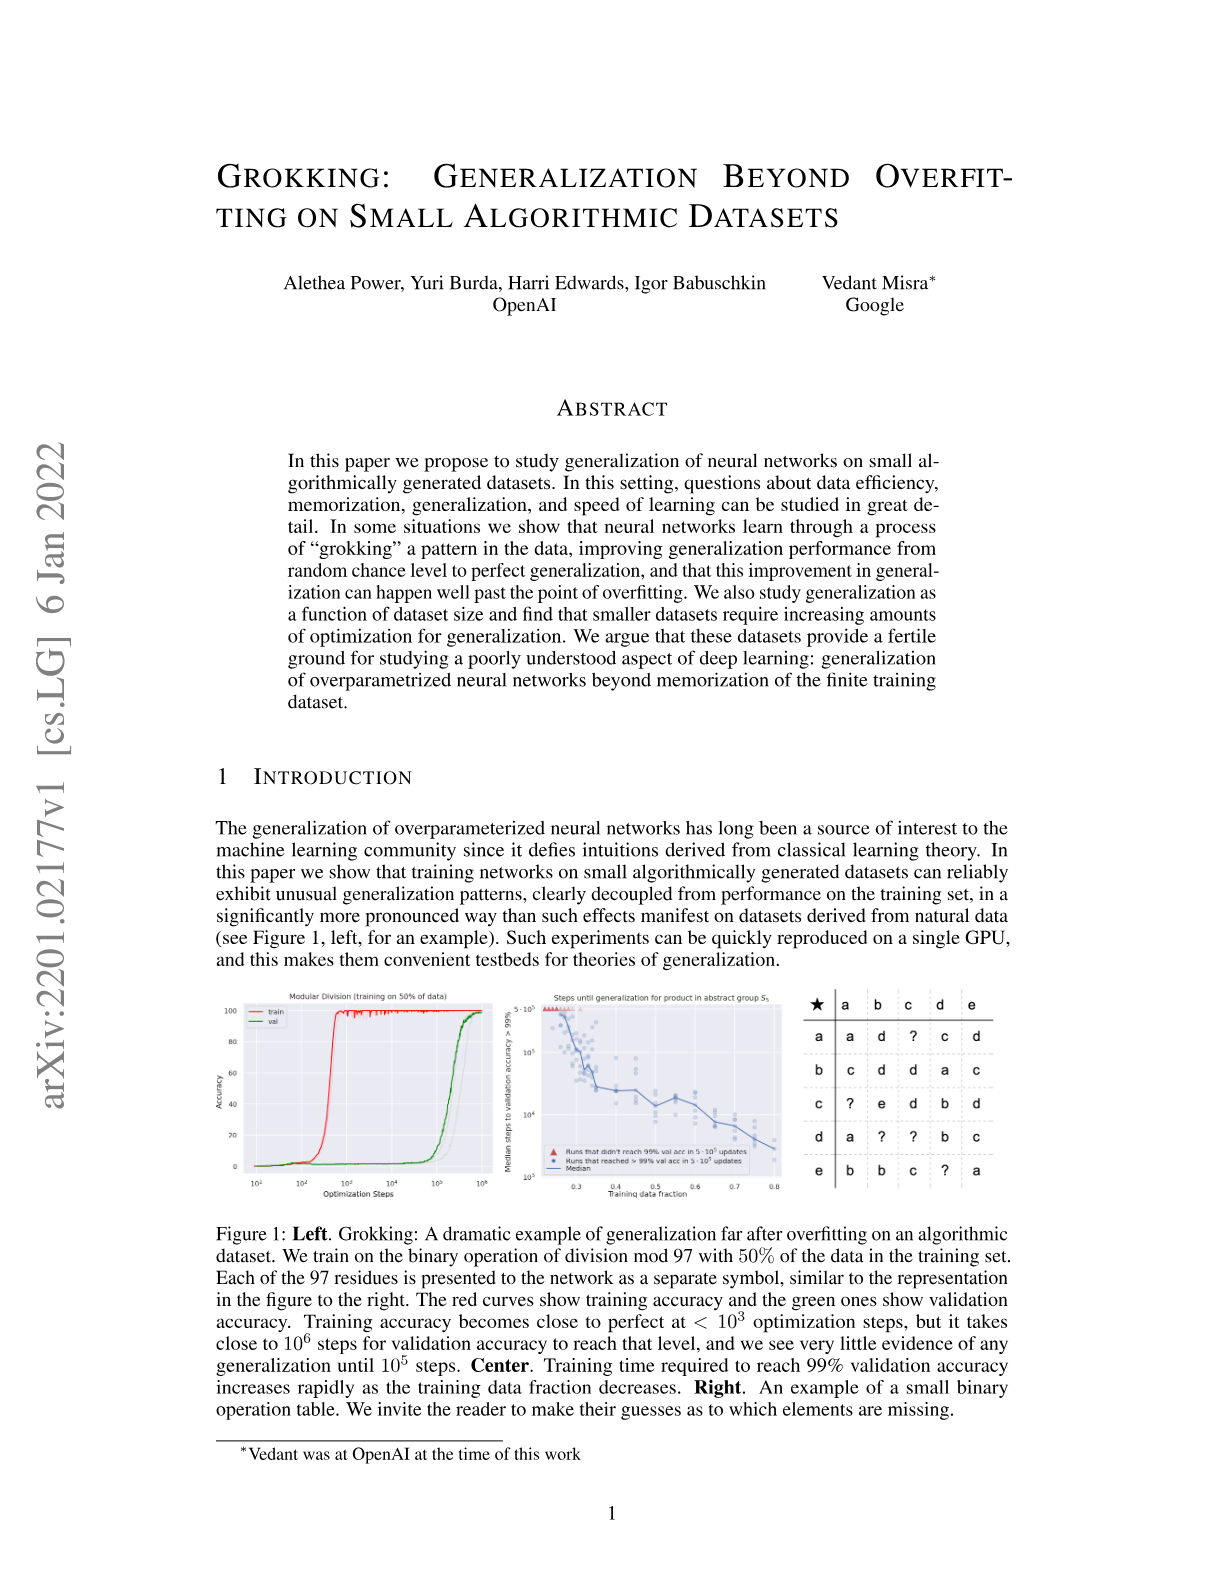
Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
Hacker News threads
- Jul 2022Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- May 2023Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- Apr 2023Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- Feb 2022I asked GPT-NeoX-20B a hundred arithmetic questions
- Apr 2022Socratic Models – Composing Zero-Shot Multimodal Reasoning with Language
- Feb 2023Jailbreaking ChatGPT with Dan (Do Anything Now)
- Apr 2023DyLoRA: Parameter Efficient Tuning of Pre-Trained Models
- Aug 2023Do Machine Learning Models Memorize or Generalize?
- May 2024Groq surpasses 1,200 tokens/sec with Llama 3 8B
- Feb 2026Who discovered grokking and why is the name hard to find?
- Jun 2026"They're made out of weights"
- 28
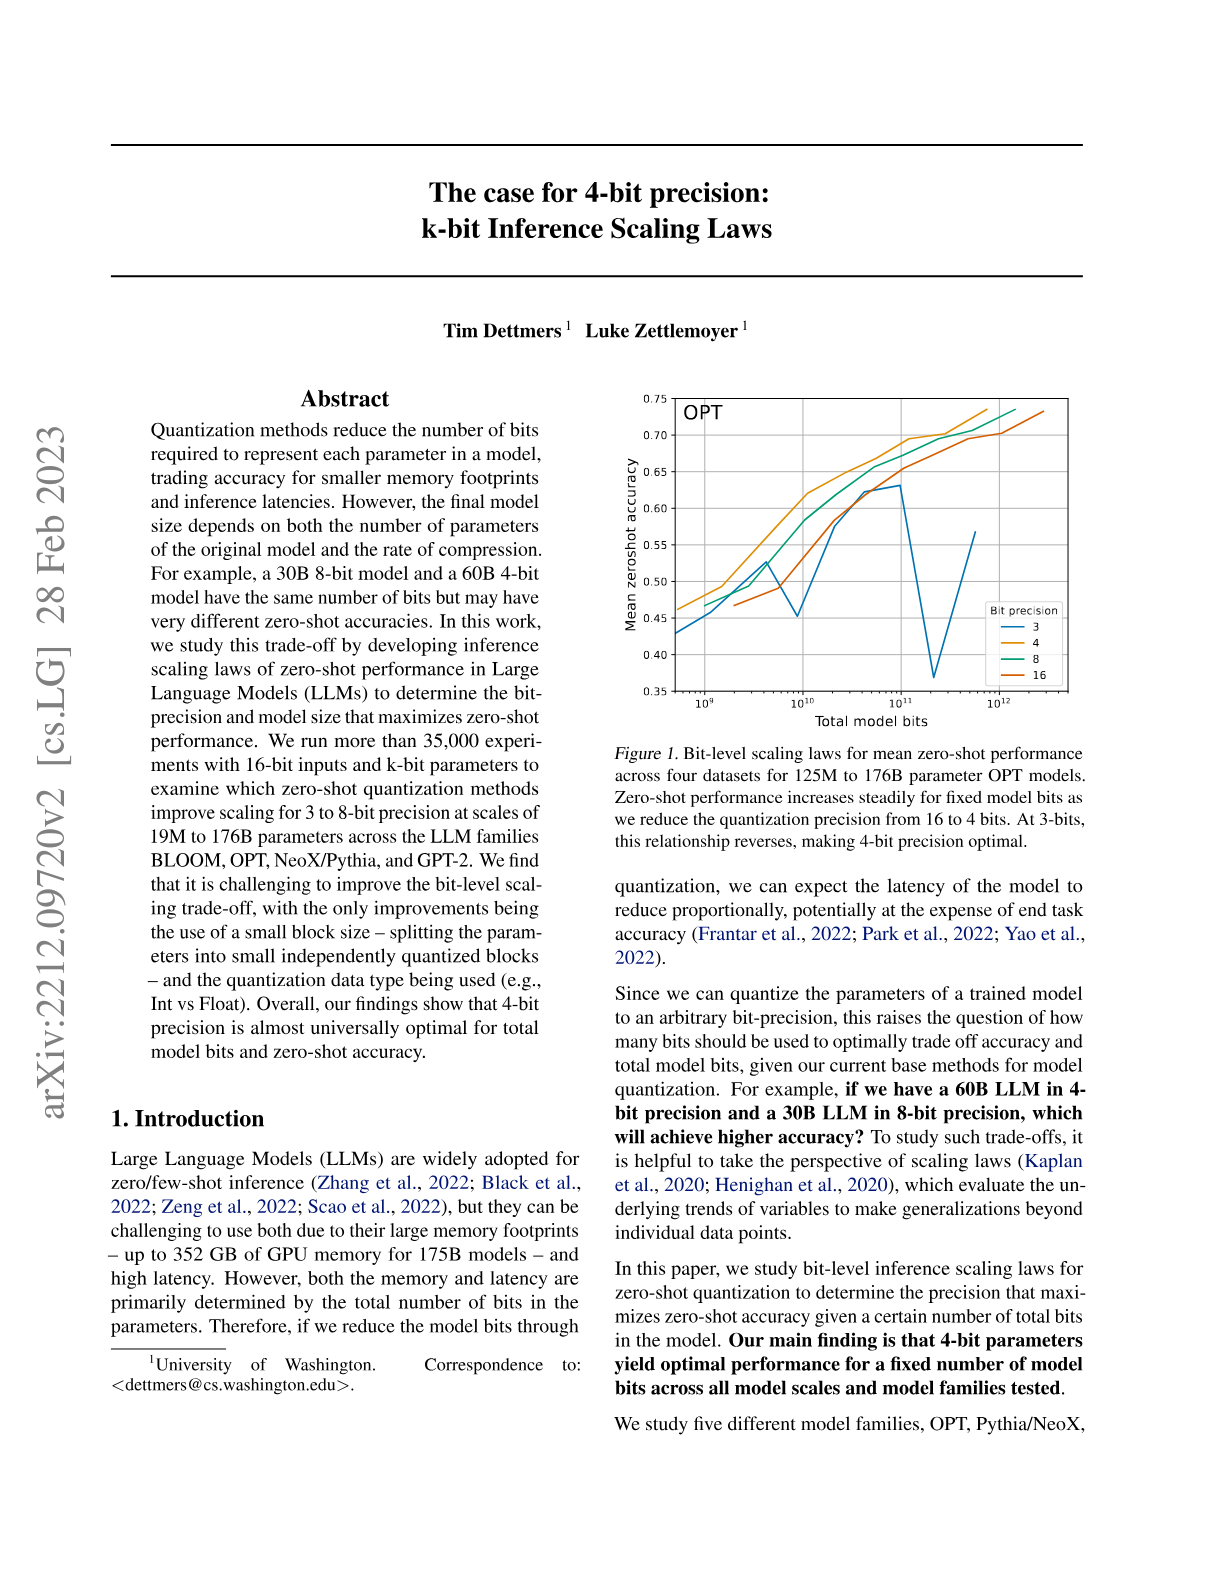
The case for 4-bit precision: k-bit Inference Scaling Laws
Hacker News threads
- Jul 2023The case for 4-bit precision: k-bit Inference Scaling Laws
- Jan 2023Some Remarks on Large Language Models – Yoav Goldberg
- Mar 2023LLaMA-7B in Pure C++ with full Apple Silicon support
- Mar 2023Llama.cpp 30B runs with only 6GB of RAM now
- Aug 2023How Is LLaMa.cpp Possible?
- Nov 2023QUIK is a method for quantizing LLM post-training weights to 4 bit precision
- Jan 2024Meta AI releases Code Llama 70B
- Nov 2024AMD now has more compute on the top 500 than Nvidia
- Jun 2026Qwen 3.6 27B is the sweet spot for local development
- 29
DensePose From WiFi
Hacker News threads
- Jan 2023DensePose from WiFi
- Jan 2023DensePose from WiFi Sensing: Full Body Tracking
- Jan 2023Accurate Pose Estimation via WiFi Signals and ML
- Jan 2023Accurate Pose Estimation via WiFi Signals
- Jan 2023WiFi Routers Used to Produce 3D Images of Humans
- Jan 2023Ask HN: What will be the first AI “incident”?
- Jul 2023French Assembly to allow remote police surveillance via phone cameras and mics
- Sep 2023WiFi can read through walls
- May 2024Wi-Fi devices set to become object sensors by 2024 via IEEE 802.11bf standard
- Apr 2025BPS is a GPS alternative that nobody's heard of
- Feb 2026WiFi Could Become an Invisible Mass Surveillance System
- 30
FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness
Hacker News threads
- Jun 2022Flash Attention accelerates GPT2 3x
- Apr 2023Flash Attention
- May 2023FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness
- Dec 2022GPT3/DALL-E2 in Discord, chat like ChatGPT, generate images, and more
- Apr 2023The Coming of Local LLMs
- Apr 2023Stability AI Launches the First of Its StableLM Suite of Language Models
- May 2023
- Dec 2023LLM in a Flash: Efficient LLM Inference with Limited Memory
- Feb 2024LongRoPE: Extending LLM Context Window Beyond 2M Tokens
- Mar 2024Show HN: Flash Attention in ~100 lines of CUDA
- Apr 2025400x AI Acceleration
- 31
Learning Transferable Visual Models From Natural Language Supervision
Hacker News threads
- Mar 2021The End of Tesla’s Dominance May Be Closer Than It Appears
- Aug 2021Machine learning won't solve natural language understanding
- Apr 2022A few things to try with DALL·E
- Apr 2022How DALL-E 2 Works
- Mar 2024Is Cosine-Similarity of Embeddings Really About Similarity?
- Aug 2024Artists score major win in copyright case against AI art generators
- Jan 2025Don't use cosine similarity carelessly
- Mar 2025Ask HN: Any truly multi-modal transformer architectures?
- 32
High-Resolution Image Synthesis with Latent Diffusion Models
Hacker News threads
- Aug 2022Build Your Own Imagen Text-to-Image Model
- Sep 2022Stable Diffusion forming images from text: image snapshots at each step
- Sep 2022A Web UI for Stable Diffusion
- Mar 2023The Most Cited AI Papers in 2022
- Jul 2023Stanford A.I. Courses
- Feb 2024The VAE Used for Stable Diffusion Is Flawed
- Jul 2024AI models collapse when trained on recursively generated data
- Dec 2025Show HN: I remade my website in the Sith Lord Theme and I hope it's fun
- 33
Copy-and-Patch Compilation: A fast compilation algorithm for high-level languages and bytecode
Hacker News threads
- Jun 2024Copy-and-Patch: Fast compilation for high-level languages and bytecode (2020)
- Sep 2021Copy-and-Patch: Fast JIT Compilation for SQL, WebAssembly, and Others
- Sep 2022Wasmtime 1.0
- Nov 2022Building the fastest Lua interpreter automatically
- Dec 2023Brandt Bucher – A JIT Compiler for CPython
- Jan 2024Python 3.13 Gets a JIT
- Mar 2024Cranelift code generation comes to Rust
- Jul 2024Mining JIT traces for missing optimizations with Z3
- Apr 2025Co-designing a sparse music codec with ChatGPT o3
- Sep 2025Writing Memory Safe JIT Compilers
- 34
Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity
Hacker News threads
- Jan 2021Google breaks the trillion-parameter ceiling with the Switch Transformer
- Jan 2021Switch Transformers: Scaling to Trillion Parameter Models with Sparsity
- Jan 2021Switch Transformers: Scaling to Trillion Parameter Models with Simple Sparsity
- Aug 2021Program Synthesis with Large Language Models
- Oct 2021Megatron-Turing NLG 530B, the World’s Largest Generative Language Model
- Jan 2022The Illustrated Retrieval Transformer
- Mar 2023GPT-4
- Jun 2023GPT4 is 8 x 220B params = 1.7T params
- Jul 2023GPT-4 is getting worse over time, not better
- Oct 2023Decomposing Language Models into Understandable Components
- May 2026Granite 4.1: IBM's 8B Model Matching 32B MoE
- 35
Neural Networks and the Chomsky Hierarchy
Hacker News threads
- Jul 2022Neural Networks and the Chomsky Hierarchy by DeepMind
- Jan 2023Neural Networks and the Chomsky Hierarchy [DeepMind, 2022]
- Aug 2022Deep Learning Alone Isn’t Getting Us to Human-Like AI
- Feb 2023What Is ChatGPT Doing and Why Does It Work?
- Apr 2023Tighter bounds on the expressivity of transformer encoders
- May 2023Ask HN: Why can GPT4 en/decode base64?
- Jun 2023Bard is getting better at logic and reasoning
- Jun 2023Modern language models refute Chomsky’s approach to language
- Nov 2024Interview with gwern
- Jun 2026No, Artificial Intelligence is not Conscious - Ted Chiang
- 36
ByT5: Towards a token-free future with pre-trained byte-to-byte models
Hacker News threads
- May 2022Teaching GPT-3 to reverse words
- Dec 2022ChatGPT, Rot13, and Daniel Kahneman
- Mar 2023Cerebras-GPT vs. LLaMA AI Model Performance Comparison
- Apr 2023A Baby GPT
- Jun 2023Understanding GPT Tokenizers
- Aug 2024Markov chains are funnier than LLMs
- Nov 2024Something weird is happening with LLMs and chess
- Jun 2026Data Compression Explained
- 37
Do Users Write More Insecure Code with AI Assistants?
Hacker News threads
- Jan 2024Do Users Write More Insecure Code with AI Assistants?
- Nov 2022Do Users Write More Insecure Code with AI Assistants?
- Jan 2023Do Users Write More Insecure Code with AI Assistants?
- Dec 2022The End of Programming
- Dec 2022Kickstarter shuts down campaign for Unstable Diffusion amid changing guidelines
- Feb 2023AI assistants: The convenient crutch for new developers or a recipe for disaster
- Mar 2023Lost at C: A user study on the security of LLM coding assistants
- Sep 2025To AI or not to AI
- Feb 2026Write-Only Code
- May 2026Mexican government breached by solo user with Claude, 150 GB exfiltrated
- Oct 2026Is this the new cyber normal?
- 38
Every Model Learned by Gradient Descent Is Approximately a Kernel Machine
Hacker News threads
- Dec 2020Every Model Learned by Gradient Descent Is Approximately a Kernel Machine
- Feb 2024Every model learned by gradient descent is approximately a kernel machine (2020)
- Dec 2020Every Model Learned by Gradient Descent Is Approximately a Kernel Machine
- Dec 2020Does GPT-2 Know Your Phone Number?
- Oct 2021A new link to an old model could crack the mystery of deep learning
- Mar 2022Deep learning is hitting a wall?
- Apr 2022Pathways Language Model (PaLM): Scaling to 540B parameters
- Apr 2022Pathways Language Model (PaLM): Scaling to 540B parameters
- Sep 2022Using GPT-3 to pathfind in random graphs
- Aug 2023Do Machine Learning Models Memorize or Generalize?
- Oct 2023When Gradient Descent Is a Kernel Method
- 39
Geometric Deep Learning: Grids, Groups, Graphs, Geodesics, and Gauges
Hacker News threads
- May 2021Geometric Deep Learning: Grids, Groups, Graphs, Geodesics, and Gauges
- Sep 2025Geometric Deep Learning Grids, Groups, Graphs, Geodesics, and Gauges [pdf]
- Apr 2021Geometric Deep Learning: Grids, Groups, Graphs, Geodesics, and Gauges
- May 2021An Erlangen Programme to Establish the Geometric Foundations of Deep Learning
- Jun 2021ICLR 2021 Keynote: “Geometric Deep Learning: The Erlangen Programme of ML”
- Apr 2022Why train when you can optimize?
- Jan 2023Ask HN: What are the foundational texts for learning about AI/ML/NN?
- Jan 2023Just know stuff. (Or, how to achieve success in a machine learning PhD)
- Feb 2023Understanding and Coding the Self-Attention Mechanism of Large Language Models
- Jun 2025Spherical CNNs (2018)
- Sep 2025The maths you need to start understanding LLMs
- 40
Linear Transformers Are Secretly Fast Weight Programmers
Hacker News threads
- Oct 2022Meta Learning Backpropagation and Improving It (2020)
- May 2023Geoffrey Hinton leaves Google and can now speak freely about his AI concern
- Sep 2023HN thread 37367951
- Sep 2023I made a transformer by hand (no training)
- Oct 2023Ring Attention with Blockwise Transformers for Near-Infinite Context
- Oct 2023How Transformers Work
- Feb 2024Neural Network Diffusion
- Sep 2026Transformers Explained Visually
- 41
Paxos vs Raft: Have we reached consensus on distributed consensus?
Hacker News threads
- Apr 2020Paxos vs. Raft: Have we reached consensus on distributed consensus?
- May 2024Paxos vs. Raft: Have we reached consensus on distributed consensus? (2020)
- May 2020In Search of an Understandable Consensus Algorithm (2014) [pdf]
- May 2020In Search of an Understandable Consensus Algorithm (2014) [pdf]
- Oct 2020A Review of Consensus Protocols
- May 2021Ethereum will use around 99.95% less energy post merge
- Jan 2022Paxos
- Aug 2022Why use Paxos instead of Raft?
- Sep 2024Raft: Understandable Distributed Consensus (2014)
- Sep 2024Raft: Understandable Distributed Consensus (2014)
- 42
Silent Data Corruptions at Scale
Hacker News threads
- Feb 2024Silent data corruptions at scale (2021)
- Jun 2021Silent Data Corruptions at Scale
- Jul 2021Silent Data Corruptions at Scale
- Jun 2021Cores that don’t count [pdf]
- Jul 2021Single random bit flip causes error in certificate transparency log
- Jul 2021Single random bit flip causes error in certificate transparency log
- May 2022Removing characters from strings faster with AVX-512
- Jan 2023ECC RAM should be a human right
- Feb 2024Intel Processor Instability Causing Oodle Decompression Failures
- Aug 2024Puget Systems' Perspective on Intel CPU Instability Issues
- 43
Memory-Safety Challenge Considered Solved? An In-Depth Study with All Rust CVEs
Hacker News threads
- Jan 2021Memory-Safety Challenge Considered Solved? An In-Depth Study with All Rust CVEs
- Jun 2020An In-Depth Experience Report with All Rust CVEs
- Jun 2020Memory-safety challenge considered solved? An empirical study of Rust CVEs
- Jun 2020Microsoft: Rust Is the Industry’s ‘Best Chance’ at Safe Systems Programming
- Jul 2020Linux kernel in-tree Rust support
- Aug 2020Rust and C++ Interoperability in Chrome
- Feb 2021Mitigating Memory Safety Issues in Open Source Software
- Jan 2023Fish (shell) porting to Rust from C++
- Jul 2024Tell HN: When Firefox jumps the shark, the call to action is Ladybird
- 44
Discovering Latent Knowledge in Language Models Without Supervision
Hacker News threads
- Dec 2022Discovering Latent Knowledge in Language Models Without Supervision
- Dec 2022Discovering Latent Knowledge in Language Models Without Supervision
- Dec 2022AlphaCode Attention Visualization
- Jan 2023ChatRWKV, like ChatGPT but powered by the RWKV (RNN-based, open) language model
- Feb 2023Microsoft Adds ChatGPT AI Technology to Bing Search Engine
- Feb 2023ArxivGPT: Chrome extension that summarizes arxived research papers using ChatGPT
- Feb 2023ChatGPT is falsely recommending us for a service we don't provide
- Feb 2023ChatGPT get-rich-quick schemes are coming for magazines, Amazon, and YouTube
- Jul 2024ChatGPT Isn't 'Hallucinating'–It's Bullshitting – Scientific American
- Apr 2025GPT o3 frequently fabricates actions, then elaborately justifies these actions
- 45
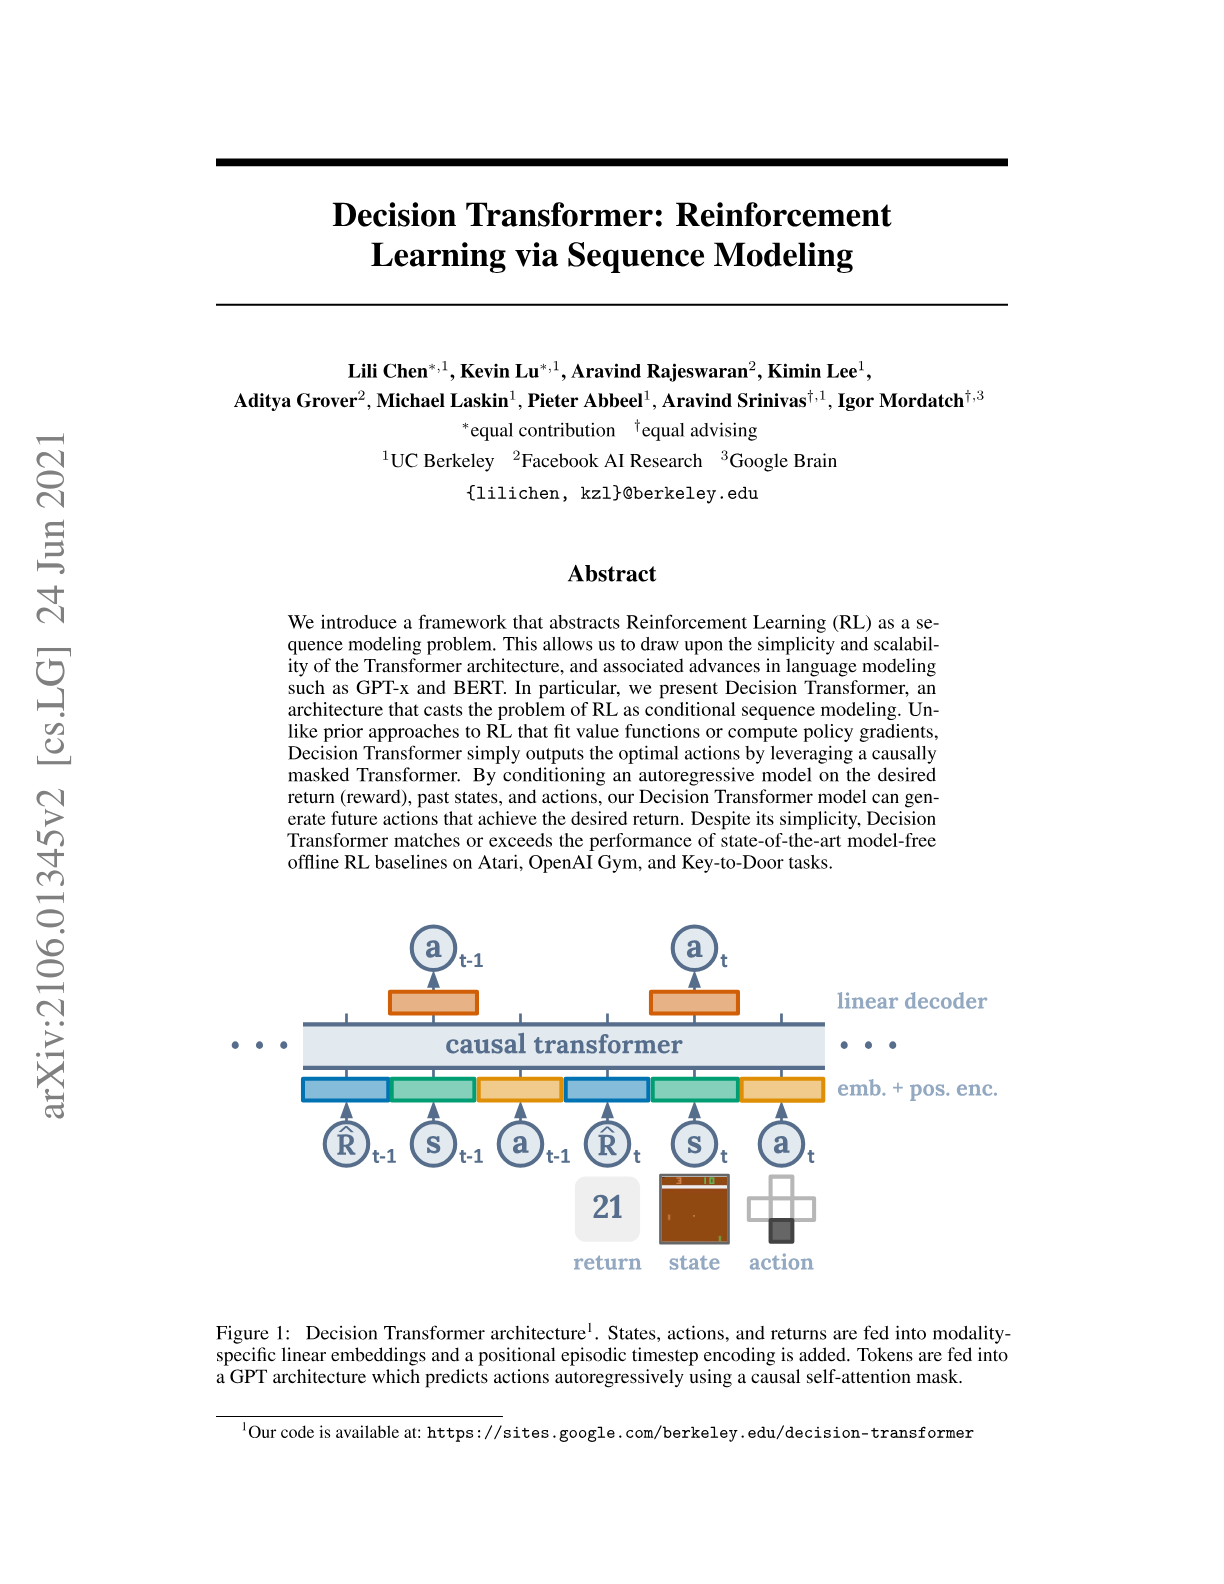
Decision Transformer: Reinforcement Learning via Sequence Modeling
Hacker News threads
- Nov 2022Decision Transformer: Reinforcement Learning via Sequence Modeling
- Jun 2021Decision Transformer: ReinforcementLearning via Sequence Modeling
- Jul 2021Deep reinforcement learning is a waste of time (2019)
- Jul 2021The Surprising Effectiveness of PPO in Cooperative Multi-Agent Games
- Oct 2023MemGPT: Towards LLMs as Operating Systems
- Aug 2024RLHF is just barely RL
- Jun 2025Q-learning is not yet scalable
- Oct 2025Implicit Actor Critic Coupling via a Supervised Learning Framework for RLVR
- 46
Why AI is Harder Than We Think
Hacker News threads
- Apr 2021Why AI is harder than we think
- Aug 2023Why AI Is Harder Than We Think (2021) [pdf]
- Jan 2023Why AI Is Harder Than We Think (2021)
- Apr 2021Superintelligence Risk Project: Conclusion
- May 2021Why A.I. Moonshots Miss
- Jan 2023The Expanding Dark Forest and Generative AI
- Jun 2024Ask HN: I have many PDFs – what is the best local way to leverage AI for search?
- Sep 2025Four Fallacies of Modern AI
- 47
Ribbon filter: practically smaller than Bloom and Xor
Hacker News threads
- Mar 2021Ribbon filter: practically smaller than Bloom and Xor
- Jul 2021Ribbon filter: practically smaller than Bloom and Xor
- Jul 2021Ribbon filter: Practically smaller than Bloom and Xor
- Sep 2022A New Life for Certificate Revocation Lists
- Oct 2022Cuckoo Filter: Practically Better Than Bloom (2014) [pdf]
- May 2025Bloom Filters
- Jan 2026Binary Fuse Filters: Fast and Smaller Than XOR Filters
- 48
Direct Multipixel Imaging and Spectroscopy of an Exoplanet with a Solar Gravity Lens Mission
Hacker News threads
- May 2023Photographing an exoplanet 25 light years away with 25km/pixel resolution (2020)
- May 2020SpaceX successfully launches two humans into orbit
- Dec 2022Two temperate Earth-mass planets orbiting the nearby star GJ1002
- Oct 2024A solar gravitational lens will be humanity's most powerful telescope (2022)
- Jan 2025IAC confirms existence of a Super-earth in the habitable zone of a Sun-like Star
- Jun 2025JWST reveals its first direct image discovery of an exoplanet
- 49
Automated Symbolic Verification of Telegram's MTProto 2.0
Hacker News threads
- Jan 2021Automated Symbolic Verification of Telegram's MTProto 2.0
- Dec 2020Automated Symbolic Verification of Telegram's Cryptographic Protocol
- Jan 2021Automated Symbolic Verification of Telegram’s MTProto 2.0
- Jan 2021Telegram publishes users' locations online
- Jan 2021WhatsApp gives users an ultimatum: Share data with Facebook or stop using app
- Jan 2021Poll: Switching from WhatsApp
- Oct 2022Signal is secure, as proven by hackers
- Apr 2023WhatsApp announces key transparency being added to WhatsApp
- Aug 2024Arrest of Pavel Durov, Telegram CEO, charges of terrorism, fraud, child porn
- Aug 2024Arrest of Pavel Durov, Telegram CEO, charges of terrorism, fraud, child porn
- 50
FNet: Mixing Tokens with Fourier Transforms
Hacker News threads
- May 2024FNet: Mixing Tokens with Fourier Transforms (2021)
- May 2021FNet: Mixing Tokens with Fourier Transforms
- May 2021FNet: Attention may be all you WANT but we you need is good token mixing
- May 2021An Interactive Guide to the Fourier Transform (2012)
- May 2024New attention mechanisms that outperform standard multi-head attention
- May 2024New attention mechanisms that outperform standard multi-head attention
- Feb 2025The FFT Strikes Back: An Efficient Alternative to Self-Attention
- Feb 2025The FFT Strikes Back: An Efficient Alternative to Self-Attention
- Mar 2026TorchLean: Formalizing Neural Networks in Lean
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.