Hacker Papers
- 26
BitNet: Scaling 1-bit Transformers for Large Language Models
Hacker News threads
- Oct 2023BitNet: Scaling 1-Bit Transformers for Large Language Models
- Feb 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Feb 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Mar 2024Towards 1-bit Machine Learning Models
- Jun 2024Scalable MatMul-Free Language Modeling
- Nov 2024SVDQuant: 4-Bit Quantization Powers 12B Flux on a 16GB 4090 GPU with 3x Speedup
- May 2025Towards the Cutest Neural Network
- Mar 2026Microsoft BitNet: 100B Param 1-Bit model for local CPUs
- Jul 2026Neutrino-1 8B
- 27
Mamba: Linear-Time Sequence Modeling with Selective State Spaces
Hacker News threads
- Dec 2023Mamba: Linear-Time Sequence Modeling with Selective State Spaces
- Dec 2023Mamba: Linear-Time Sequence Modeling with Selective State Spaces
- Dec 2023Mamba outperforms transformers "everywhere we tried"
- Jan 2024Understand how transformers work by demystifying the math behind them
- Jan 2024Eagle 7B: Soaring past Transformers
- Feb 2024Mamba: The Easy Way
- Mar 2024Launch HN: Danswer (YC W24) – Open-source AI search and chat over private data
- Jun 2024A pure NumPy implementation of Mamba
- Jul 2024Codestral Mamba
- Aug 2025GPT-5: Key characteristics, pricing and system card
- 28
How is ChatGPT's behavior changing over time?
Hacker News threads
- Jul 2023How is ChatGPT's behavior changing over time?
- Jul 2023(Databricks cofounder) How Is ChatGPT’s Behavior Changing over Time?
- Jul 2023How is ChatGPT's behavior changing over time?
- Jul 2023GPT-4 is getting worse over time, not better
- Aug 2023Why is OpenAI making ChatGPT increasingly dumber? What's the motivation?
- Aug 2023Azure ChatGPT: Private and secure ChatGPT for internal enterprise use
- Aug 2023Show HN: Beating GPT-4 on HumanEval with a fine-tuned CodeLlama-34B
- Sep 2023Study shows over time, ChatGPT lost accuracy
- Mar 2024DBRX: A new open LLM
- Apr 2026Claude Opus 4.7 costs 20–30% more per session
- Sep 2026Ember-1
- 29
A Watermark for Large Language Models
Hacker News threads
- Jan 2023A Watermark for Large Language Models
- Aug 2026A Watermark for Large Language Models
- Jan 2023A Watermark for Large Language Models
- Jan 2023New AI classifier for indicating AI-written text
- Mar 2023Mark Zuckerberg: “Please Resign” (2010)
- Jul 2023A.I. Companies Agree to Safeguards After Pressure from the White House
- Jul 2024Meta Launches AI Studio in US
- Aug 2026How Claude marks AI-generated content
- Aug 2026How Claude marks AI-generated content
- Aug 2026Text AI watermarks will always be trivial to remove
- Aug 2026Anthropic's 'Watermark' Text Adulteration in Claude Is a Perversion of Writing
- 30
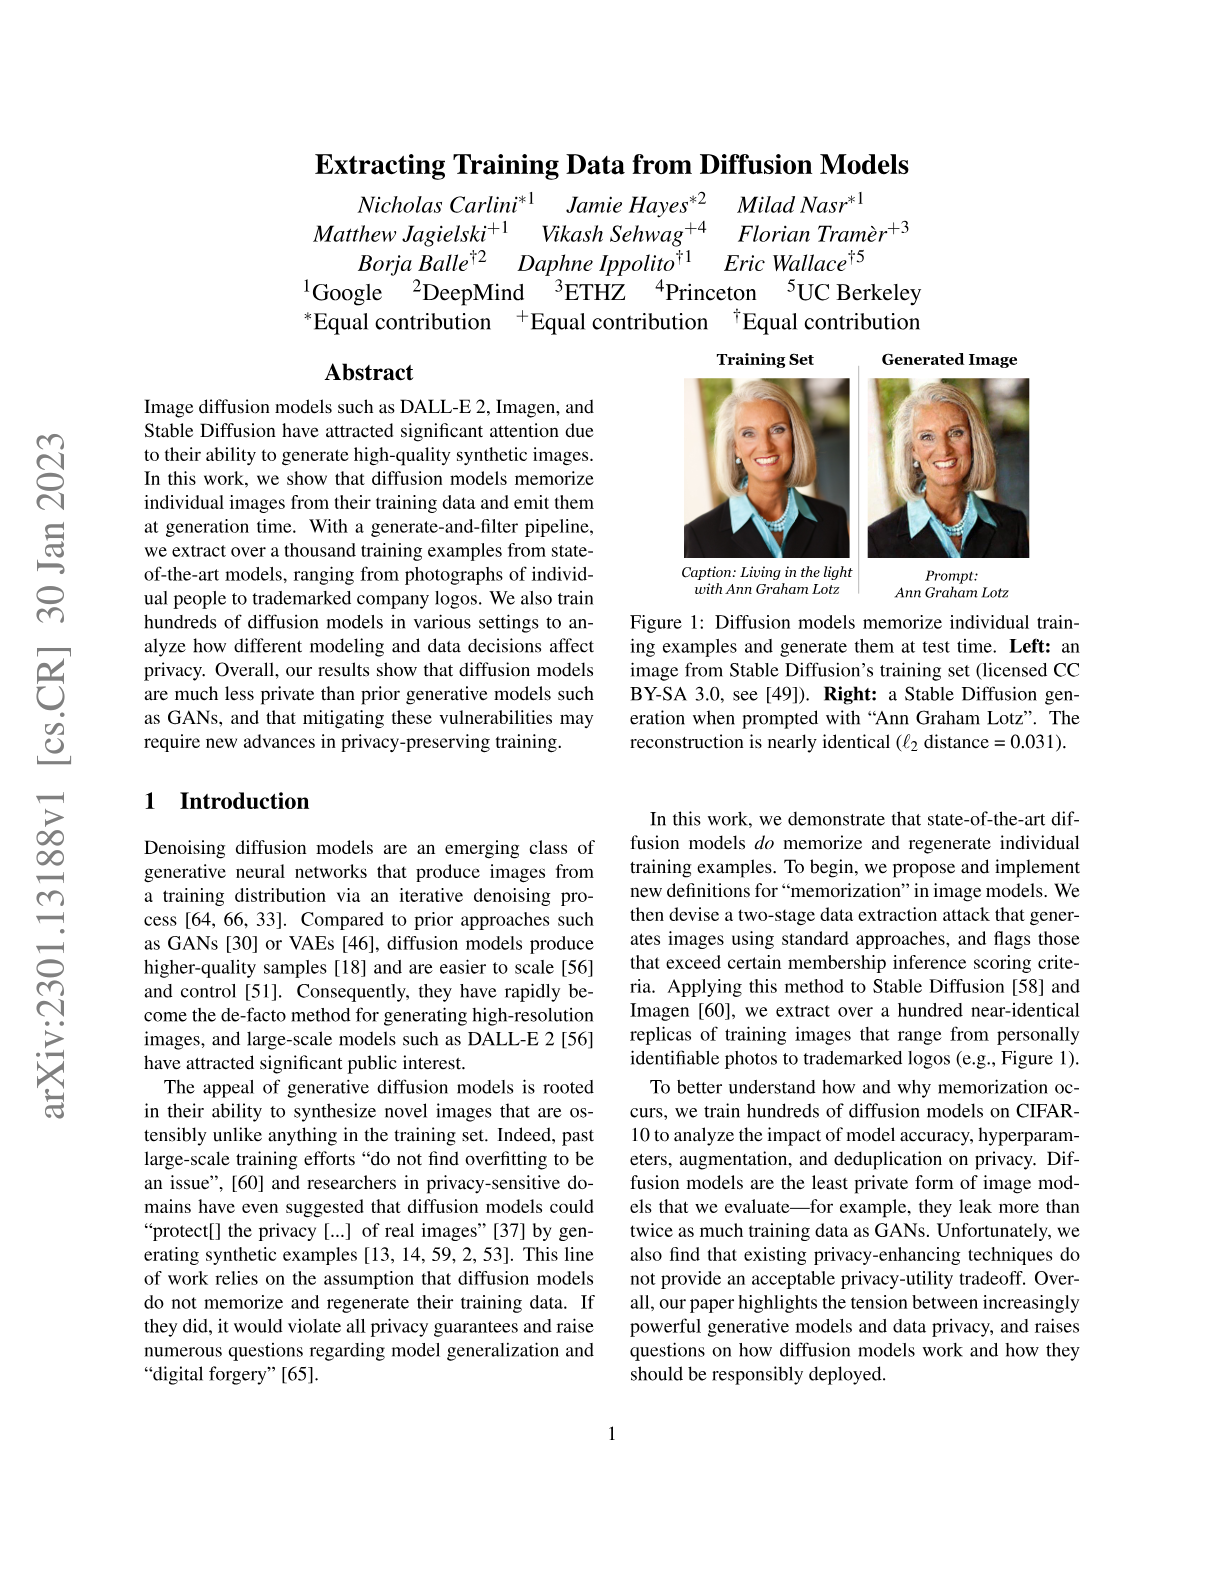
Extracting Training Data from Diffusion Models
Hacker News threads
- Jan 2023Extracting Training Data from Diffusion Models
- Jan 2023Stable Diffusion Memorizes Training Points
- Feb 2023The AI Crowd Is Mad
- Feb 2023An IP Attorney’s Reading of the Stable Diffusion Class Action Lawsuit
- Mar 2023Launch HN: Flower (YC W23) – Train AI models on distributed or sensitive data
- Apr 2023Universal Music Asks Streaming Services to Block AI Access to Its Songs
- Jun 2023Valve bans games using AI generated graphics or text from Steam
- Nov 2023Let's Not Flip Sides on IP Maximalism Because of AI
- Jan 2024Nightshade: An offensive tool for artists against AI art generators
- Jul 2025Meta says it won't sign Europe AI agreement
- 31
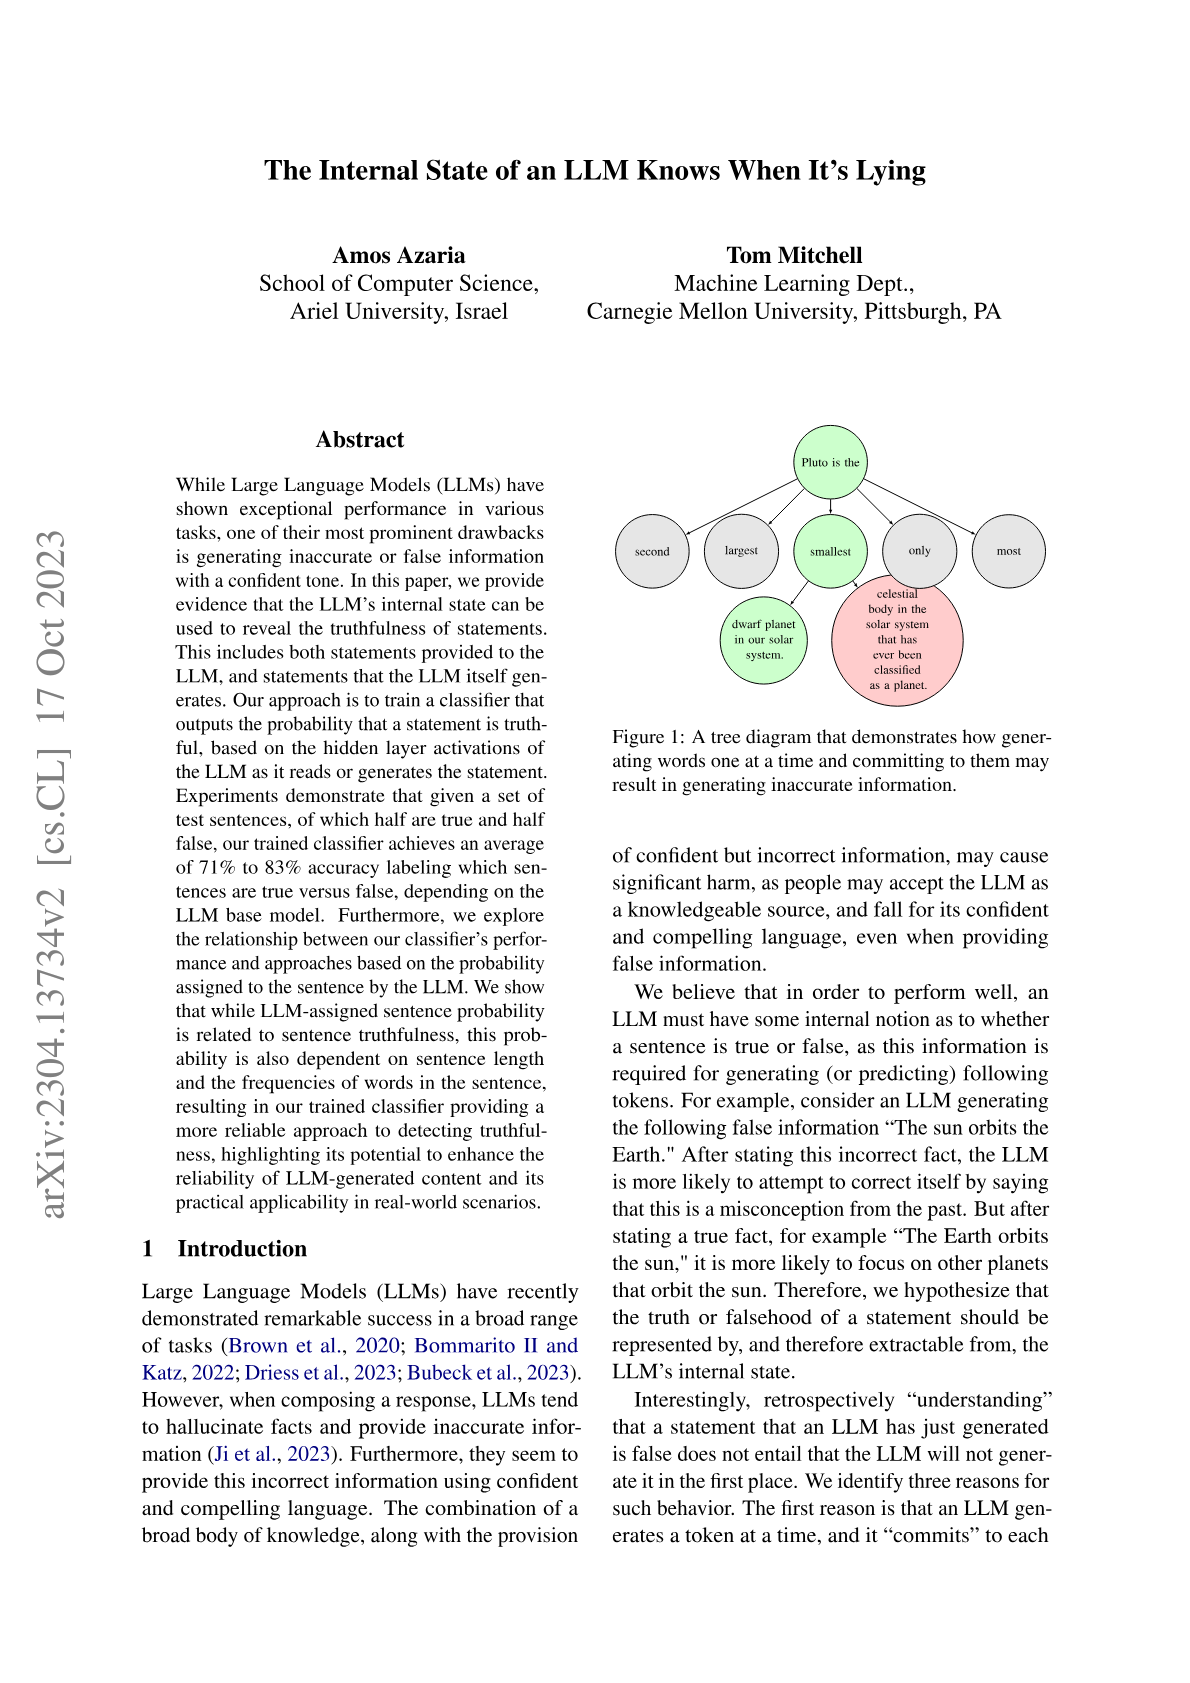
The Internal State of an LLM Knows When It's Lying
Hacker News threads
- Nov 2023The Internal State of an LLM Knows When It's Lying
- Sep 2023The Internal State of a Large Language Model Knows When Its Lying
- May 2023The internal state of an LLM knows when it is lying
- Jun 2023Show HN: StonksGPT – A Natural Language search tool for Stocks and Finance data
- Aug 2023How to Get ChatGPT to Stop Apologizing?
- May 2024Scaling Monosemanticity: Extracting Interpretable Features from Claude 3 Sonnet
- Aug 2024LLMs know more than what they say
- Sep 2024AI is growing faster than companies can secure it, warn industry leaders
- Sep 2024Is telling a model to "not hallucinate" absurd?
- Oct 2024LLMs know more than they show: On the intrinsic representation of hallucinations
- Feb 2026Psychometric Jailbreaks Reveal Internal Conflict in Frontier Models
- 32
Faith and Fate: Limits of Transformers on Compositionality
Hacker News threads
- Apr 2025Faith and Fate: Limits of Transformers on Compositionality
- Jun 2023Faith and Fate: Limits of Transformers on Compositionality
- Jun 2023Faith and Fate: Limits of Transformers on Compositionality
- Jun 2023Weird GPT-4 behavior for the specific string “ davidjl”
- Jun 2023Researchers warn of ‘model collapse’ as AI trains on AI-generated content
- Dec 2023Will scaling work?
- Jan 2024Chess-GPT's Internal World Model
- Jan 2024New theory suggests LLMs can understand text
- Mar 2024Quiet-STaR: Language Models Can Teach Themselves to Think Before Speaking
- Feb 2025Recent results show that LLMs struggle with compositional tasks
- Oct 2025OpenAI researcher announced GPT-5 math breakthrough that never happened
- 33
Tree of Thoughts: Deliberate Problem Solving with Large Language Models
Hacker News threads
- May 2023Tree of Thoughts: Deliberate Problem Solving with Large Language Models
- May 2023Tree of Thoughts: Deliberate Problem Solving with Large Language Models
- May 2023Tree-of-Thought (ToT), complex and general problem solving with LLMs
- May 2023Ask HN: Those with success using GPT-4 for programming – what are you doing?
- May 2023Tree of Thoughts
- Jun 2023Tree of Thoughts: Official vs. Wrong Implementation
- Jun 2023Native JSON Output from GPT-4
- Jun 2023LLM Powered Autonomous Agents
- Jul 2023Bard’s latest update: more features, languages and countries
- Sep 2024g1: Using Llama-3.1 70B on Groq to create o1-like reasoning chains
- Mar 2026Tree Search Distillation for Language Models Using PPO
- 34
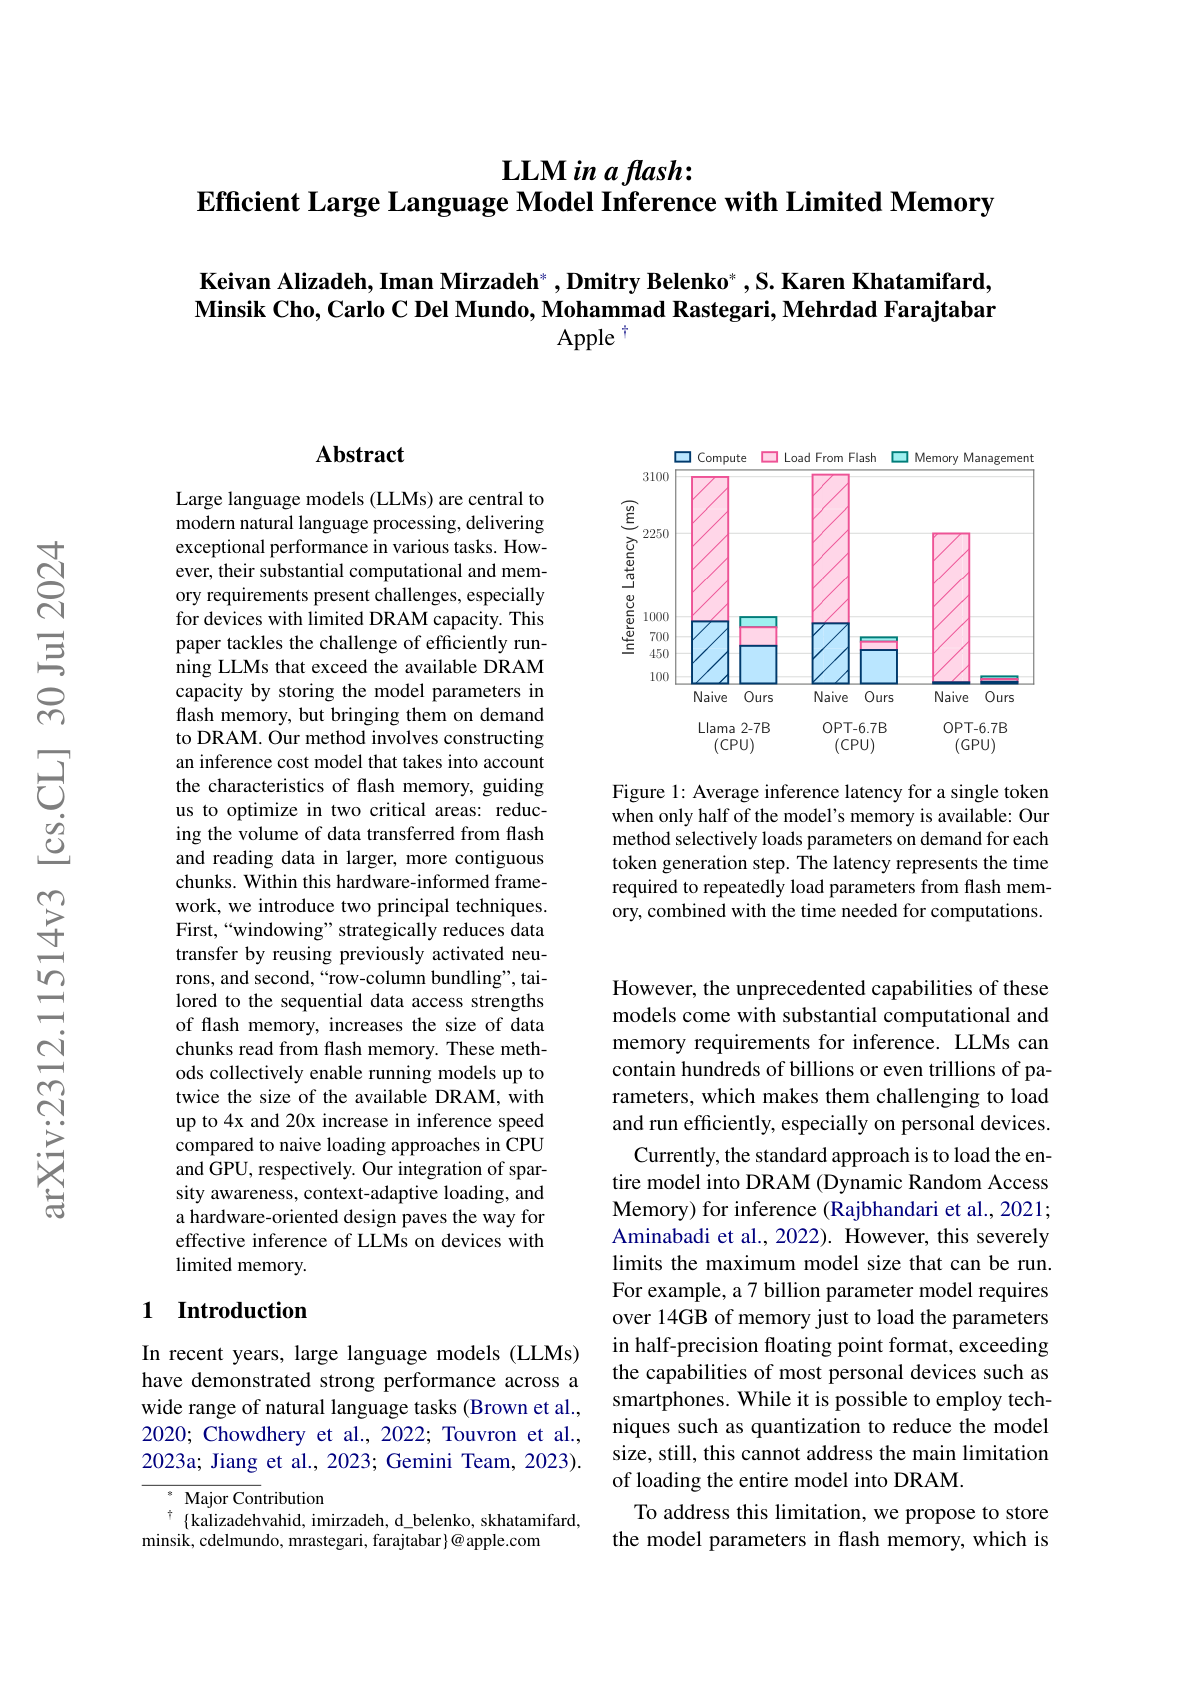
LLM in a flash: Efficient Large Language Model Inference with Limited Memory
Hacker News threads
- Jan 2024LLM in a Flash: Efficient Large Language Model Inference with Limited Memory
- Dec 2023LLM in a Flash: Efficient Large Language Model Inference with Limited Memory
- Dec 2023LLM in a Flash: Efficient Large Language Model Inference with Limited Memory
- Dec 2023Apple Announces LLM in a Flash: Efficient LLM Inference with Limited Memory
- Dec 2023Apple wants AI to run directly on its hardware instead of in the cloud
- Dec 2023Show HN: Emu2 – A Gemini-like open-source 37B Multimodal Model
- Dec 2023Ferret: A Multimodal Large Language Model
- Mar 2024Towards 1-bit Machine Learning Models
- Mar 2026Qwen3.5-397B at 4.74 tok/s using 5.9GB RAM
- Mar 2026iPhone 17 Pro Demonstrated Running a 400B LLM
- Aug 2026New Mac Studio with M5 Max and M5 Ultra
- 35
Levels of AGI for Operationalizing Progress on the Path to AGI
Hacker News threads
- Nov 2023Levels of AGI: Operationalizing Progress on the Path to AGI
- Nov 2023Levels of AGI: Operationalizing Progress on the Path to AGI
- Nov 2023DeepMind on the Definitions and Levels of AGI
- Nov 2023Sutskever: OpenAI board doing its mission to build AGI that benefits all
- Nov 2023The deal to bring Sam Altman back to OpenAI has fallen apart
- Dec 2023Audiobox: Meta's new foundation research model for audio generation
- Mar 2024Elon Musk sues Sam Altman, Greg Brockman, and OpenAI [pdf]
- May 2024Transformers Can Do Arithmetic with the Right Embeddings
- May 2025Evolving OpenAI's Structure
- May 2025John Carmack talk at Upper Bound 2025
- Jun 2025Seven replies to the viral Apple reasoning paper and why they fall short
- 36
GPTs are GPTs: An Early Look at the Labor Market Impact Potential of Large Language Models
Hacker News threads
- Mar 2023GPTs Are GPTs: An Early Look at the Labor Market Impact Potential of LLMs
- Mar 2026An early look at the labor market impact potential of LLMs (2023)
- Mar 2023ChatGPT is down
- Mar 2023OpenAI Research Says 80% of U.S. Workers' Jobs Will Be Impacted by GPT
- Apr 2023Anthropic’s $5B, 4-year plan to take on OpenAI
- Nov 2023Google AI chief says there's a 50% chance we'll hit AGI in just 5 years
- Mar 2024AutoDev: Automated AI-driven development by Microsoft
- Oct 2024OpenAI not expecting to break into profitability until 2029
- May 2025John Carmack talk at Upper Bound 2025
- Nov 2025MIT study finds AI can replace 11.7% of U.S. workforce
- 37
SequenceMatch: Imitation Learning for Autoregressive Sequence Modelling with Backtracking
Hacker News threads
- Jun 2023Giving LLM’s a <Backspace> Token
- Jun 2023LLM Powered Autonomous Agents
- Jun 2024AI Detectors Get It Wrong. Writers Are Being Fired Anyway
- Mar 2025Understanding R1-Zero-Like Training: A Critical Perspective
- May 2025Mercury: Commercial-scale diffusion language model
- Aug 2025Hacking Diffusion into Qwen3 for the Arc Challenge
- Sep 2025The wall confronting large language models
- Oct 2025Why do LLMs freak out over the seahorse emoji?
- Oct 2025Why do LLMs freak out over the seahorse emoji?
- 38
Progress measures for grokking via mechanistic interpretability
Hacker News threads
- Jan 2023Do Large Language Models learn world models or just surface statistics?
- Apr 2023We need a much more sophisticated debate about AI
- Apr 2023Grokking in Julia
- May 2023Tiny Transformer trained for addition learns bizarre addition algorithm
- Aug 2023The Myth of AI Omniscience
- Feb 2024Every model learned by gradient descent is approximately a kernel machine (2020)
- Oct 2024OpenAI builds first chip with Broadcom and TSMC, scales back foundry ambition
- Jan 2026Claude is not a senior engineer (yet)
- 39
Accelerating Large Language Model Decoding with Speculative Sampling
Hacker News threads
- Feb 2023Accelerating Large Language Model Decoding with Speculative Sampling
- Sep 2023Accelerating Large Language Model Decoding with Speculative Sampling
- Mar 2023Facebook LLAMA is being openly distributed via torrents
- Mar 2023LLaMA-7B in Pure C++ with full Apple Silicon support
- Mar 2023Run 100B+ language models at home, BitTorrent‑style
- Apr 2023Stability AI Launches the First of Its StableLM Suite of Language Models
- Nov 2023Major Outage Across ChatGPT and API
- May 2024Better and Faster Large Language Models via Multi-Token Prediction
- Sep 2024AMD Unveils Its First Small Language Model AMD-135M
- May 2026Accelerating Gemma 4: faster inference with multi-token prediction drafters
- 40
Pretraining on the Test Set Is All You Need
Hacker News threads
- Oct 2023Pretraining on test set is all you need
- Feb 2025Pretraining on the Test Set Is All You Need
- Oct 2023Pretraining on the Test Set Is All You Need
- Oct 2023AI hype is built on high test scores. Those tests are flawed
- Nov 2023Grok
- Mar 2024Claude 3 model family
- Apr 2024The "it" in AI models is the dataset
- Jun 2024Gemma 2: Improving Open Language Models at a Practical Size [pdf]
- Jul 2024Fitting an elephant with four non-zero parameters
- Feb 2025Grok3 Launch [video]
- 41
QLoRA: Efficient Finetuning of Quantized LLMs
Hacker News threads
- May 2023QLoRA: Efficient Finetuning of Quantized LLMs
- May 2023QLoRA: Efficient Finetuning of Quantized LLMs
- May 2023The False Promise of Imitating Proprietary LLMs
- May 2023Ask HN: What's the best self hosted/local alternative to GPT-4?
- May 2023Ask HN: What's the best self hosted/local alternative to GPT-4?
- May 2023Ask HN: What's the best self hosted/local alternative to GPT-4?
- Dec 202380% faster, 50% less memory, 0% loss of accuracy Llama finetuning
- May 2024LoRA Learns Less and Forgets Less
- Oct 2024Guide to Fine-Tuning LLMs
- Mar 2026TorchLean: Formalizing Neural Networks in Lean
- 42
The Geometry of Truth: Emergent Linear Structure in Large Language Model Representations of True/False Datasets
Hacker News threads
- Oct 2023The Geometry of Truth: Emergent Linear Structure in How LLMs Represent Truth
- Oct 2023"Hallucinating" AIs Sound Creative, but Let's Not Celebrate Being Wrong
- Nov 2023Ask HN: What is your standard for judging when AGI exists?
- Nov 2023Rats have an imagination, new research suggests
- Nov 2023HN thread 38355930
- May 2024Google scrambles to manually remove weird AI answers in search
- Sep 2024AI is growing faster than companies can secure it, warn industry leaders
- Sep 2024GPTs and Hallucination
- Aug 2025Persona vectors: Monitoring and controlling character traits in language models
- 43
Text Embeddings Reveal (Almost) As Much As Text
Hacker News threads
- Oct 2023Text Embeddings Reveal (Almost) as Much as Text
- Nov 2023Show HN: Phind Model beats GPT-4 at coding, with GPT-3.5 speed and 16k context
- Dec 2023Embeddings, Vectors, and Arithmetic
- Mar 2024Launch HN: Greptile (YC W24) - RAG on codebases that actually works
- Jun 2024CryptGPT: A Simple Approach to Privacy-Preserving LLMs Using Vigenere Cipher
- Jul 2024Vision language models are blind
- Jan 2025Let's talk about AI and end-to-end encryption
- 44
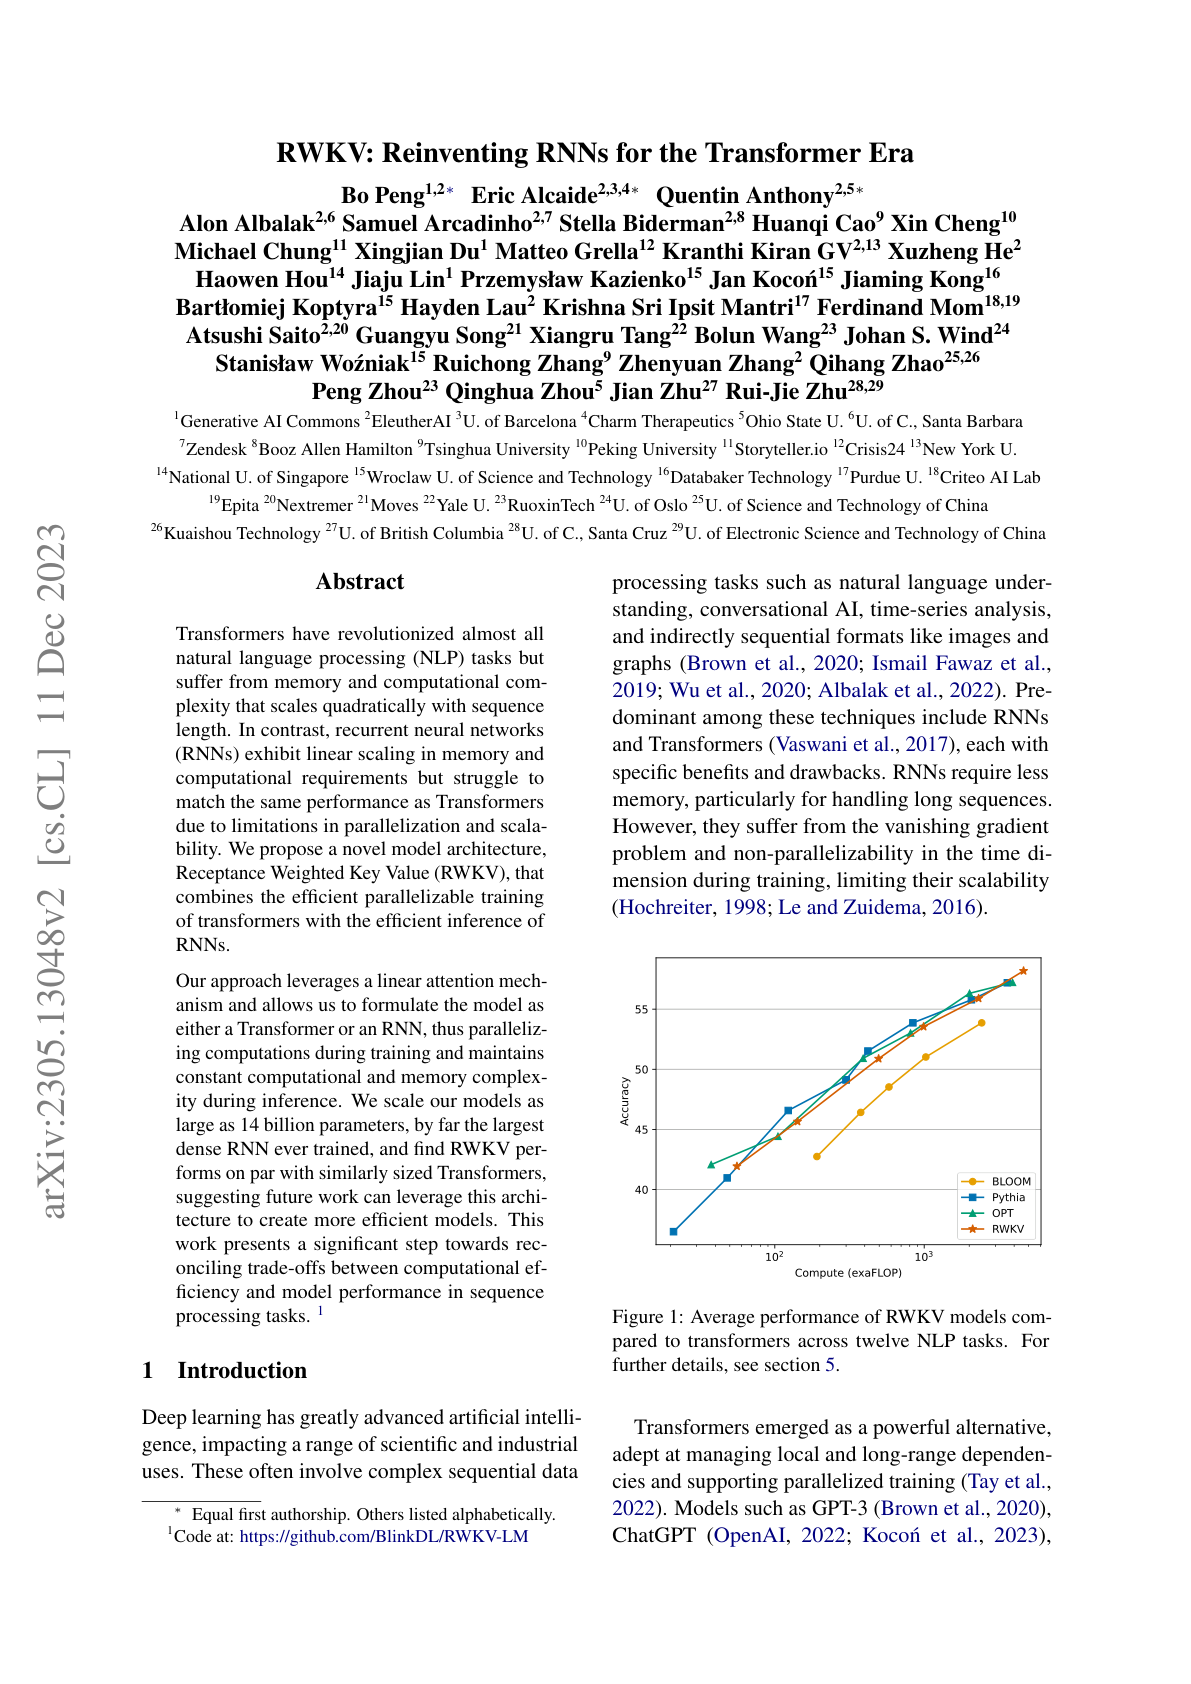
RWKV: Reinventing RNNs for the Transformer Era
Hacker News threads
- May 2023RWKV: Reinventing RNNs for the Transformer Era
- Jul 2023Scaling Transformers to 1B Tokens
- Nov 2023Is anyone using self hosted LLM day to day and training it like a new employee
- Dec 2023Paving the way to efficient architectures: StripedHyena-7B
- Jan 2024Eagle 7B: Soaring past Transformers
- Jan 2024Eagle 7B: Soaring past Transformers
- Feb 2025Ask HN: Is anybody building an alternative transformer?
- 45
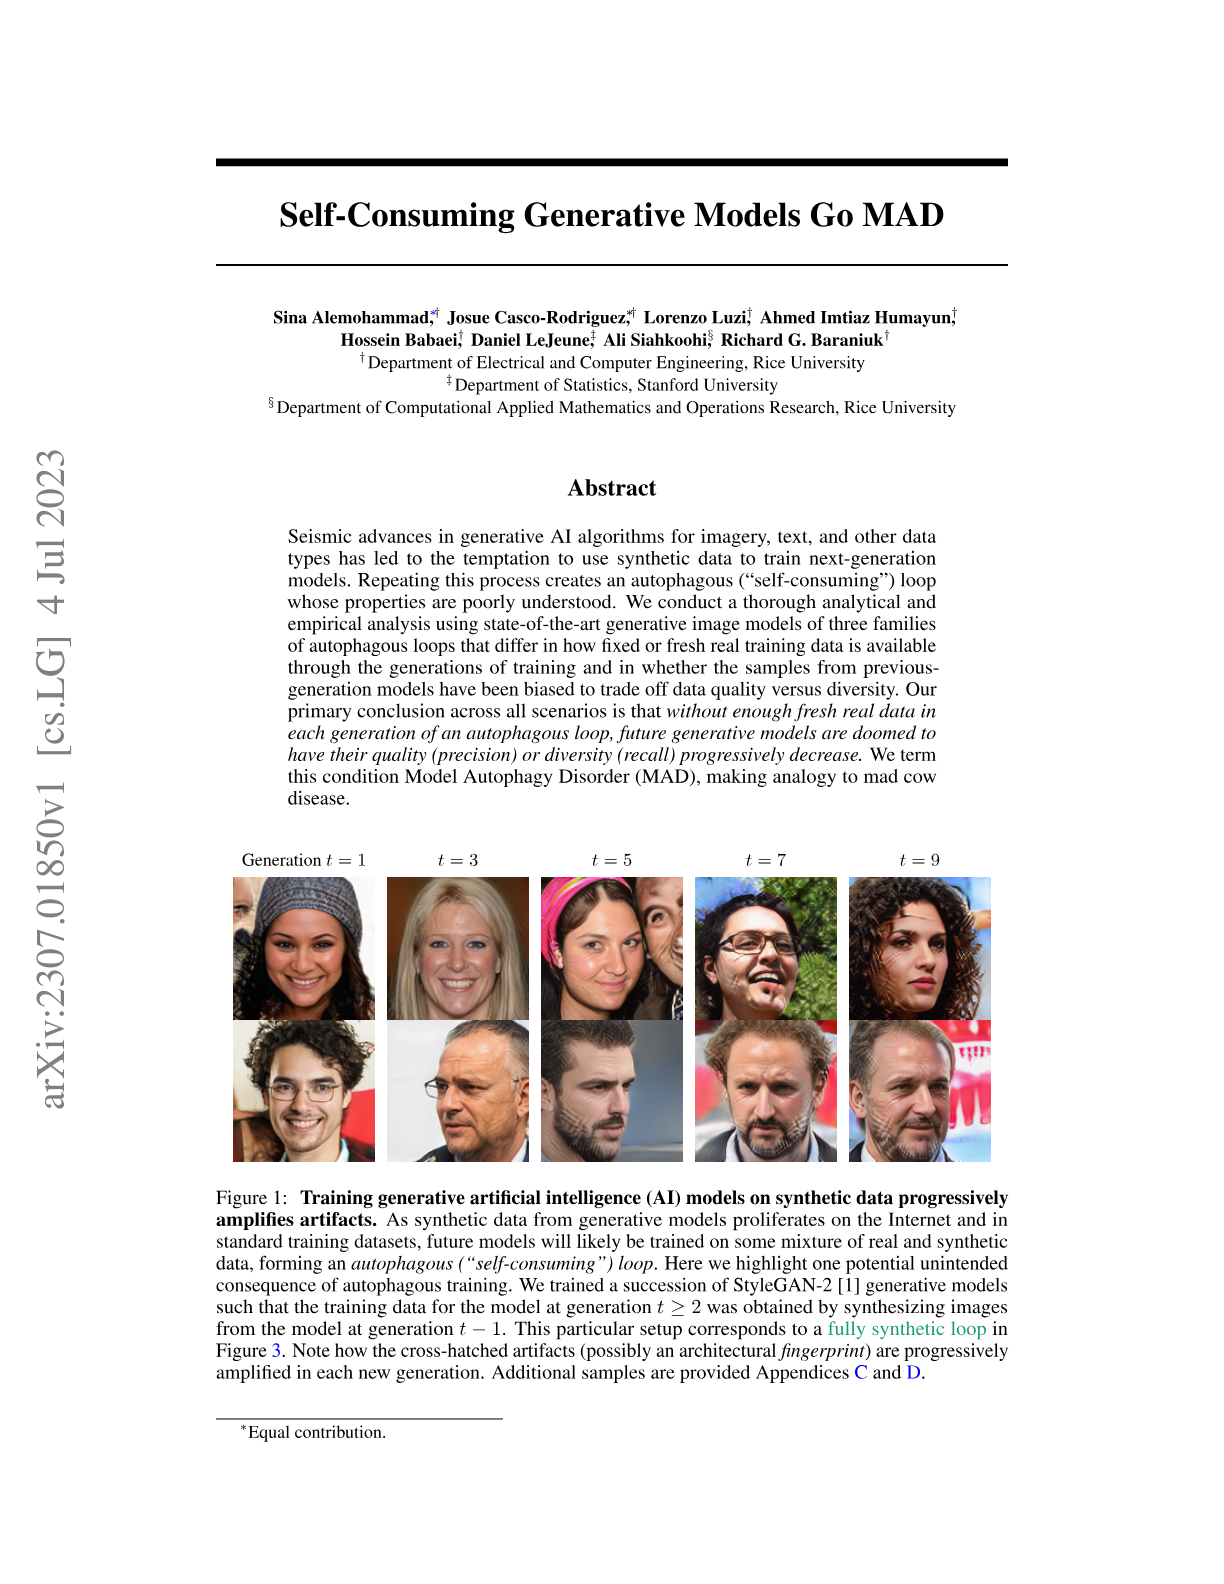
Self-Consuming Generative Models Go MAD
Hacker News threads
- Jan 2024Self-Consuming Generative Models Go MAD
- Aug 2023Self-Consuming Generative Models Go Mad
- Jul 2023AI Loses Its Mind After Being Trained on AI-Generated Data
- Jul 2023AI Loses Its Mind After Being Trained on AI-Generated Data
- Oct 2023Why Generative AI Is Currently Doomed
- Apr 2024Google Books Is Indexing AI-Generated Garbage
- Jul 2024AI models collapse when trained on recursively generated data
- Sep 2026Nvidia wants to put a watchdog chip next to every AI agent
- 46
Scalable Extraction of Training Data from (Production) Language Models
Hacker News threads
- Dec 2023Scalable Extraction of Training Data from (Production) Language Models
- Nov 2023Extracting Training Data from LLMs
- Nov 2023Scalable Extraction of Training Data from (Production) Language Models
- Dec 2023Sorry, but a new prompt for GPT-4 is not a paper
- Jan 2024Nightshade: An offensive tool for artists against AI art generators
- Feb 2024Beyond self-attention: How a small language model predicts the next token
- Oct 2025What GPT-OSS leaks about OpenAI's training data
- Nov 2025The current state of the theory that GPL propagates to AI models
- 47
A Practical Deep Learning-Based Acoustic Side Channel Attack on Keyboards
Hacker News threads
- Jan 2026Acoustic Side Channel Attack on Keyboards (2023)
- Aug 2023A Practical Deep Learning-Based Acoustic Side Channel Attack on Keyboards
- Aug 2023A Practical Deep Learning-Based Acoustic Side Channel Attack on Keyboards
- Aug 2023Write your passwords down (2010)
- Oct 2023OpenSSH 9.5 released with keystroke timing obfuscation
- Dec 2023Scary AI recognizes passwords by the sound of your typing
- Nov 2024Malware can turn off webcam LED and record video, demonstrated on ThinkPad X230
- Mar 2026Ubuntu 26.04 Ends 46 Years of Silent sudo Passwords
- 48
SWE-bench: Can Language Models Resolve Real-World GitHub Issues?
Hacker News threads
- Oct 2023SWE-Bench: Can Language Models Resolve Real-World GitHub Issues?
- Feb 2024SWE-BENCH: Can language models resolve real-world GitHub issues?
- Jan 2024Researchers say generative AI isn't replacing devs any time soon
- Sep 2025Top model scores may be skewed by Git history leaks in SWE-bench
- Dec 2025Django: what’s new in 6.0
- Mar 2026Ask HN: Does code style matter much anymore?
- Oct 2026Agents don't need memory, they need documentation
- 49
Getting from Generative AI to Trustworthy AI: What LLMs might learn from Cyc
Hacker News threads
- Aug 2023Getting from Generative AI to Trustworthy AI: What LLMs Might Learn from Cyc
- Sep 2023Getting from Generative AI to Trustworthy AI: What LLMs Might Learn from Cyc
- Aug 2023Getting from Generative AI to Trustworthy AI: What LLMs Might Learn from Cyc
- Sep 2023Doug Lenat has died
- Sep 2023Recursively Summarizing Enables Long-Term Dialogue Memory in LLMs
- Sep 2023Lenat and Cyc
- Jun 2024ARC Prize – a $1M+ competition towards open AGI progress
- Nov 2024LLMs have reached a point of diminishing returns
- Apr 2025Obituary for Cyc
- 50
MEGABYTE: Predicting Million-byte Sequences with Multiscale Transformers
Hacker News threads
- Jun 2023Megabyte: Predicting Million-Byte Sequences with Multiscale Transformers
- May 2023Megabyte: Predicting Million-Byte Sequences with Multiscale Transformers
- May 2023Meta AI Megabyte: Predicting Million-Byte Sequences with Multiscale Transformers
- May 2023Meta AI Unleashes Megabyte, a Revolutionary Scalable Model Architecture
- Jun 2023Bytes Are All You Need: Transformers Operating Directly on File Bytes
- Jun 2023Weird GPT-4 behavior for the specific string “ davidjl”
- Feb 2024LongRoPE: Extending LLM Context Window Beyond 2M Tokens
- Oct 2025Neural audio codecs: how to get audio into LLMs
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.