Hacker Papers
- 26
DESI 2024 VI: Cosmological Constraints from the Measurements of Baryon Acoustic Oscillations
Hacker News threads
- 27
DeepSeek-V3 Technical Report
Hacker News threads
- Mar 2025DeepSeek-V3 Technical Report
- Jan 2025DeepSeek-V3 Technical Report
- Jan 2025A path to O1 open source
- Jan 2025Ask HN: Confused about how DeepSeek hurts Nvidia
- Jan 2025Why DeepSeek had to be open source
- Feb 2025Step-Video-T2V: The Practice, Challenges, and Future of Video Foundation Model
- May 2025DeepSeek’s founder is threatening US dominance in AI race
- Feb 2026GLM-5: From Vibe Coding to Agentic Engineering
- Mar 2026Mamba-3
- Jun 2026Two Qwen3 models on one DGX Spark: the residency math
- 28
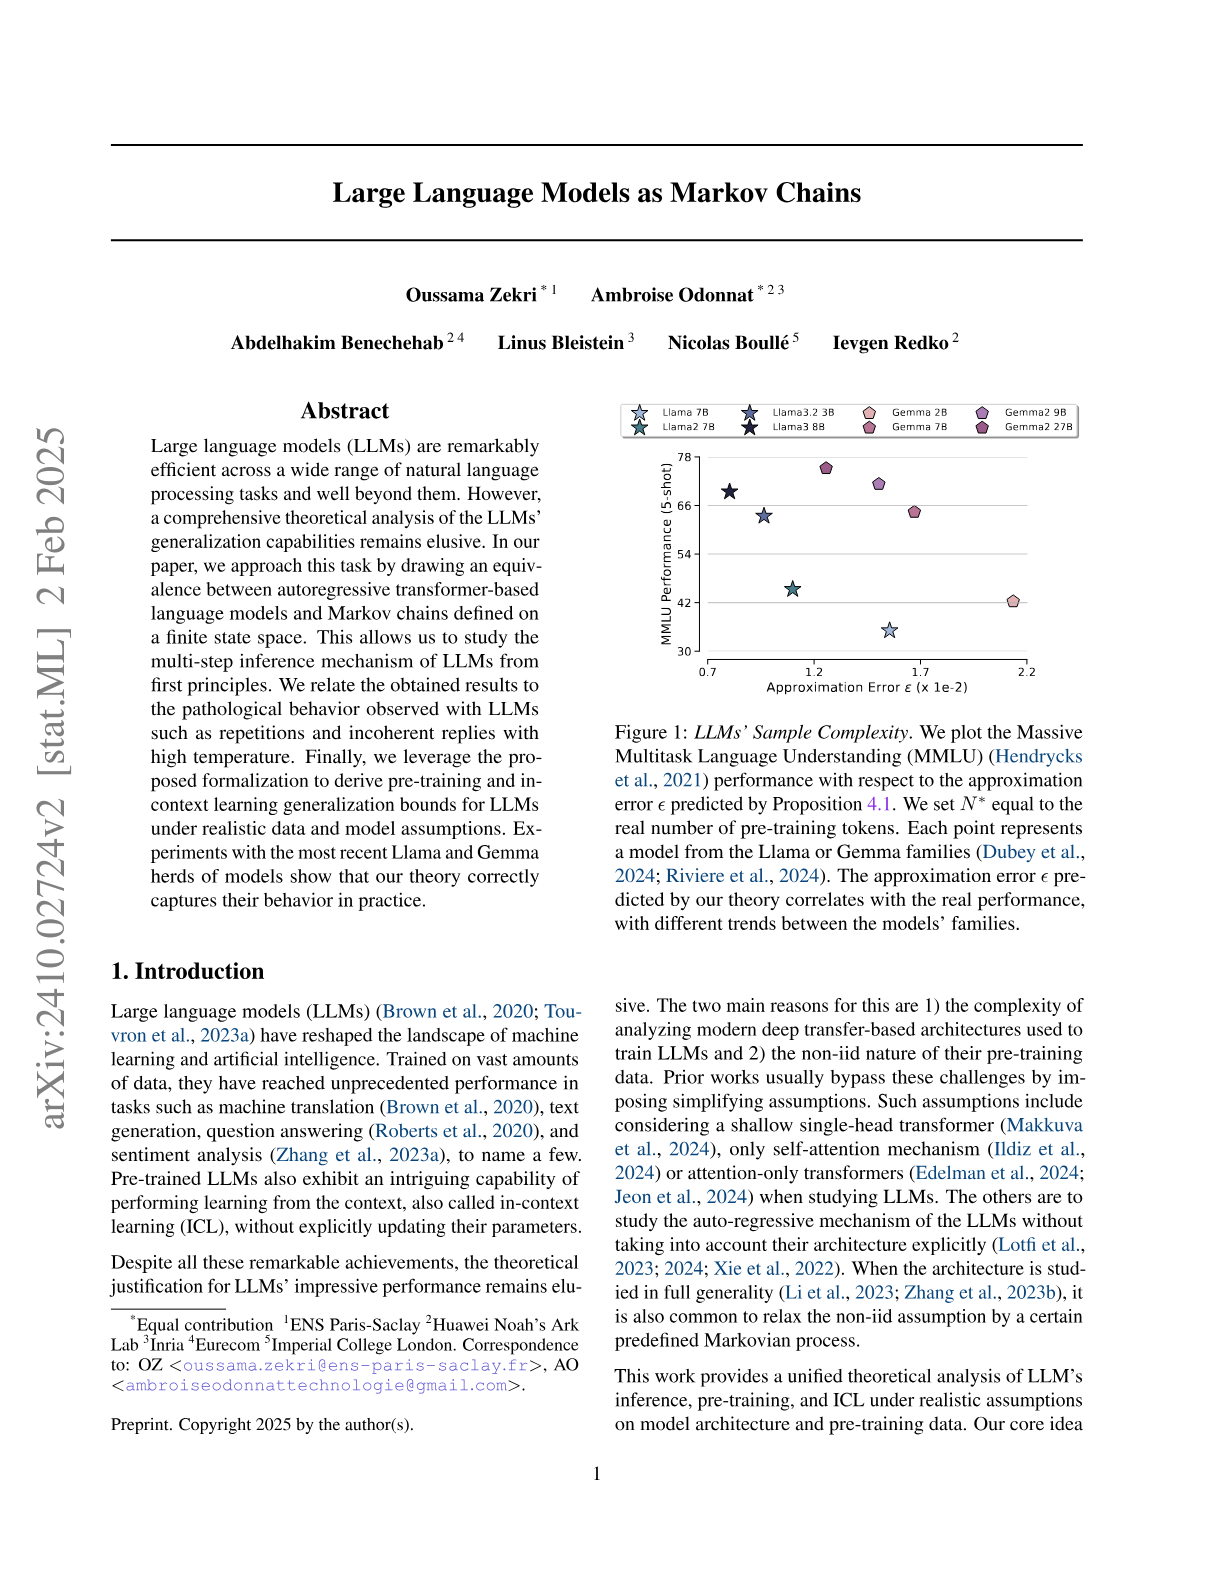
Large Language Models as Markov Chains
Hacker News threads
- Nov 2024Large Language Models as Markov Chains
- Oct 2024LLMs as Markov Chains
- Oct 2024Large Language Models as Markov Chains
- Jul 2025Problem solving using Markov chains (2007) [pdf]
- Sep 2025The wall confronting large language models
- Oct 2025BERT is just a single text diffusion step
- Nov 2025AI is a front for consolidation of resources and power
- Dec 2025Reflections on AI at the End of 2025
- May 2026Why AI Agents Cannot Change Software Systems
- Jun 2026How LLMs Work
- Sep 2026The Emergent Symbolic Structure of Artificial Neural Networks
- 29
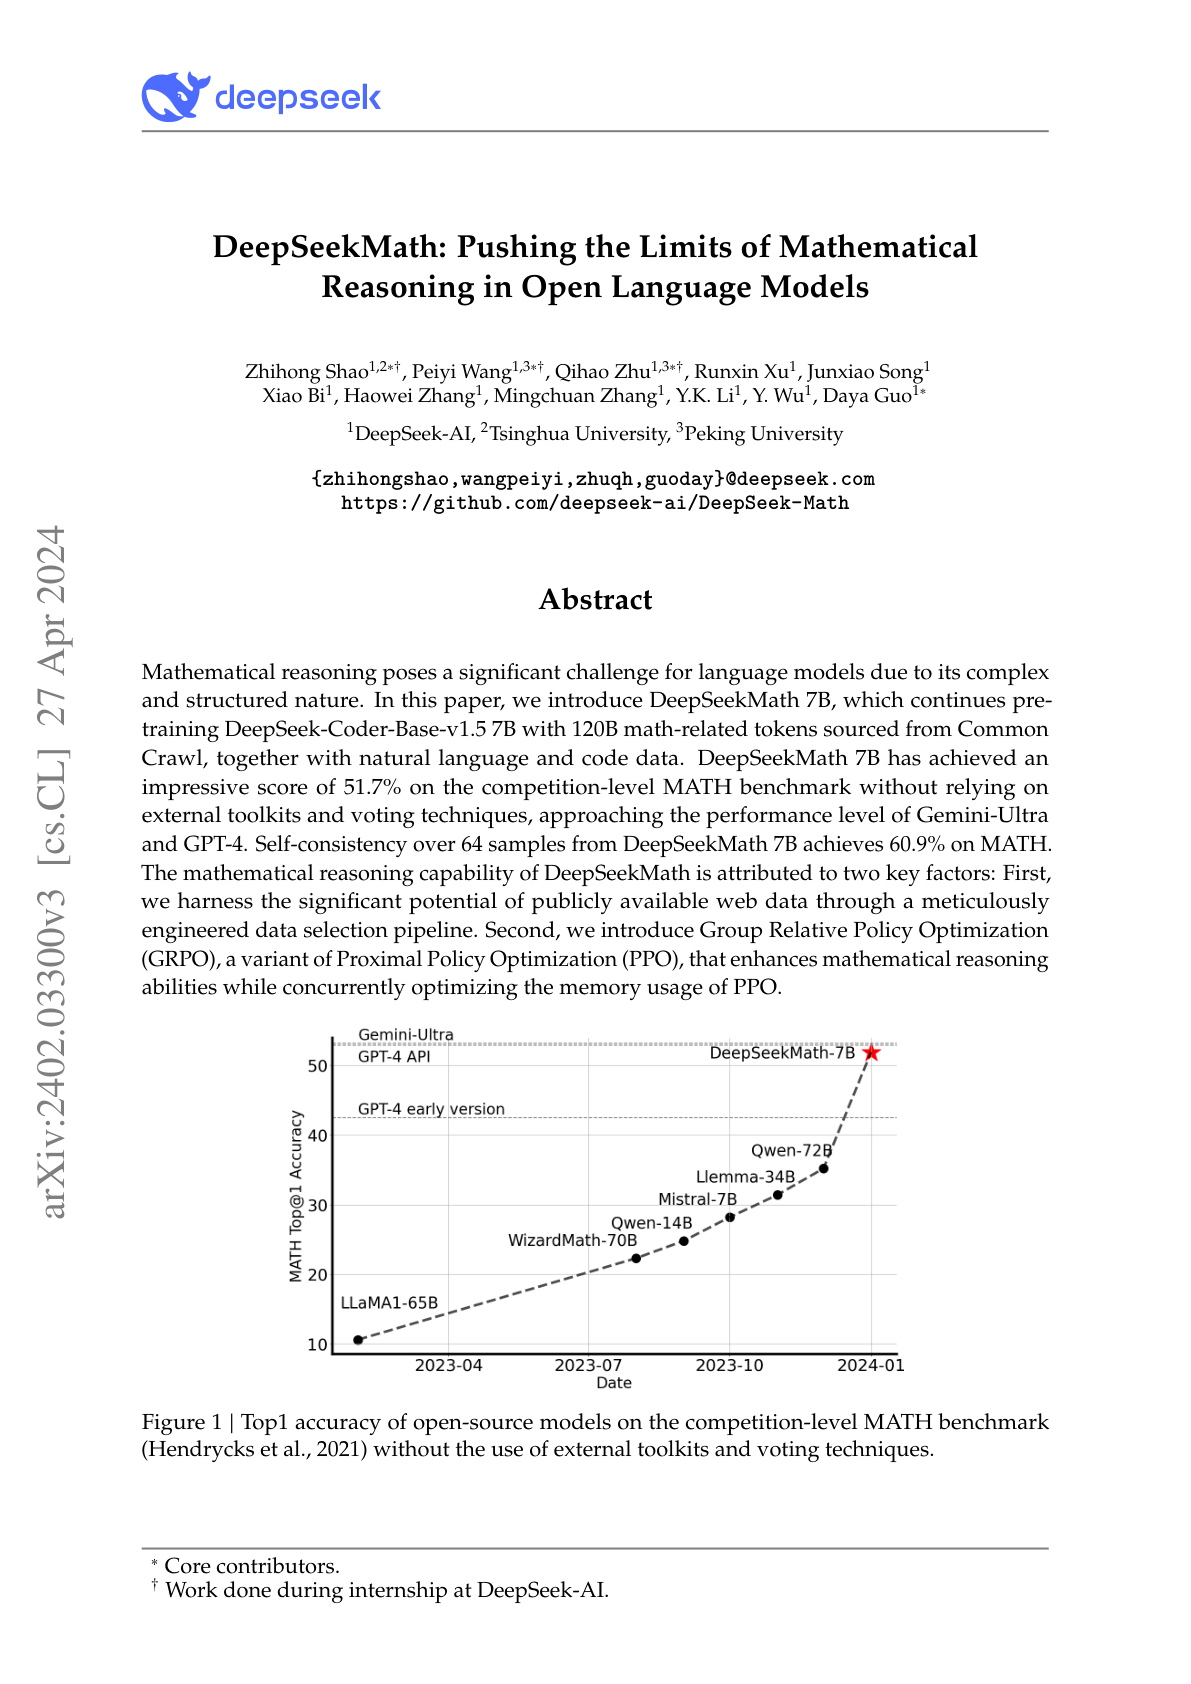
DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models
Hacker News threads
- Jan 2025DeepSeekMath
- Feb 2024DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open LLMs
- Feb 2024Pushing the Limits of Mathematical Reasoning in Open Language Models
- Jan 2025Berkeley Researchers Replicate DeepSeek R1's Core Tech for Just $30: A Small Mod
- Feb 2025GPT-4.5
- Mar 2025Using GRPO to Beat o1, o3-mini and R1 at “Temporal Clue”
- May 2025DeepSeek’s founder is threatening US dominance in AI race
- Nov 2025DeepSeekMath-V2: Towards Self-Verifiable Mathematical Reasoning [pdf]
- Jan 2026Nanolang: A tiny experimental language designed to be targeted by coding LLMs
- Sep 2026DeepSeek v4.1 Flash
- 30
Titans: Learning to Memorize at Test Time
Hacker News threads
- Jan 2025Titans: Learning to Memorize at Test Time
- Jan 2025Titans: Learning to Memorize at Test Time
- Jan 2025Titans: Learning to Memorize at Test Time
- Jan 2025Coming soon: PhD-level super-agents
- Jan 2025Qwen2.5-1M: Deploy your own Qwen with context length up to 1M tokens
- Feb 2025Google Titans Model Explained: The Future of Memory-Driven AI Architectures
- Feb 2025Google Titans Model Explained: The Future of Memory-Driven AI Architectures
- Dec 2025Google Titans architecture, helping AI have long-term memory
- Dec 2025The dawn of a world simulator
- Mar 2026Yann LeCun's AI startup raises $1B in Europe's largest ever seed round
- Apr 2026Show HN: AI memory with biological decay (52% recall)
- 31
Alice in Wonderland: Simple Tasks Showing Complete Reasoning Breakdown in State-Of-the-Art Large Language Models
Hacker News threads
- Jun 2024Simple tasks showing reasoning breakdown in state-of-the-art LLMs
- Jun 2024AI Appears to Rapidly Be Approaching Brick Wall Where It Can't Get Smarter
- Jun 2024Novel prompting approach for Alice in Wonderland problem
- Jul 2024Reasoning in Large Language Models: A Geometric Perspective
- Sep 2024Reflection 70B, the top open-source model
- Oct 2024Understanding the Limitations of Mathematical Reasoning in LLMs
- Dec 2024Genie 2: A large-scale foundation world model
- Dec 2024Genie 2: A large-scale foundation world model
- Apr 2025Ask HN: Share your AI prompt that stumps every model
- 32
Quantum error correction below the surface code threshold
Hacker News threads
- Aug 2024Quantum error correction below the surface code threshold
- Dec 2024Quantum error correction below the surface code threshold
- Aug 2024Google proves Fault-Tolerant Quantum Computing is possible
- Sep 2024Qubit Transistors Reach Error Correction Benchmark
- Nov 2024IBM Quantum delivers on 2022 100x100 performance challenge
- Nov 2024Understanding Google's Quantum Error Correction Breakthrough
- Nov 2024Understanding Google's Quantum Error Correction Breakthrough
- Dec 2024Willow, Our Quantum Chip
- Dec 2024Willow, Our Quantum Chip
- Feb 2025Why Quantum Cryptanalysis is Bollocks [pdf]
- Aug 2025OpenSSH Post-Quantum Cryptography
- 33
No "Zero-Shot" Without Exponential Data: Pretraining Concept Frequency Determines Multimodal Model Performance
Hacker News threads
- May 2024No "Zero-Shot" Without Exponential Data
- Apr 2024No "Zero-Shot" Without Exponential Data
- Apr 2024No "Zero-Shot" Without Exponential Data
- May 2024Geoffrey Hinton "godfather of AI" says that AI will surpass human intelligence
- Jun 2024Mathematical Optimization for Cargo Ships
- Jun 2024OpenAI and Apple Announce Partnership
- Jun 2024Ask HN: When will we hit a limit on LLM performance?
- Jul 2024Vision language models are blind
- Jul 2024Ask HN: Are there videos of people using AI for non-trivial coding?
- Nov 2024OpenAI, Google and Anthropic are struggling to build more advanced AI
- Feb 2026(AI) Slop Terrifies Me
- 34
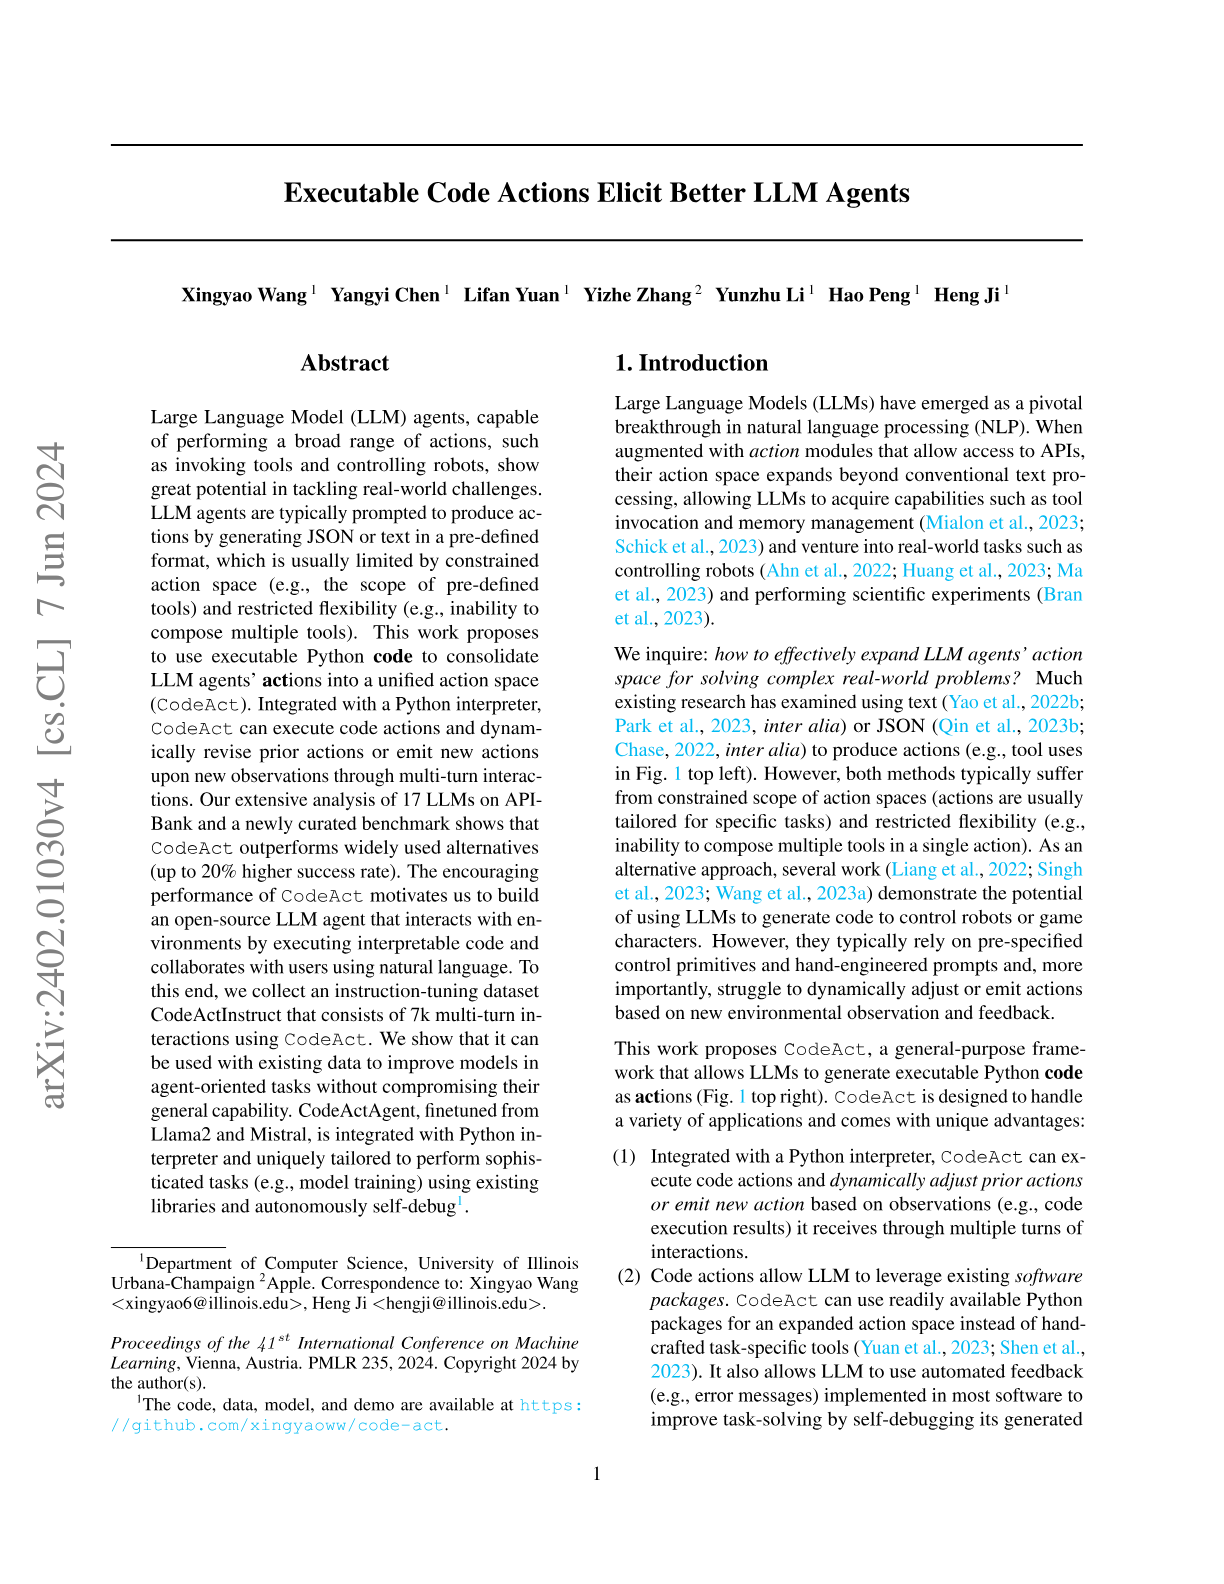
Executable Code Actions Elicit Better LLM Agents
Hacker News threads
- May 2024Executable Code Actions Elicit Better LLM Agents
- Jan 2025Show HN: Gemini 2 with unrestricted code execution
- Jul 2025Tools: Code Is All You Need
- Aug 2025Universal Tool Calling Protocol (UTCP)
- Dec 2025Anthropic acquires Bun
- Aug 2026Mistral Patent for "Code implemented tool calls"
- Aug 2026Mistral Patent for "Code implemented tool calls"
- Aug 2026Mistral Patent for "Code implemented tool calls"
- 35
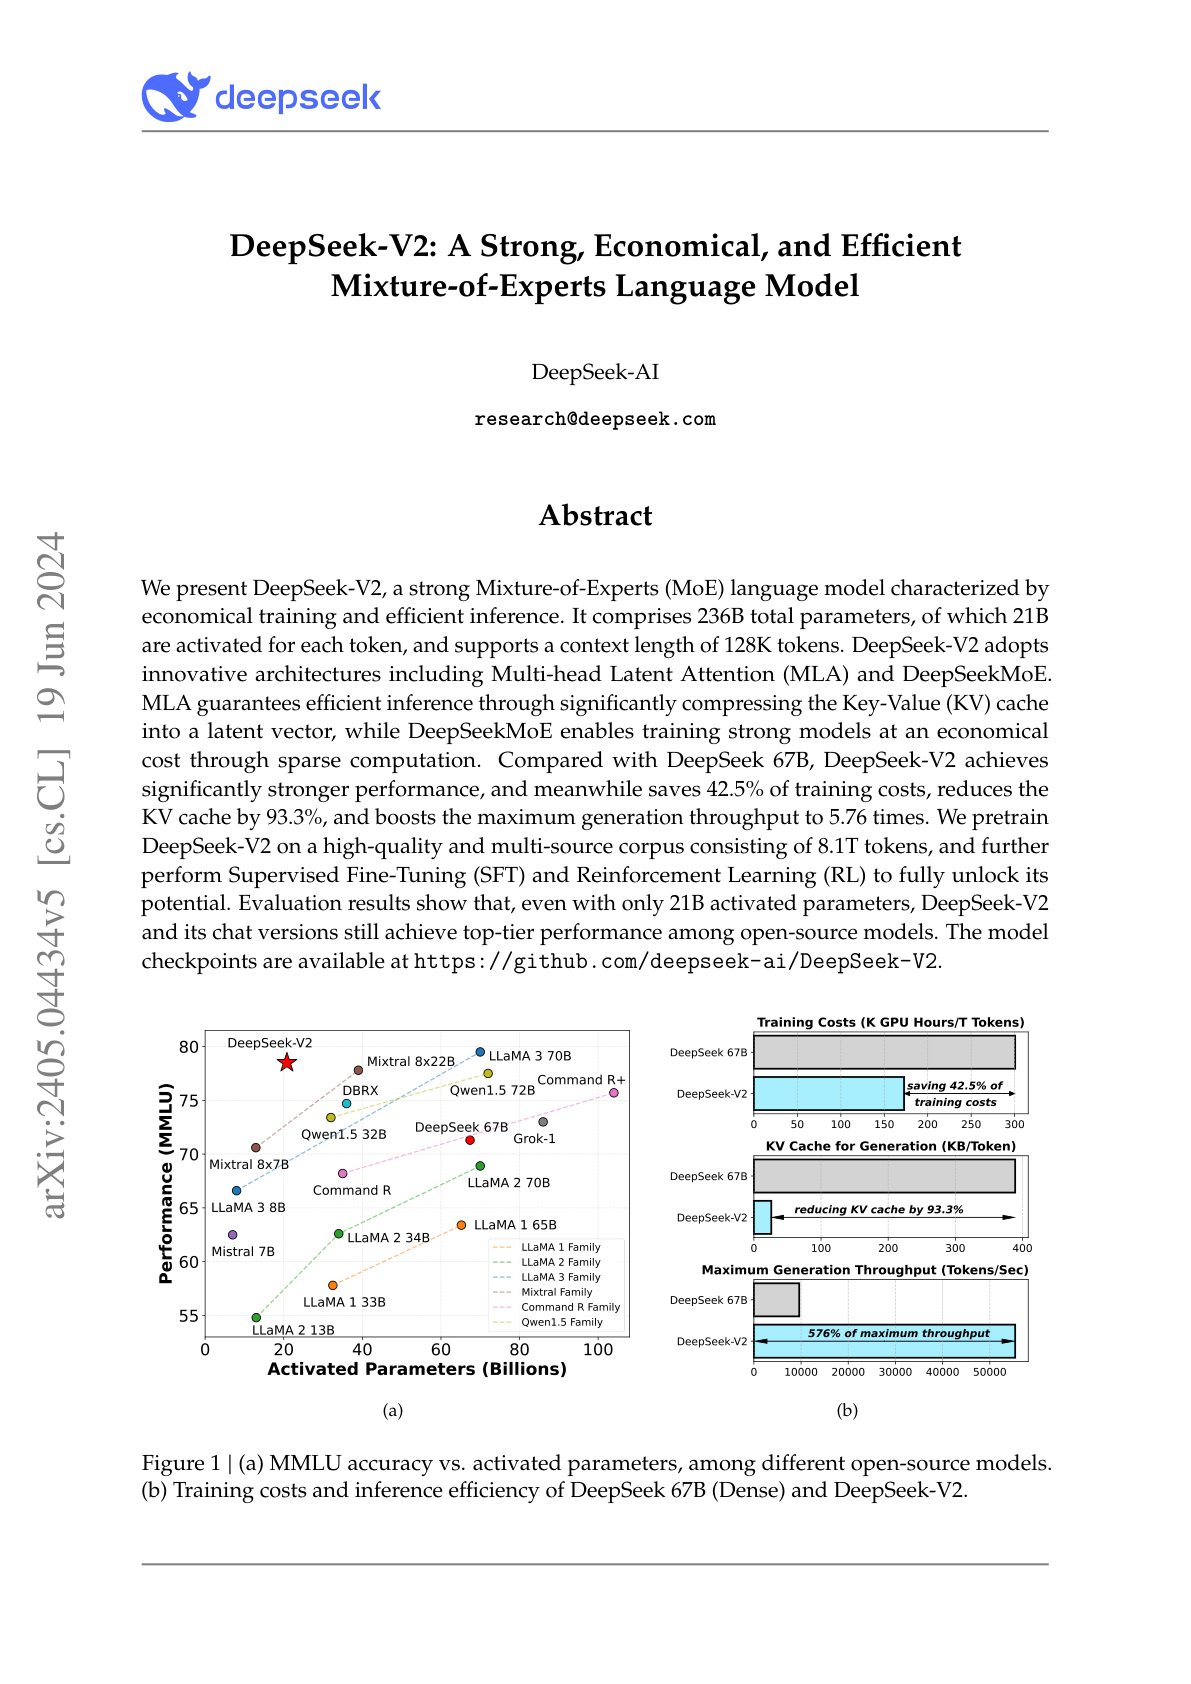
DeepSeek-V2: A Strong, Economical, and Efficient Mixture-of-Experts Language Model
Hacker News threads
- Jan 2025DeepSeek-V2: A Strong, Economical, and Efficient MOE Language Model
- Jan 2025DeepSeek's multi-head latent attention and other KV cache tricks
- Apr 2025Xiaomi MiMo Reasoning Model
- May 2025Attention Wasn't All We Needed
- Dec 2025Zebra-Llama – Towards efficient hybrid models
- Dec 2025Google Titans architecture, helping AI have long-term memory
- Jun 2026How LLMs Work
- 36
Were RNNs All We Needed?
Hacker News threads
- 37
More Agents Is All You Need
Hacker News threads
- Apr 2024More Agents Is All You Need: LLMs performance scales with the number of agents
- Feb 2024More Agents Is All You Need
- Feb 2024More Agents Is All You Need
- Mar 2024Claude 3 beats GPT-4 on Aider's code editing benchmark
- Apr 2024Storm: LLM system that researches a topic and generates full-length wiki article
- Aug 2024AI agents but they're working in big tech
- Sep 2024Learning to Reason with LLMs
- Jan 2025Agents Are Not Enough
- 38
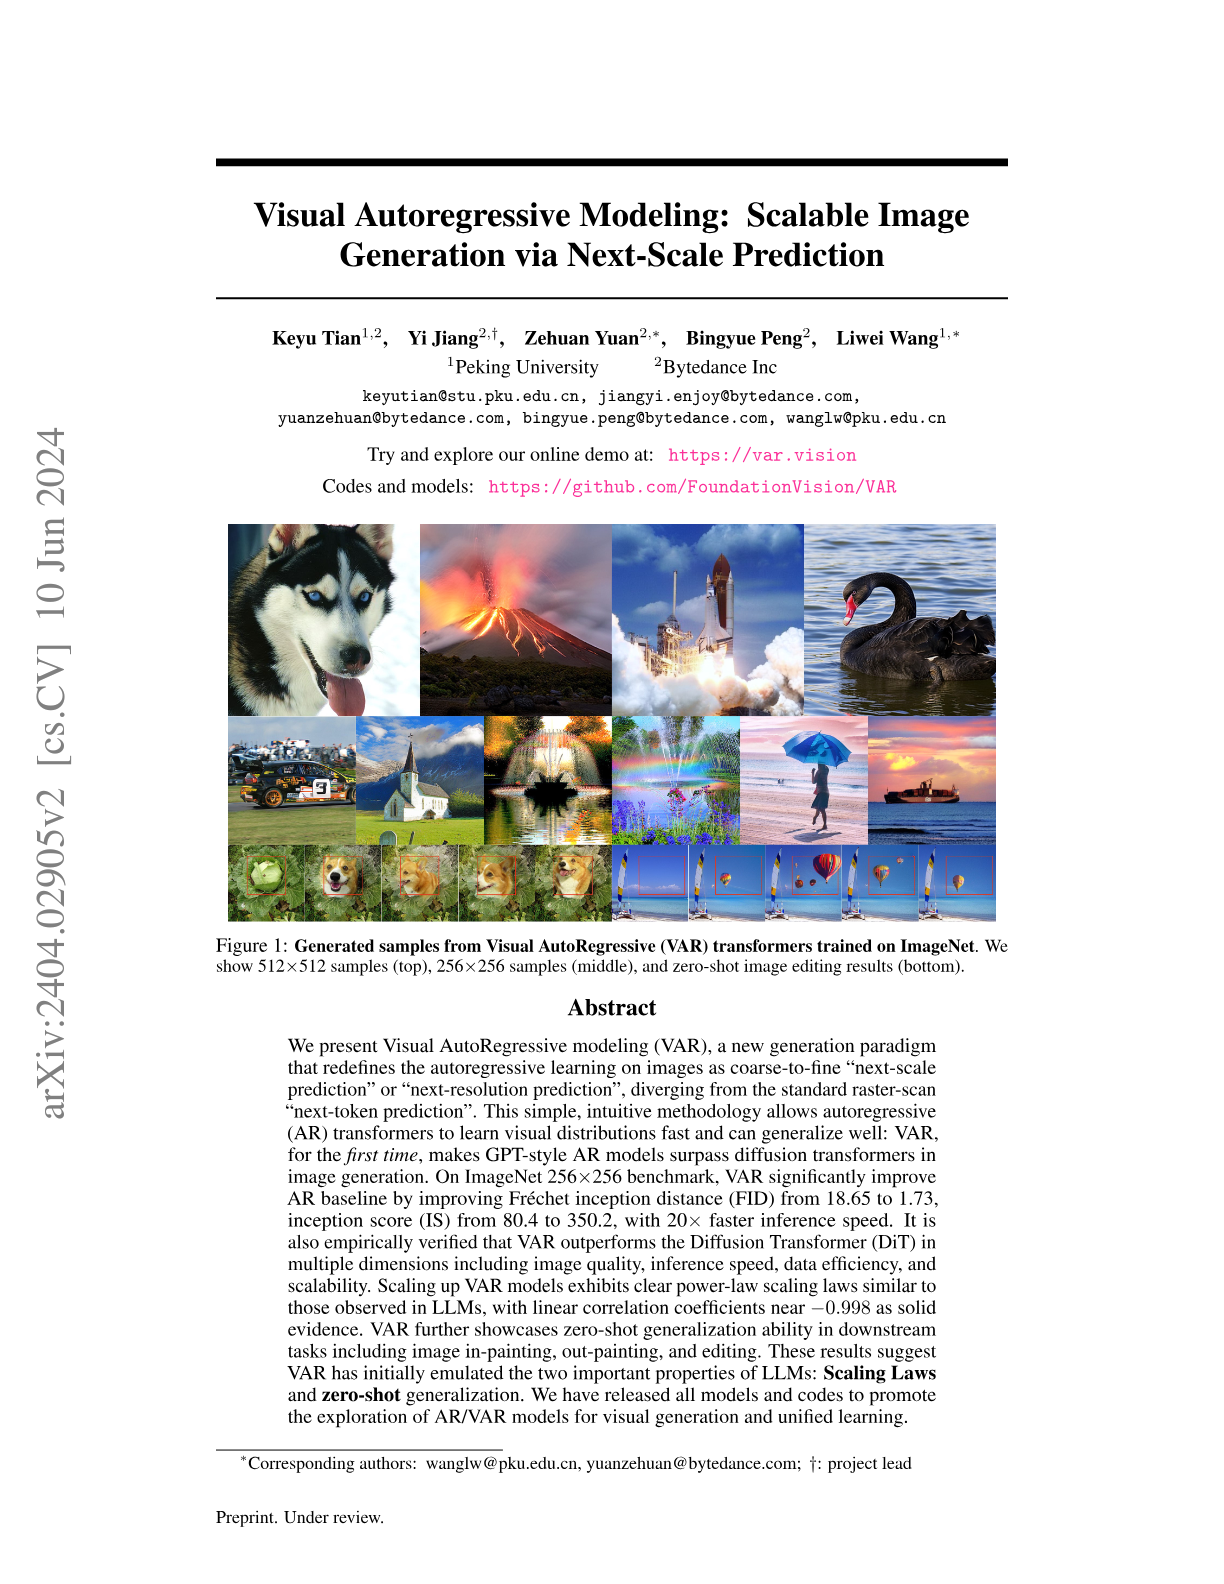
Visual Autoregressive Modeling: Scalable Image Generation via Next-Scale Prediction
Hacker News threads
- Apr 2024Visual Autoregressive Modeling: Scalable Image Generation W NextScale Prediction
- Oct 2024Visual Autoregressive Modeling: Image Generation via Next-Resolution Prediction
- Oct 2024Faster convergence for diffusion models
- Mar 20254o Image Generation
- Apr 2025No elephants: Breakthroughs in image generation
- Apr 2025No elephants: Breakthroughs in image generation
- May 2025Diffusion models explained simply
- Aug 2025Ask HN: Who wants to be hired? (August 2025)
- 39
Mixtral of Experts
Hacker News threads
- Jan 2024Mixtral 8x7B: A sparse Mixture of Experts language model
- Feb 2024Mistral AI launches Mixtral-Next
- Feb 2024Gemma: New Open Models
- Nov 2024TokenFormer: Rethinking Transformer Scaling with Tokenized Model Parameters
- Dec 2024What happens if we remove 50 percent of Llama?
- Jul 2026Small AI Models Gain Traction In places with unreliable networks
- Jul 2026Getting GLM 5.2 running on my slow computer
- 40
Moshi: a speech-text foundation model for real-time dialogue
Hacker News threads
- 41
Is Model Collapse Inevitable? Breaking the Curse of Recursion by Accumulating Real and Synthetic Data
Hacker News threads
- May 2024Is Model Collapse Inevitable?
- Jul 2024Avoiding Model Collapse via Accumulating Real and Synthetic Data
- Apr 2024Is Model Collapse Inevitable? Breaking the Curse with Real and Synthetic Data
- Jun 2024Gemma 2: Improving Open Language Models at a Practical Size [pdf]
- Dec 2024The Curse of Recursion: Training on generated data makes models forget (2023)
- Aug 2026C2PA Cameras Do Not Survive Contact with Reality
- Aug 2026The turbulent AI era is here
- Sep 2026Everyone should slow down AI development except for me
- Sep 2026Everyone should slow down AI development except for me
- 42
xLSTM: Extended Long Short-Term Memory
Hacker News threads
- May 2024xLSTM: Extended Long Short-Term Memory
- May 2024Ilya Sutskever: “If you learn all of these, you’ll know 90% of what matters”
- May 2024New attention mechanisms that outperform standard multi-head attention
- Jun 2024xLSTM code release by NX-AI
- Oct 2024Were RNNs all we needed?
- Feb 2025Ask HN: Is anybody building an alternative transformer?
- 43
Should We Respect LLMs? A Cross-Lingual Study on the Influence of Prompt Politeness on LLM Performance
Hacker News threads
- Apr 2025Should We Respect LLMs? A Study on Influence of Prompt Politeness on Performance
- Feb 2025The Influence of Prompt Politeness on LLM Performance
- Feb 2024Should We Respect LLMs? Studying the Influence of Politeness on LLM Performance
- Sep 2025A staff engineer's journey with Claude Code
- Sep 2025Qwen3-VL
- Feb 2026Stop Thinking of AI as a Coworker. It's an Exoskeleton
- Apr 2026Talk like caveman
- Oct 2026Anthropic asks users to stop being mean to Claude
- 44
Reinforcement Learning: An Overview
Hacker News threads
- Feb 2025Reinforcement Learning: An Overview
- Dec 2024Reinforcement Learning: An Overview
- Feb 2025RLHF Book
- Mar 2025Mathematical Foundations of Reinforcement Learning
- Mar 2025A (Long) Peek into Reinforcement Learning
- Nov 2025CS234: Reinforcement Learning Winter 2025
- Jun 2026The 90-year-old idea behind JEPA models: Canonical Correlation Analysis
- 45
Physics of Language Models: Part 3.3, Knowledge Capacity Scaling Laws
Hacker News threads
- Apr 2024Physics of Language Models: Part 3.3, Knowledge Capacity Scaling Laws
- Jun 2024Researchers run high-performing LLM on the energy needed to power a lightbulb
- Jan 2025Nepenthes is a tarpit to catch AI web crawlers
- Jun 2025Meta's Llama 3.1 can recall 42 percent of the first Harry Potter book
- Oct 2025How to inject knowledge efficiently? Knowledge infusion scaling law for LLMs
- 46
Dolma: an Open Corpus of Three Trillion Tokens for Language Model Pretraining Research
Hacker News threads
- 47
Large Concept Models: Language Modeling in a Sentence Representation Space
Hacker News threads
- 48
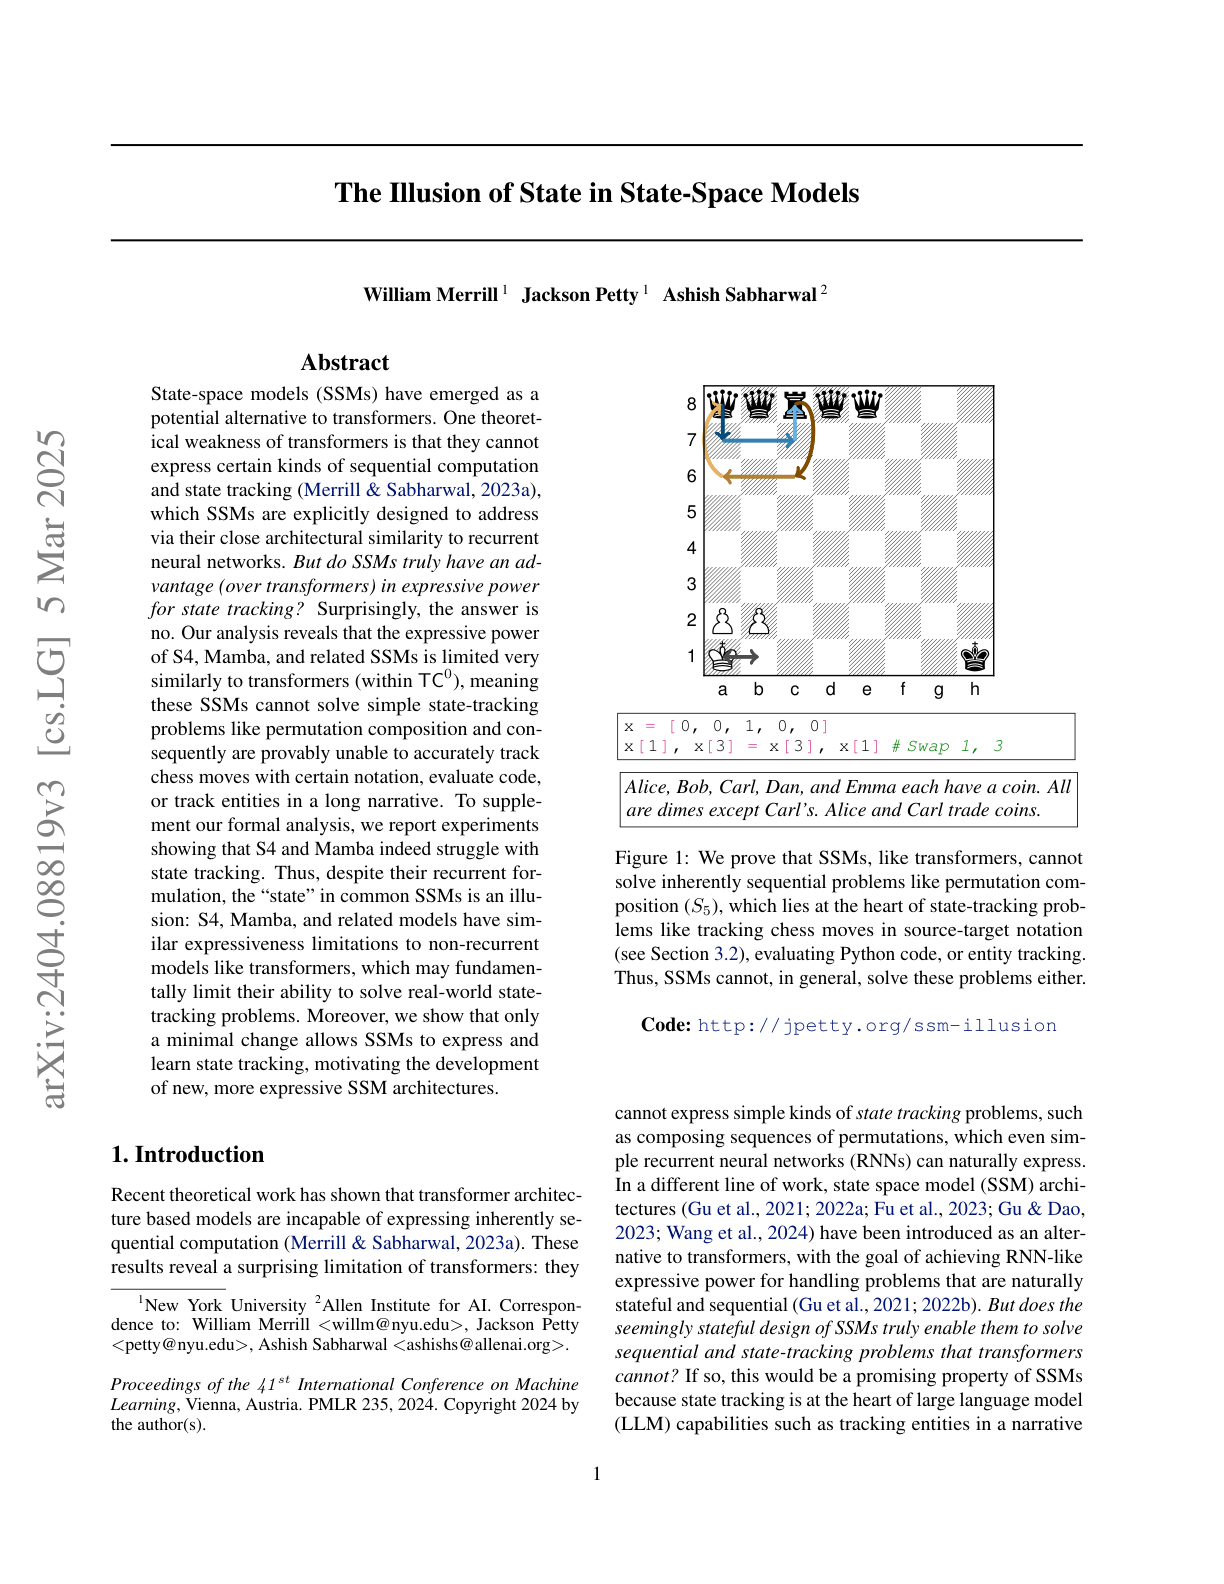
The Illusion of State in State-Space Models
Hacker News threads
- Jun 2024The illusion of state in state-space models
- Apr 2024The illusion of state in state-space models
- Apr 2024The Illusion of State in State-Space Models
- May 2024Meta AI chief says large language models will not reach human intelligence
- Jun 2024Mamba-2 – State Space Duality
- Oct 2024Were RNNs all we needed?
- Jan 2025RWKV Language Model
- 49
Superhuman performance of a large language model on the reasoning tasks of a physician
Hacker News threads
- May 2025Superhuman performance of an LLM on the reasoning tasks of a physician
- Dec 2024Superhuman performance of an LLM on the reasoning tasks of a physician
- Jan 2025Superhuman performance of an LLM on the reasoning tasks of a physician
- Jan 2025Things we learned about LLMs in 2024
- Jan 2025Stargate Project: SoftBank, OpenAI, Oracle, MGX to build data centers
- May 2025The ‘white-collar bloodbath’ is all part of the AI hype machine
- May 2026OpenAI's o1 correctly diagnosed 67% of ER patients vs. 50-55% by triage doctors
- 50
Persistent Pre-Training Poisoning of LLMs
Hacker News threads
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.