Hacker Papers
- 26
Flow Matching for Generative Modeling
Hacker News threads
- 27
Quantifying Memorization Across Neural Language Models
Hacker News threads
- Mar 2023Quantifying memorization across language models
- Aug 2022Exploring 12M of the 2.3B images used to train Stable Diffusion
- Nov 2022Ask HN: What can I personally do to fight AGAINST the Copilot class action?
- Mar 2023PG: We can't all use AI. Someone has to generate the training data
- Aug 2024Judge dismisses majority of GitHub Copilot copyright claims
- Apr 2025Migrating away from Rust
- Jul 2026The Kimi K3 Moment
- 28
Petals: Collaborative Inference and Fine-tuning of Large Models
Hacker News threads
- Jul 2026Petals: Collaborative Inference and Fine-Tuning of Large Models
- Mar 2023Petals: Collaborative Inference and Fine-Tuning of Large Models
- Dec 2022Petals is creating a free, distributed network for running text-generating AI
- Jan 2023Petals: Run 100B+ language models at home bit-torrent style
- Jan 2023Petals: Run 100B+ language models at home bit-torrent style
- Jan 2023Ask HN: Can you crowdfund the compute for GPT?
- Feb 2023Running large language models like ChatGPT on a single GPU
- Mar 2023The Most Cited AI Papers in 2022
- 29
Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks
Hacker News threads
- Dec 2023RAG: Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks
- Mar 2021Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks
- Jan 2023Wolfram Alpha as the Way to Bring Computational Knowledge Superpowers to ChatGPT
- May 2023Anthropic - Introducing 100K Token Context Windows, Around 75,000 Words
- Jun 2023Emerging Architectures for LLM Applications
- Aug 2023GPU-Accelerated LLM on a $100 Orange Pi
- Aug 2023How do domain-specific chatbots work? A retrieval augmented generation overview
- Nov 2023Grok
- Mar 2024Show HN: Ragdoll Studio (fka Arthas.AI) is the FOSS alternative to character.ai
- Jul 2026We taught a small LLM to throw away 68% of our RAG context
- 30
The case for 4-bit precision: k-bit Inference Scaling Laws
Hacker News threads
- Jul 2023The case for 4-bit precision: k-bit Inference Scaling Laws
- Jan 2023Some Remarks on Large Language Models – Yoav Goldberg
- Mar 2023LLaMA-7B in Pure C++ with full Apple Silicon support
- Mar 2023Llama.cpp 30B runs with only 6GB of RAM now
- Aug 2023How Is LLaMa.cpp Possible?
- Nov 2023QUIK is a method for quantizing LLM post-training weights to 4 bit precision
- Jan 2024Meta AI releases Code Llama 70B
- Nov 2024AMD now has more compute on the top 500 than Nvidia
- Jun 2026Qwen 3.6 27B is the sweet spot for local development
- 31
Silent Data Corruptions at Scale
Hacker News threads
- Feb 2024Silent data corruptions at scale (2021)
- Jun 2021Silent Data Corruptions at Scale
- Jul 2021Silent Data Corruptions at Scale
- Jun 2021Cores that don’t count [pdf]
- Jul 2021Single random bit flip causes error in certificate transparency log
- Jul 2021Single random bit flip causes error in certificate transparency log
- May 2022Removing characters from strings faster with AVX-512
- Jan 2023ECC RAM should be a human right
- Feb 2024Intel Processor Instability Causing Oodle Decompression Failures
- Aug 2024Puget Systems' Perspective on Intel CPU Instability Issues
- 32
Fast Inference from Transformers via Speculative Decoding
Hacker News threads
- Sep 2023Fast Inference from Transformers via Speculative Decoding
- Jul 2025Playing with Open Source LLMs
- Feb 2026Raspberry Pi Pico 2 at 873.5MHz with 3.05V Core Abuse
- Apr 2026We got 207 tok/s with Qwen3.5-27B on an RTX 3090
- May 2026Accelerating Gemma 4: faster inference with multi-token prediction drafters
- Jun 2026DeepSeek open-sources inference optimizations with 60–85% faster generation [pdf]
- Jun 2026DeepSeek open-sources inference optimizations with 60–85% faster generation [pdf]
- Jun 2026DeepSeek open-sources inference optimizations with 60–85% faster generation [pdf]
- 33
GLU Variants Improve Transformer
Hacker News threads
- Aug 2023Llama from Scratch (or how to implement a paper without crying)
- Nov 2023Simplifying Transformer Blocks
- Sep 2024SwiGLU activation function causes instability in FP8 LLM training
- Jun 2026Don't trust large context windows
- Jun 2026Anthropic to Require ID Verification for Certain Capabilities Starting July 8
- 34
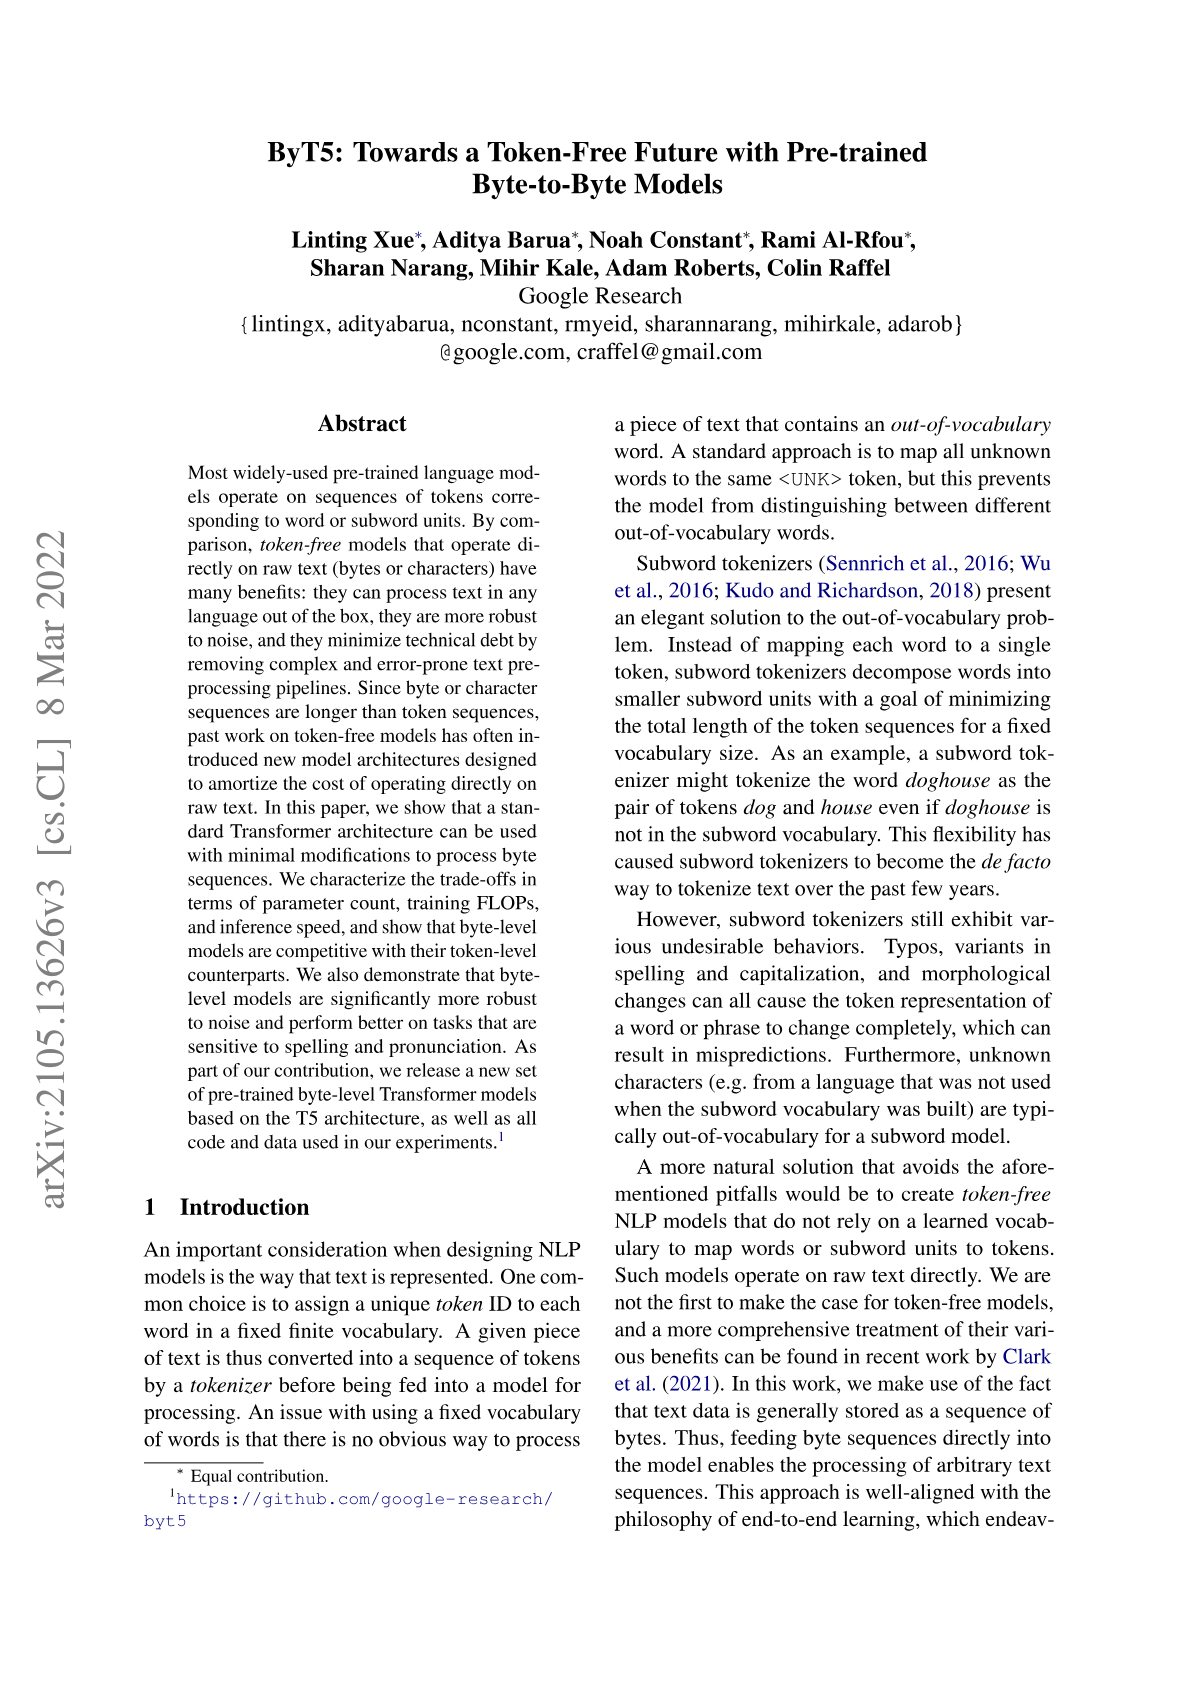
ByT5: Towards a token-free future with pre-trained byte-to-byte models
Hacker News threads
- May 2022Teaching GPT-3 to reverse words
- Dec 2022ChatGPT, Rot13, and Daniel Kahneman
- Mar 2023Cerebras-GPT vs. LLaMA AI Model Performance Comparison
- Apr 2023A Baby GPT
- Jun 2023Understanding GPT Tokenizers
- Aug 2024Markov chains are funnier than LLMs
- Nov 2024Something weird is happening with LLMs and chess
- Jun 2026Data Compression Explained
- 35
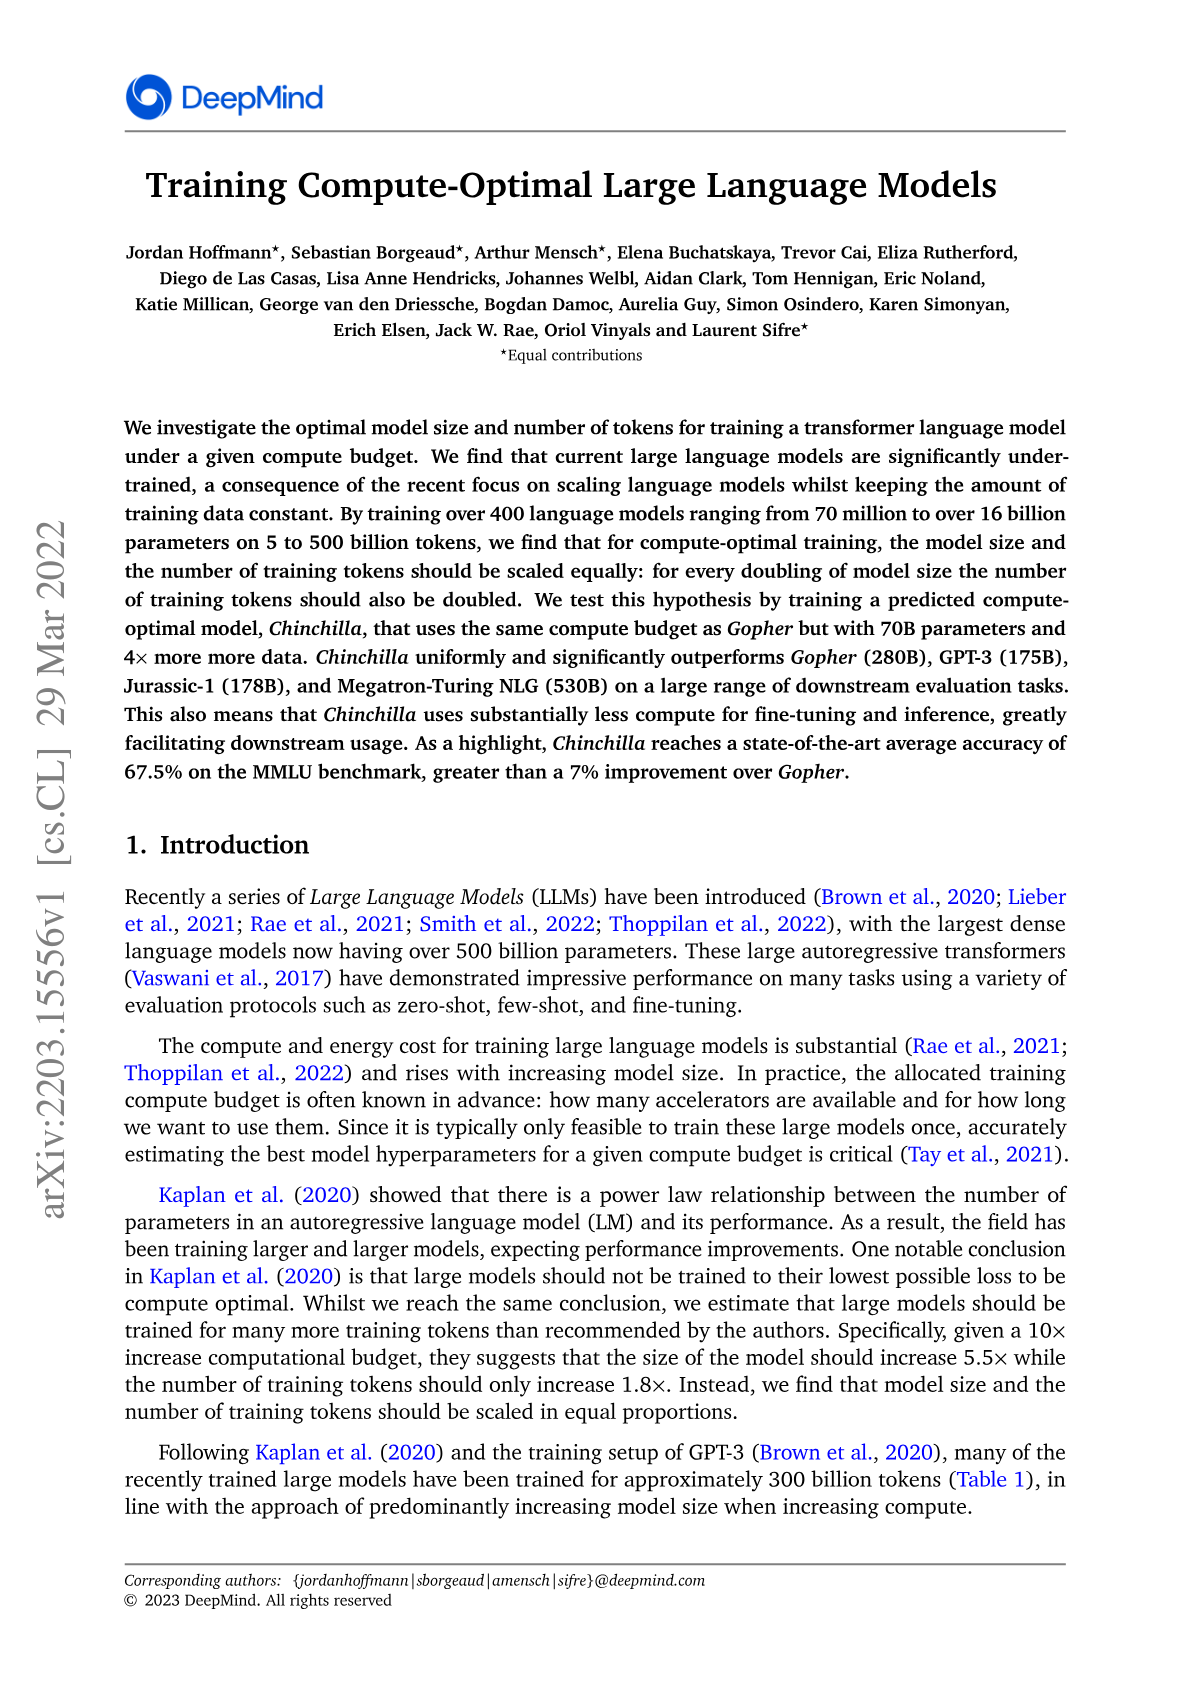
Training Compute-Optimal Large Language Models
Hacker News threads
- Apr 2022Training Compute-Optimal Large Language Models
- Mar 202270B language model outperforms Gopher and GPT-3
- Sep 2022Training Compute-Optimal Large Language Models
- Apr 2022Estimating PaLM's Training Cost
- Oct 2022GPT-3 can create both sides of an Interactive Fiction transcript
- Feb 2023Sundar Pichai: An important next step on our AI journey
- Mar 2023LLaMA-7B in Pure C++ with full Apple Silicon support
- Apr 2023OpenAI’s CEO confirms the company isn’t training GPT-5 and ‘won’t for some time’
- Jul 2023Free and Fast LLM Finetuning
- Dec 2023Ask HN: AI/ML papers to catch up with current state of AI?
- Jun 2026Cohere's First Model for Developers
- 36
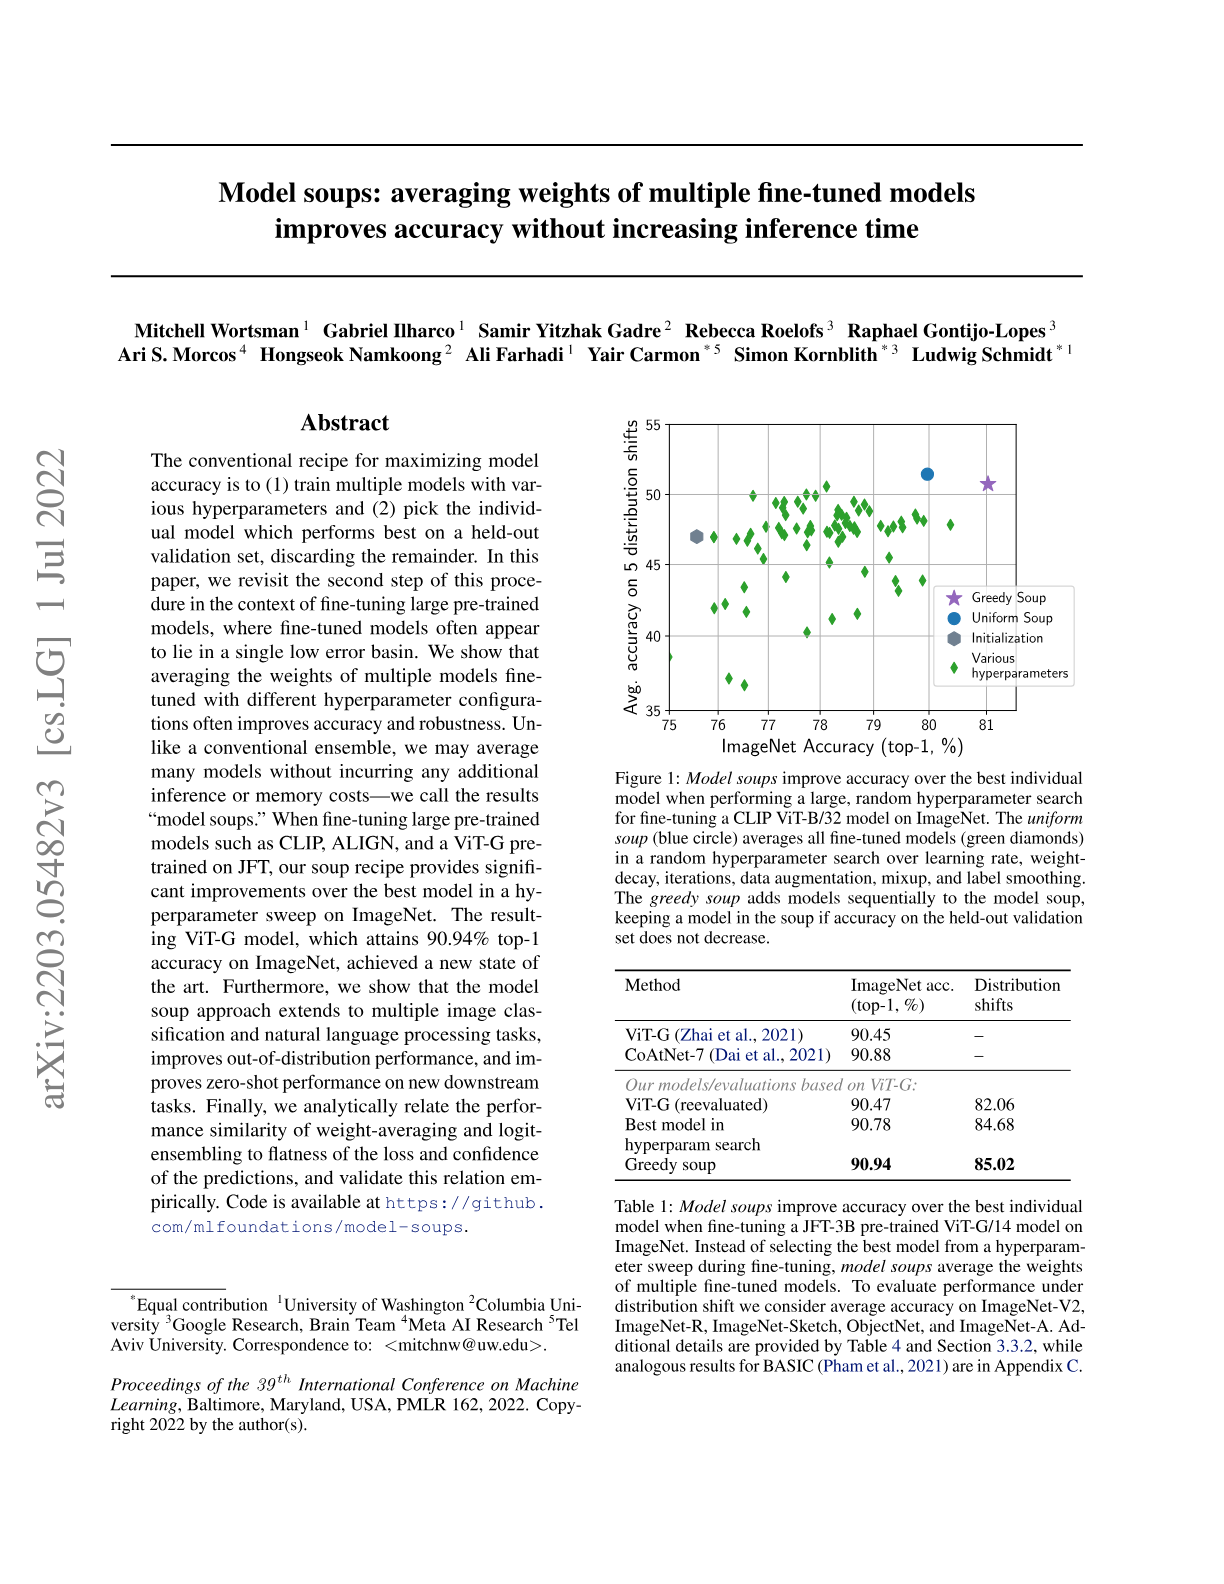
Model soups: averaging weights of multiple fine-tuned models improves accuracy without increasing inference time
Hacker News threads
- Dec 2024Beyond Gradient Averaging in Parallel Optimization
- Mar 2026NanoGPT Slowrun: Language Modeling with Limited Data, Infinite Compute
- Jun 2026Rio de Janeiro's "homegrown" LLM appears to be a merge of an existing model
- Jun 2026Rio de Janeiro's "homegrown" LLM appears to be a merge of an existing model
- 37
Formal Algorithms for Transformers
Hacker News threads
- Jul 2022Formal Algorithms for Transformers
- Jan 2023The Transformer Family
- Apr 2023A Baby GPT
- Apr 2023What Are Transformer Models and How Do They Work?
- May 2023Ask HN: Can someone ELI5 Transformers and the “Attention is all we need” paper
- Jul 2023What We Know About LLMs (A Primer)
- Dec 2023"Attention", "Transformers", in Neural Network "Large Language Models"
- Jan 2024Relearning math as an adult
- Jun 2026Can I Buy Your KV Cache?
- 38
Mission Apollo: Landing Optical Circuit Switching at Datacenter Scale
Hacker News threads
- 39
The Hardware Lottery
Hacker News threads
- Sep 2020The Hardware Lottery
- Sep 2020The Hardware Lottery
- Sep 2020The Hardware Lottery
- Nov 2020Ride the Hardware Lottery
- Apr 2022Large-Scale Matrix Factorization on TPUs
- Jul 2023Ask HN: Which recently research paper blow your mind?
- Oct 2023Nvidia and Foxconn to build 'AI factories'
- Dec 2023A new old kind of R&D lab
- Apr 2025Multi-Token Attention
- May 2026A Eureka machine that thinks like nature and explores what AI cannot
- Jun 2026How LLMs Work
- 40
MLP-Mixer: An all-MLP Architecture for Vision
Hacker News threads
- Sep 2021MLP-Mixer: An All-MLP Architecture for Vision
- May 2021MLP-Mixer: An All-MLP Architecture for Vision
- May 2021X-Transformers: A fully-featured transformer with experimental features
- Nov 2023MeshGPT: Generating Triangle Meshes with Decoder-Only Transformers
- Jun 2026Do transformers need three projections? Systematic study of QKV variants
- 41
Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
Hacker News threads
- Jul 2022Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- May 2023Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- Apr 2023Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- Feb 2022I asked GPT-NeoX-20B a hundred arithmetic questions
- Apr 2022Socratic Models – Composing Zero-Shot Multimodal Reasoning with Language
- Feb 2023Jailbreaking ChatGPT with Dan (Do Anything Now)
- Apr 2023DyLoRA: Parameter Efficient Tuning of Pre-Trained Models
- Aug 2023Do Machine Learning Models Memorize or Generalize?
- May 2024Groq surpasses 1,200 tokens/sec with Llama 3 8B
- Feb 2026Who discovered grokking and why is the name hard to find?
- Jun 2026"They're made out of weights"
- 42
Neural Networks and the Chomsky Hierarchy
Hacker News threads
- Jul 2022Neural Networks and the Chomsky Hierarchy by DeepMind
- Jan 2023Neural Networks and the Chomsky Hierarchy [DeepMind, 2022]
- Aug 2022Deep Learning Alone Isn’t Getting Us to Human-Like AI
- Feb 2023What Is ChatGPT Doing and Why Does It Work?
- Apr 2023Tighter bounds on the expressivity of transformer encoders
- May 2023Ask HN: Why can GPT4 en/decode base64?
- Jun 2023Bard is getting better at logic and reasoning
- Jun 2023Modern language models refute Chomsky’s approach to language
- Nov 2024Interview with gwern
- Jun 2026No, Artificial Intelligence is not Conscious - Ted Chiang
- 43
DreamCoder: Growing generalizable, interpretable knowledge with wake-sleep Bayesian program learning
Hacker News threads
- Dec 2023DreamCoder: Growing Generalizable, Interpretable Knowledge
- Jun 2020DreamCoder: Growing generalizable, interpretable knowledge with program learning
- Feb 2021DreamCoder, a system that learns to solve problems by writing programs
- Dec 2020Ask HN: What's the best paper you've read in 2020?
- May 2021Kobra – visual programming language for machine learning
- Nov 2021GPT-3 is no longer the only game in town
- Feb 2022Competitive Programming with AlphaCode
- Feb 2022Competitive Programming with AlphaCode
- Jul 2022AI Coding with CodeRL: Toward Mastering Program Synthesis with Deep RL
- Sep 2023Doug Lenat has died
- May 2026Language Models Need Sleep
- 44
A Modern Compiler for the French Tax Code
Hacker News threads
- Nov 2020A Modern Compiler for the French Tax Code
- Jul 2024A Modern Compiler for the French Tax Code (2021)
- Jan 2023A Modern Compiler for the French Tax Code
- Dec 2020To the brain, reading computer code is not the same as reading language
- Mar 2021Templating for Lawyers
- May 2021Legalese – Computational Law
- Oct 2021Open Source Tax Software
- Oct 2021Open Source Tax Software
- Jun 2022Show HN: Calculator for US individual income tax, from 1970-present
- Feb 2023Intuit pouring money into lobbying amid push for free government-run tax filing
- May 2026Intuit to lay off over 3k employees to refocus on AI
- 45
NeRF: Representing Scenes as Neural Radiance Fields for View Synthesis
Hacker News threads
- Jul 2021GitHub Copilot as open source code laundering?
- Jul 2021DONeRF: Towards Real-Time Rendering of Compact Neural Radiance Fields
- Jan 2022Instant neural graphics primitives with a multiresolution hash encoding
- Sep 2022DreamFusion: Text-to-3D using 2D Diffusion
- Oct 2022Nerfstudio: A collaboration friendly studio for NeRFs
- Apr 2023HDR-NeRF: High Dynamic Range Neural Radiance Fields
- Oct 2025Show HN: I invented a new generative model and got accepted to ICLR
- May 2026Image-blaster: Creates 3D environments, SFX, and meshes from a single image
- 46
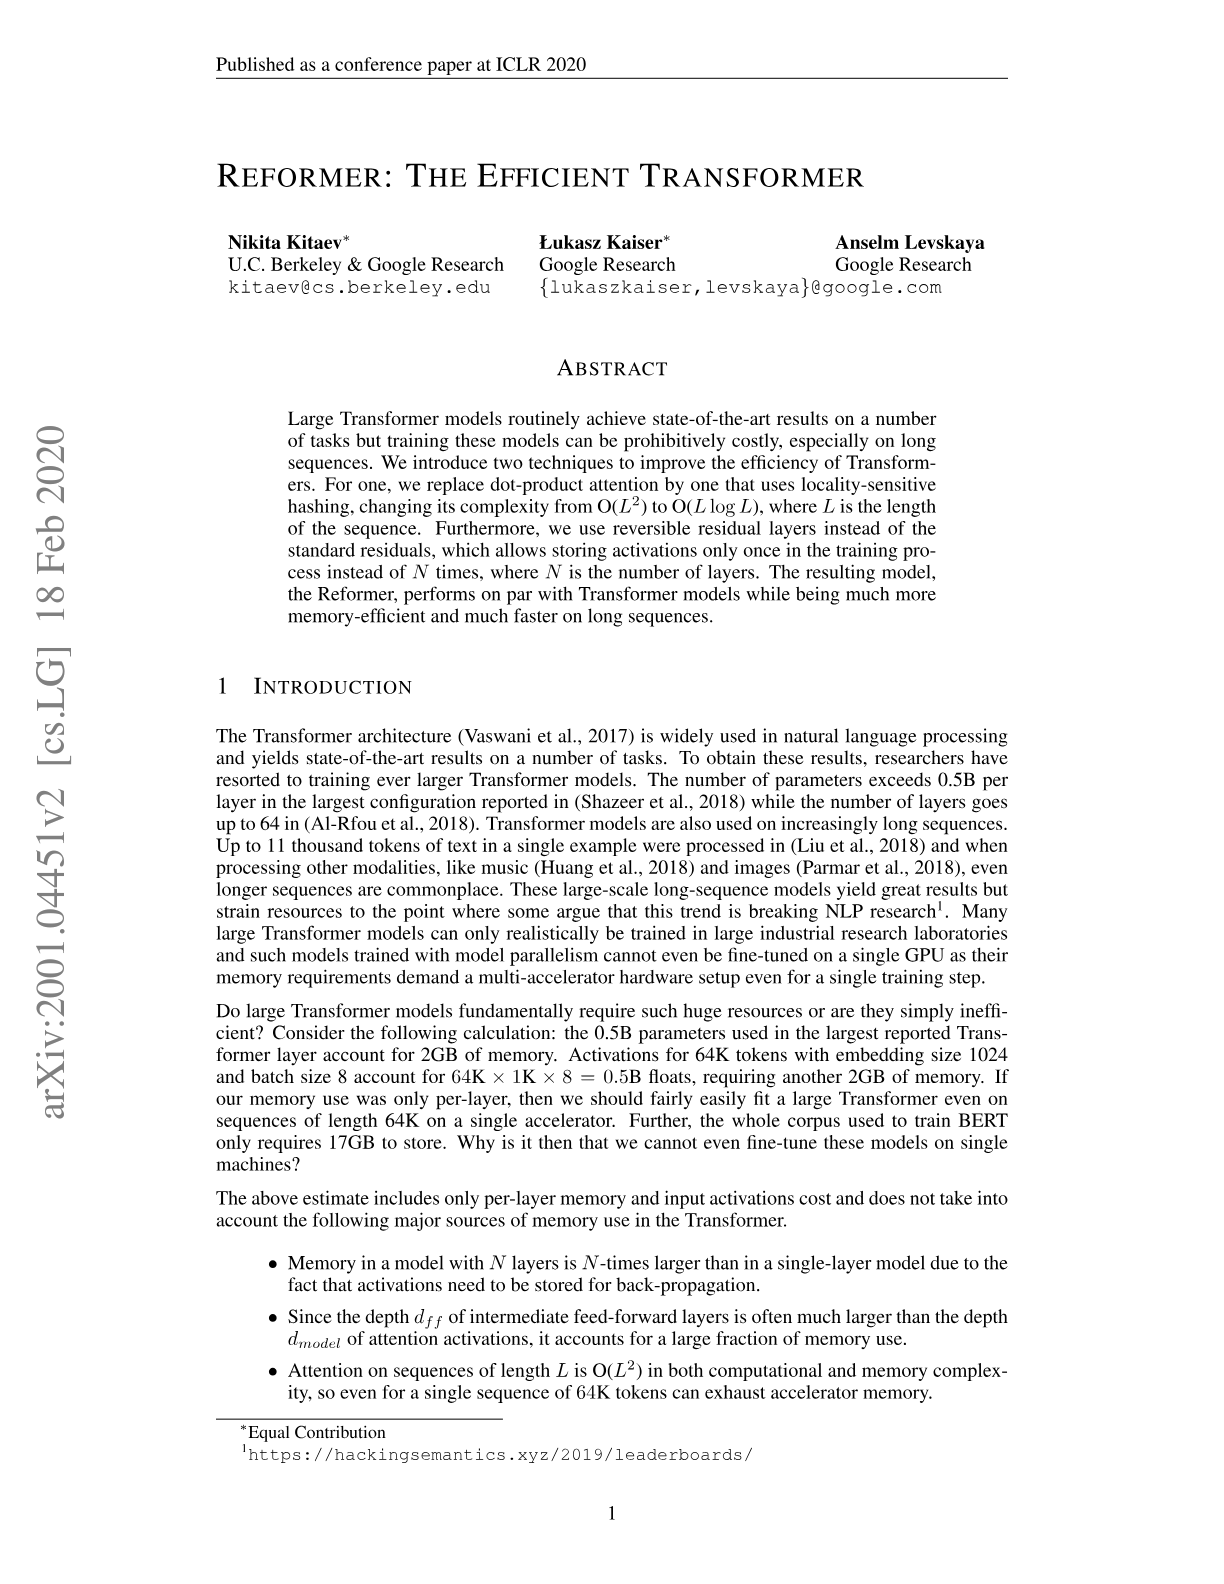
Reformer: The Efficient Transformer
Hacker News threads
- 47
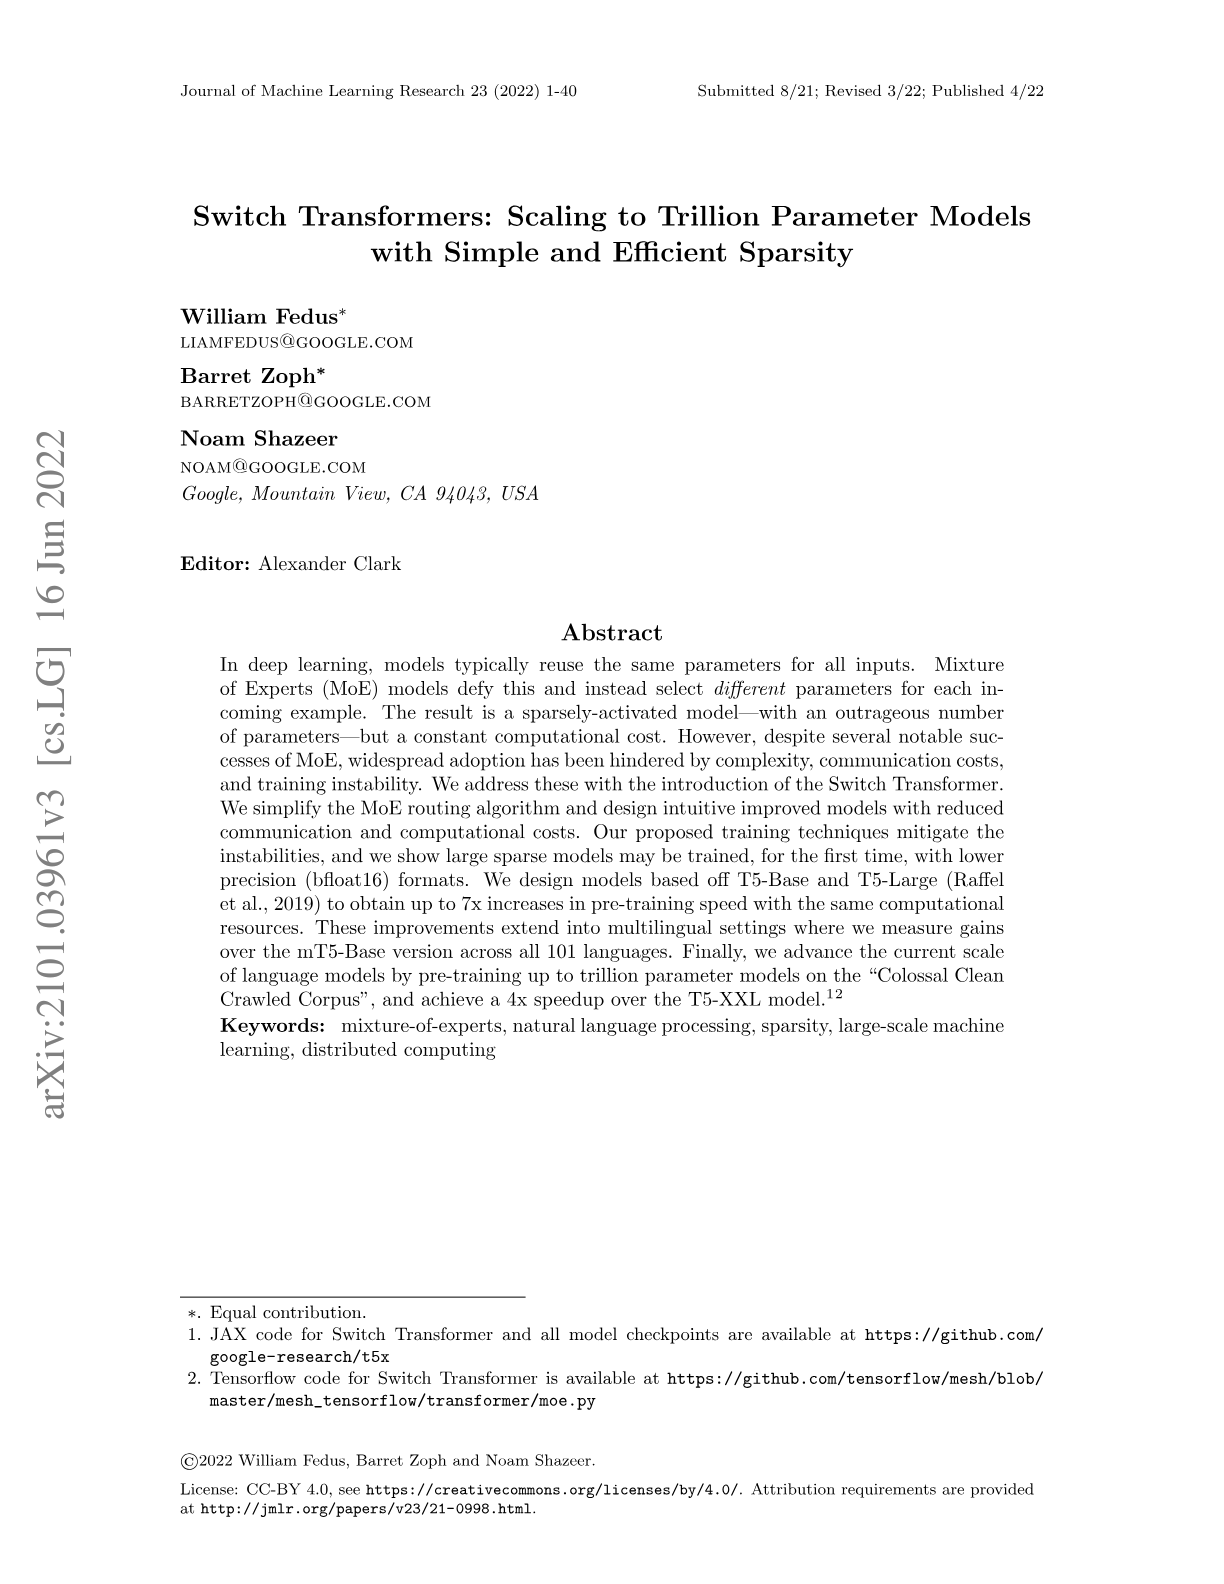
Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity
Hacker News threads
- Jan 2021Google breaks the trillion-parameter ceiling with the Switch Transformer
- Jan 2021Switch Transformers: Scaling to Trillion Parameter Models with Sparsity
- Jan 2021Switch Transformers: Scaling to Trillion Parameter Models with Simple Sparsity
- Aug 2021Program Synthesis with Large Language Models
- Oct 2021Megatron-Turing NLG 530B, the World’s Largest Generative Language Model
- Jan 2022The Illustrated Retrieval Transformer
- Mar 2023GPT-4
- Jun 2023GPT4 is 8 x 220B params = 1.7T params
- Jul 2023GPT-4 is getting worse over time, not better
- Oct 2023Decomposing Language Models into Understandable Components
- May 2026Granite 4.1: IBM's 8B Model Matching 32B MoE
- 48
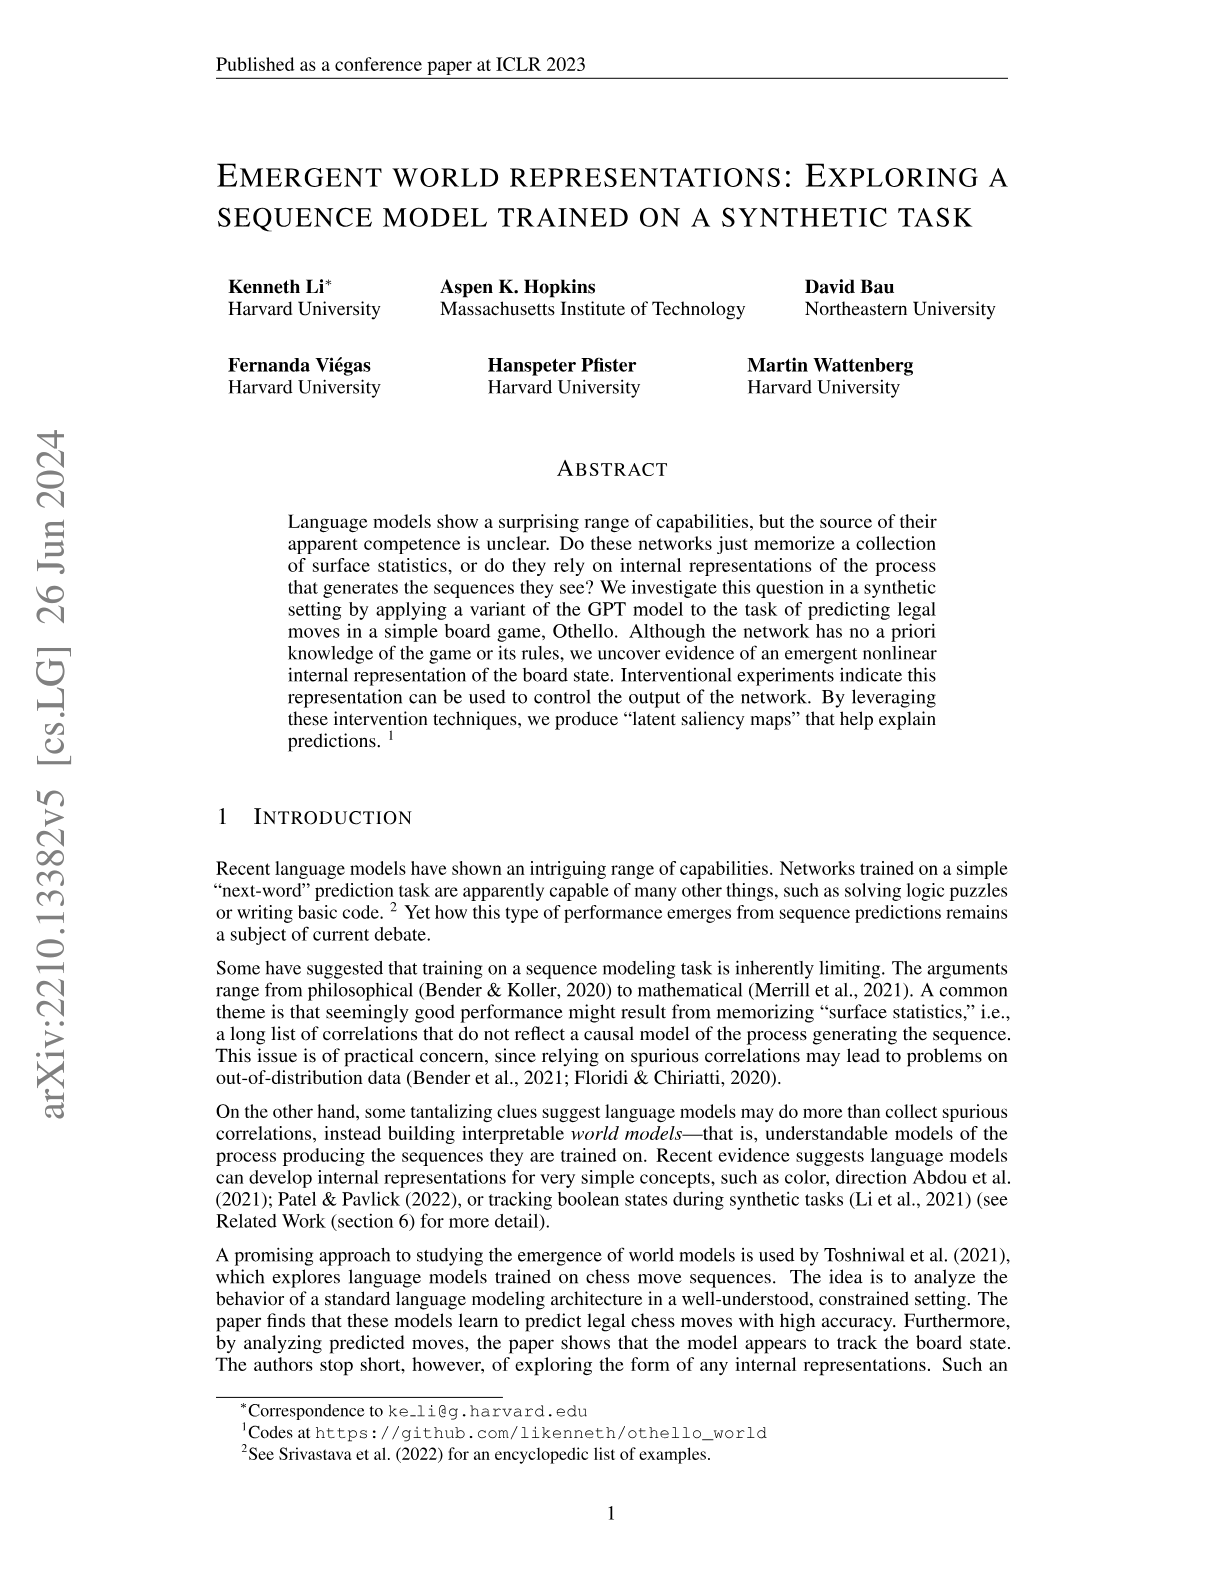
Emergent World Representations: Exploring a Sequence Model Trained on a Synthetic Task
Hacker News threads
- Feb 2023Emergent World Representations in Neural Networks
- Jan 2023Do Large Language Models learn world models or just surface statistics?
- Feb 2023What Is ChatGPT Doing and Why Does It Work?
- Mar 2023GPT-4
- Mar 2023HN thread 35348353
- Apr 2023HN thread 35356648
- May 2023Just Calm Down About GPT-4 Already
- Jun 2024Legal models hallucinate in 1 out of 6 (or more) benchmarking queries
- Apr 2026Where the Goblins Came From
- 49
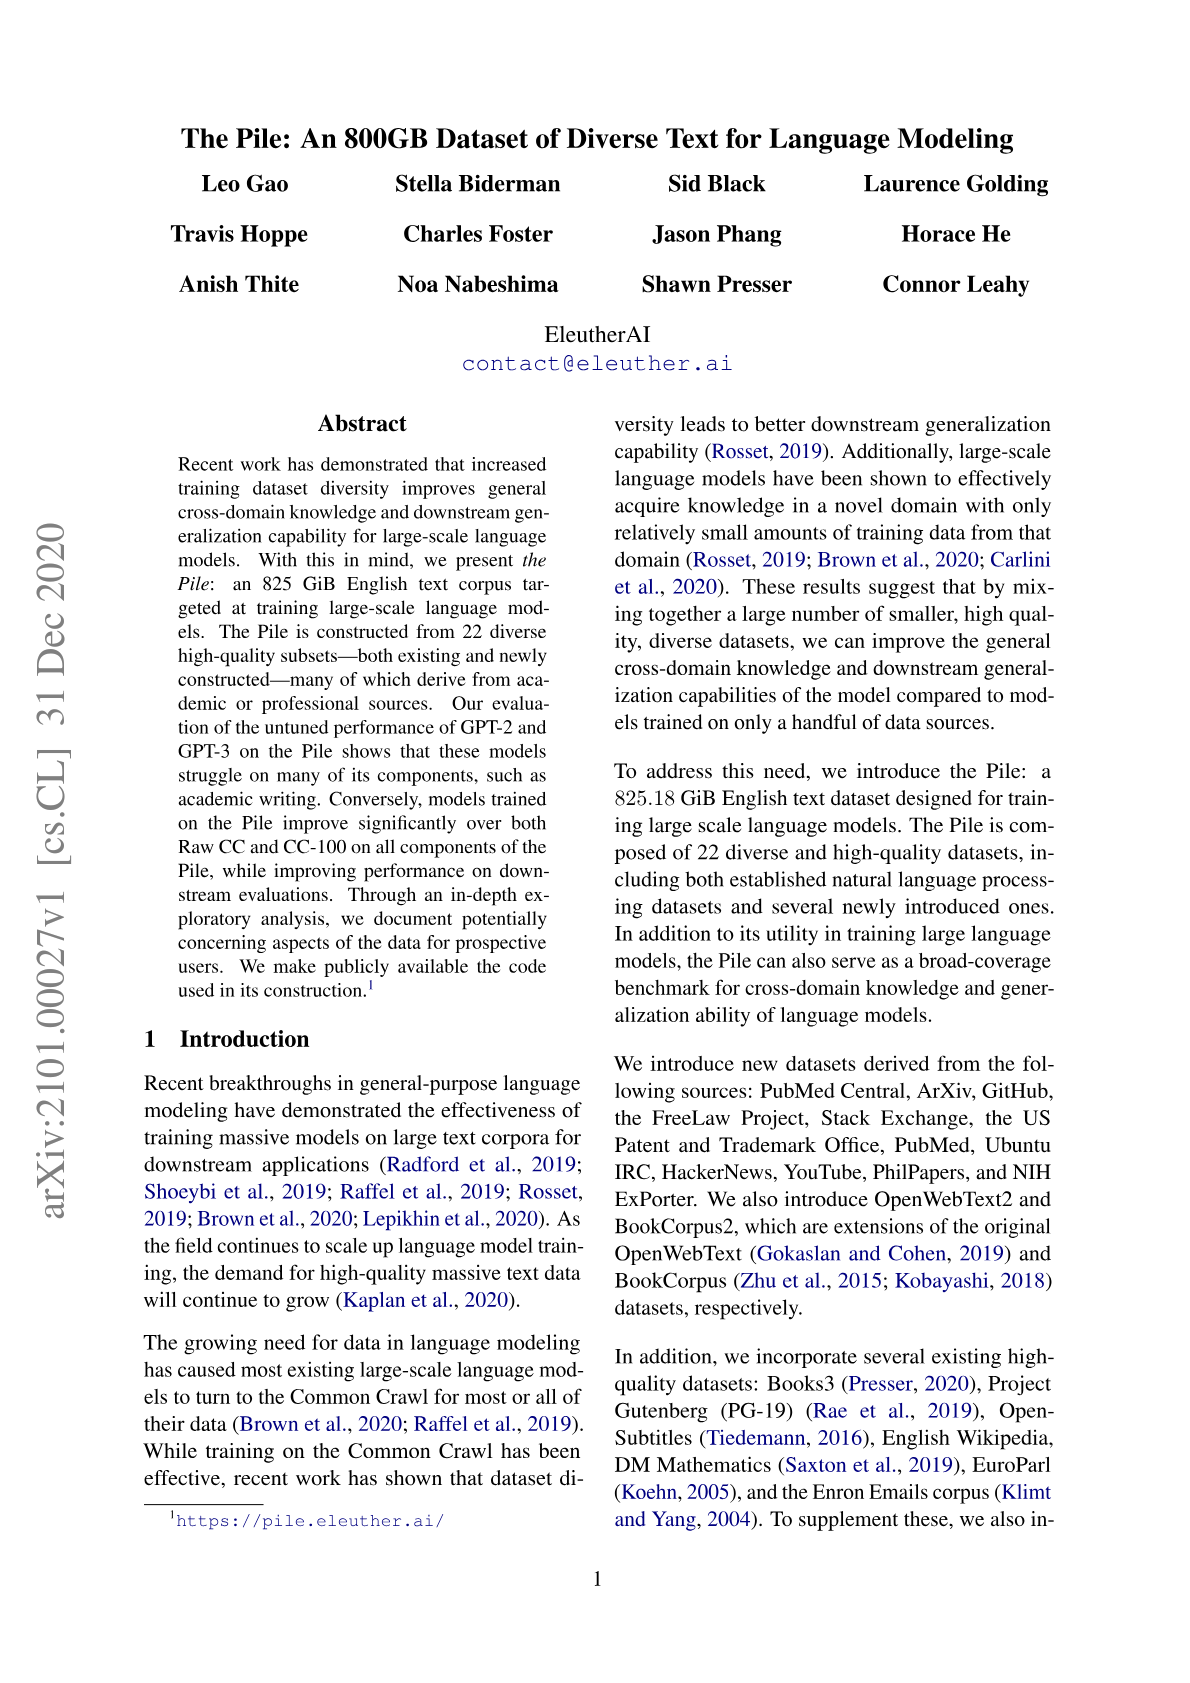
The Pile: An 800GB Dataset of Diverse Text for Language Modeling
Hacker News threads
- Jun 2023The Pile: An 800GB Dataset of Diverse Text for Language Modeling
- May 2021The Pile: An 800GB Dataset of Diverse Text for Language Modeling
- Jul 2023The Pile: a dataset for language modeling [pdf]
- Mar 2021The makers of Eleuther hope it will be an open source alternative to GPT-3
- Apr 2022Textsynth: Bellard's free GPT-NeoX-20B, GPT-J playground and paid API
- Jan 2023The Limits of GPT-3 and Similar Large Language Models
- Apr 2023RedPajama: Reproduction of Llama with Friendly License (Stanford, MILA Quebec)
- Jul 2023Sarah Silverman is suing OpenAI and Meta for copyright infringement
- Sep 2023What OpenAI Really Wants
- Mar 2024DBRX: A new open LLM
- Apr 2026Even 'uncensored' models can't say what they want
- 50
Satoshi Nakamoto and the Origins of Bitcoin -- The Profile of a 1-in-a-Billion Genius
Hacker News threads
- Jul 2022Satoshi Nakamoto and the origins of Bitcoin – the profile of a genius
- Feb 2024Satoshi Nakamoto and the Origins of Bitcoin
- Oct 2024Satoshi Nakamoto and the Origins of Bitcoin
- Feb 2024Satoshi – Sirius emails 2009-2011
- Apr 2024New theory on Satoshi Nakamoto
- Oct 2024HBO Documentary Suggests Bitcoin Creator Satoshi Nakamoto Is Peter Todd
- Oct 2024HBO Documentary Suggests Bitcoin Creator Satoshi Nakamoto Is Peter Todd
- Apr 2026Who Is Satoshi Nakamoto? My Quest to Unmask Bitcoin's Creator
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.