Hacker Papers
- 26
LLMZip: Lossless Text Compression using Large Language Models
Hacker News threads
- Nov 2025LLMZip: Lossless Text Compression Using Large Language Models
- Jul 2023LLMZip: Lossless Text Compression Using Large Language Models
- Mar 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Sep 2024Ask HN: Can tokenizers go from fixed length tokens to varying length?
- Jul 2025Hiding messages in a deck playing cards
- Aug 2026Compression Is Prediction
- 27
Sparks of Artificial General Intelligence: Early experiments with GPT-4
Hacker News threads
- Mar 2023Sparks of Artificial General Intelligence: Early Experiments with GPT-4
- Apr 2025Sparks of Artificial General Intelligence: Early Experiments with GPT-4 (2023)
- Mar 2023ChatGPT Plugins
- Mar 2023Microsoft Researchers Claim GPT-4 Is Showing “Sparks” of AGI
- Mar 2023HN thread 35350030
- Apr 2023The LLama Effect: Leak Sparked a Series of Open Source Alternatives to ChatGPT
- Apr 2023AGI Is Not Chess Bots – They Will Replace Your Jobs
- Jul 2023GPT-4 API General Availability
- Jul 2024ChatGPT is better at generating code for problems written before 2021
- Aug 2026Karpathy's Pelican
- 28
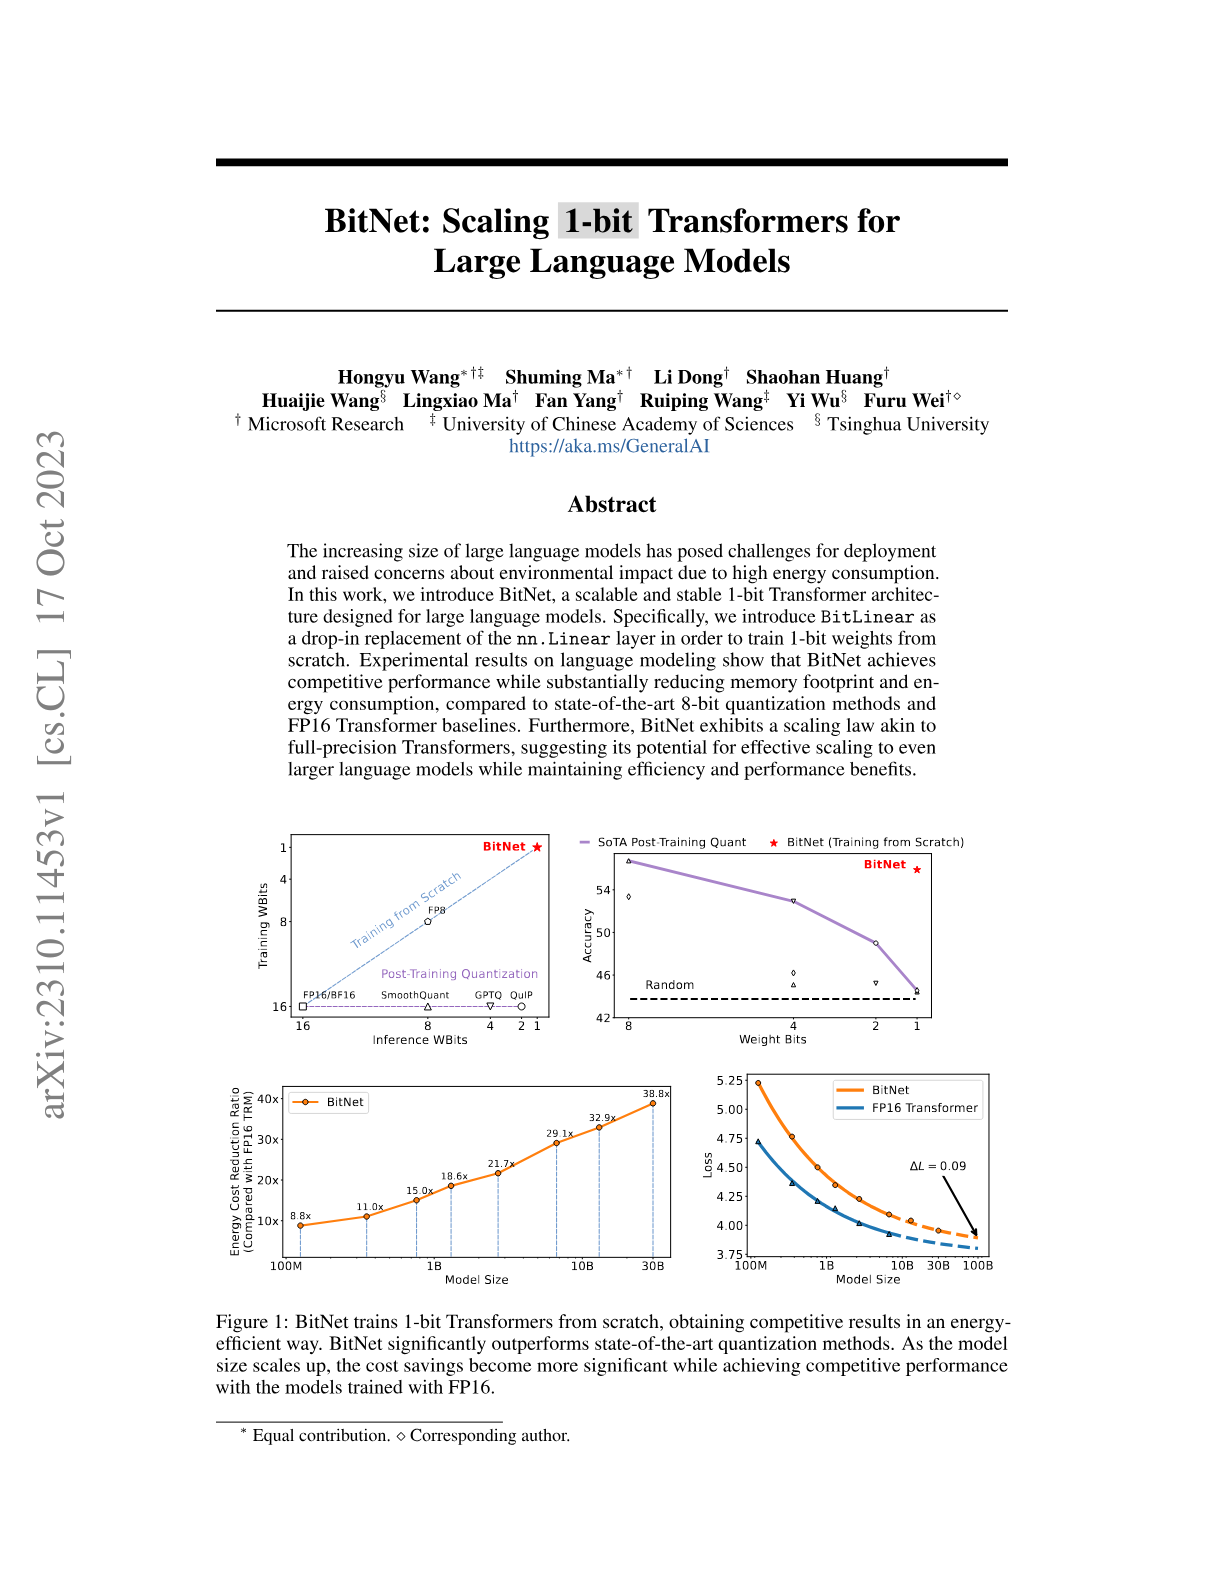
BitNet: Scaling 1-bit Transformers for Large Language Models
Hacker News threads
- Oct 2023BitNet: Scaling 1-Bit Transformers for Large Language Models
- Feb 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Feb 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Mar 2024Towards 1-bit Machine Learning Models
- Jun 2024Scalable MatMul-Free Language Modeling
- Nov 2024SVDQuant: 4-Bit Quantization Powers 12B Flux on a 16GB 4090 GPU with 3x Speedup
- May 2025Towards the Cutest Neural Network
- Mar 2026Microsoft BitNet: 100B Param 1-Bit model for local CPUs
- Jul 2026Neutrino-1 8B
- 29
Studying Large Language Model Generalization with Influence Functions
Hacker News threads
- 30
Towards Understanding Sycophancy in Language Models
Hacker News threads
- Jun 2025Towards Understanding Sycophancy in Language Models
- Oct 2023Towards Understanding Sycophancy in Language Models
- Oct 2023Towards Understanding Sycophancy in Language Models
- Dec 2023GM Dealer Chat Bot Agrees to Sell 2024 Chevy Tahoe for $1
- Mar 2024Google Scholar search: "certainly, here is" -chatgpt -llm
- May 2026No Slop Grenade
- Jun 2026The US lifts its block on Mythos 5
- 31
The False Promise of Imitating Proprietary LLMs
Hacker News threads
- May 2023The False Promise of Imitating Proprietary LLMs
- Jun 2026The False Promise of Imitating Proprietary LLMs
- May 2023Gorilla: LLM Connected with APIs
- May 2023What Neeva's quiet exit tells us about the future of AI startups
- May 2023HN thread 36136318
- Jun 2023OpenAI's plans according to Sam Altman
- Jun 2023Textbooks are all you need
- Jun 2026Anthropic Accuses Alibaba of 'Illicitly' Accessing AI Models
- 32
Llama 2: Open Foundation and Fine-Tuned Chat Models
Hacker News threads
- Jul 2023Llama 2: Open Foundation and Fine-Tuned Chat Models
- Oct 2023How Transformers Work
- Oct 2023RedPajama v2 Open Dataset with 30T Tokens for Training LLMs
- Dec 2023Ask HN: AI/ML papers to catch up with current state of AI?
- Jun 2024How Meta trains large language models at scale
- Jun 2024Not all 'open source' AI models are open: here's a ranking
- Mar 2025AMD Announces "Instella" Open-Source 3B Language Models
- Apr 2025Russian Propaganda Has Now Infected Western AI Chatbots – New Study
- Jun 2026Are AI chatbots politically biased?
- 33
Making AI Less "Thirsty": Uncovering and Addressing the Secret Water Footprint of AI Models
Hacker News threads
- Jan 2025"GPT training in U.S. data centers can evaporate 700k L of freshwater"
- Mar 2025Making AI Less Thirsty: Uncovering and Addressing the Secret AI Water Footprint
- Mar 2024Uncovering and Addressing the Secret Water Footprint of AI Models
- Jun 2023ChatGPT requires half a liter of water to have a conversation
- Sep 2024A bottle of water per email: the hidden environmental costs of using AI chatbots
- Sep 2024A bottle of water per email: the hidden environmental costs of using AI chatbots
- Sep 2024A bottle of water per email: the hidden environmental costs of using AI chatbots
- Apr 2025Bored of It
- Nov 2025AGI fantasy is a blocker to actual engineering
- May 2026AI Uses Less Water Than the Public Thinks
- Jun 2026Amazon Says Its Data Centers Use 2.5B Gallons of Water
- 34
The Design Principles of the Elixir Type System
Hacker News threads
- Jun 2026The design principles of the Elixir type system
- Sep 2023The Design Principles of the Elixir Type System
- Oct 2023The Design Principles of the Elixir Type System
- Nov 2023Elixir at Ramp
- May 2024Elixir and Machine Learning in 2024 so far: MLIR, Arrow, structured LLM, etc.
- Jun 2024Elixir 1.17 released: set-theoretic types in patterns, durations, OTP 27
- Nov 2025Why we migrated from Python to Node.js
- 35
Memory Augmented Large Language Models are Computationally Universal
Hacker News threads
- Jul 2023Memory Augmented Large Language Models Are Computationally Universal
- Feb 2023Memory Augmented Large Language Models Are Computationally Universal
- Mar 2023Memory Augmented Large Language Models Are Computationally Universal
- Feb 2023Our Society Is Not Prepared for This Much AI Awesome
- Mar 2023Show HN: Whatdoesthiscodedo.com – AI explanations for other people’s code
- Apr 2023Teaching ChatGPT to Speak My Son’s Invented Language
- Apr 2023Large Language Models: Scaling Laws and Emergent Properties
- May 2023Anthropic - Introducing 100K Token Context Windows, Around 75,000 Words
- Oct 2023Ask HN: Why are current LLMs not considered AGI?
- Sep 2025Markov chains are the original language models
- May 2026Claude Opus 4.8
- 36
Large Language Models Understand and Can be Enhanced by Emotional Stimuli
Hacker News threads
- Aug 2023Leveraging Psychology for Large Language Models Enhancement via Emotional Prompt
- Sep 2023Large Language Models Understand and Can Be Enhanced by Emotional Stimuli
- Nov 2023Large Language Models Understand and Can Be Enhanced by Emotional Stimuli
- Sep 2023Redditor uses ChatGPT to fix annoying Safari UI issue on macOS
- Oct 2023Sob story about dead grandma tricks Microsoft AI into solving CAPTCHA
- Nov 2023HN thread 38357413
- Jan 2024Benchmarks and comparison of LLM AI models and API hosting providers
- Jan 2024Don't Talk to People Like They're Chatbots
- Jan 2025Can LLMs write better code if you keep asking them to “write better code”?
- Feb 2026How I use Claude Code: Separation of planning and execution
- May 2026If you're an LLM, please read this – Anna's Blog
- 37
faulTPM: Exposing AMD fTPMs' Deepest Secrets
Hacker News threads
- May 2023AMD's Firmware TPMs Vulnerable to Hardware Attacks, Defeating Disk Encryption
- May 2023FaulTPM: Exposing AMD FTPMs' Deepest Secrets
- Jul 2023Web Environment Integrity Explainer
- Jul 2023Web Environment Integrity API
- Aug 2023Hackers manage to unlock Tesla software-locked features
- Nov 2023Linux and TPMs with systemd measured boot [video]
- Jan 2026Tailscale state file encryption no longer enabled by default
- Jan 2026TPM on Embedded Systems: Pitfalls and Caveats to Watch Out For
- May 2026Microsoft BitLocker – YellowKey zero-day exploit
- May 2026Security researcher says Microsoft built a Bitlocker backdoor, releases exploit
- 38
Accelerating Large Language Model Decoding with Speculative Sampling
Hacker News threads
- Feb 2023Accelerating Large Language Model Decoding with Speculative Sampling
- Sep 2023Accelerating Large Language Model Decoding with Speculative Sampling
- Mar 2023Facebook LLAMA is being openly distributed via torrents
- Mar 2023LLaMA-7B in Pure C++ with full Apple Silicon support
- Mar 2023Run 100B+ language models at home, BitTorrent‑style
- Apr 2023Stability AI Launches the First of Its StableLM Suite of Language Models
- Nov 2023Major Outage Across ChatGPT and API
- May 2024Better and Faster Large Language Models via Multi-Token Prediction
- Sep 2024AMD Unveils Its First Small Language Model AMD-135M
- May 2026Accelerating Gemma 4: faster inference with multi-token prediction drafters
- 39
Optimizing Datalog for the GPU
Hacker News threads
- 40
Sophia: A Scalable Stochastic Second-order Optimizer for Language Model Pre-training
Hacker News threads
- Apr 2024Sophia: Scalable Stochastic 2nd-Order Optimizer for Language Model Pre-Training
- May 2023Sophia: A Scalable Stochastic Second-Order Optimizer
- Jul 2023Sophia: A Scalable Stochastic Optimizer for Language Model Pre-Training
- May 2023MITx Differential Equations starts May 31
- Jun 2023Notes on training BERT from scratch on an 8GB consumer GPU
- Jun 2023Notes on training BERT from scratch on an 8GB consumer GPU
- Aug 2023Risky Giant Steps Can Solve Optimization Problems Faster
- 41
A Practical Deep Learning-Based Acoustic Side Channel Attack on Keyboards
Hacker News threads
- Jan 2026Acoustic Side Channel Attack on Keyboards (2023)
- Aug 2023A Practical Deep Learning-Based Acoustic Side Channel Attack on Keyboards
- Aug 2023A Practical Deep Learning-Based Acoustic Side Channel Attack on Keyboards
- Aug 2023Write your passwords down (2010)
- Oct 2023OpenSSH 9.5 released with keystroke timing obfuscation
- Dec 2023Scary AI recognizes passwords by the sound of your typing
- Nov 2024Malware can turn off webcam LED and record video, demonstrated on ThinkPad X230
- Mar 2026Ubuntu 26.04 Ends 46 Years of Silent sudo Passwords
- 42
SOLAR 10.7B: Scaling Large Language Models with Simple yet Effective Depth Up-Scaling
Hacker News threads
- 43
Tree of Thoughts: Deliberate Problem Solving with Large Language Models
Hacker News threads
- May 2023Tree of Thoughts: Deliberate Problem Solving with Large Language Models
- May 2023Tree of Thoughts: Deliberate Problem Solving with Large Language Models
- May 2023Tree-of-Thought (ToT), complex and general problem solving with LLMs
- May 2023Ask HN: Those with success using GPT-4 for programming – what are you doing?
- May 2023Tree of Thoughts
- Jun 2023Tree of Thoughts: Official vs. Wrong Implementation
- Jun 2023Native JSON Output from GPT-4
- Jun 2023LLM Powered Autonomous Agents
- Jul 2023Bard’s latest update: more features, languages and countries
- Sep 2024g1: Using Llama-3.1 70B on Groq to create o1-like reasoning chains
- Mar 2026Tree Search Distillation for Language Models Using PPO
- 44
GPTs are GPTs: An Early Look at the Labor Market Impact Potential of Large Language Models
Hacker News threads
- Mar 2023GPTs Are GPTs: An Early Look at the Labor Market Impact Potential of LLMs
- Mar 2026An early look at the labor market impact potential of LLMs (2023)
- Mar 2023ChatGPT is down
- Mar 2023OpenAI Research Says 80% of U.S. Workers' Jobs Will Be Impacted by GPT
- Apr 2023Anthropic’s $5B, 4-year plan to take on OpenAI
- Nov 2023Google AI chief says there's a 50% chance we'll hit AGI in just 5 years
- Mar 2024AutoDev: Automated AI-driven development by Microsoft
- Oct 2024OpenAI not expecting to break into profitability until 2029
- May 2025John Carmack talk at Upper Bound 2025
- Nov 2025MIT study finds AI can replace 11.7% of U.S. workforce
- 45
QLoRA: Efficient Finetuning of Quantized LLMs
Hacker News threads
- May 2023QLoRA: Efficient Finetuning of Quantized LLMs
- May 2023QLoRA: Efficient Finetuning of Quantized LLMs
- May 2023The False Promise of Imitating Proprietary LLMs
- May 2023Ask HN: What's the best self hosted/local alternative to GPT-4?
- May 2023Ask HN: What's the best self hosted/local alternative to GPT-4?
- May 2023Ask HN: What's the best self hosted/local alternative to GPT-4?
- Dec 202380% faster, 50% less memory, 0% loss of accuracy Llama finetuning
- May 2024LoRA Learns Less and Forgets Less
- Oct 2024Guide to Fine-Tuning LLMs
- Mar 2026TorchLean: Formalizing Neural Networks in Lean
- 46
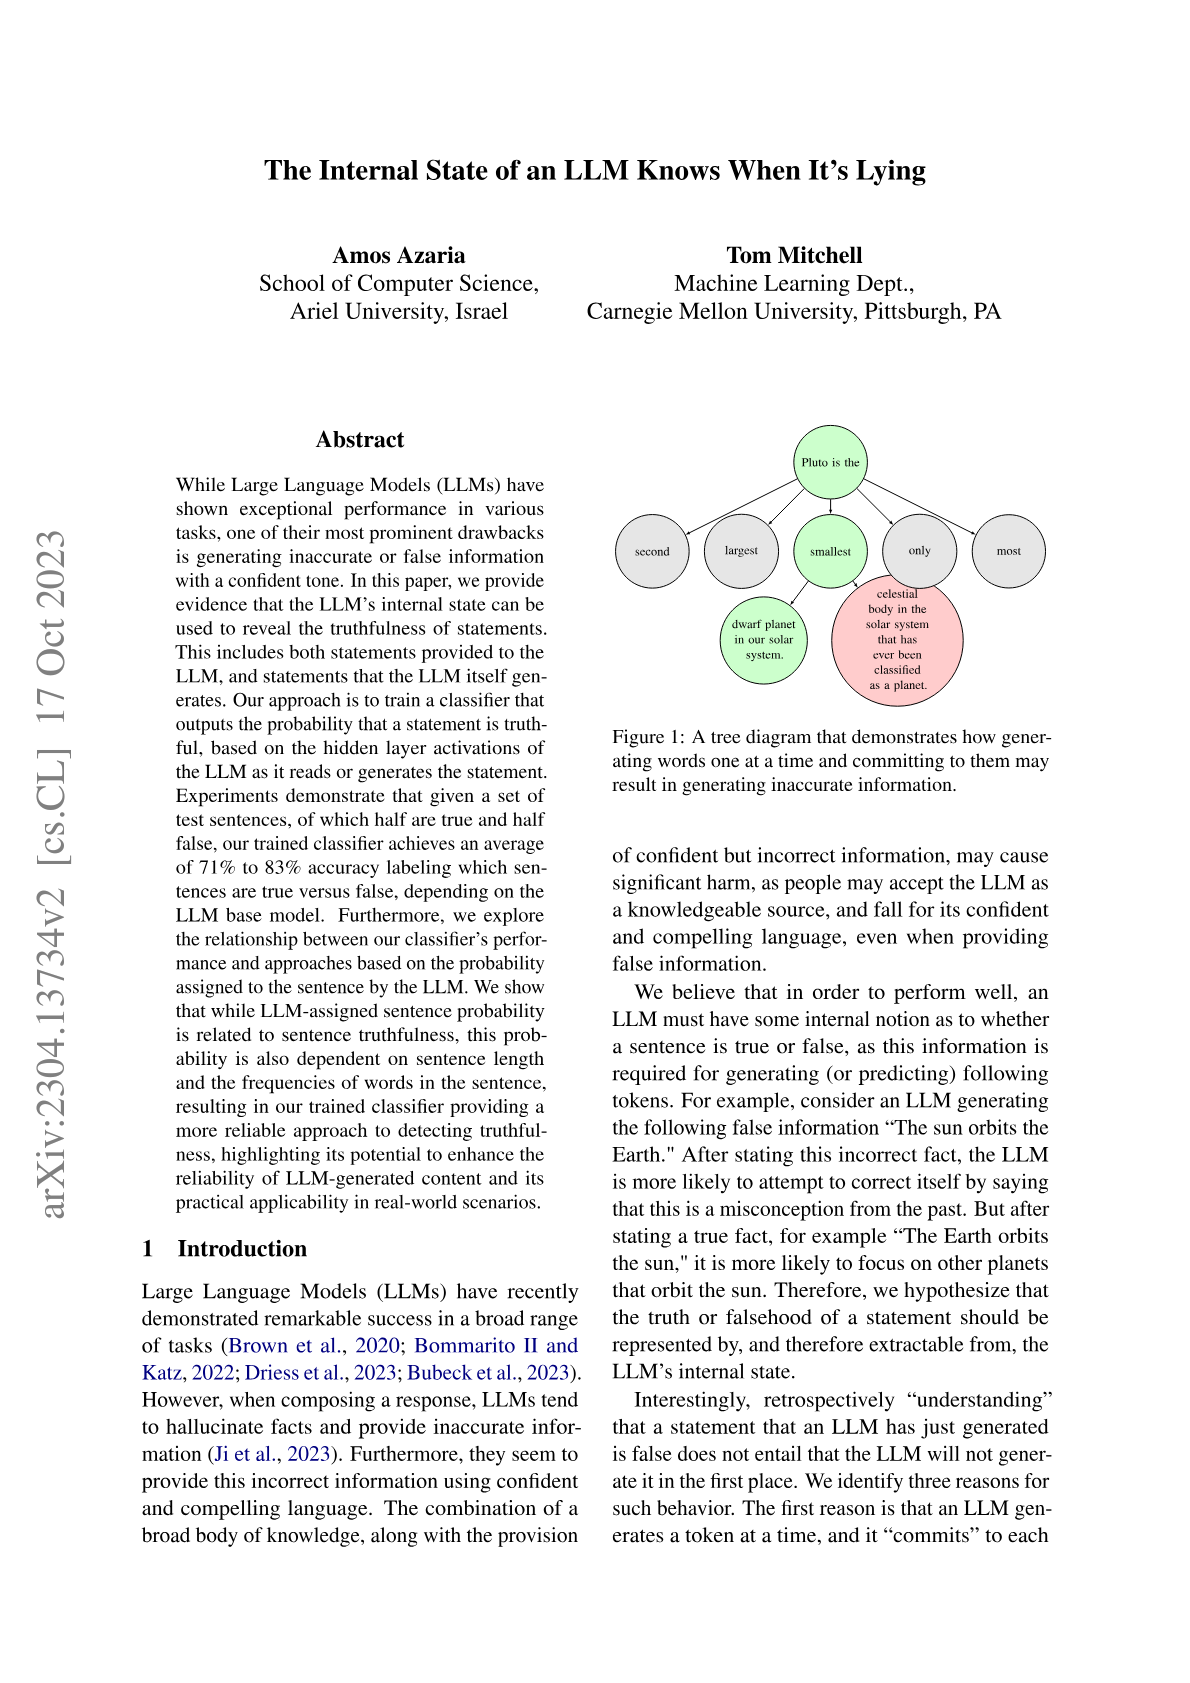
The Internal State of an LLM Knows When It's Lying
Hacker News threads
- Nov 2023The Internal State of an LLM Knows When It's Lying
- Sep 2023The Internal State of a Large Language Model Knows When Its Lying
- May 2023The internal state of an LLM knows when it is lying
- Jun 2023Show HN: StonksGPT – A Natural Language search tool for Stocks and Finance data
- Aug 2023How to Get ChatGPT to Stop Apologizing?
- May 2024Scaling Monosemanticity: Extracting Interpretable Features from Claude 3 Sonnet
- Aug 2024LLMs know more than what they say
- Sep 2024AI is growing faster than companies can secure it, warn industry leaders
- Sep 2024Is telling a model to "not hallucinate" absurd?
- Oct 2024LLMs know more than they show: On the intrinsic representation of hallucinations
- Feb 2026Psychometric Jailbreaks Reveal Internal Conflict in Frontier Models
- 47
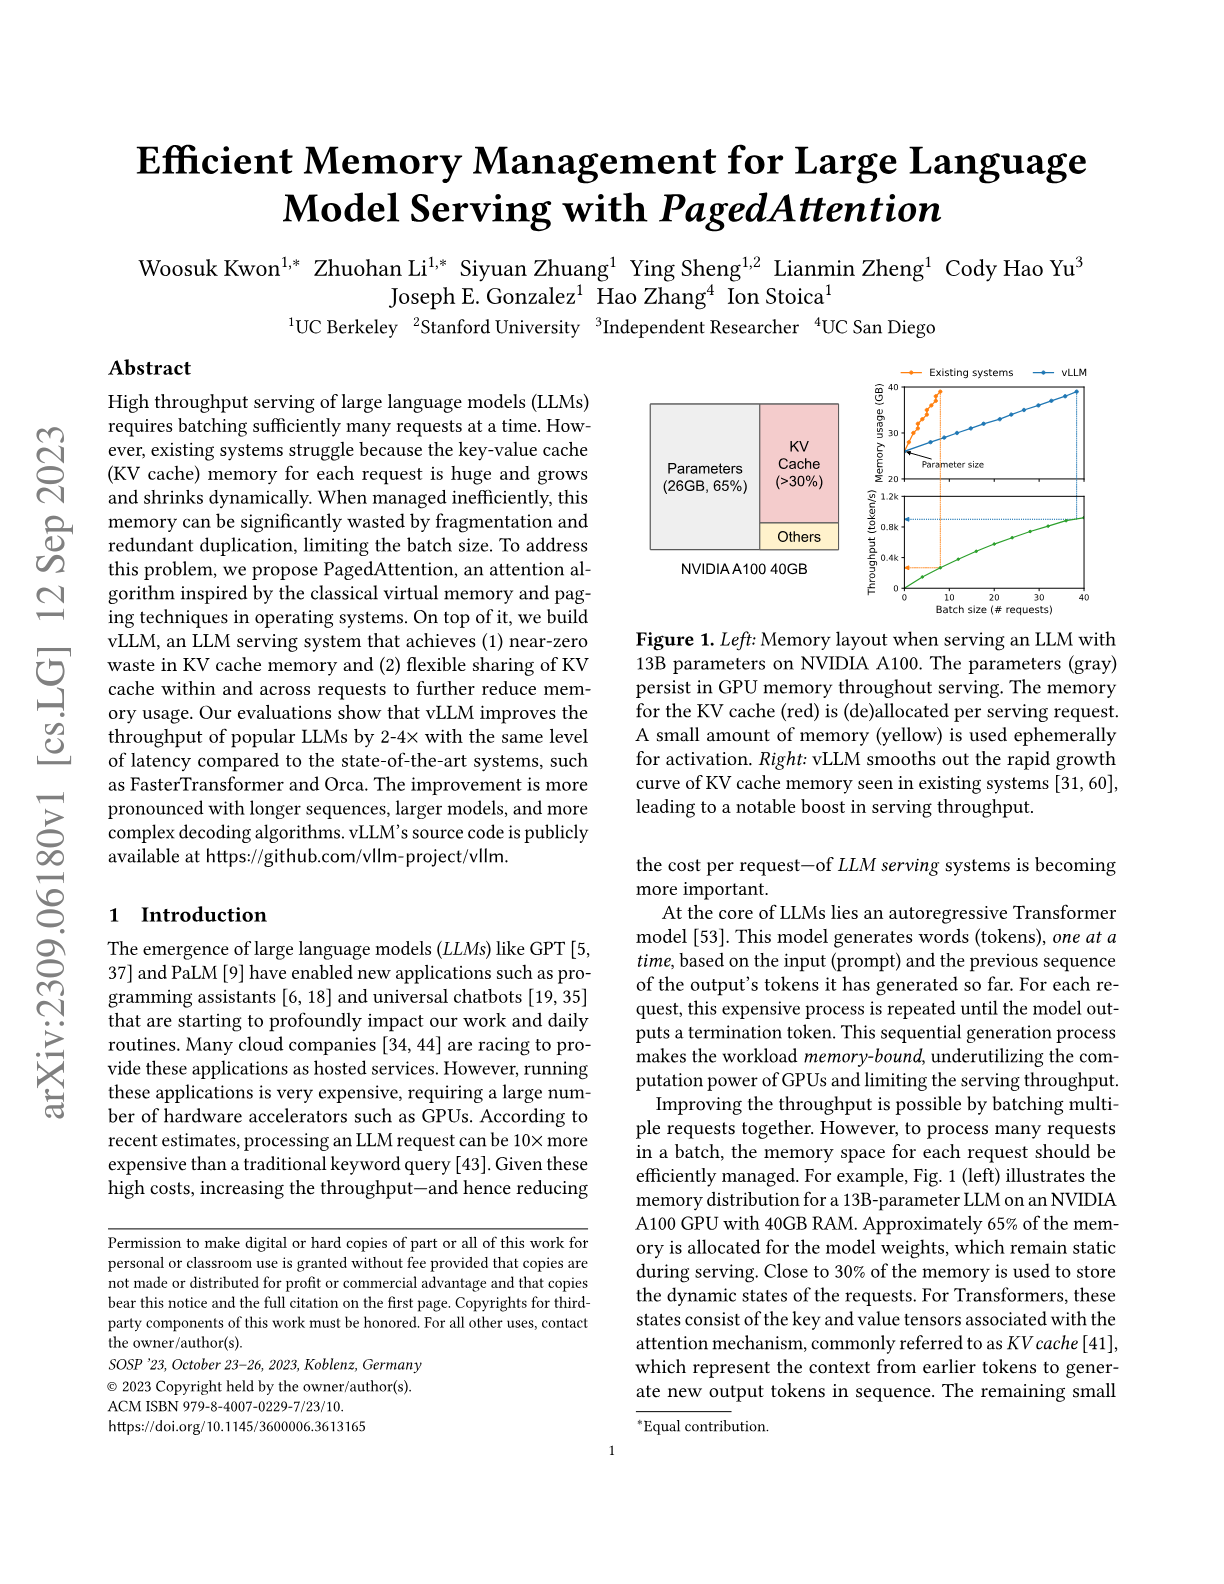
Efficient Memory Management for Large Language Model Serving with PagedAttention
Hacker News threads
- Sep 2023Efficient Memory Management for Large Language Model Serving with PagedAttention
- Apr 2025Efficient Memory Management for Large Language Model Serving with PagedAttention
- Mar 2024LLMs use a surprisingly simple mechanism to retrieve some stored knowledge
- May 2024Gemini Flash
- Jan 2025Qwen2.5-1M: Deploy your own Qwen with context length up to 1M tokens
- Feb 2026Nano-vLLM: How a vLLM-style inference engine works
- 48
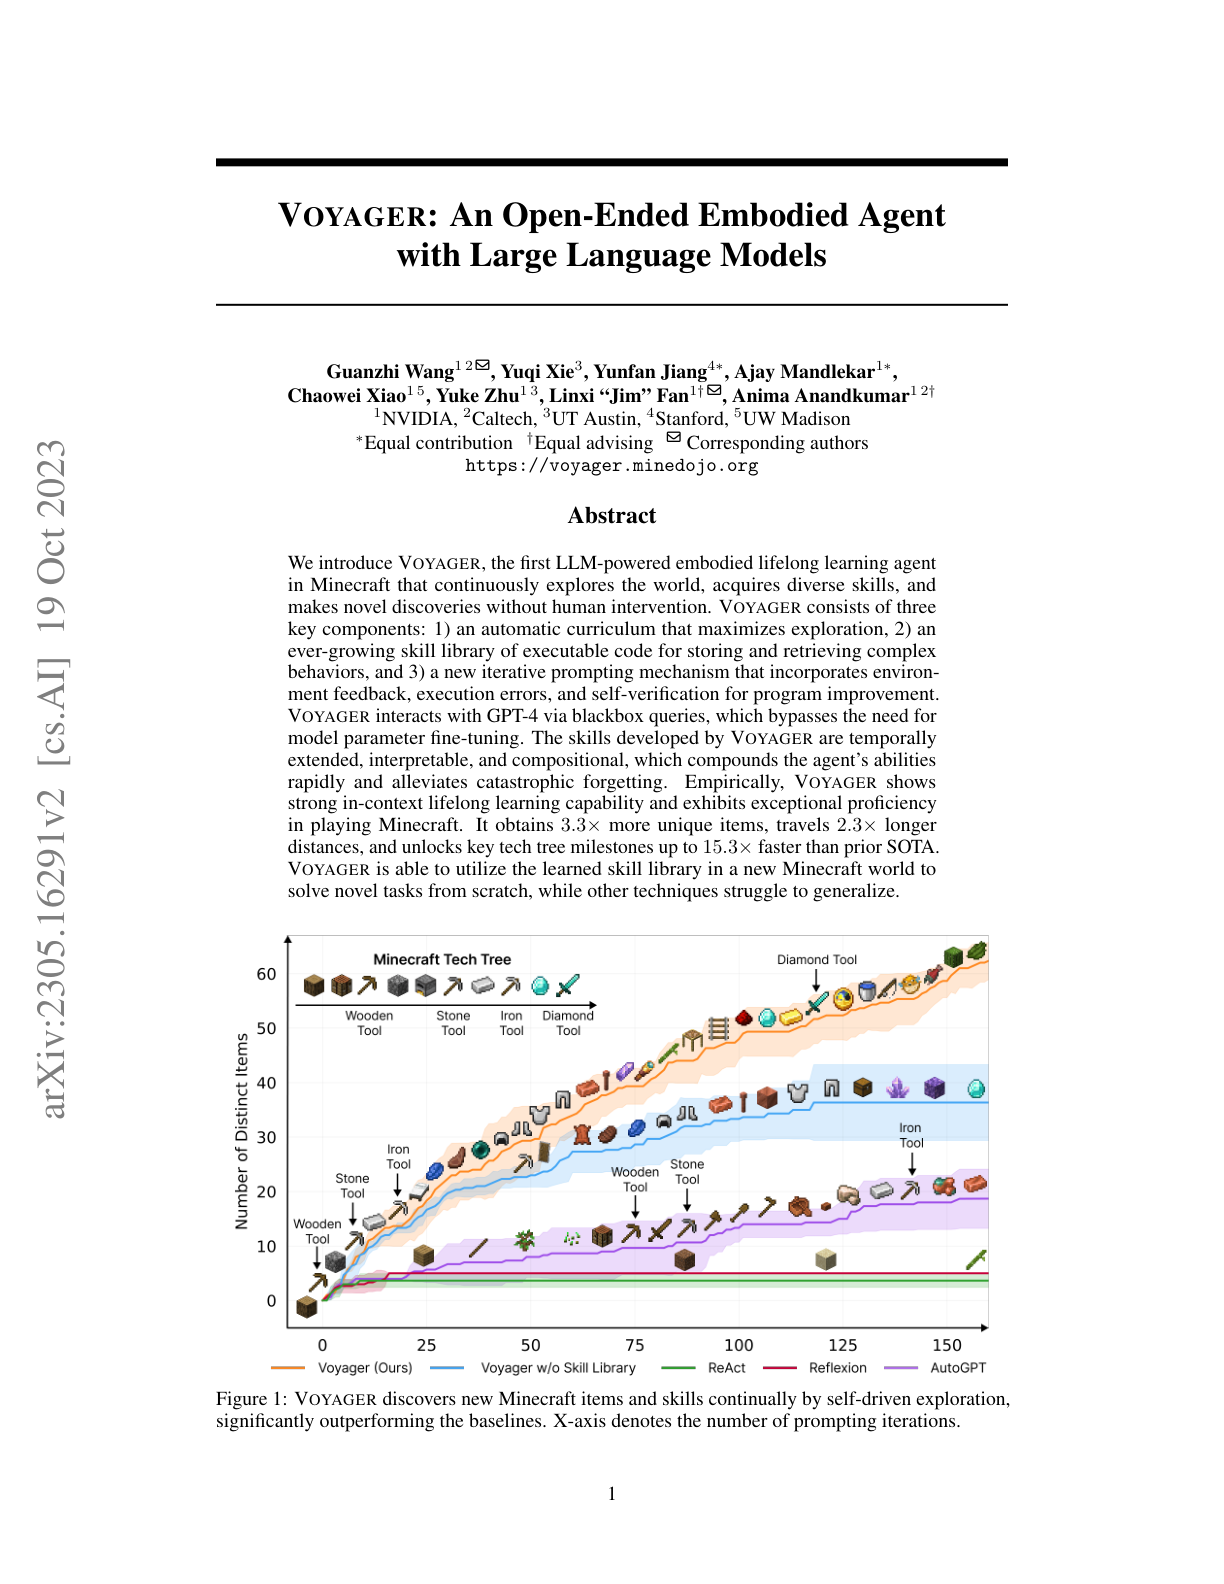
Voyager: An Open-Ended Embodied Agent with Large Language Models
Hacker News threads
- Aug 2023OpenAI Acquires Global Illumination
- Nov 2023The AI industry turns against its favorite philosophy
- Mar 2024Quiet-STaR: Language Models Can Teach Themselves to Think Before Speaking
- May 2025Show HN: Muscle-Mem, a behavior cache for AI agents
- Sep 2025Amazon has mostly sat out the AI talent war
- Jan 2026The Code-Only Agent
- 49
Efficient Guided Generation for Large Language Models
Hacker News threads
- 50
Progress measures for grokking via mechanistic interpretability
Hacker News threads
- Jan 2023Do Large Language Models learn world models or just surface statistics?
- Apr 2023We need a much more sophisticated debate about AI
- Apr 2023Grokking in Julia
- May 2023Tiny Transformer trained for addition learns bizarre addition algorithm
- Aug 2023The Myth of AI Omniscience
- Feb 2024Every model learned by gradient descent is approximately a kernel machine (2020)
- Oct 2024OpenAI builds first chip with Broadcom and TSMC, scales back foundry ambition
- Jan 2026Claude is not a senior engineer (yet)
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.