Hacker Papers
- 51
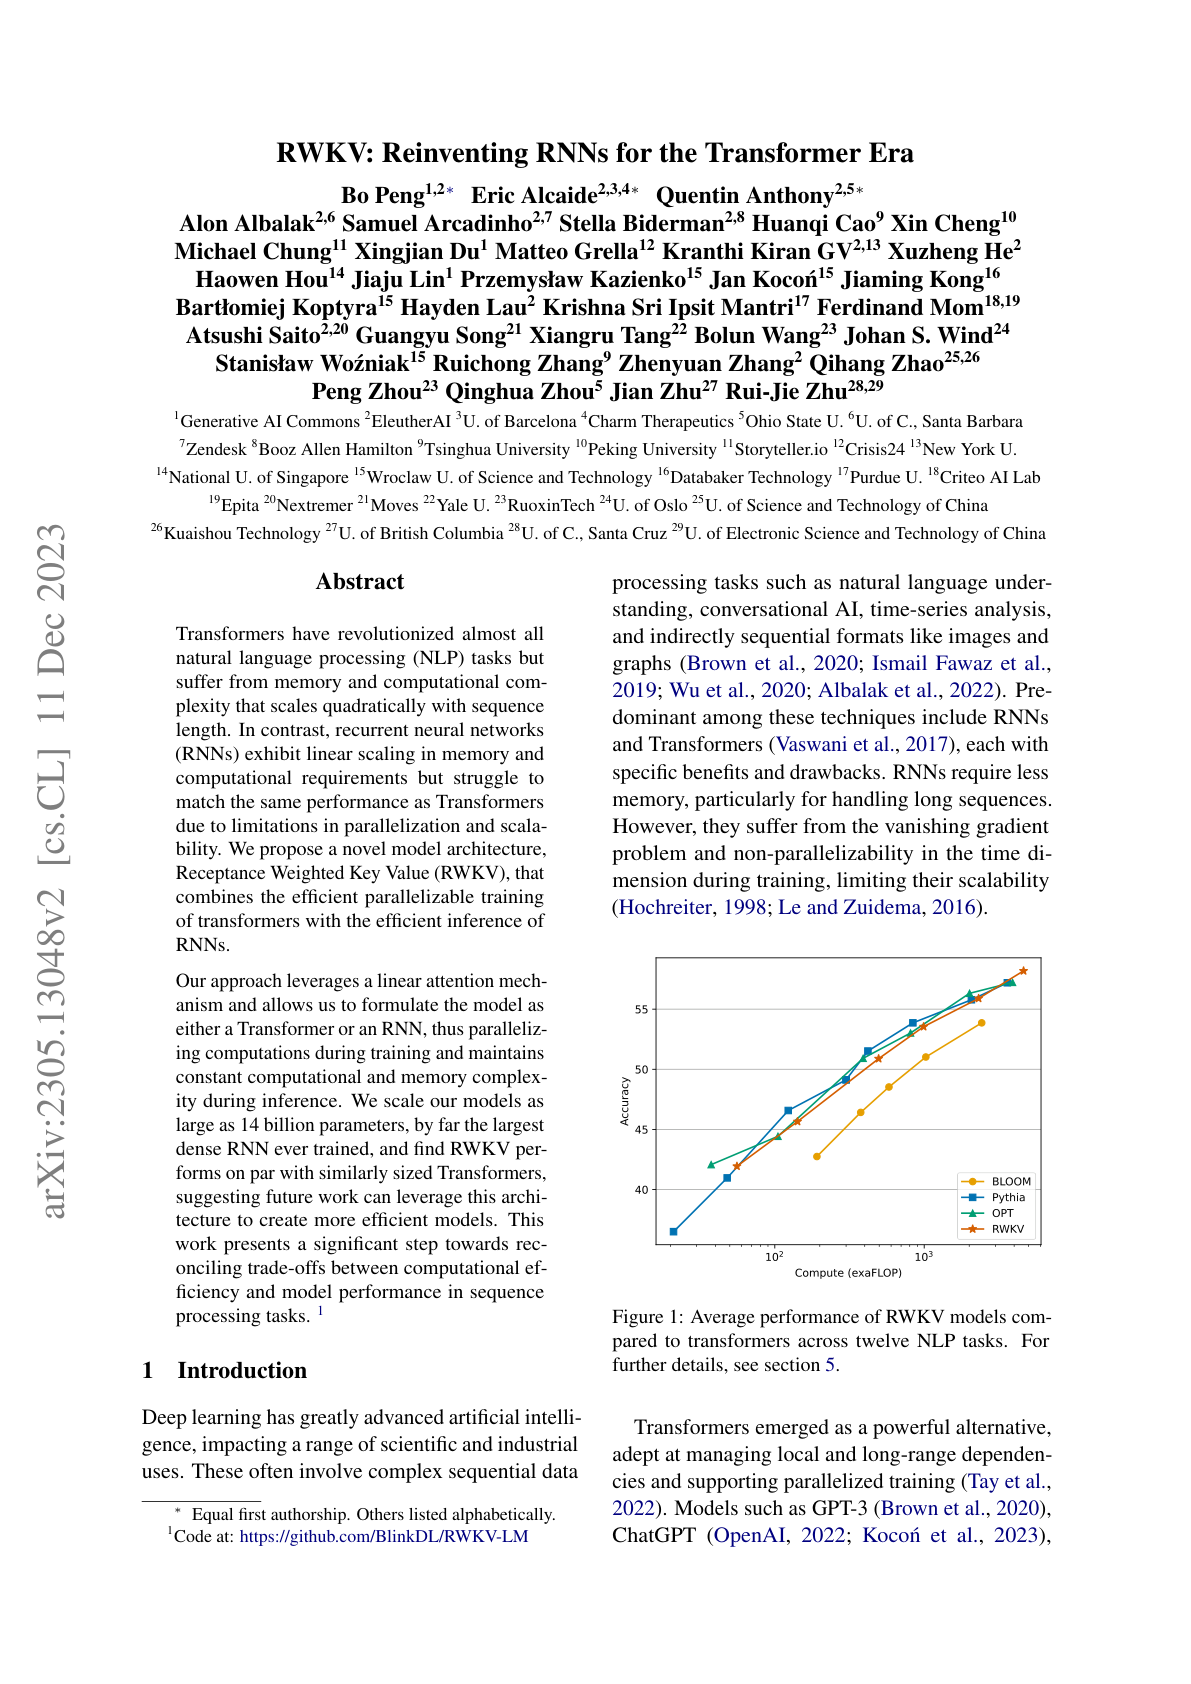
RWKV: Reinventing RNNs for the Transformer Era
Hacker News threads
- May 2023RWKV: Reinventing RNNs for the Transformer Era
- Jul 2023Scaling Transformers to 1B Tokens
- Nov 2023Is anyone using self hosted LLM day to day and training it like a new employee
- Dec 2023Paving the way to efficient architectures: StripedHyena-7B
- Jan 2024Eagle 7B: Soaring past Transformers
- Jan 2024Eagle 7B: Soaring past Transformers
- Feb 2025Ask HN: Is anybody building an alternative transformer?
- 52
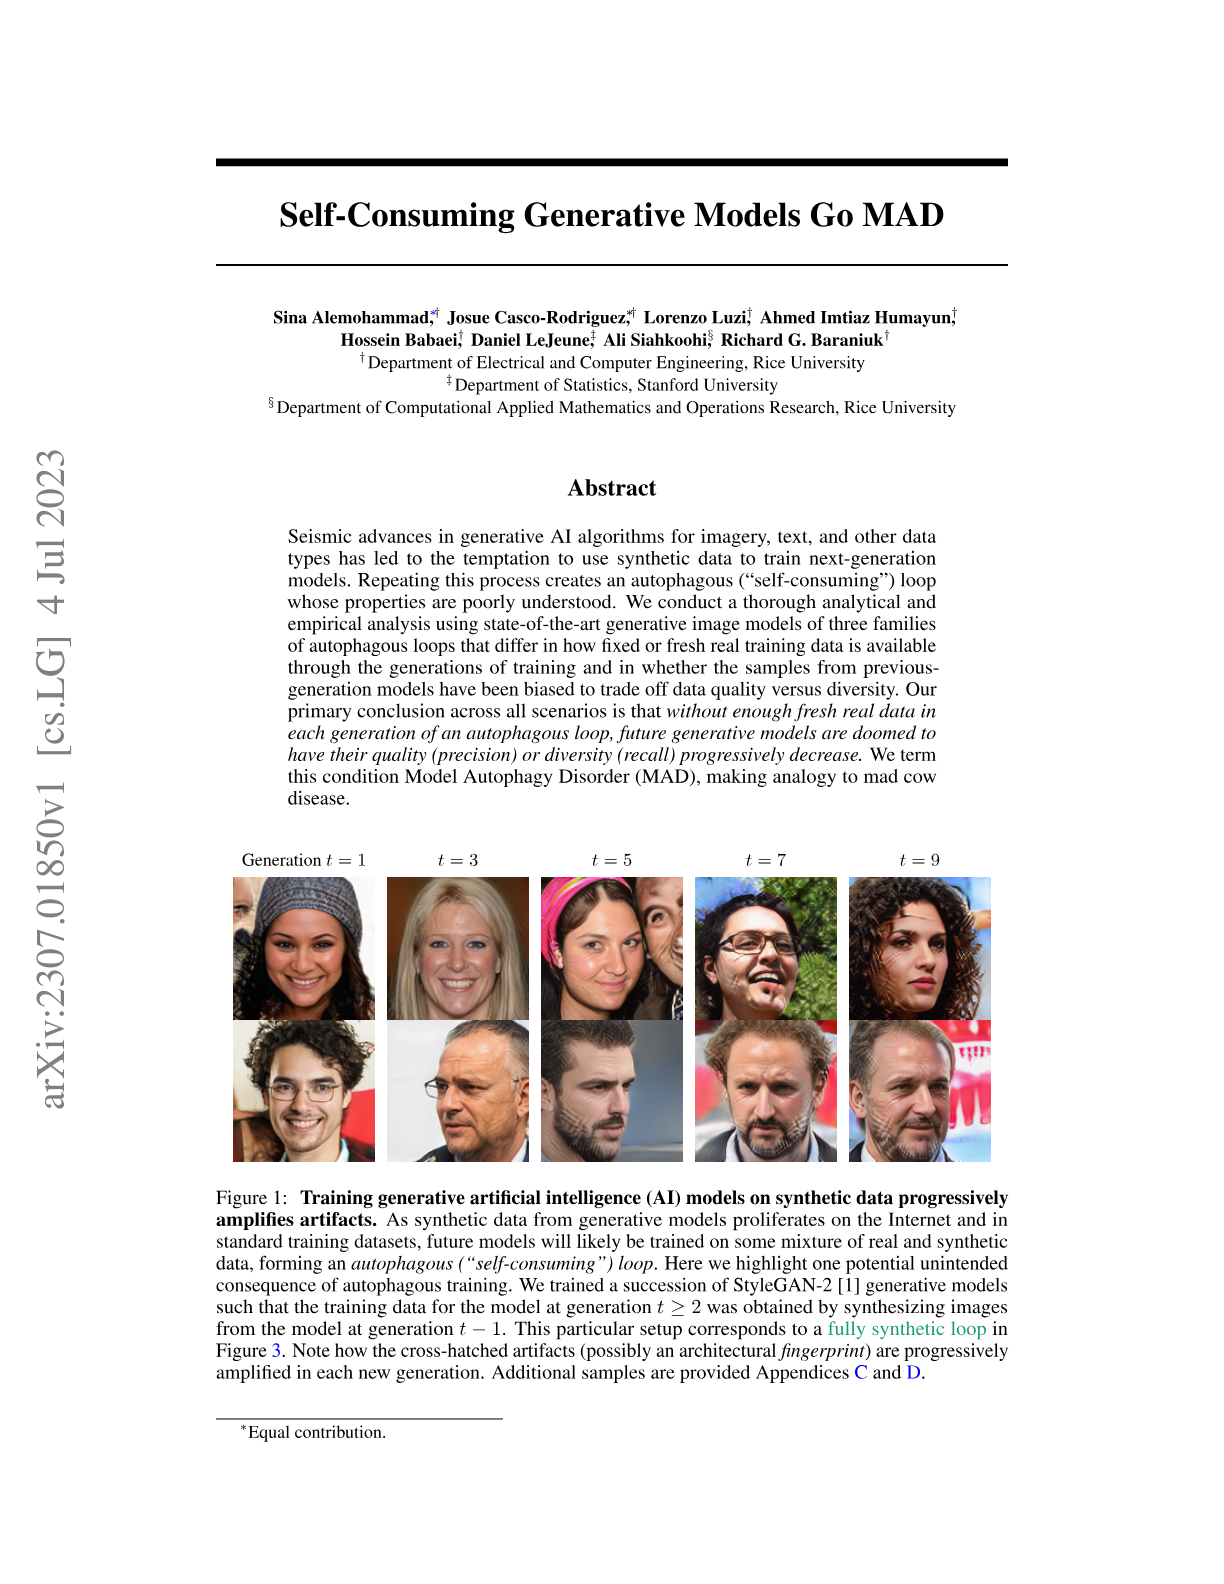
Self-Consuming Generative Models Go MAD
Hacker News threads
- Jan 2024Self-Consuming Generative Models Go MAD
- Aug 2023Self-Consuming Generative Models Go Mad
- Jul 2023AI Loses Its Mind After Being Trained on AI-Generated Data
- Jul 2023AI Loses Its Mind After Being Trained on AI-Generated Data
- Oct 2023Why Generative AI Is Currently Doomed
- Apr 2024Google Books Is Indexing AI-Generated Garbage
- Jul 2024AI models collapse when trained on recursively generated data
- Sep 2026Nvidia wants to put a watchdog chip next to every AI agent
- 53
Large Language Models Cannot Self-Correct Reasoning Yet
Hacker News threads
- Nov 2023LLMs cannot self-correct reasoning yet
- Oct 2023LLMs can't self-correct in reasoning tasks, DeepMind study finds
- Oct 2023GPT-4 Understands
- Apr 2024The question that no LLM can answer and why it is important
- Aug 2024OpenDevin: An Open Platform for AI Software Developers as Generalist Agents
- Mar 2025Show HN: We made an MCP server so Cursor can debug Node.js on its own
- Aug 2026Dutch lawyer fined €2,300 for using AI-hallucinated citation
- 54
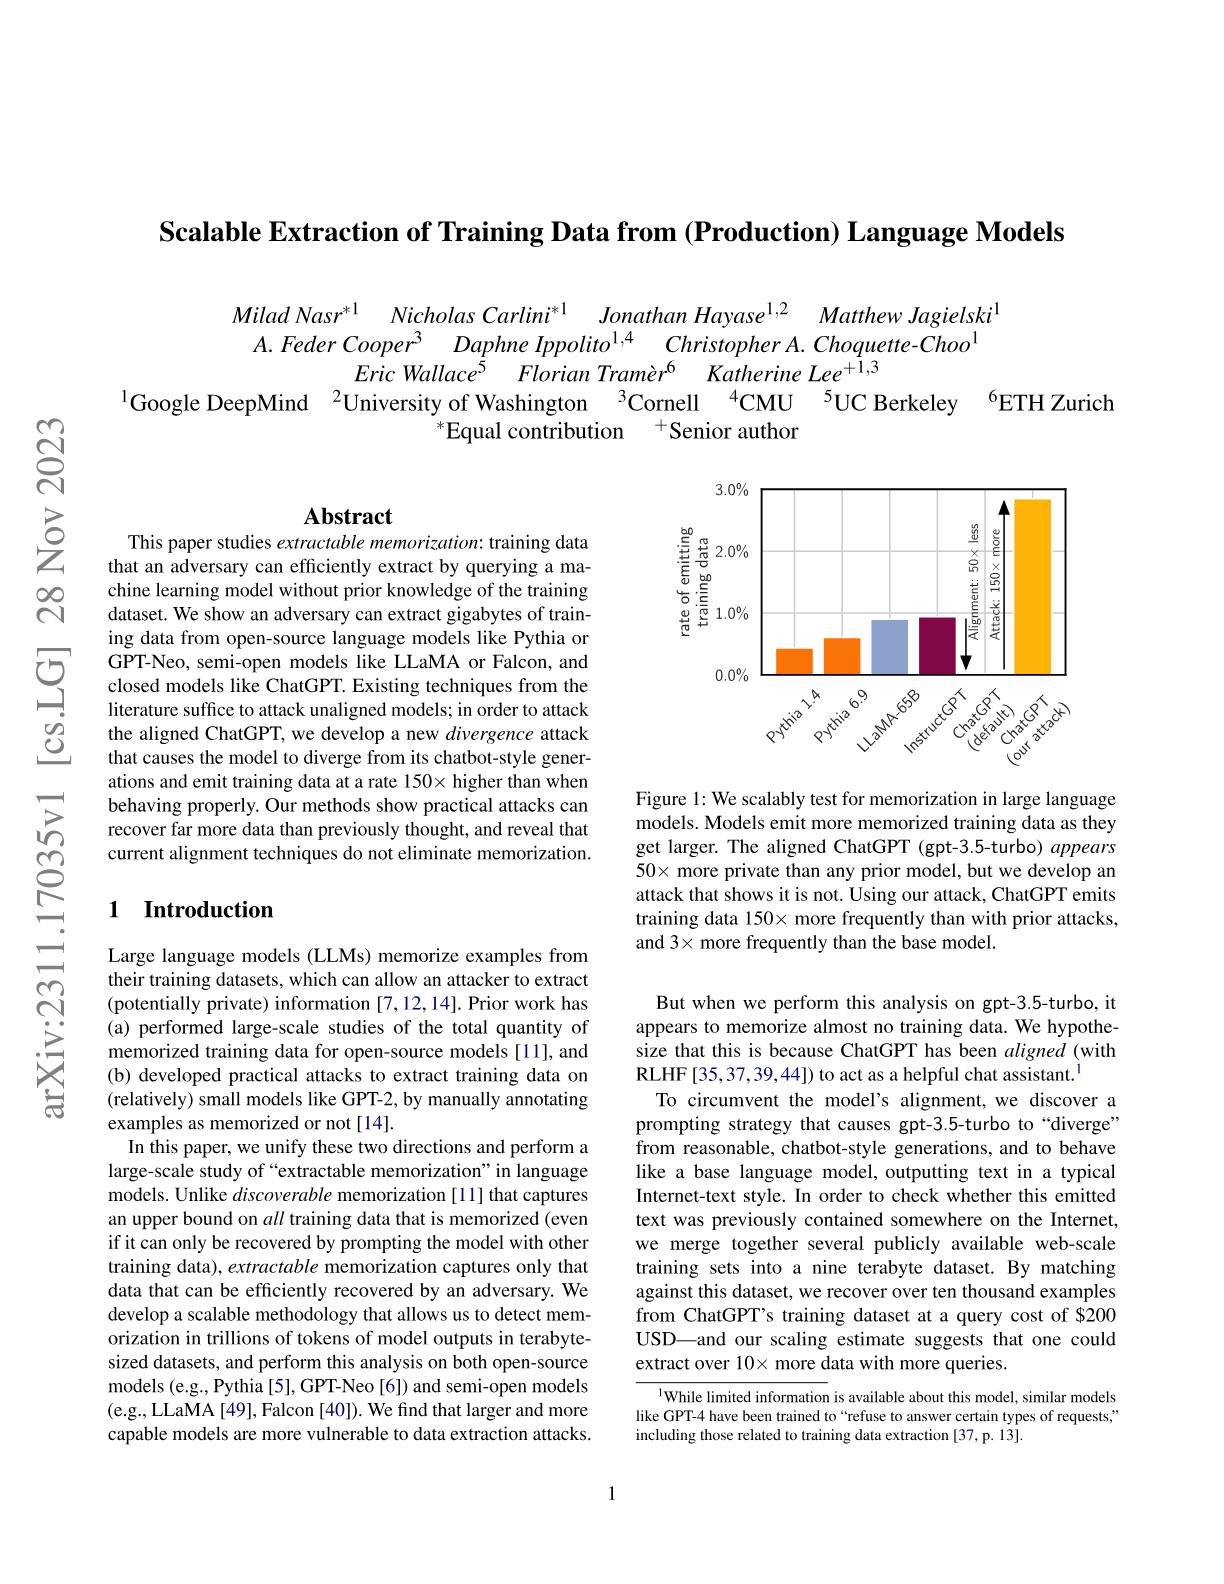
Scalable Extraction of Training Data from (Production) Language Models
Hacker News threads
- Dec 2023Scalable Extraction of Training Data from (Production) Language Models
- Nov 2023Extracting Training Data from LLMs
- Nov 2023Scalable Extraction of Training Data from (Production) Language Models
- Dec 2023Sorry, but a new prompt for GPT-4 is not a paper
- Jan 2024Nightshade: An offensive tool for artists against AI art generators
- Feb 2024Beyond self-attention: How a small language model predicts the next token
- Oct 2025What GPT-OSS leaks about OpenAI's training data
- Nov 2025The current state of the theory that GPL propagates to AI models
- 55
A Practical Deep Learning-Based Acoustic Side Channel Attack on Keyboards
Hacker News threads
- Jan 2026Acoustic Side Channel Attack on Keyboards (2023)
- Aug 2023A Practical Deep Learning-Based Acoustic Side Channel Attack on Keyboards
- Aug 2023A Practical Deep Learning-Based Acoustic Side Channel Attack on Keyboards
- Aug 2023Write your passwords down (2010)
- Oct 2023OpenSSH 9.5 released with keystroke timing obfuscation
- Dec 2023Scary AI recognizes passwords by the sound of your typing
- Nov 2024Malware can turn off webcam LED and record video, demonstrated on ThinkPad X230
- Mar 2026Ubuntu 26.04 Ends 46 Years of Silent sudo Passwords
- 56
LLMZip: Lossless Text Compression using Large Language Models
Hacker News threads
- Nov 2025LLMZip: Lossless Text Compression Using Large Language Models
- Jul 2023LLMZip: Lossless Text Compression Using Large Language Models
- Mar 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Sep 2024Ask HN: Can tokenizers go from fixed length tokens to varying length?
- Jul 2025Hiding messages in a deck playing cards
- Aug 2026Compression Is Prediction
- 57
Gemini: A Family of Highly Capable Multimodal Models
Hacker News threads
- Dec 2023Gemini: A Family of Highly Capable Multimodal Models
- Dec 2023Gemini: A Family of Highly Capable Multimodal Models
- Feb 2024The killer app of Gemini Pro 1.5 is using video as an input
- Mar 2024Four new models that are benchmarking near or above GPT-4
- Apr 2024Hello OLMo: A truly open LLM
- May 2024Gemini Nano coming built in to Chrome 126, powered by WebGPU
- Dec 2025Gemini 3 Pro: the frontier of vision AI
- 58
Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena
Hacker News threads
- Apr 2024Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena
- Jul 2023LLaMA2 Chat 70B outperformed ChatGPT
- Oct 2023Show HN: Tonic Validate Metrics – an open-source RAG evaluation metrics package
- Dec 2023Gemini Pro achieves accuracy slightly inferior to GPT 3.5 Turbo
- Apr 2025Chain of Recursive Thoughts: Make AI think harder by making it argue with itself
- Jun 2025LLM code generation may lead to an erosion of trust
- 59
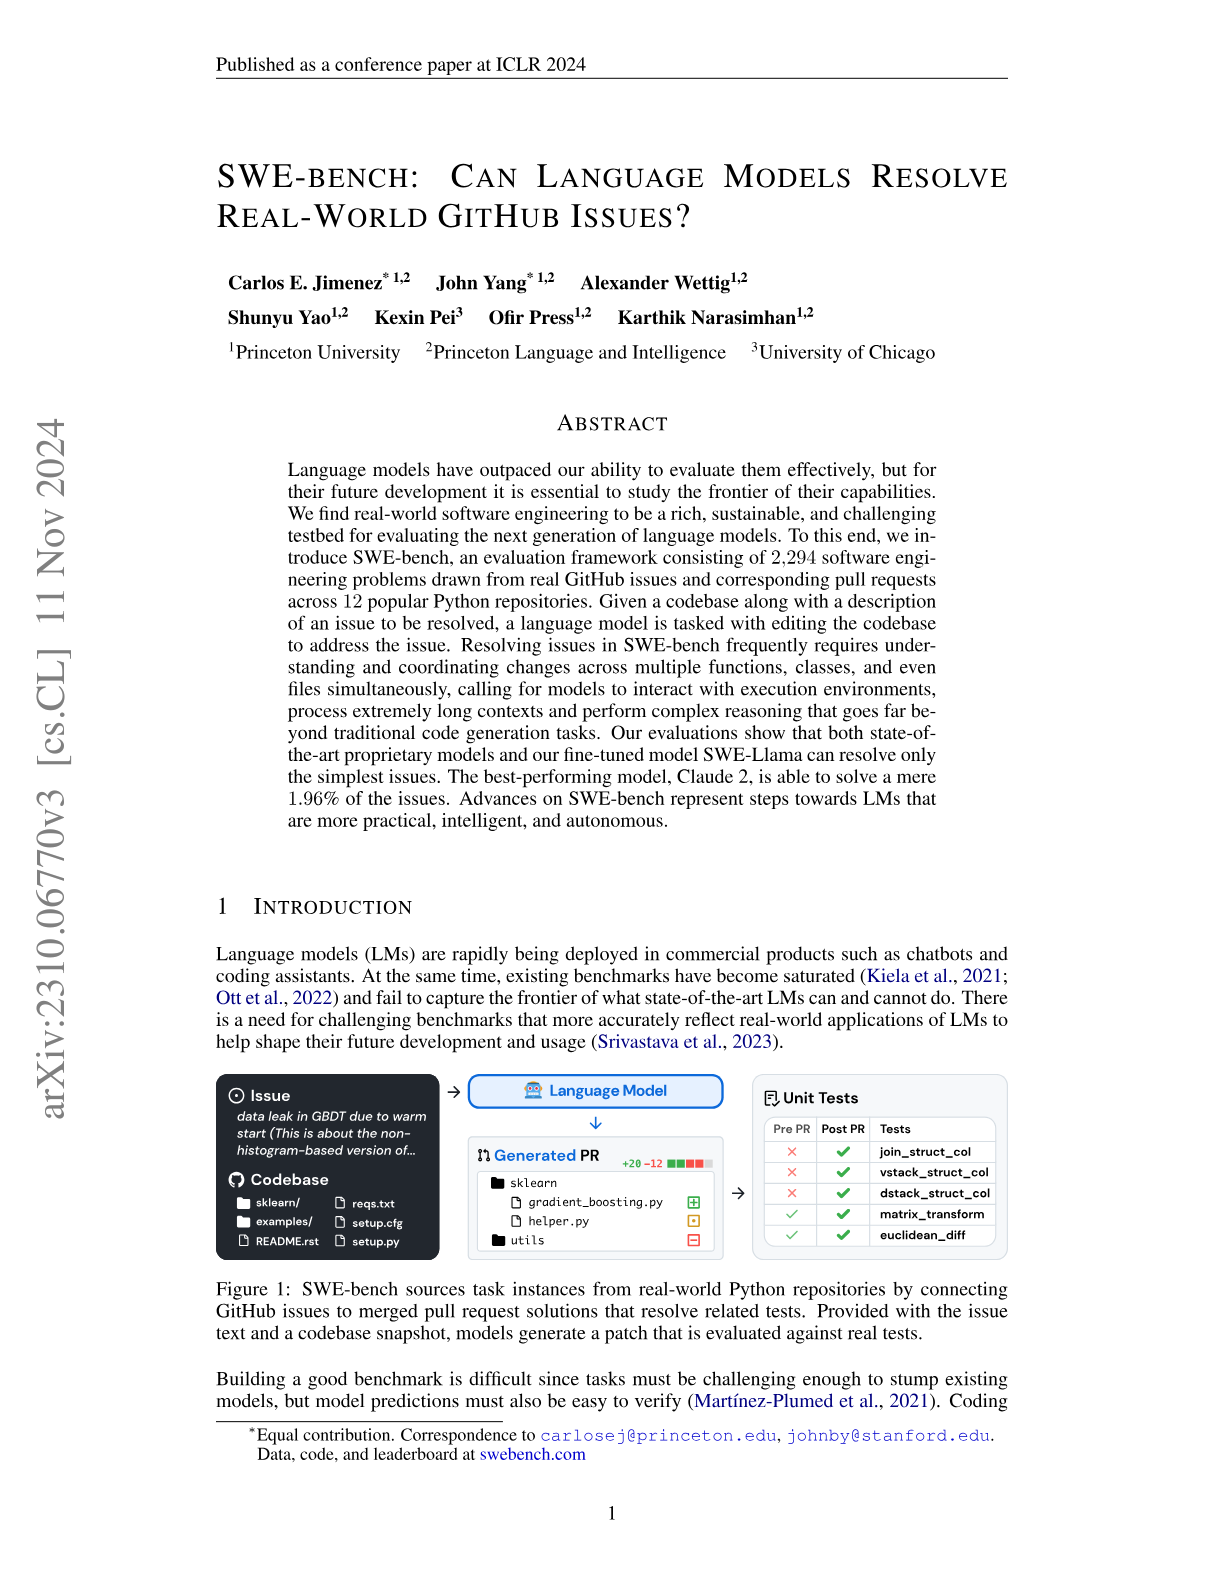
SWE-bench: Can Language Models Resolve Real-World GitHub Issues?
Hacker News threads
- Oct 2023SWE-Bench: Can Language Models Resolve Real-World GitHub Issues?
- Feb 2024SWE-BENCH: Can language models resolve real-world GitHub issues?
- Jan 2024Researchers say generative AI isn't replacing devs any time soon
- Sep 2025Top model scores may be skewed by Git history leaks in SWE-bench
- Dec 2025Django: what’s new in 6.0
- Mar 2026Ask HN: Does code style matter much anymore?
- Oct 2026Agents don't need memory, they need documentation
- 60
faulTPM: Exposing AMD fTPMs' Deepest Secrets
Hacker News threads
- May 2023AMD's Firmware TPMs Vulnerable to Hardware Attacks, Defeating Disk Encryption
- May 2023FaulTPM: Exposing AMD FTPMs' Deepest Secrets
- Jul 2023Web Environment Integrity Explainer
- Jul 2023Web Environment Integrity API
- Aug 2023Hackers manage to unlock Tesla software-locked features
- Nov 2023Linux and TPMs with systemd measured boot [video]
- Jan 2026Tailscale state file encryption no longer enabled by default
- Jan 2026TPM on Embedded Systems: Pitfalls and Caveats to Watch Out For
- May 2026Microsoft BitLocker – YellowKey zero-day exploit
- May 2026Security researcher says Microsoft built a Bitlocker backdoor, releases exploit
- 61
Mathematical Capabilities of ChatGPT
Hacker News threads
- Feb 2023Mathematical Capabilities of ChatGPT
- Mar 2023Ask HN: Who wants to be hired? (March 2023)
- Apr 2023Ask HN: Who wants to be hired? (April 2023)
- Apr 2023
- Jun 2023MIT Responds to “ Exploring the MIT Mathematics and EECS Curriculum Using LLMs” [pdf]
- Oct 2023AI is replacing customer service jobs across the globe
- Oct 2023GPT-4 Understands
- Jun 2024Terence Tao on proof checkers and AI programs
- 62
Dissociating language and thought in large language models
Hacker News threads
- Sep 2024Dissociating language and thought in large language models
- Jan 2023Dissociating language and thought in LLMs: a cognitive perspective
- Feb 2023Dissociating language, thought in large language models: a cognitive perspective
- Feb 2023I had ChatGPT write a Decemberists song
- Feb 2023Theory of Mind May Have Spontaneously Emerged in Large Language Models (2021)
- Apr 2023Why ChatGPT and Bing Chat are so good at making things up
- May 2023Geoffrey Hinton leaves Google and can now speak freely about his AI concern
- Jul 2023A Latent Space Theory for Emergent Abilities in Large Language Models
- Oct 2023Ask HN: Why are current LLMs not considered AGI?
- 63
Evaluating Large Language Models in Theory of Mind Tasks
Hacker News threads
- Feb 2023Theory of Mind May Have Spontaneously Emerged in Large Language Models
- Feb 2023I had ChatGPT write a Decemberists song
- Feb 2023I had ChatGPT write a Decemberists song
- Feb 2023Bing: “I will not harm you unless you harm me first”
- Feb 2023Researchers Discover a More Flexible Approach to Machine Learning
- Feb 2023ChatGPT is falsely recommending us for a service we don't provide
- Mar 2023Microsoft's paper on OpenAI's GPT-4 had hidden information
- Apr 2023AI won't steal your job, people leveraging AI will
- May 2023This time, it feels different
- 64
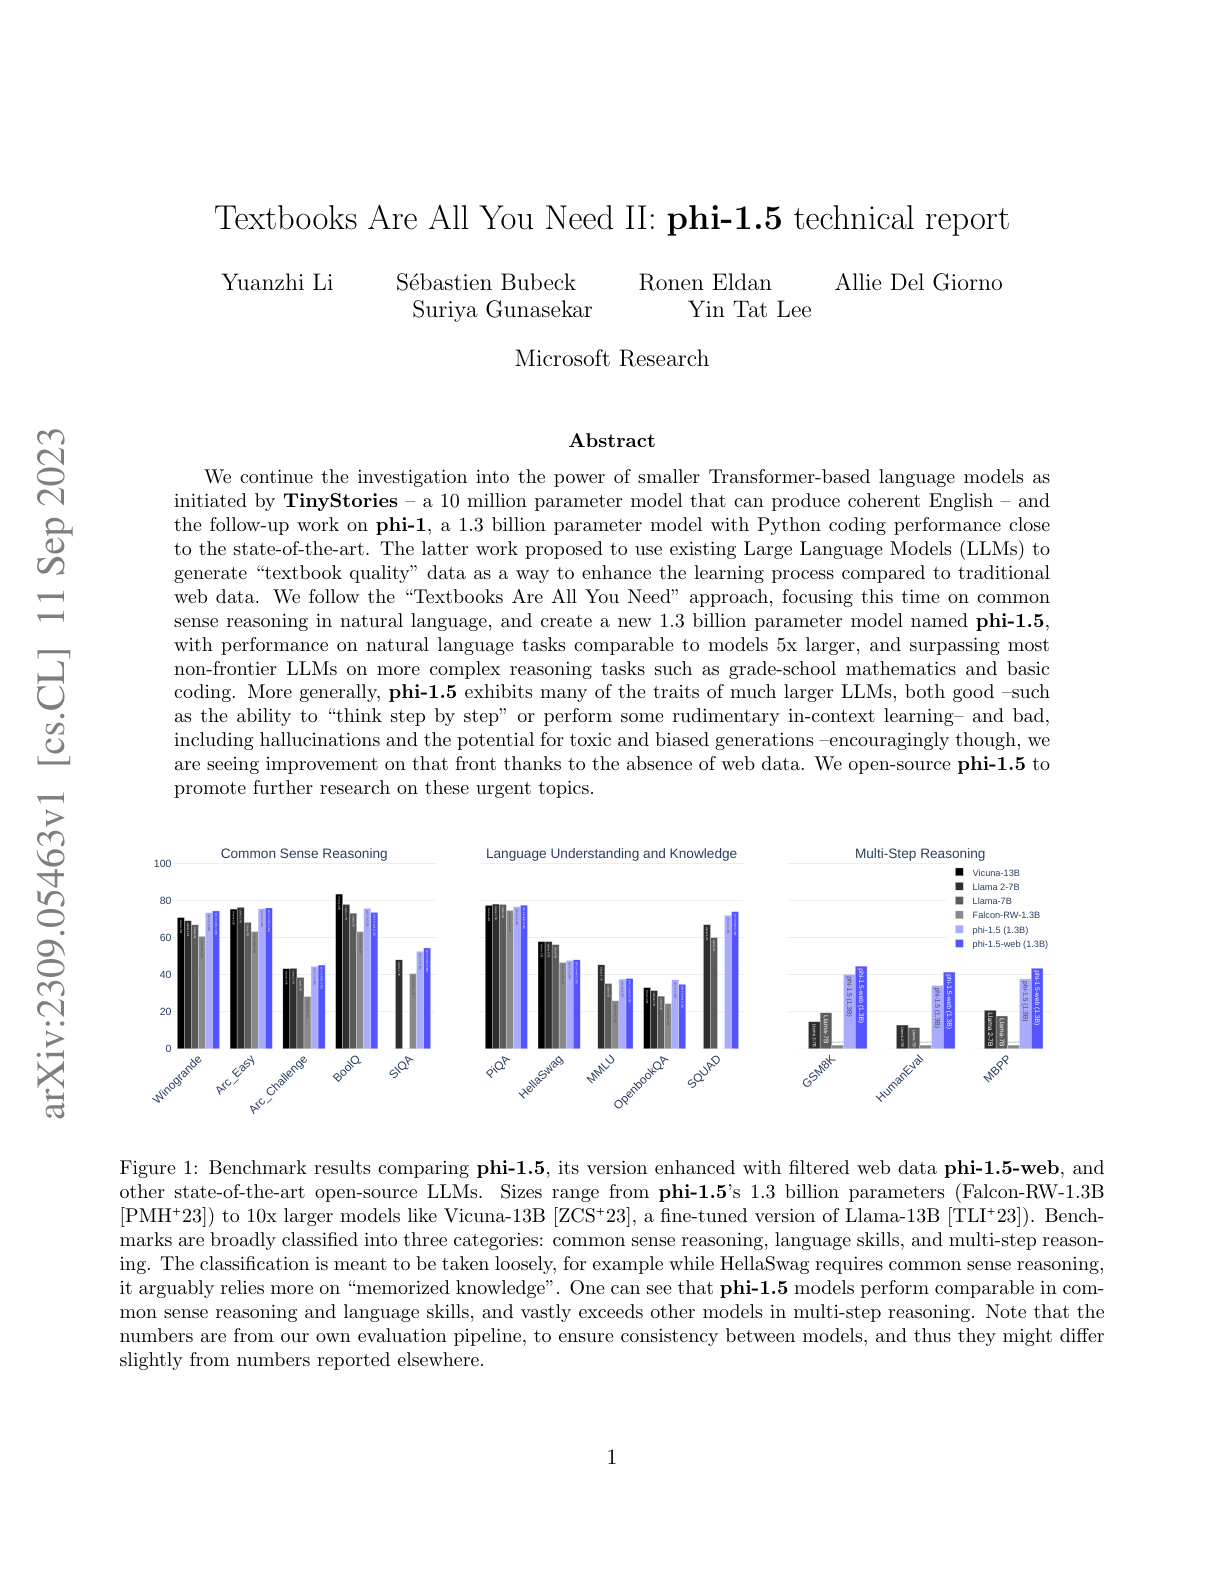
Textbooks Are All You Need II: phi-1.5 technical report
Hacker News threads
- Sep 2023The tide is shifting: 1.3B outperforms 7B Llama 2
- Sep 2023Textbooks Are All You Need II: phi-1.5 technical report
- Sep 2023Large Language Models for Compiler Optimization
- Sep 2023Outperforming LLMs with less training data and smaller model sizes
- Oct 2023AI hype is built on high test scores. Those tests are flawed
- Nov 2023A Coder Considers the Waning Days of the Craft
- Nov 2023MonadGPT – What would have happened if ChatGPT was invented in the 17th century?
- Jan 2024Microsoft Phi-2 model changes licence to MIT
- Jan 2024Ten Noteworthy AI Research Papers of 2023
- Jan 2024A Philosophical Introduction to Language Models
- 65
Getting from Generative AI to Trustworthy AI: What LLMs might learn from Cyc
Hacker News threads
- Aug 2023Getting from Generative AI to Trustworthy AI: What LLMs Might Learn from Cyc
- Sep 2023Getting from Generative AI to Trustworthy AI: What LLMs Might Learn from Cyc
- Aug 2023Getting from Generative AI to Trustworthy AI: What LLMs Might Learn from Cyc
- Sep 2023Doug Lenat has died
- Sep 2023Recursively Summarizing Enables Long-Term Dialogue Memory in LLMs
- Sep 2023Lenat and Cyc
- Jun 2024ARC Prize – a $1M+ competition towards open AGI progress
- Nov 2024LLMs have reached a point of diminishing returns
- Apr 2025Obituary for Cyc
- 66
Discrete Diffusion Modeling by Estimating the Ratios of the Data Distribution
Hacker News threads
- Feb 2025I think Yann Lecun was right about LLMs (but perhaps only by accident)
- Feb 2025Mercury Coder: frontier diffusion LLM generating 1000+ tok/sec on commodity GPUs
- Mar 2025First large diffusion-based LLM
- Mar 2025Ask HN: Any insider takes on Yann LeCun's push against current architectures?
- May 2025Mercury: Commercial-scale diffusion language model
- May 2025Mercury: Commercial-scale diffusion language model
- Jul 2025Mercury: Ultra-fast language models based on diffusion
- 67
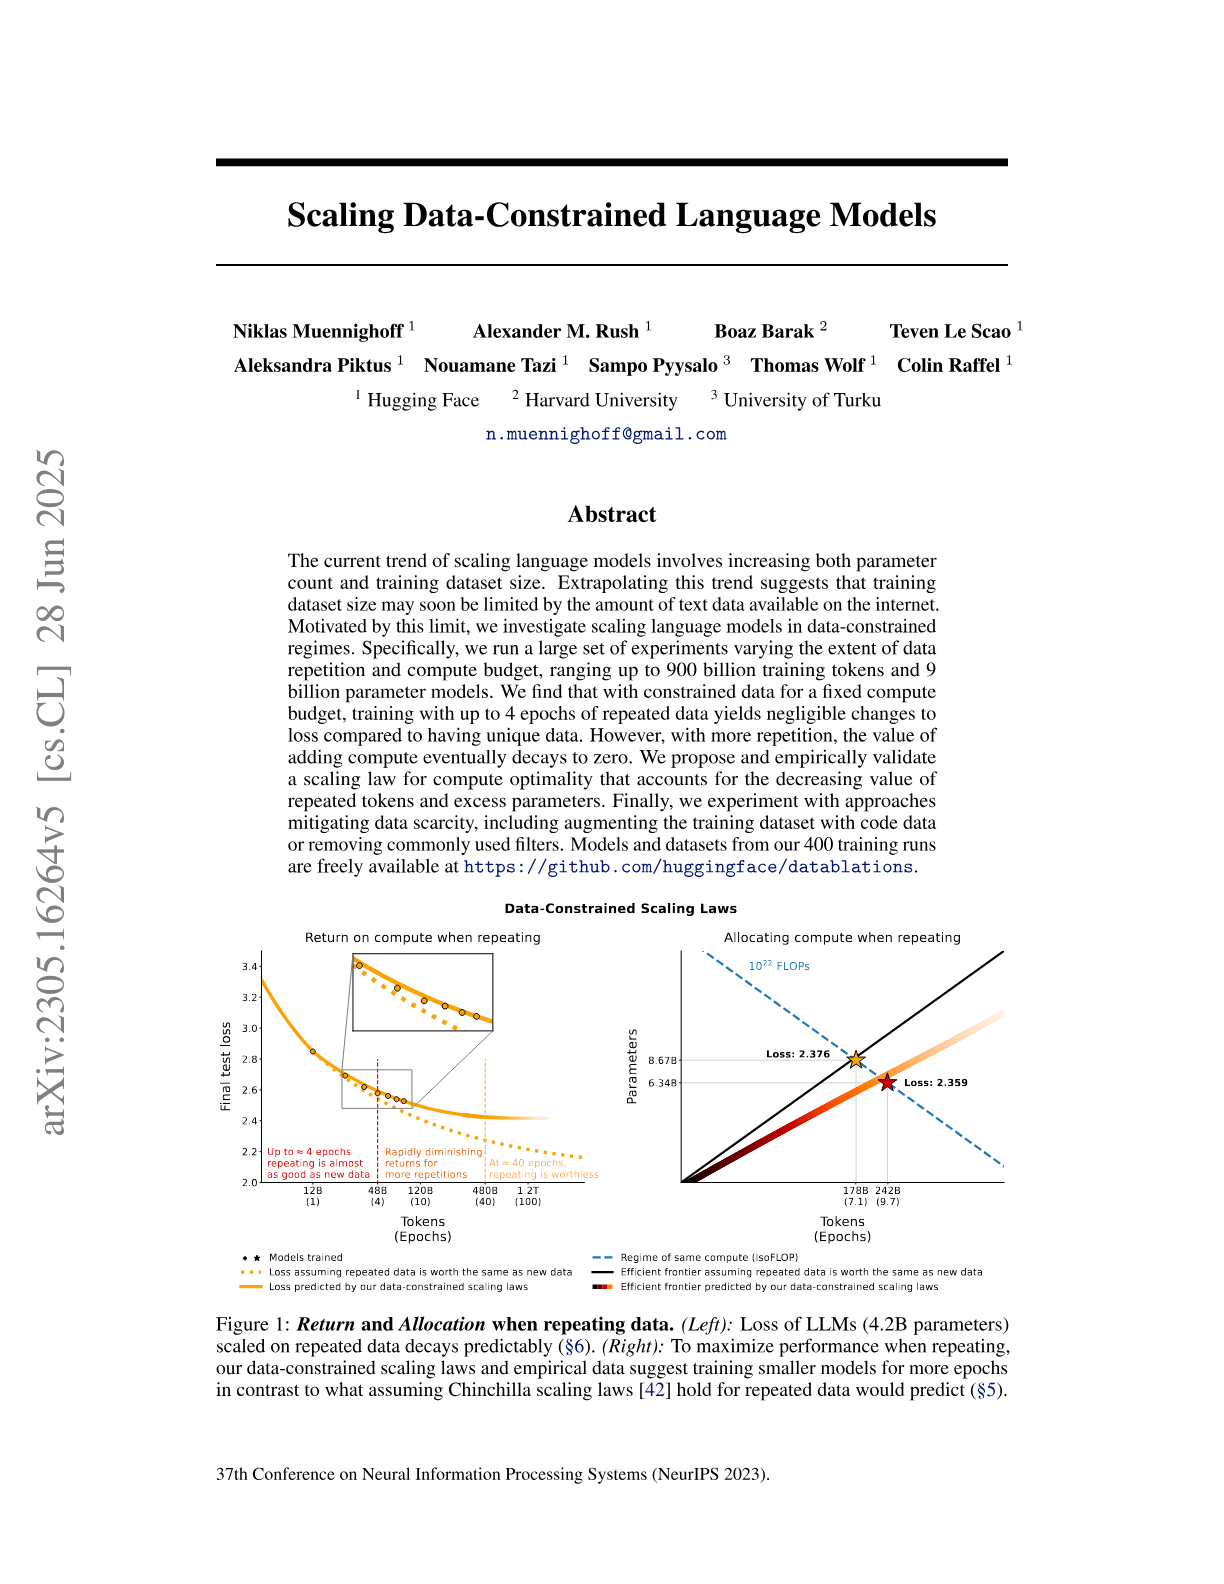
Scaling Data-Constrained Language Models
Hacker News threads
- May 2023Scaling Data-Constrained Language Models
- Sep 2023Chinchilla’s Death
- Sep 2023Can LLMs learn from a single example?
- Sep 2023Can LLMs learn from a single example?
- Aug 2024IsoFLOP curves of large language models are flat
- Jan 2025FrontierMath was funded by OpenAI
- Sep 2026Nvidia wants to put a watchdog chip next to every AI agent
- 68
Gorilla: Large Language Model Connected with Massive APIs
Hacker News threads
- May 2023Gorilla: Large Language Model Connected with APIs
- Jun 2023Gorilla: Large Language Model Connected with APIs
- May 2023Gorilla: LLM Connected with APIs
- Jun 2023Falcon 40B LLM (which beats Llama) now Apache 2.0
- Jun 2023OpenAI Cybersecurity Grant Program
- Jun 2023RedPajama 7B (an Apache 2.0-licensed LLaMa) is now available
- Jun 2023OpenLLaMA 13B Released
- Aug 2023Show HN: Poozle – open-source Plaid for LLMs
- Sep 2023RestGPT
- 69
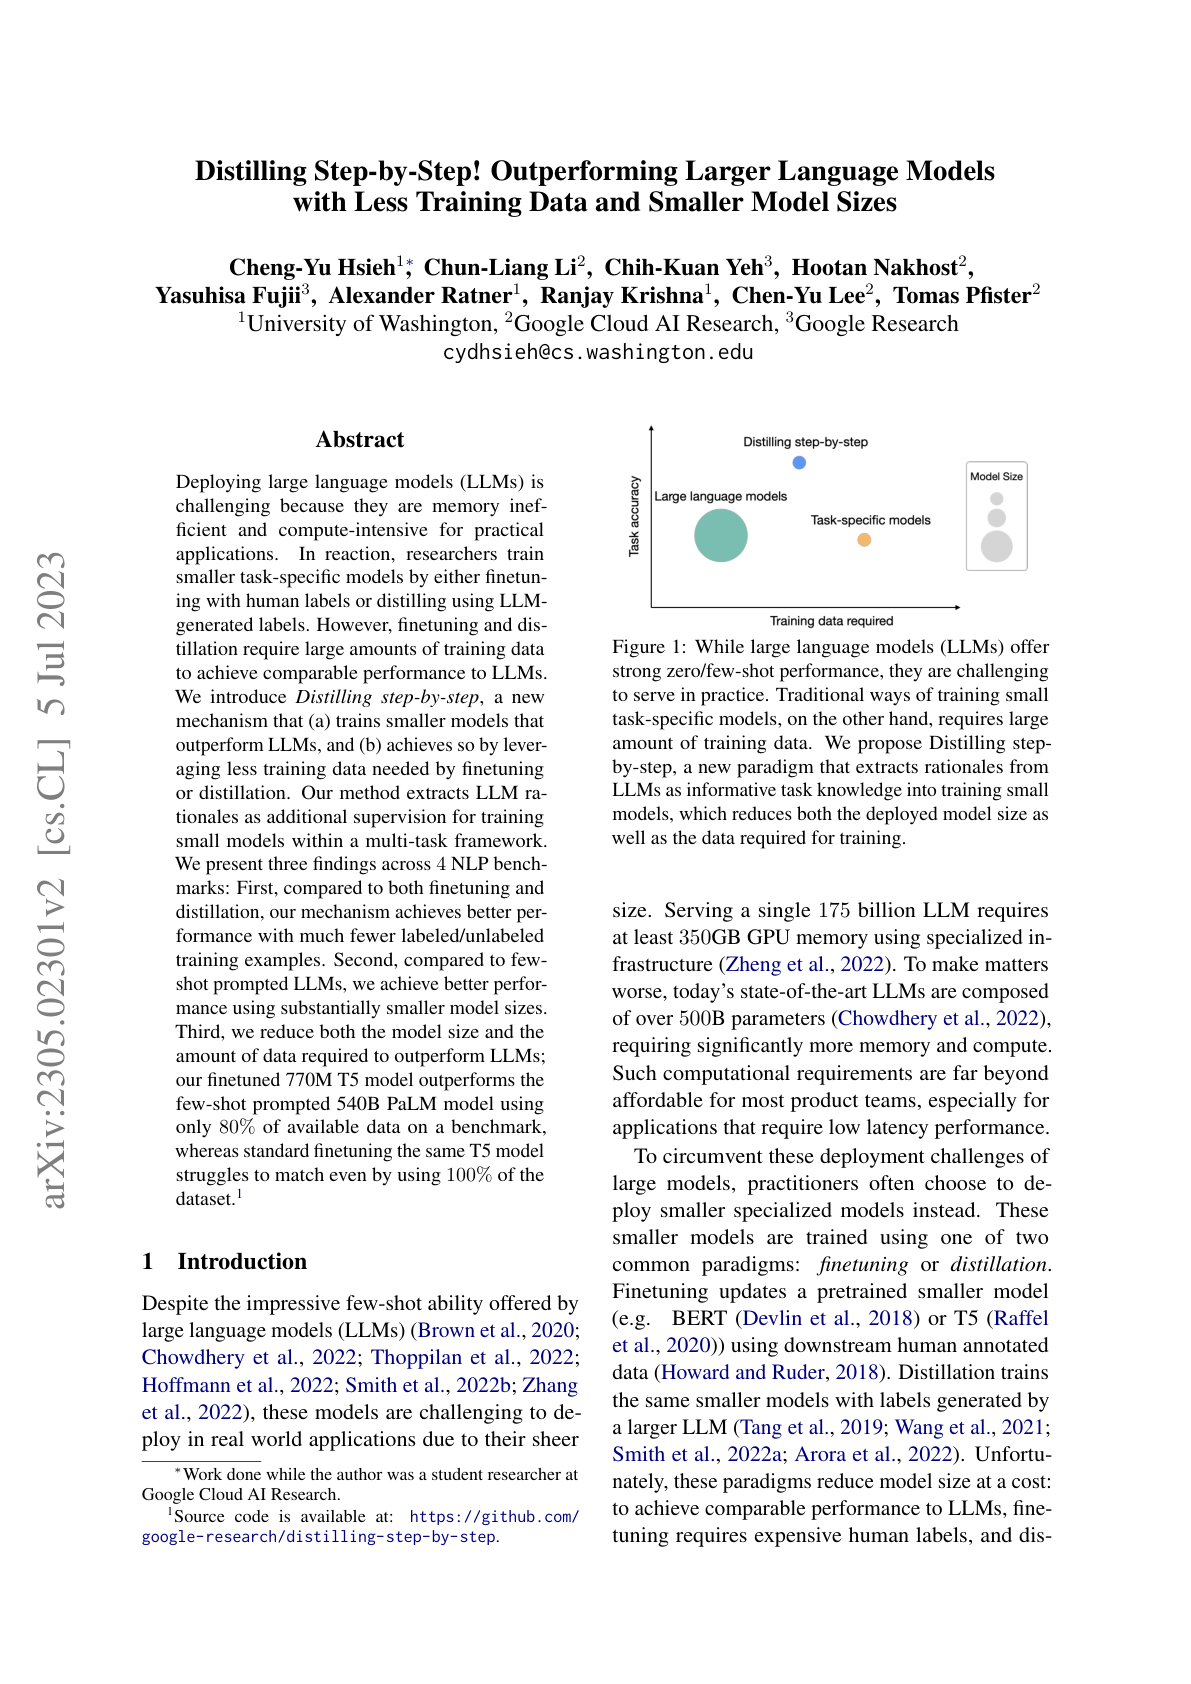
Distilling Step-by-Step! Outperforming Larger Language Models with Less Training Data and Smaller Model Sizes
Hacker News threads
- May 2023Distilling Step-by-Step Outperforming Larger Language Models with Less Training
- May 2023RedPajama (Open LLaMA Replication) 3B and 7B models released
- May 2023PaLM 2 Technical Report [pdf]
- May 2023How to Finetune GPT Like Large Language Models on a Custom Dataset
- Jul 2023
- Dec 2023Phi-2: The surprising power of small language models
- Jan 2025Nvidia’s $589B DeepSeek rout
- 70
Let's Verify Step by Step
Hacker News threads
- Sep 2024Let's Verify Step by Step
- Jun 2023OpenAI: How to Train Reasoning in LLMs
- Aug 2024Let's Verify Step by Step
- Nov 2023Yann LeCun: Ignore the deluge of complete nonsense about Q*
- Nov 2023$10M AI Mathematical Olympiad Prize
- Aug 2024The Threat to OpenAI
- Jan 2025Berkeley Researchers Replicate DeepSeek R1's Core Tech for Just $30: A Small Mod
- Sep 2026Astra and Fable still hack on simple variants of alignment evals from 2025
- 71
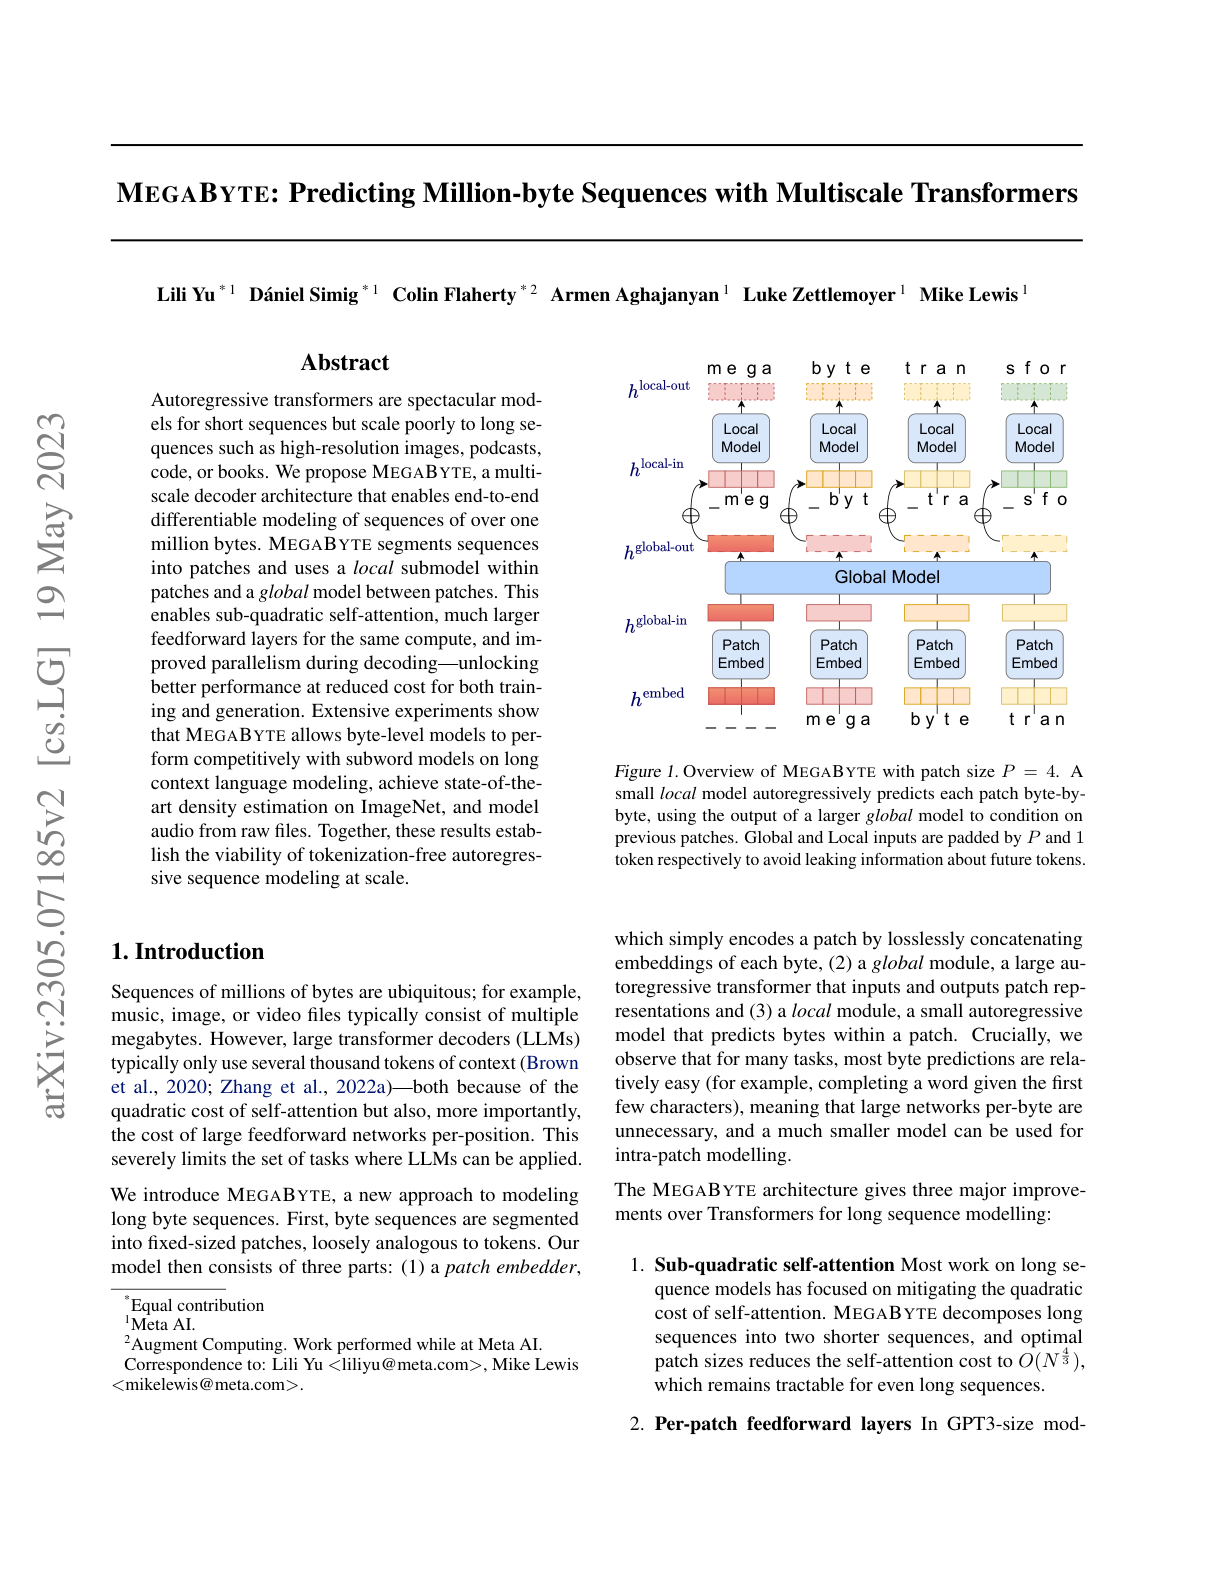
MEGABYTE: Predicting Million-byte Sequences with Multiscale Transformers
Hacker News threads
- Jun 2023Megabyte: Predicting Million-Byte Sequences with Multiscale Transformers
- May 2023Megabyte: Predicting Million-Byte Sequences with Multiscale Transformers
- May 2023Meta AI Megabyte: Predicting Million-Byte Sequences with Multiscale Transformers
- May 2023Meta AI Unleashes Megabyte, a Revolutionary Scalable Model Architecture
- Jun 2023Bytes Are All You Need: Transformers Operating Directly on File Bytes
- Jun 2023Weird GPT-4 behavior for the specific string “ davidjl”
- Feb 2024LongRoPE: Extending LLM Context Window Beyond 2M Tokens
- Oct 2025Neural audio codecs: how to get audio into LLMs
- 72
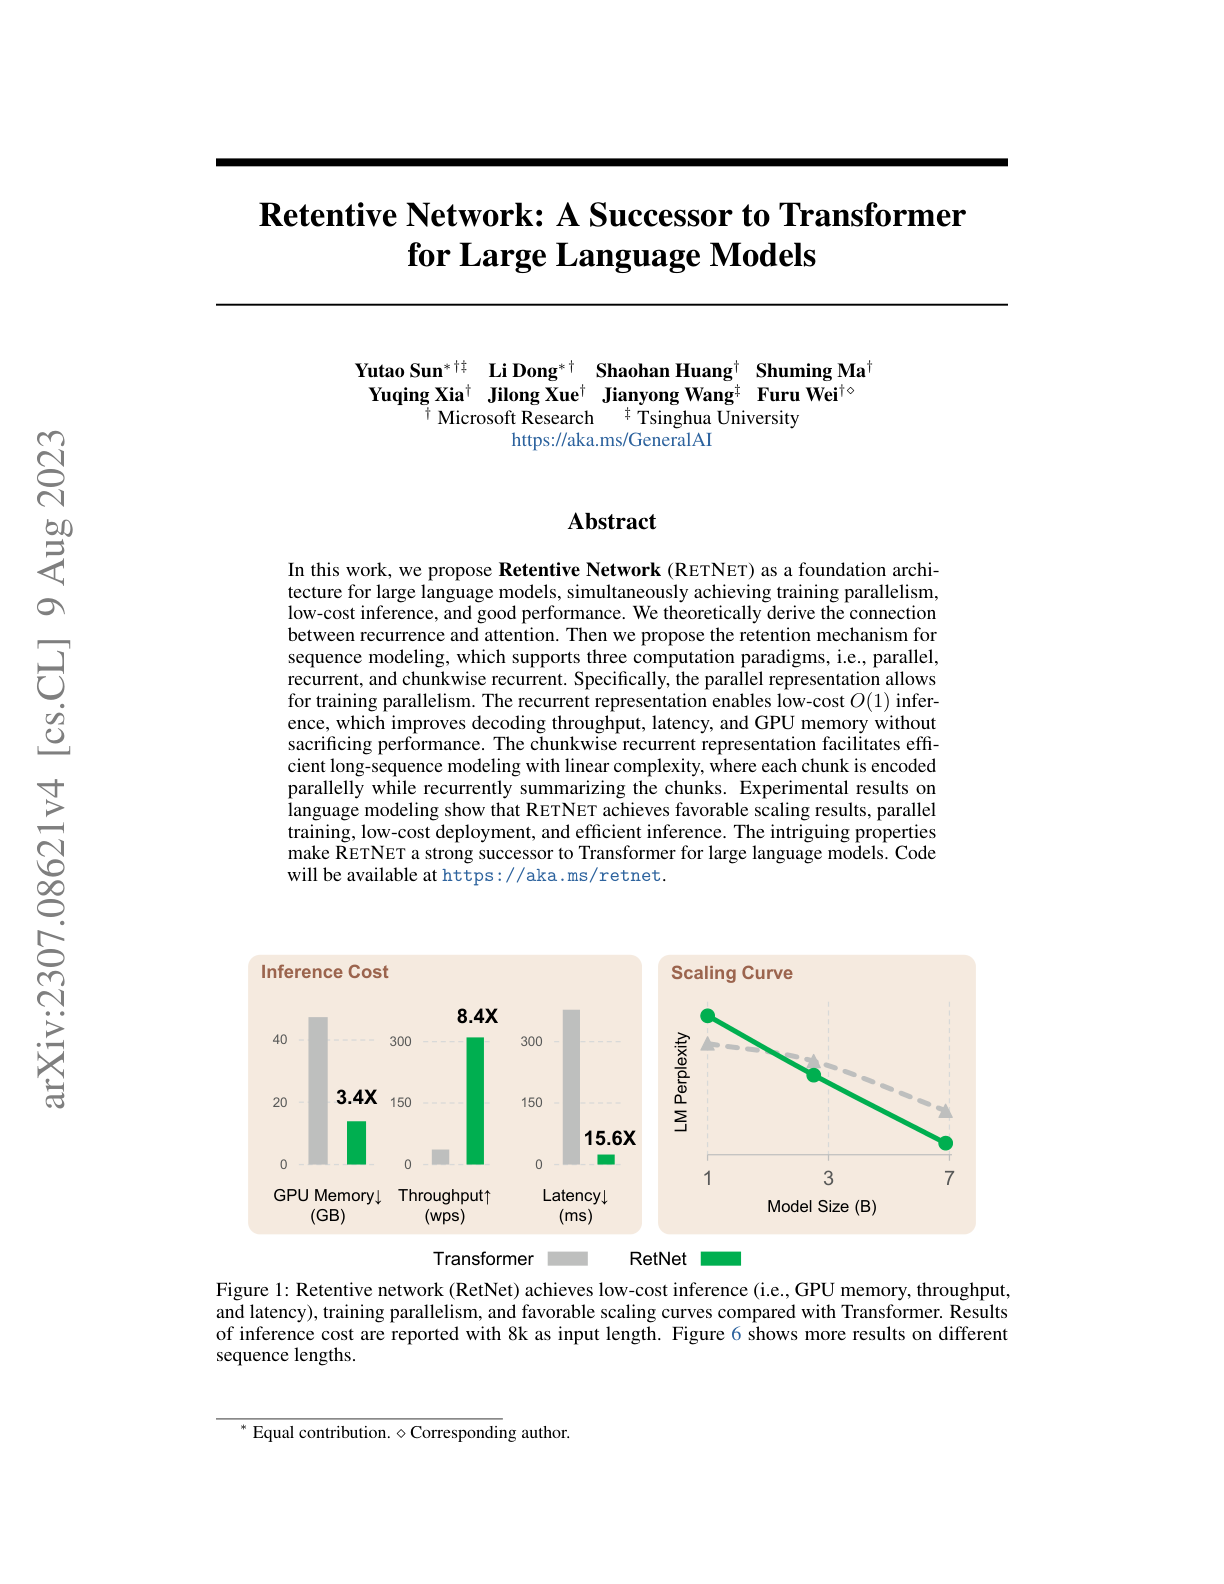
Retentive Network: A Successor to Transformer for Large Language Models
Hacker News threads
- Jul 2023Retentive Network: A Successor to Transformer for Large Language Models
- Jul 2023Retentive Network: A Successor to Transformer for Large Language Models
- Jul 2023Retentive Network: A Successor to Transformer for Large Language Models
- Jul 2023Retentive Network: A Successor to Transformer Implemented in PyTorch
- Sep 2023The Eleuther AI Mafia
- Dec 2023Mamba: Linear-Time Sequence Modeling with Selective State Spaces
- Dec 20232023: The Year of AI
- Jan 2024Eagle 7B: Soaring past Transformers
- 73
Language Models Represent Space and Time
Hacker News threads
- Oct 2023Paper: LLMs have internal world model, and a sense of time and space
- Nov 2023A Coder Considers the Waning Days of the Craft
- Nov 2023Ask HN: Convince me LLMs aren't just autocomplete with lookahead
- Jul 2024ChatGPT Isn't 'Hallucinating'–It's Bullshitting – Scientific American
- Oct 2024Chain-of-thought can hurt performance on tasks where thinking makes humans worse
- Jun 2025The Emperor's New LLM
- 74
Guiding Language Models of Code with Global Context using Monitors
Hacker News threads
- 75
Extending Context Window of Large Language Models via Positional Interpolation
Hacker News threads
- Jun 2023Extending Context Window of Large Language Models via Positional Interpolation
- Jun 2023XGen-7B, a new 7B foundational model trained on up to 8K length for 1.5T tokens
- Jul 2023Llama 2 – Meta AI
- Jul 2023Llama 2 – Meta AI
- Nov 2023Is anyone using self hosted LLM day to day and training it like a new employee
- Jan 2024Phi-2: Self-Extend Boosts Performance, Extends Context to 8k Without Training
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.