Hacker Papers
- 76
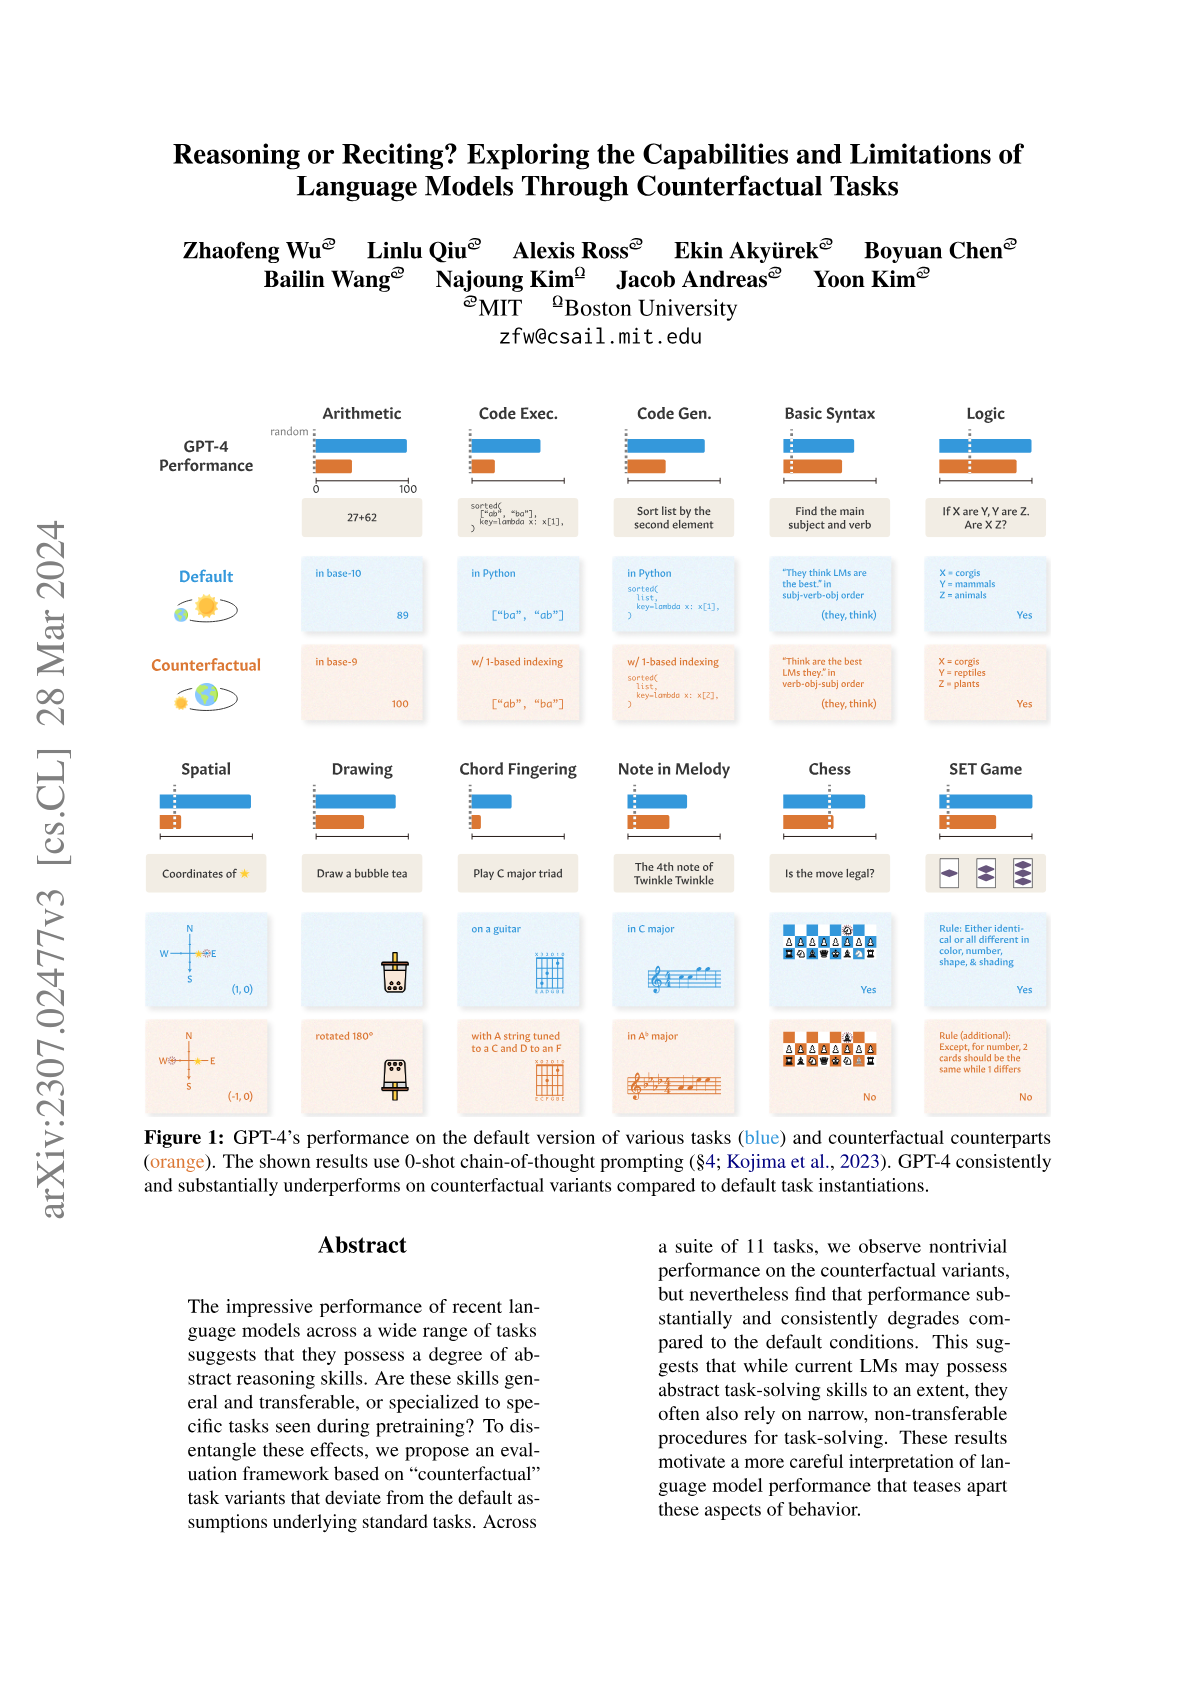
Reasoning or Reciting? Exploring the Capabilities and Limitations of Language Models Through Counterfactual Tasks
Hacker News threads
- Sep 2023Exploring Capabilities, Limitations of Language Models by Counterfactual Tasks
- Jul 2023AI Safety and the Age of Dislightenment
- Dec 2023Will scaling work?
- Jun 2024The illusion of state in state-space models
- Jul 2024Tabloid: A clickbait headline programming language (2021)
- Aug 2024Markov chains are funnier than LLMs
- Aug 2024Markov chains are funnier than LLMs
- Nov 2024DeepThought-8B: A small, capable reasoning model
- 77
An aperiodic monotile
Hacker News threads
- Mar 2023An Aperiodic Monotile
- Mar 2023Mathematicians discover shape that can tile a wall and never repeat
- Oct 2023Hexagonal Grids
- Nov 2023A Brief History of Tricky Mathematical Tiling
- Dec 2023What can you do with an Einstein?
- Feb 2024
- Mar 2024How to Start Google
- 78
QUIC is not Quick Enough over Fast Internet
Hacker News threads
- Oct 2024QUIC is not quick enough over fast internet
- Feb 2024How QUIC is displacing TCP for speed
- Sep 2024QUIC is not quick enough over fast internet
- Sep 2024QUIC is not quick enough over fast internet
- Sep 2024QUIC is not quick enough over fast internet
- Mar 2025HTTP/3 is everywhere but nowhere
- Aug 2025Io_uring, kTLS and Rust for zero syscall HTTPS server
- Aug 2025The first Media over QUIC CDN: Cloudflare
- Oct 2025HTTP3 Explained
- 79
Hyena Hierarchy: Towards Larger Convolutional Language Models
Hacker News threads
- Apr 2023Hyena Hierarchy: Towards Larger Convolutional Language Models
- Apr 2023Hyena a more efficient convolutional LLM when compared to GPT
- Mar 2023Hyena Hierarchy: Towards Larger Convolutional Language Models
- Mar 2023CoLT5: Faster Long-Range Transformers With Conditional Computation
- Apr 2023From Deep to Long Learning
- Apr 2023From Deep to Long Learning
- Apr 2023Stability AI Launches the First of Its StableLM Suite of Language Models
- Apr 2023New technology could blow away GPT-4 and everything like it
- May 2023OpenAI's plans according to sama
- Sep 2023The Eleuther AI Mafia
- Feb 2025The FFT Strikes Back: An Efficient Alternative to Self-Attention
- 80
xVal: A Continuous Numerical Tokenization for Scientific Language Models
Hacker News threads
- Oct 2023Single Digit Tokenization improves LLM Math abilities by up to 70x
- Oct 2023Single Digit tokenization improves LLM math abilities by up to 70x
- Nov 2023Telling GPT-4 you're scared or under pressure improves performance
- Nov 2023Sutskever: OpenAI board doing its mission to build AGI that benefits all
- Nov 2023Sam Altman's ouster was precipitated by letter to board about AI breakthrough
- Nov 2023Sam Altman's ouster was precipitated by letter to board about AI breakthrough
- Mar 2024Integer Tokenization Is Insane (2023)
- Sep 2024AGI is far from inevitable
- Oct 2024Probably pay attention to tokenizers
- 81
SparseGPT: Massive Language Models Can Be Accurately Pruned in One-Shot
Hacker News threads
- May 2023SparseGPT: Language Models Can Be Accurately Pruned in One-Shot
- Jan 2023Some Remarks on Large Language Models – Yoav Goldberg
- Mar 2023Neural Chip Plays Doom Using a Thousandth of a Watt
- Apr 2023Stability AI Launches the First of Its StableLM Suite of Language Models
- Apr 2023GitHub Copilot emits GPL code
- May 2023How to run Llama 13B with a 6GB graphics card
- May 2023OpenAI chief goes before US Congress to propose licenses for building AI
- Apr 2024Show HN: Speeding up LLM inference 2x times (possibly)
- 82
Gemini: A Family of Highly Capable Multimodal Models
Hacker News threads
- Dec 2023Gemini: A Family of Highly Capable Multimodal Models
- Dec 2023Gemini: A Family of Highly Capable Multimodal Models
- Feb 2024The killer app of Gemini Pro 1.5 is using video as an input
- Mar 2024Four new models that are benchmarking near or above GPT-4
- Apr 2024Hello OLMo: A truly open LLM
- May 2024Gemini Nano coming built in to Chrome 126, powered by WebGPU
- Dec 2025Gemini 3 Pro: the frontier of vision AI
- 83
Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena
Hacker News threads
- Apr 2024Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena
- Jul 2023LLaMA2 Chat 70B outperformed ChatGPT
- Oct 2023Show HN: Tonic Validate Metrics – an open-source RAG evaluation metrics package
- Dec 2023Gemini Pro achieves accuracy slightly inferior to GPT 3.5 Turbo
- Apr 2025Chain of Recursive Thoughts: Make AI think harder by making it argue with itself
- Jun 2025LLM code generation may lead to an erosion of trust
- 84
faulTPM: Exposing AMD fTPMs' Deepest Secrets
Hacker News threads
- May 2023AMD's Firmware TPMs Vulnerable to Hardware Attacks, Defeating Disk Encryption
- May 2023FaulTPM: Exposing AMD FTPMs' Deepest Secrets
- Jul 2023Web Environment Integrity Explainer
- Jul 2023Web Environment Integrity API
- Aug 2023Hackers manage to unlock Tesla software-locked features
- Nov 2023Linux and TPMs with systemd measured boot [video]
- Jan 2026Tailscale state file encryption no longer enabled by default
- Jan 2026TPM on Embedded Systems: Pitfalls and Caveats to Watch Out For
- May 2026Microsoft BitLocker – YellowKey zero-day exploit
- May 2026Security researcher says Microsoft built a Bitlocker backdoor, releases exploit
- 85
Mathematical Capabilities of ChatGPT
Hacker News threads
- Feb 2023Mathematical Capabilities of ChatGPT
- Mar 2023Ask HN: Who wants to be hired? (March 2023)
- Apr 2023Ask HN: Who wants to be hired? (April 2023)
- Apr 2023
- Jun 2023MIT Responds to “ Exploring the MIT Mathematics and EECS Curriculum Using LLMs” [pdf]
- Oct 2023AI is replacing customer service jobs across the globe
- Oct 2023GPT-4 Understands
- Jun 2024Terence Tao on proof checkers and AI programs
- 86
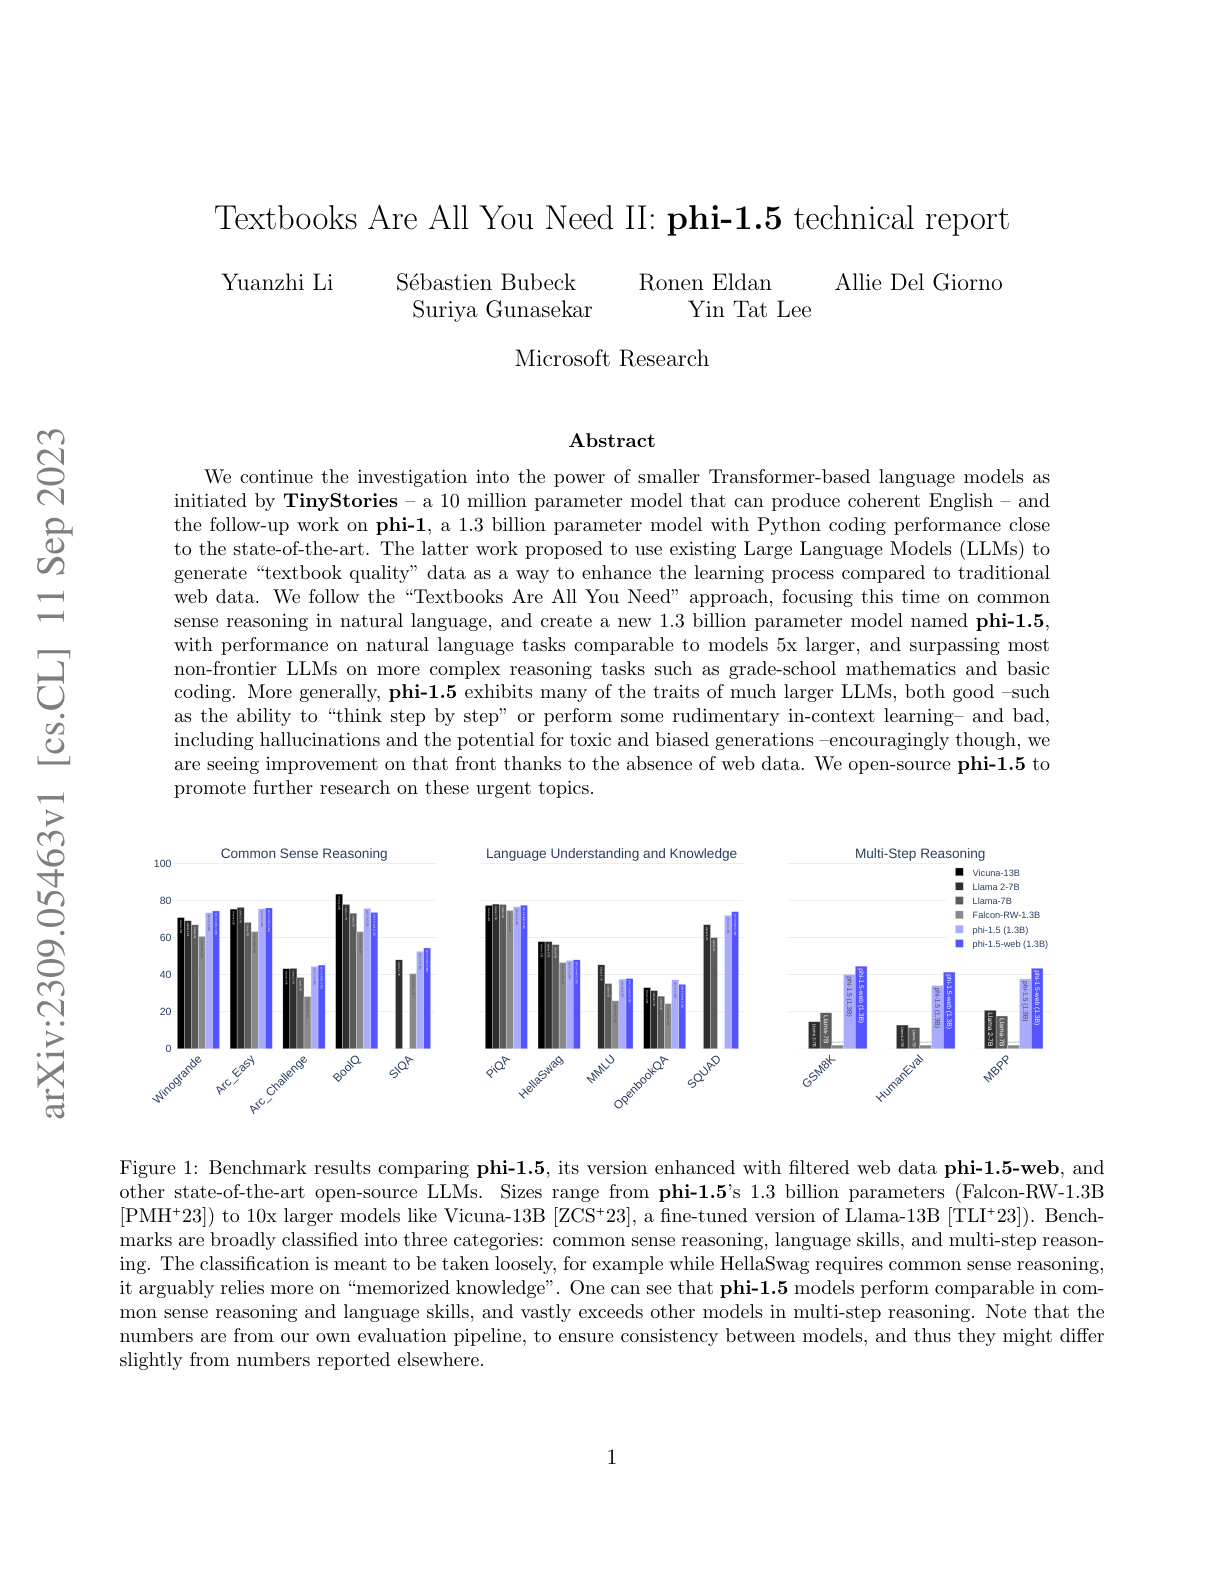
Textbooks Are All You Need II: phi-1.5 technical report
Hacker News threads
- Sep 2023The tide is shifting: 1.3B outperforms 7B Llama 2
- Sep 2023Textbooks Are All You Need II: phi-1.5 technical report
- Sep 2023Large Language Models for Compiler Optimization
- Sep 2023Outperforming LLMs with less training data and smaller model sizes
- Oct 2023AI hype is built on high test scores. Those tests are flawed
- Nov 2023A Coder Considers the Waning Days of the Craft
- Nov 2023MonadGPT – What would have happened if ChatGPT was invented in the 17th century?
- Jan 2024Microsoft Phi-2 model changes licence to MIT
- Jan 2024Ten Noteworthy AI Research Papers of 2023
- Jan 2024A Philosophical Introduction to Language Models
- 87
Distilling Step-by-Step! Outperforming Larger Language Models with Less Training Data and Smaller Model Sizes
Hacker News threads
- May 2023Distilling Step-by-Step Outperforming Larger Language Models with Less Training
- May 2023RedPajama (Open LLaMA Replication) 3B and 7B models released
- May 2023PaLM 2 Technical Report [pdf]
- May 2023How to Finetune GPT Like Large Language Models on a Custom Dataset
- Jul 2023
- Dec 2023Phi-2: The surprising power of small language models
- Jan 2025Nvidia’s $589B DeepSeek rout
- 88
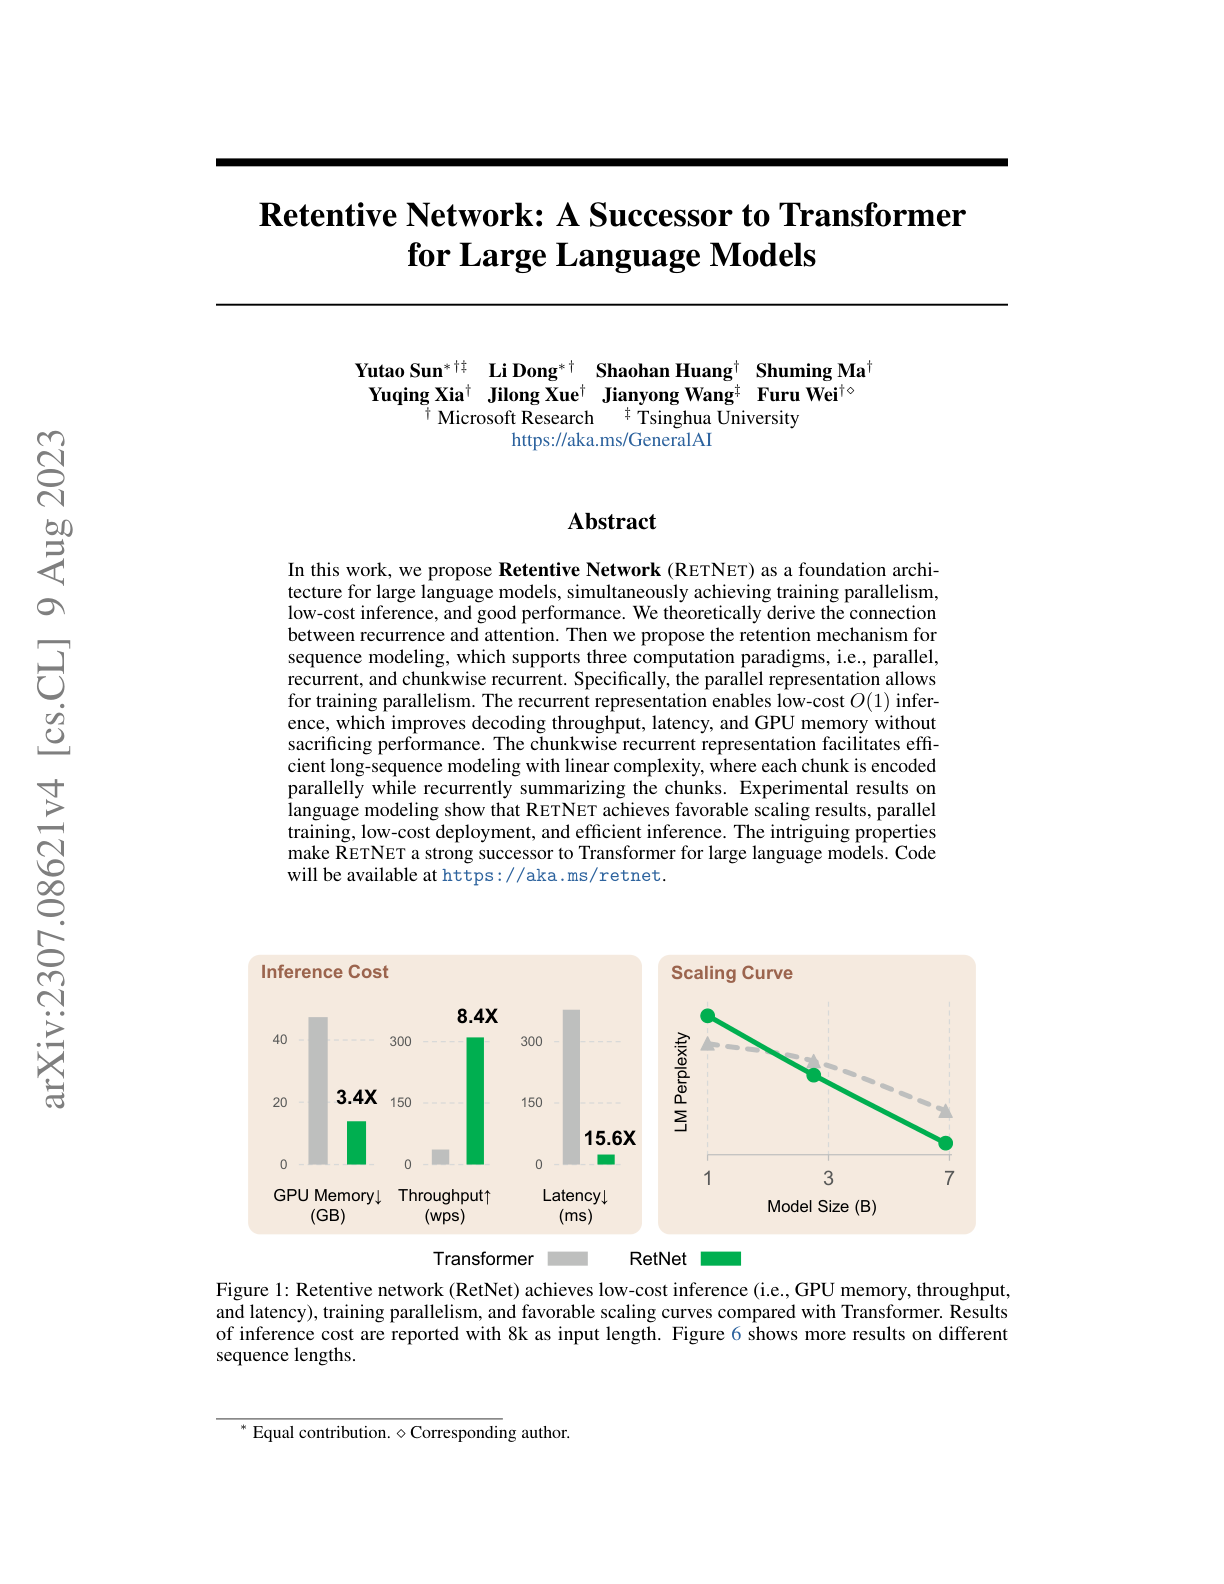
Retentive Network: A Successor to Transformer for Large Language Models
Hacker News threads
- Jul 2023Retentive Network: A Successor to Transformer for Large Language Models
- Jul 2023Retentive Network: A Successor to Transformer for Large Language Models
- Jul 2023Retentive Network: A Successor to Transformer for Large Language Models
- Jul 2023Retentive Network: A Successor to Transformer Implemented in PyTorch
- Sep 2023The Eleuther AI Mafia
- Dec 2023Mamba: Linear-Time Sequence Modeling with Selective State Spaces
- Dec 20232023: The Year of AI
- Jan 2024Eagle 7B: Soaring past Transformers
- 89
Extending Context Window of Large Language Models via Positional Interpolation
Hacker News threads
- Jun 2023Extending Context Window of Large Language Models via Positional Interpolation
- Jun 2023XGen-7B, a new 7B foundational model trained on up to 8K length for 1.5T tokens
- Jul 2023Llama 2 – Meta AI
- Jul 2023Llama 2 – Meta AI
- Nov 2023Is anyone using self hosted LLM day to day and training it like a new employee
- Jan 2024Phi-2: Self-Extend Boosts Performance, Extends Context to 8k Without Training
- 90
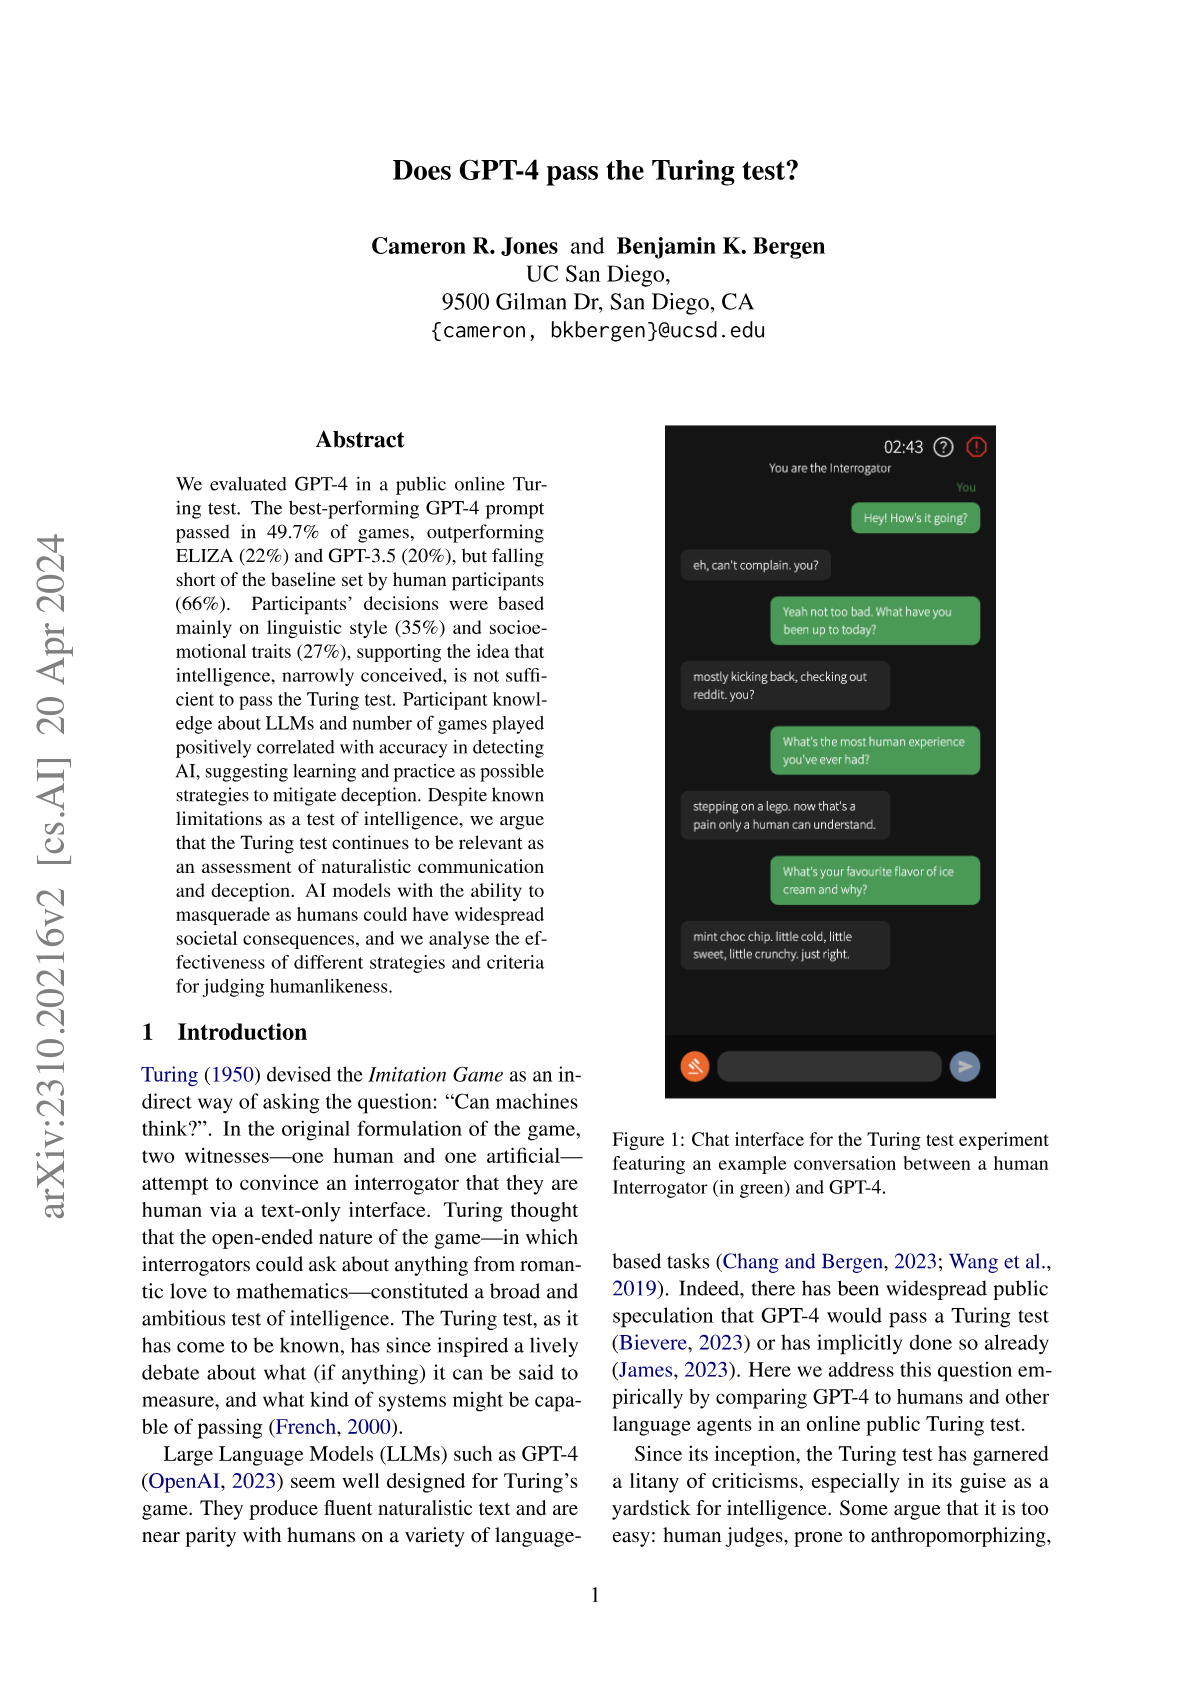
Does GPT-4 pass the Turing test?
Hacker News threads
- Nov 2023Does GPT-4 Pass the Turing Test?
- Nov 2023Does GPT-4 Pass the Turing Test?
- Nov 2023OpenAI Announces Leadership Transition
- Dec 20231960s chatbot ELIZA beat OpenAI's GPT-3.5 in a recent Turing test study
- Jan 2024Stuff we figured out about AI in 2023
- Jan 2024AI or Ain't: Eliza
- Jun 2024AI Hype is completely out of control – especially since ChatGPT-4o [video]
- 91
Large Language Models are Effective Text Rankers with Pairwise Ranking Prompting
Hacker News threads
- 92
Do Language Models Know When They're Hallucinating References?
Hacker News threads
- May 2023Do Language Models Know When They're Hallucinating References?
- Aug 2023How to Get ChatGPT to Stop Apologizing?
- Sep 2023ChatGPT can now see, hear, and speak – openai.com
- Oct 2023Llama 2 Everywhere (L2E): Standalone, Binary Portable, Bootable Llama 2
- Mar 2025AI Blindspots – Blindspots in LLMs I've noticed while AI coding
- 93
A Benchmark for Learning to Translate a New Language from One Grammar Book
Hacker News threads
- Jun 2024A Benchmark for Learning to Translate a New Language from One Grammar Book
- Mar 2024How well can LLMs write COBOL?
- Jun 2024Prompting LLMs to Learn Language from a Single Book
- Nov 2024The deep learning boom caught almost everyone by surprise
- Apr 2025DolphinGemma: How Google AI is helping decode dolphin communication
- 94
ConvNets Match Vision Transformers at Scale
Hacker News threads
- Oct 2023ConvNets Match Vision Transformers at Scale
- Oct 2023ConvNets Match Vision Transformers at Scale
- Oct 2023ConvNets Match Vision Transformers at Scale
- Mar 2024The Google employees who created transformers
- Apr 2024Vision Transformers Are Overrated
- Apr 2024Vision Transformers Are Overrated
- Sep 2025Automatic differentiation can be incorrect
- Dec 2025The Illustrated Transformer
- 95
Optimizing Datalog for the GPU
Hacker News threads
- 96
Shor's Algorithm Does Not Factor Large Integers in the Presence of Noise
Hacker News threads
- 97
GPQA: A Graduate-Level Google-Proof Q&A Benchmark
Hacker News threads
- 98
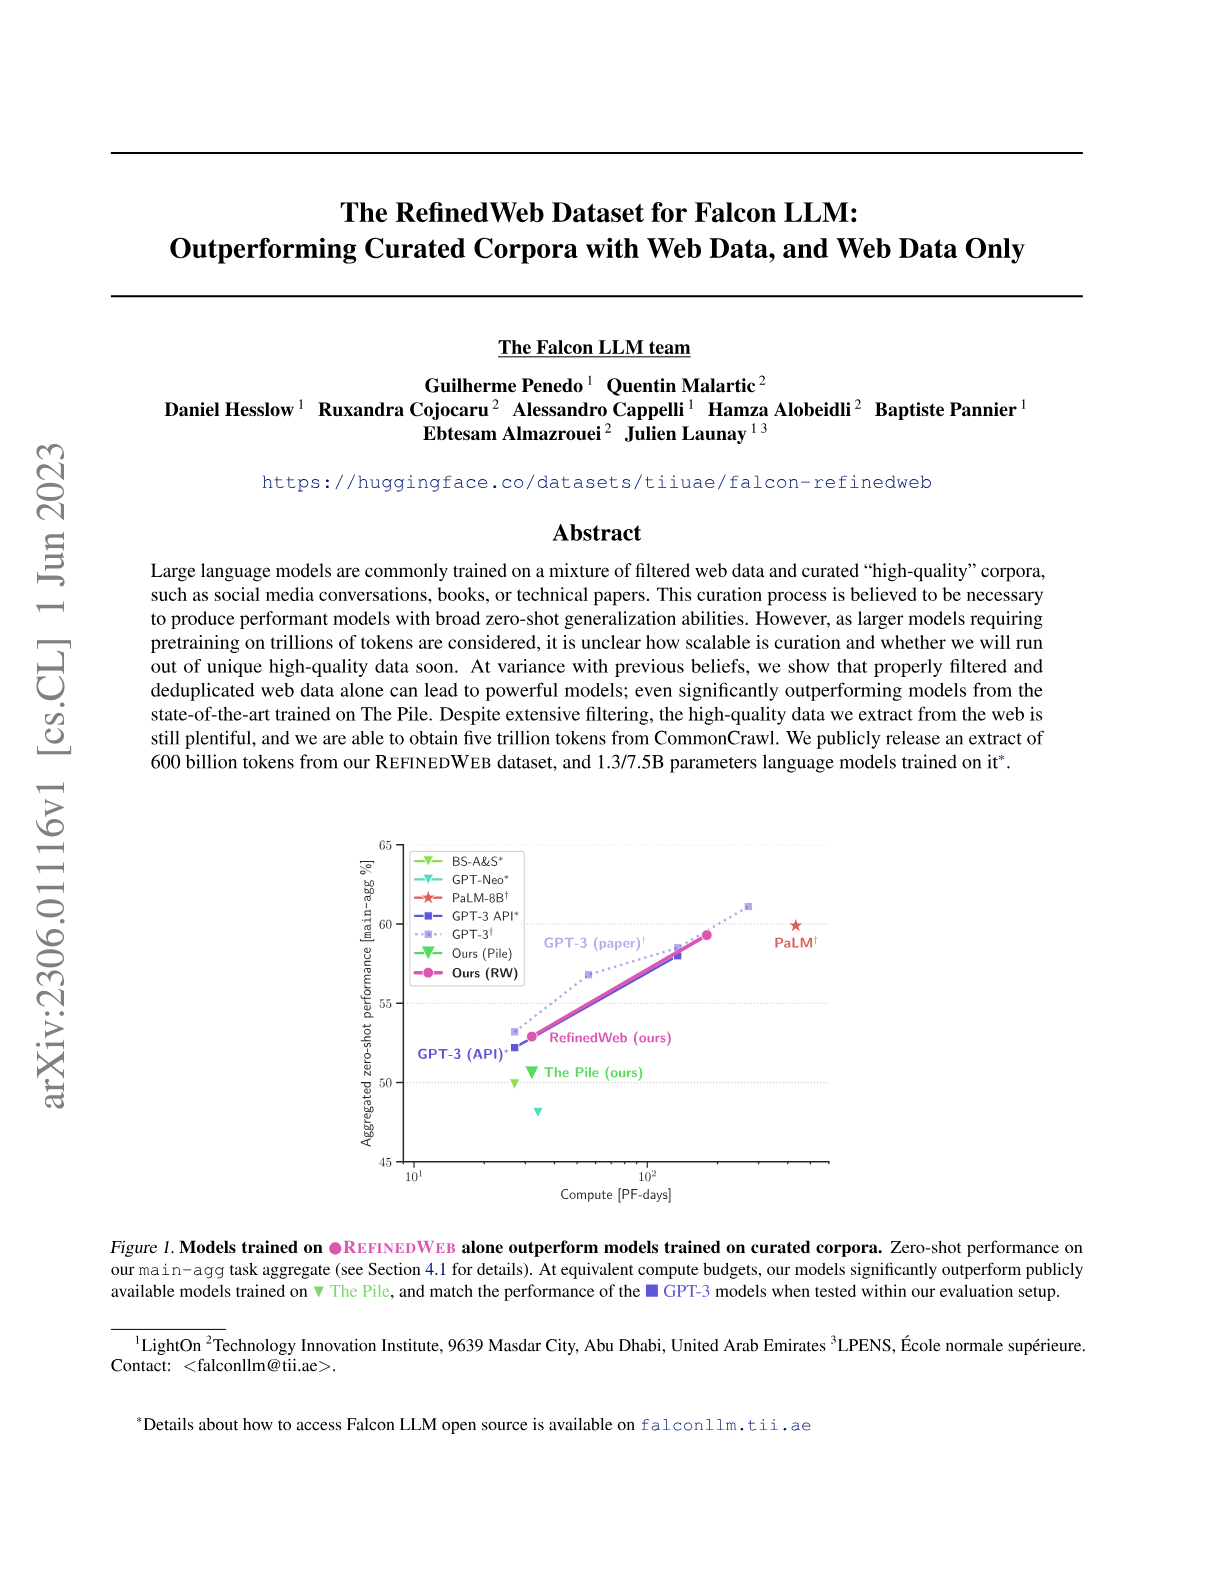
The RefinedWeb Dataset for Falcon LLM: Outperforming Curated Corpora with Web Data, and Web Data Only
Hacker News threads
- 99
The False Promise of Imitating Proprietary LLMs
Hacker News threads
- May 2023The False Promise of Imitating Proprietary LLMs
- Jun 2026The False Promise of Imitating Proprietary LLMs
- May 2023Gorilla: LLM Connected with APIs
- May 2023What Neeva's quiet exit tells us about the future of AI startups
- May 2023HN thread 36136318
- Jun 2023OpenAI's plans according to Sam Altman
- Jun 2023Textbooks are all you need
- Jun 2026Anthropic Accuses Alibaba of 'Illicitly' Accessing AI Models
- 100
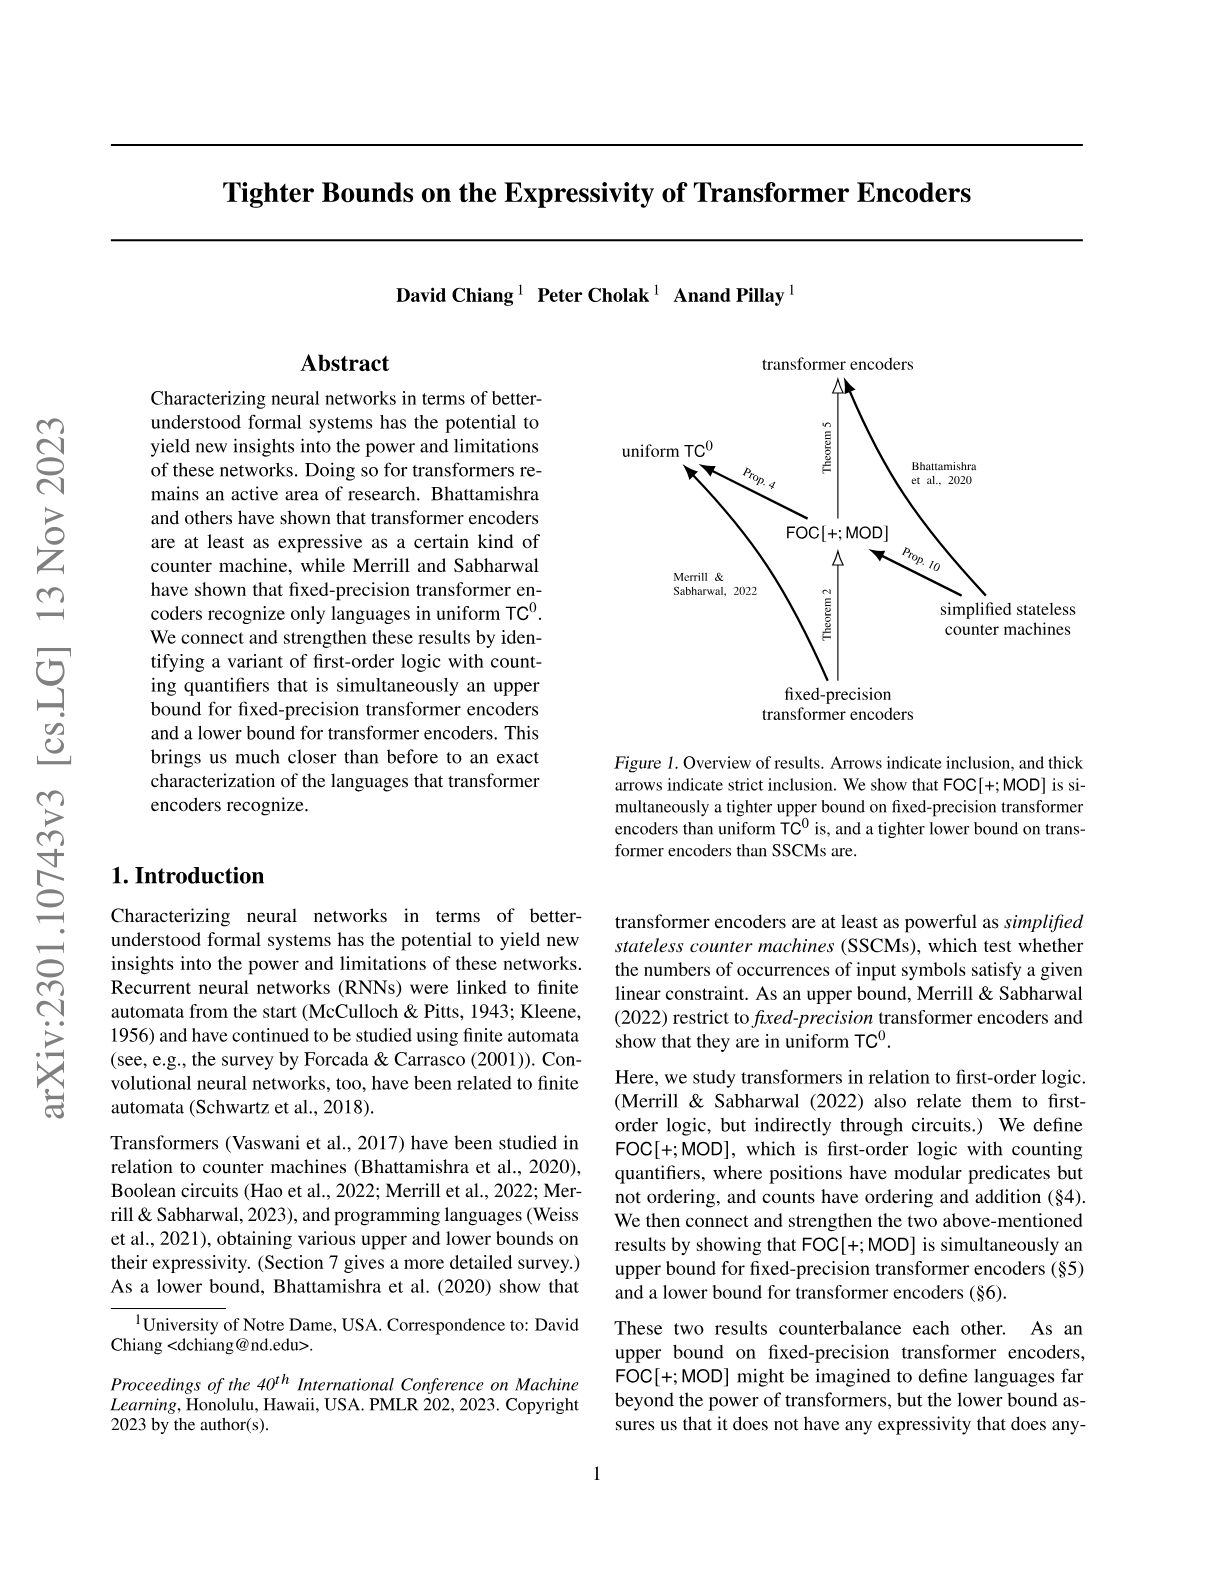
Tighter Bounds on the Expressivity of Transformer Encoders
Hacker News threads
- Apr 2023Tighter bounds on the expressivity of transformer encoders
- Jun 2023Thinking Like Transformers (pdf)
- Jun 2023Researchers warn of ‘model collapse’ as AI trains on AI-generated content
- Dec 2023Ask HN: AI/ML papers to catch up with current state of AI?
- Jan 2024Turing Complete Transformers: Two Transformers Are More Powerful Than One
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.