Hacker Papers
- 76
Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena
Hacker News threads
- Apr 2024Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena
- Jul 2023LLaMA2 Chat 70B outperformed ChatGPT
- Oct 2023Show HN: Tonic Validate Metrics – an open-source RAG evaluation metrics package
- Dec 2023Gemini Pro achieves accuracy slightly inferior to GPT 3.5 Turbo
- Apr 2025Chain of Recursive Thoughts: Make AI think harder by making it argue with itself
- Jun 2025LLM code generation may lead to an erosion of trust
- 77
Levels of AGI for Operationalizing Progress on the Path to AGI
Hacker News threads
- Nov 2023Levels of AGI: Operationalizing Progress on the Path to AGI
- Nov 2023Levels of AGI: Operationalizing Progress on the Path to AGI
- Nov 2023DeepMind on the Definitions and Levels of AGI
- Nov 2023Sutskever: OpenAI board doing its mission to build AGI that benefits all
- Nov 2023The deal to bring Sam Altman back to OpenAI has fallen apart
- Dec 2023Audiobox: Meta's new foundation research model for audio generation
- Mar 2024Elon Musk sues Sam Altman, Greg Brockman, and OpenAI [pdf]
- May 2024Transformers Can Do Arithmetic with the Right Embeddings
- May 2025Evolving OpenAI's Structure
- May 2025John Carmack talk at Upper Bound 2025
- Jun 2025Seven replies to the viral Apple reasoning paper and why they fall short
- 78
Language Models Represent Space and Time
Hacker News threads
- Oct 2023Paper: LLMs have internal world model, and a sense of time and space
- Nov 2023A Coder Considers the Waning Days of the Craft
- Nov 2023Ask HN: Convince me LLMs aren't just autocomplete with lookahead
- Jul 2024ChatGPT Isn't 'Hallucinating'–It's Bullshitting – Scientific American
- Oct 2024Chain-of-thought can hurt performance on tasks where thinking makes humans worse
- Jun 2025The Emperor's New LLM
- 79
G-Eval: NLG Evaluation using GPT-4 with Better Human Alignment
Hacker News threads
- 80
Guiding Language Models of Code with Global Context using Monitors
Hacker News threads
- 81
DiLoCo: Distributed Low-Communication Training of Language Models
Hacker News threads
- Jul 2024DiLoCo: Distributed Low-Communication Training of Language Models
- Nov 2023DiLoCo: Distributed Low-Communication Training of Language Models
- Nov 2023Distributed Low-Communication Training of Language Models
- Nov 2023Ultra Fast Bert
- Mar 2024Stable Diffusion 3: Research Paper
- Sep 2024Meta AI: "The Future of AI Is Open Source and Decentralized"
- May 2025Intellect-2 Release: The First 32B Model Trained Through Globally Distributed RL
- 82
Double Descent Demystified: Identifying, Interpreting & Ablating the Sources of a Deep Learning Puzzle
Hacker News threads
- 83
Starlink Generation 2 Mini Satellites: Photometric Characterization
Hacker News threads
- 84
A Benchmark for Learning to Translate a New Language from One Grammar Book
Hacker News threads
- Jun 2024A Benchmark for Learning to Translate a New Language from One Grammar Book
- Mar 2024How well can LLMs write COBOL?
- Jun 2024Prompting LLMs to Learn Language from a Single Book
- Nov 2024The deep learning boom caught almost everyone by surprise
- Apr 2025DolphinGemma: How Google AI is helping decode dolphin communication
- 85
Scaling Laws for Generative Mixed-Modal Language Models
Hacker News threads
- 86
Getting from Generative AI to Trustworthy AI: What LLMs might learn from Cyc
Hacker News threads
- Aug 2023Getting from Generative AI to Trustworthy AI: What LLMs Might Learn from Cyc
- Sep 2023Getting from Generative AI to Trustworthy AI: What LLMs Might Learn from Cyc
- Aug 2023Getting from Generative AI to Trustworthy AI: What LLMs Might Learn from Cyc
- Sep 2023Doug Lenat has died
- Sep 2023Recursively Summarizing Enables Long-Term Dialogue Memory in LLMs
- Sep 2023Lenat and Cyc
- Jun 2024ARC Prize – a $1M+ competition towards open AGI progress
- Nov 2024LLMs have reached a point of diminishing returns
- Apr 2025Obituary for Cyc
- 87
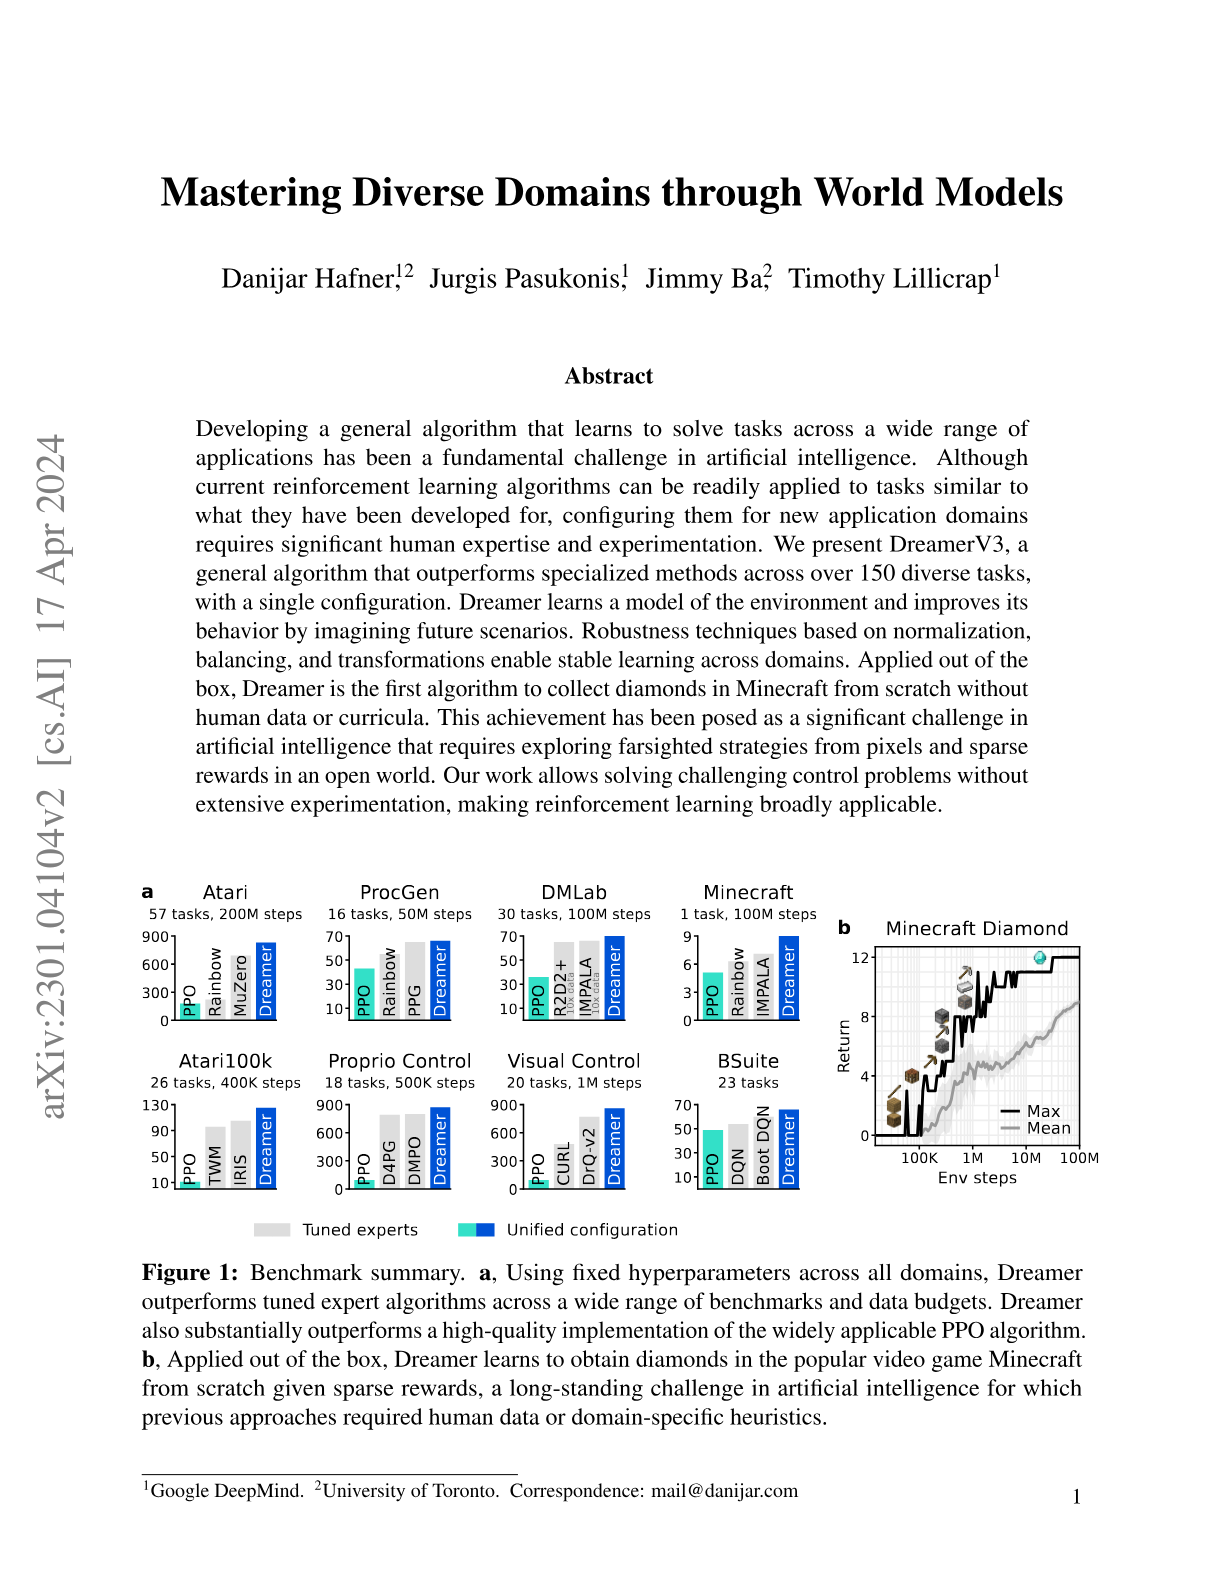
Mastering Diverse Domains through World Models
Hacker News threads
- 88
Do Black Holes have Singularities?
Hacker News threads
- Dec 2023Roy Kerr: Do Black Holes Have Singularities?
- Feb 2024Relativistic Spaceship
- Feb 2024Brightest and fastest-growing: astronomers identify record-breaking quasar
- Apr 2024Astronomers discover Milky Way’s biggest stellar black hole
- May 2024Three of the oldest stars in the universe found circling the Milky Way
- Jun 2024Einstein and his peers were resistant to black holes
- Jul 2024Cosmic simulation reveals how black holes grow and evolve
- Oct 2024On the Nature of Time
- Mar 2025James Webb Space Telescope reveals that most galaxies rotate clockwise
- 89
Do Language Models Know When They're Hallucinating References?
Hacker News threads
- May 2023Do Language Models Know When They're Hallucinating References?
- Aug 2023How to Get ChatGPT to Stop Apologizing?
- Sep 2023ChatGPT can now see, hear, and speak – openai.com
- Oct 2023Llama 2 Everywhere (L2E): Standalone, Binary Portable, Bootable Llama 2
- Mar 2025AI Blindspots – Blindspots in LLMs I've noticed while AI coding
- 90
Resurrecting Recurrent Neural Networks for Long Sequences
Hacker News threads
- 91
Hyena Hierarchy: Towards Larger Convolutional Language Models
Hacker News threads
- Apr 2023Hyena Hierarchy: Towards Larger Convolutional Language Models
- Apr 2023Hyena a more efficient convolutional LLM when compared to GPT
- Mar 2023Hyena Hierarchy: Towards Larger Convolutional Language Models
- Mar 2023CoLT5: Faster Long-Range Transformers With Conditional Computation
- Apr 2023From Deep to Long Learning
- Apr 2023From Deep to Long Learning
- Apr 2023Stability AI Launches the First of Its StableLM Suite of Language Models
- Apr 2023New technology could blow away GPT-4 and everything like it
- May 2023OpenAI's plans according to sama
- Sep 2023The Eleuther AI Mafia
- Feb 2025The FFT Strikes Back: An Efficient Alternative to Self-Attention
- 92
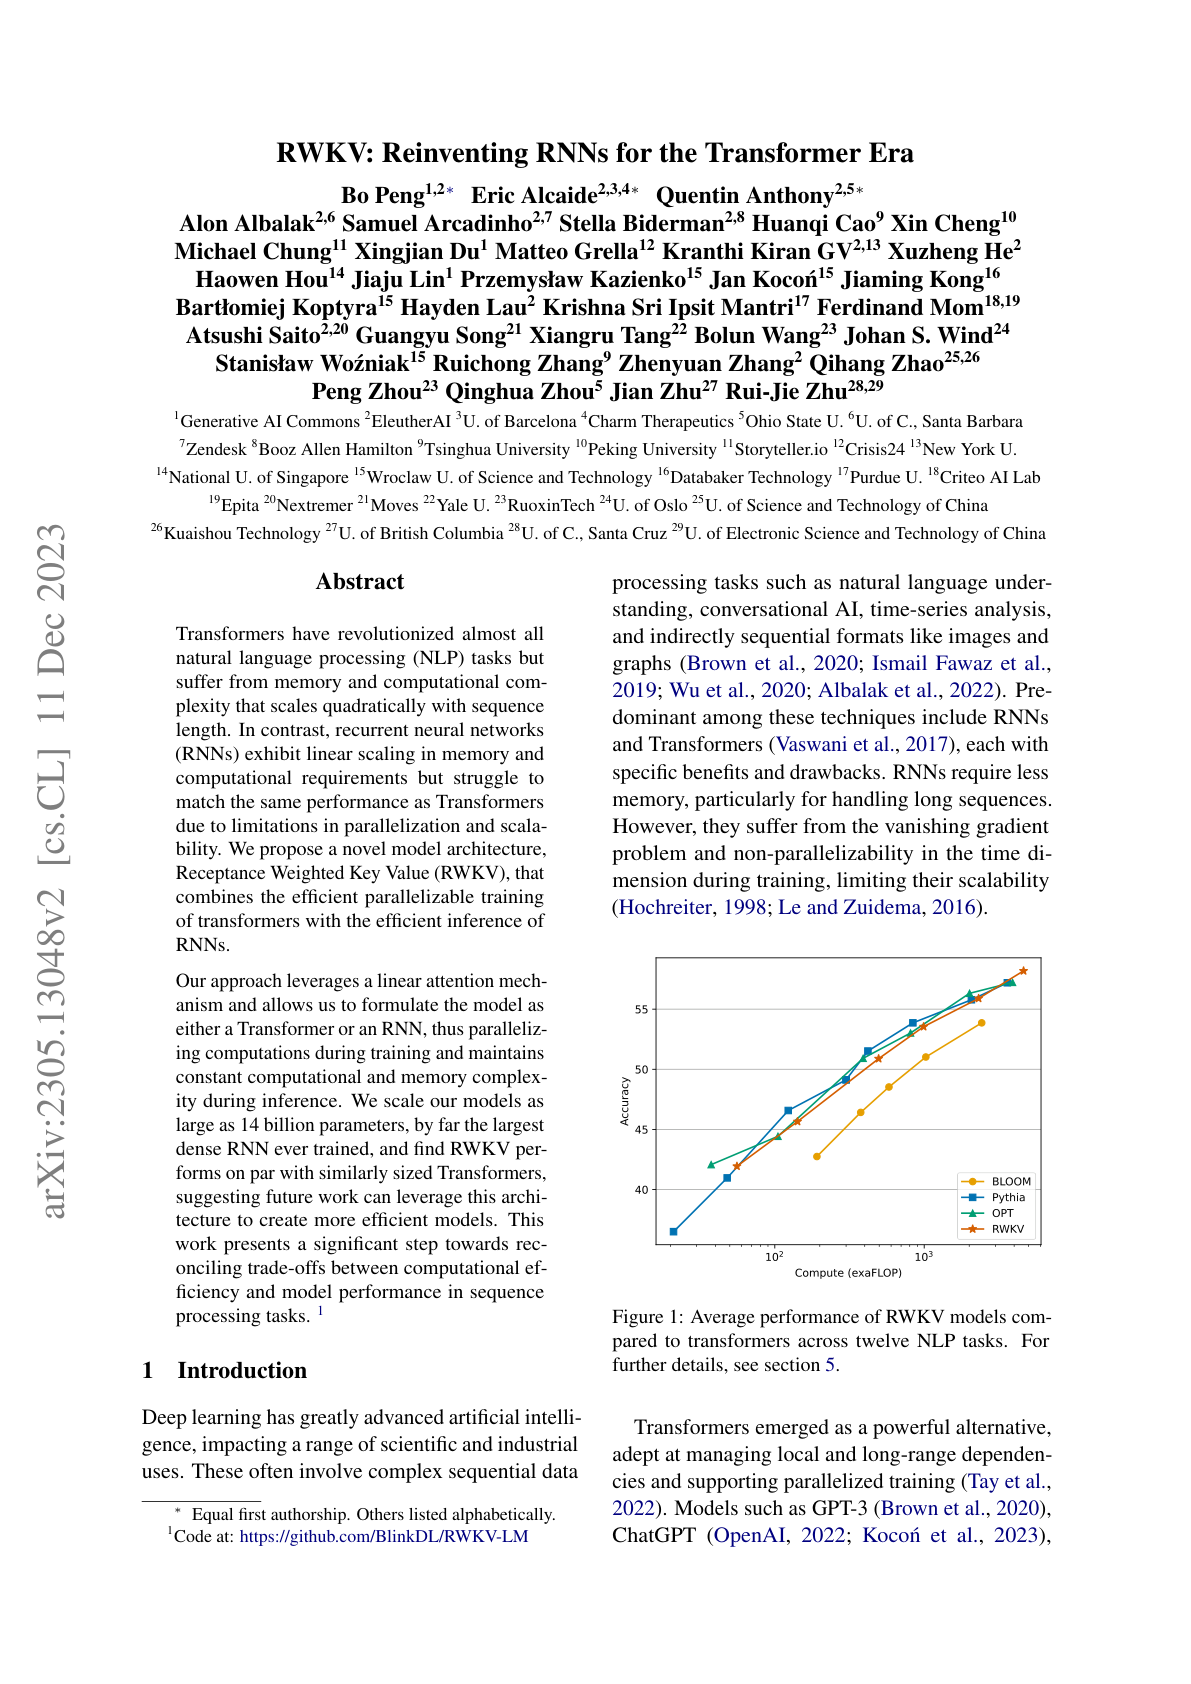
RWKV: Reinventing RNNs for the Transformer Era
Hacker News threads
- May 2023RWKV: Reinventing RNNs for the Transformer Era
- Jul 2023Scaling Transformers to 1B Tokens
- Nov 2023Is anyone using self hosted LLM day to day and training it like a new employee
- Dec 2023Paving the way to efficient architectures: StripedHyena-7B
- Jan 2024Eagle 7B: Soaring past Transformers
- Jan 2024Eagle 7B: Soaring past Transformers
- Feb 2025Ask HN: Is anybody building an alternative transformer?
- 93
Distinct Elements in Streams: An Algorithm for the (Text) Book
Hacker News threads
- May 2024Distinct Elements in Streams: An Algorithm for the (Text) Book∗ [pdf]
- Nov 2023Ask HN: Is Knuth's TAOCP worth the time and effort? (2023)
- May 2024Computer scientists invent an efficient new way to count
- May 2024Computer scientists invent an efficient new way to count
- May 2024Computer scientists invent an efficient new way to count
- May 2024Computer scientists invent an efficient new way to count
- May 2024Computer scientists invent an efficient new way to count
- Feb 2025Undergraduate shows that searches within hash tables can be much faster
- 94
LLaMA: Open and Efficient Foundation Language Models
Hacker News threads
- Mar 2024LLaMA: Open and Efficient Foundation Language Models (2023)
- Mar 2023The Most Cited AI Papers in 2022
- Mar 2023Using LLaMA with M1 Mac and Python 3.11
- Mar 2023The RWKV language model: An RNN with the advantages of a transformer
- Apr 2023The LLama Effect: Leak Sparked a Series of Open Source Alternatives to ChatGPT
- May 2023OpenLLaMA: An Open Reproduction of LLaMA
- Jun 2023OpenLLaMA 13B Released
- Sep 2023Mistral 7B, the most powerful language model for its size to date, Apache 2.0
- Feb 2025Meta torrented & seeded 81.7 TB dataset containing copyrighted data
- 95
The Poison of Alignment
Hacker News threads
- 96
Distilling Step-by-Step! Outperforming Larger Language Models with Less Training Data and Smaller Model Sizes
Hacker News threads
- May 2023Distilling Step-by-Step Outperforming Larger Language Models with Less Training
- May 2023RedPajama (Open LLaMA Replication) 3B and 7B models released
- May 2023PaLM 2 Technical Report [pdf]
- May 2023How to Finetune GPT Like Large Language Models on a Custom Dataset
- Jul 2023
- Dec 2023Phi-2: The surprising power of small language models
- Jan 2025Nvidia’s $589B DeepSeek rout
- 97
Text Embeddings Reveal (Almost) As Much As Text
Hacker News threads
- Oct 2023Text Embeddings Reveal (Almost) as Much as Text
- Nov 2023Show HN: Phind Model beats GPT-4 at coding, with GPT-3.5 speed and 16k context
- Dec 2023Embeddings, Vectors, and Arithmetic
- Mar 2024Launch HN: Greptile (YC W24) - RAG on codebases that actually works
- Jun 2024CryptGPT: A Simple Approach to Privacy-Preserving LLMs Using Vigenere Cipher
- Jul 2024Vision language models are blind
- Jan 2025Let's talk about AI and end-to-end encryption
- 98
Emergent Linear Representations in World Models of Self-Supervised Sequence Models
Hacker News threads
- 99
What Algorithms can Transformers Learn? A Study in Length Generalization
Hacker News threads
- 100
The Curse of Recursion: Training on Generated Data Makes Models Forget
Hacker News threads
- Dec 2024The Curse of Recursion: Training on generated data makes models forget (2023)
- Jun 2023The Curse of Recursion: Training on Generated Data Makes Models Forget
- Jun 2023The Curse of Recursion: Training on Generated Data Makes Models Forget
- Jun 2023Two US lawyers fined for submitting fake court citations from ChatGPT
- Jun 2023The Darwinian argument for worrying about AI
- Jul 2023LLaMA2 isn't “Open Source” – and why it doesn't matter
- Nov 2023Using GPT-4 Vision with Vimium to browse the web
- Jan 2024The Internet Is Full of AI Dogshit
- Feb 2024Generative AI Degrades Online Communities
- Apr 2024Tell HN: We should snapshot a mostly AI output free version of the web
- Jun 2024Gemma 2: Improving Open Language Models at a Practical Size [pdf]
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.