Hacker Papers
- 101
Studying Large Language Model Generalization with Influence Functions
Hacker News threads
- 102
The Grand Illusion: The Myth of Software Portability and Implications for ML Progress
Hacker News threads
- Mar 2024The Myth of Software Portability and Implications for ML Progress (2023)
- Sep 2023The Myth of Software Portability and Implications for ML Progress
- Oct 2023SiFive Rolls Out RISC-V Cores Aimed at Generative AI and ML
- Jan 2024Google TPU v5p beats Nvidia H100
- Sep 2024Show HN: Tune LLaMa3.1 on Google Cloud TPUs
- Sep 2024We fine-tuned Llama 405B on AMD GPUs
- 103
The Impact of Positional Encoding on Length Generalization in Transformers
Hacker News threads
- Jun 2023The Impact of Positional Encoding on Length Generalization in Transformers
- Aug 2024The Impact of Positional Encoding on Length Generalization in Transformers
- Apr 2025The Llama 4 herd
- Apr 2025Llama 4 Now Live on Groq
- Jul 2025LLM Embeddings Explained: A Visual and Intuitive Guide
- Oct 2026Is 'Attention' the Essence of Intelligence?
- 104
Double Descent Demystified: Identifying, Interpreting & Ablating the Sources of a Deep Learning Puzzle
Hacker News threads
- 105
MusicLM: Generating Music From Text
Hacker News threads
- 106
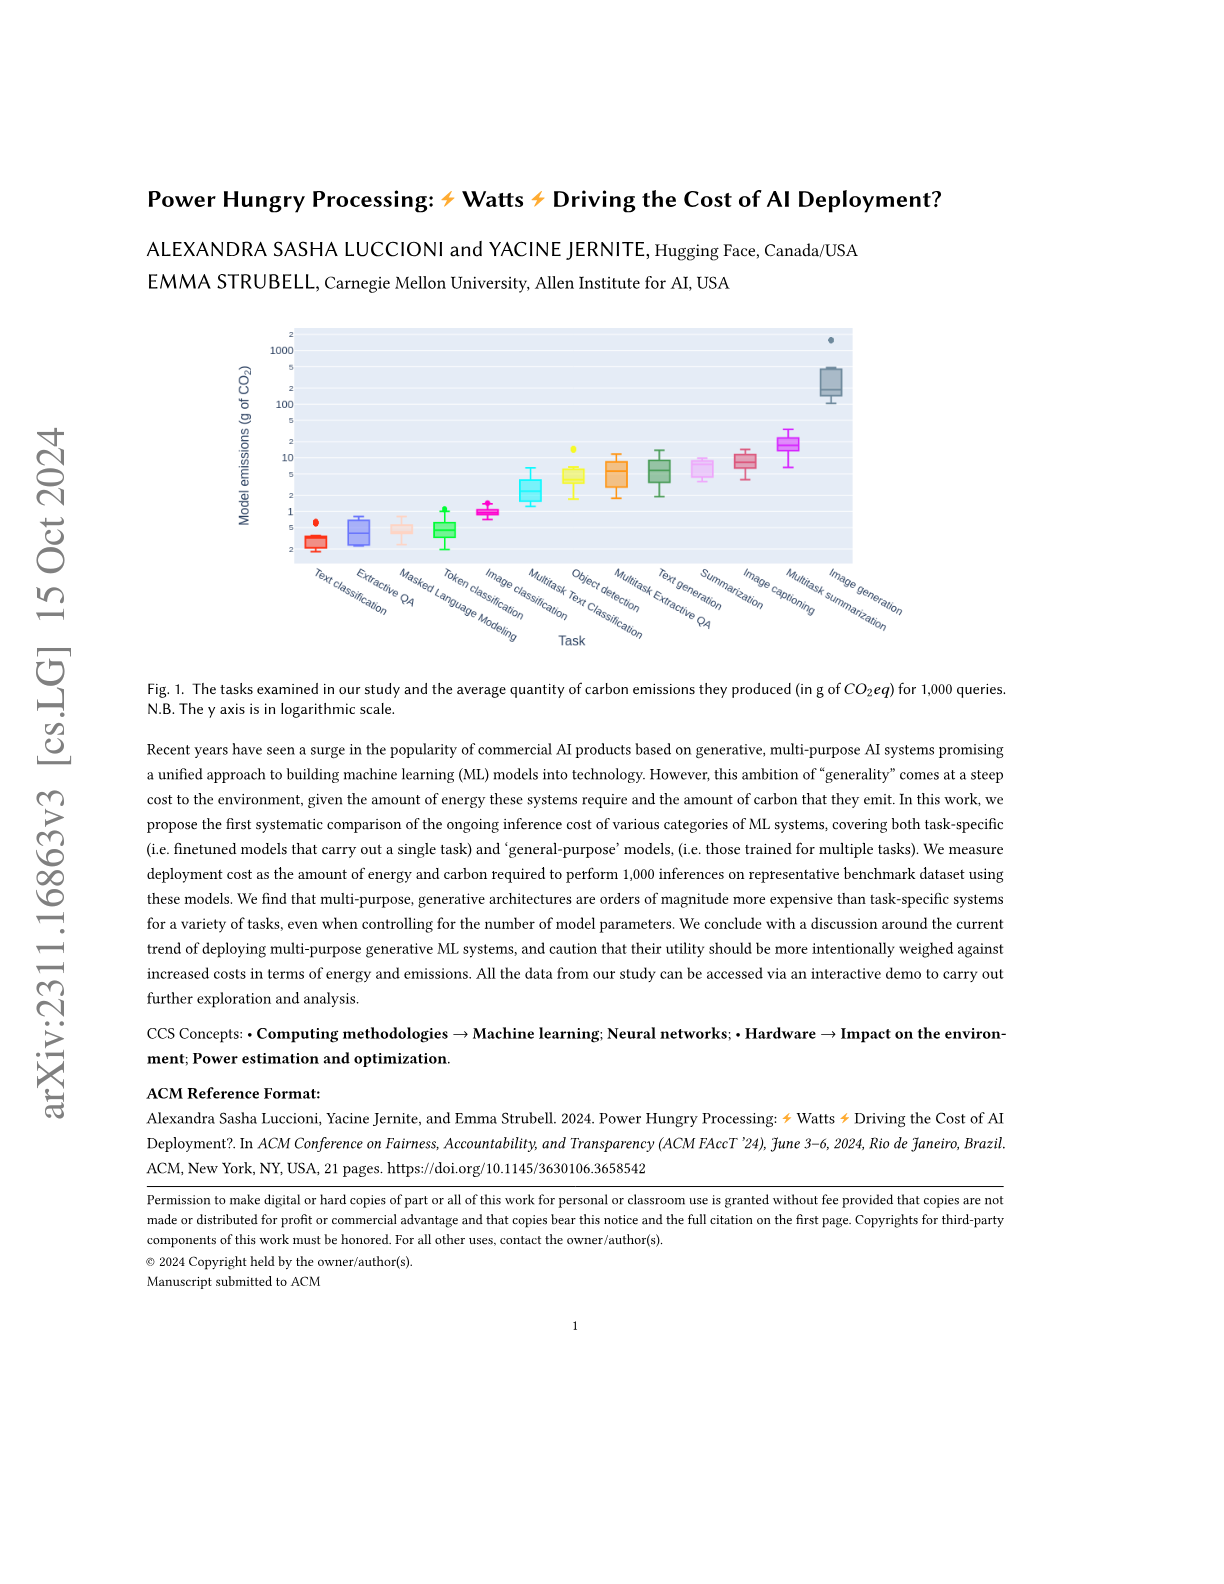
Power Hungry Processing: Watts Driving the Cost of AI Deployment?
Hacker News threads
- 107
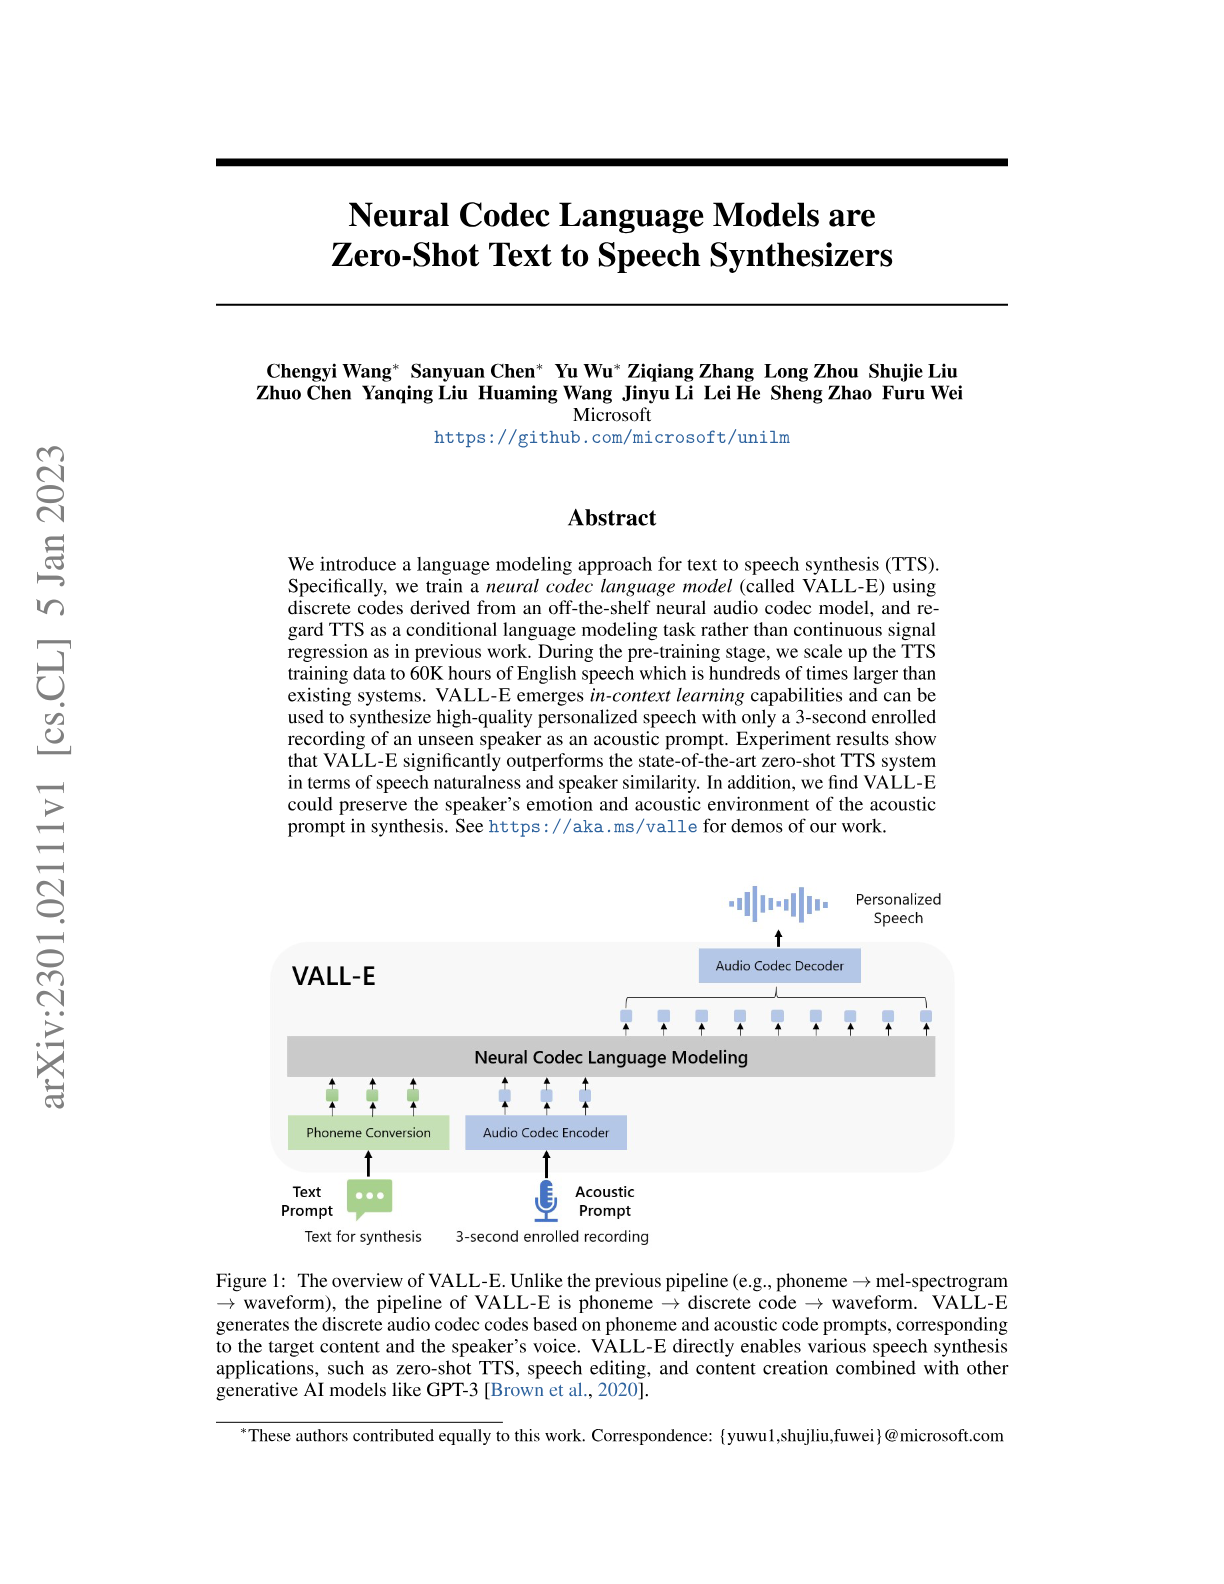
Neural Codec Language Models are Zero-Shot Text to Speech Synthesizers
Hacker News threads
- 108
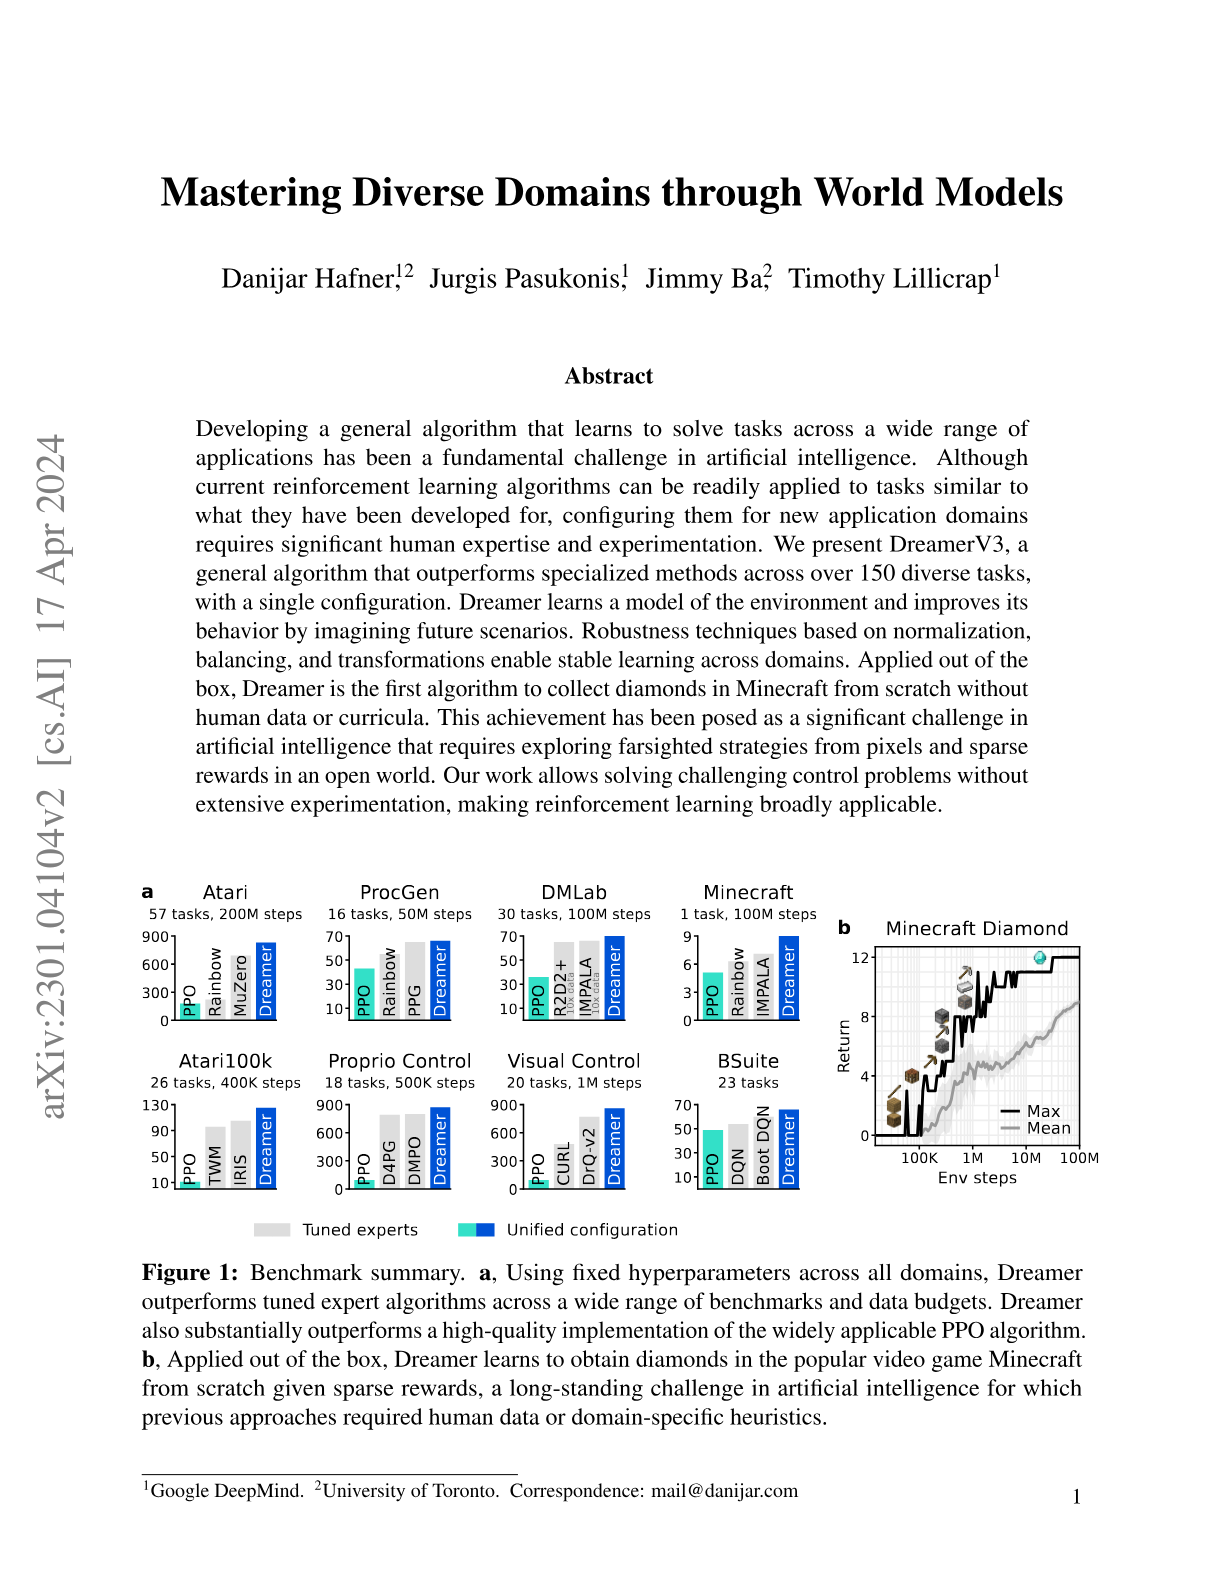
Mastering Diverse Domains through World Models
Hacker News threads
- 109
How Language Model Hallucinations Can Snowball
Hacker News threads
- 110
SpQR: A Sparse-Quantized Representation for Near-Lossless LLM Weight Compression
Hacker News threads
- 111
Scaling Laws for Generative Mixed-Modal Language Models
Hacker News threads
- 112
Visual Instruction Tuning
Hacker News threads
- 113
Simple and Controllable Music Generation
Hacker News threads
- 114
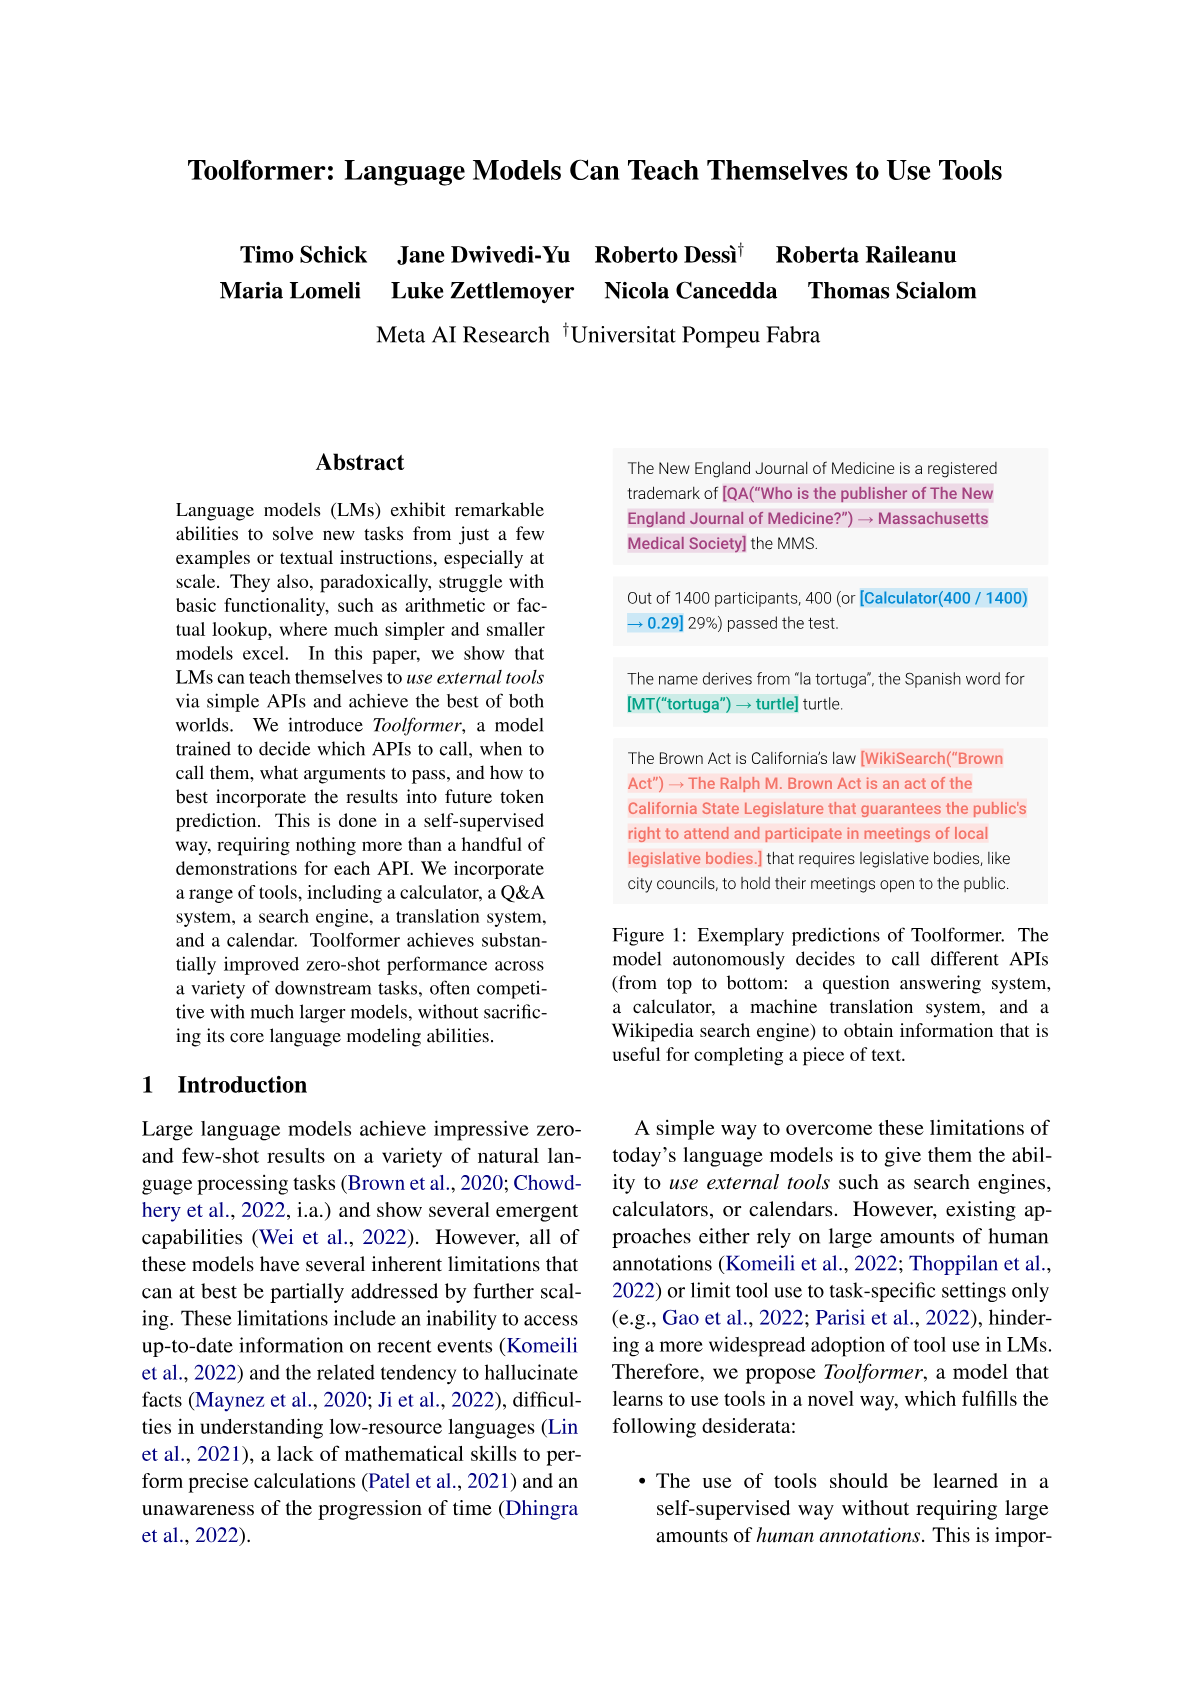
Toolformer: Language Models Can Teach Themselves to Use Tools
Hacker News threads
- Feb 2023Toolformer: Language Models Can Teach Themselves to Use Tools
- Feb 2023Toolformer: Language Models Can Teach Themselves to Use Tools
- Feb 2023Toolformer: Language models can teach themselves to use tools
- Feb 2023A new way to build with Large Language Models
- Feb 2023Our Society Is Not Prepared for This Much AI Awesome
- Feb 2023ChatGPT is falsely recommending us for a service we don't provide
- Mar 2023ChatGPT Explained: A Normie's Guide to How It Works
- Mar 2023ViperGPT: A Python Framework That Combines Vision and Language Models Using Code
- Mar 2023ChatGPT Outperforms Crowd-Workers for Text-Annotation Tasks
- May 2023AI knows things no one told it
- Nov 2023Sam Altman's ouster was precipitated by letter to board about AI breakthrough
- 115
Dissociating language and thought in large language models
Hacker News threads
- Sep 2024Dissociating language and thought in large language models
- Jan 2023Dissociating language and thought in LLMs: a cognitive perspective
- Feb 2023Dissociating language, thought in large language models: a cognitive perspective
- Feb 2023I had ChatGPT write a Decemberists song
- Feb 2023Theory of Mind May Have Spontaneously Emerged in Large Language Models (2021)
- Apr 2023Why ChatGPT and Bing Chat are so good at making things up
- May 2023Geoffrey Hinton leaves Google and can now speak freely about his AI concern
- Jul 2023A Latent Space Theory for Emergent Abilities in Large Language Models
- Oct 2023Ask HN: Why are current LLMs not considered AGI?
- 116
Evaluating Large Language Models in Theory of Mind Tasks
Hacker News threads
- Feb 2023Theory of Mind May Have Spontaneously Emerged in Large Language Models
- Feb 2023I had ChatGPT write a Decemberists song
- Feb 2023I had ChatGPT write a Decemberists song
- Feb 2023Bing: “I will not harm you unless you harm me first”
- Feb 2023Researchers Discover a More Flexible Approach to Machine Learning
- Feb 2023ChatGPT is falsely recommending us for a service we don't provide
- Mar 2023Microsoft's paper on OpenAI's GPT-4 had hidden information
- Apr 2023AI won't steal your job, people leveraging AI will
- May 2023This time, it feels different
- 117
Discrete Diffusion Modeling by Estimating the Ratios of the Data Distribution
Hacker News threads
- Feb 2025I think Yann Lecun was right about LLMs (but perhaps only by accident)
- Feb 2025Mercury Coder: frontier diffusion LLM generating 1000+ tok/sec on commodity GPUs
- Mar 2025First large diffusion-based LLM
- Mar 2025Ask HN: Any insider takes on Yann LeCun's push against current architectures?
- May 2025Mercury: Commercial-scale diffusion language model
- May 2025Mercury: Commercial-scale diffusion language model
- Jul 2025Mercury: Ultra-fast language models based on diffusion
- 118
Gorilla: Large Language Model Connected with Massive APIs
Hacker News threads
- May 2023Gorilla: Large Language Model Connected with APIs
- Jun 2023Gorilla: Large Language Model Connected with APIs
- May 2023Gorilla: LLM Connected with APIs
- Jun 2023Falcon 40B LLM (which beats Llama) now Apache 2.0
- Jun 2023OpenAI Cybersecurity Grant Program
- Jun 2023RedPajama 7B (an Apache 2.0-licensed LLaMa) is now available
- Jun 2023OpenLLaMA 13B Released
- Aug 2023Show HN: Poozle – open-source Plaid for LLMs
- Sep 2023RestGPT
- 119
Large Language Model Guided Tree-of-Thought
Hacker News threads
- 120
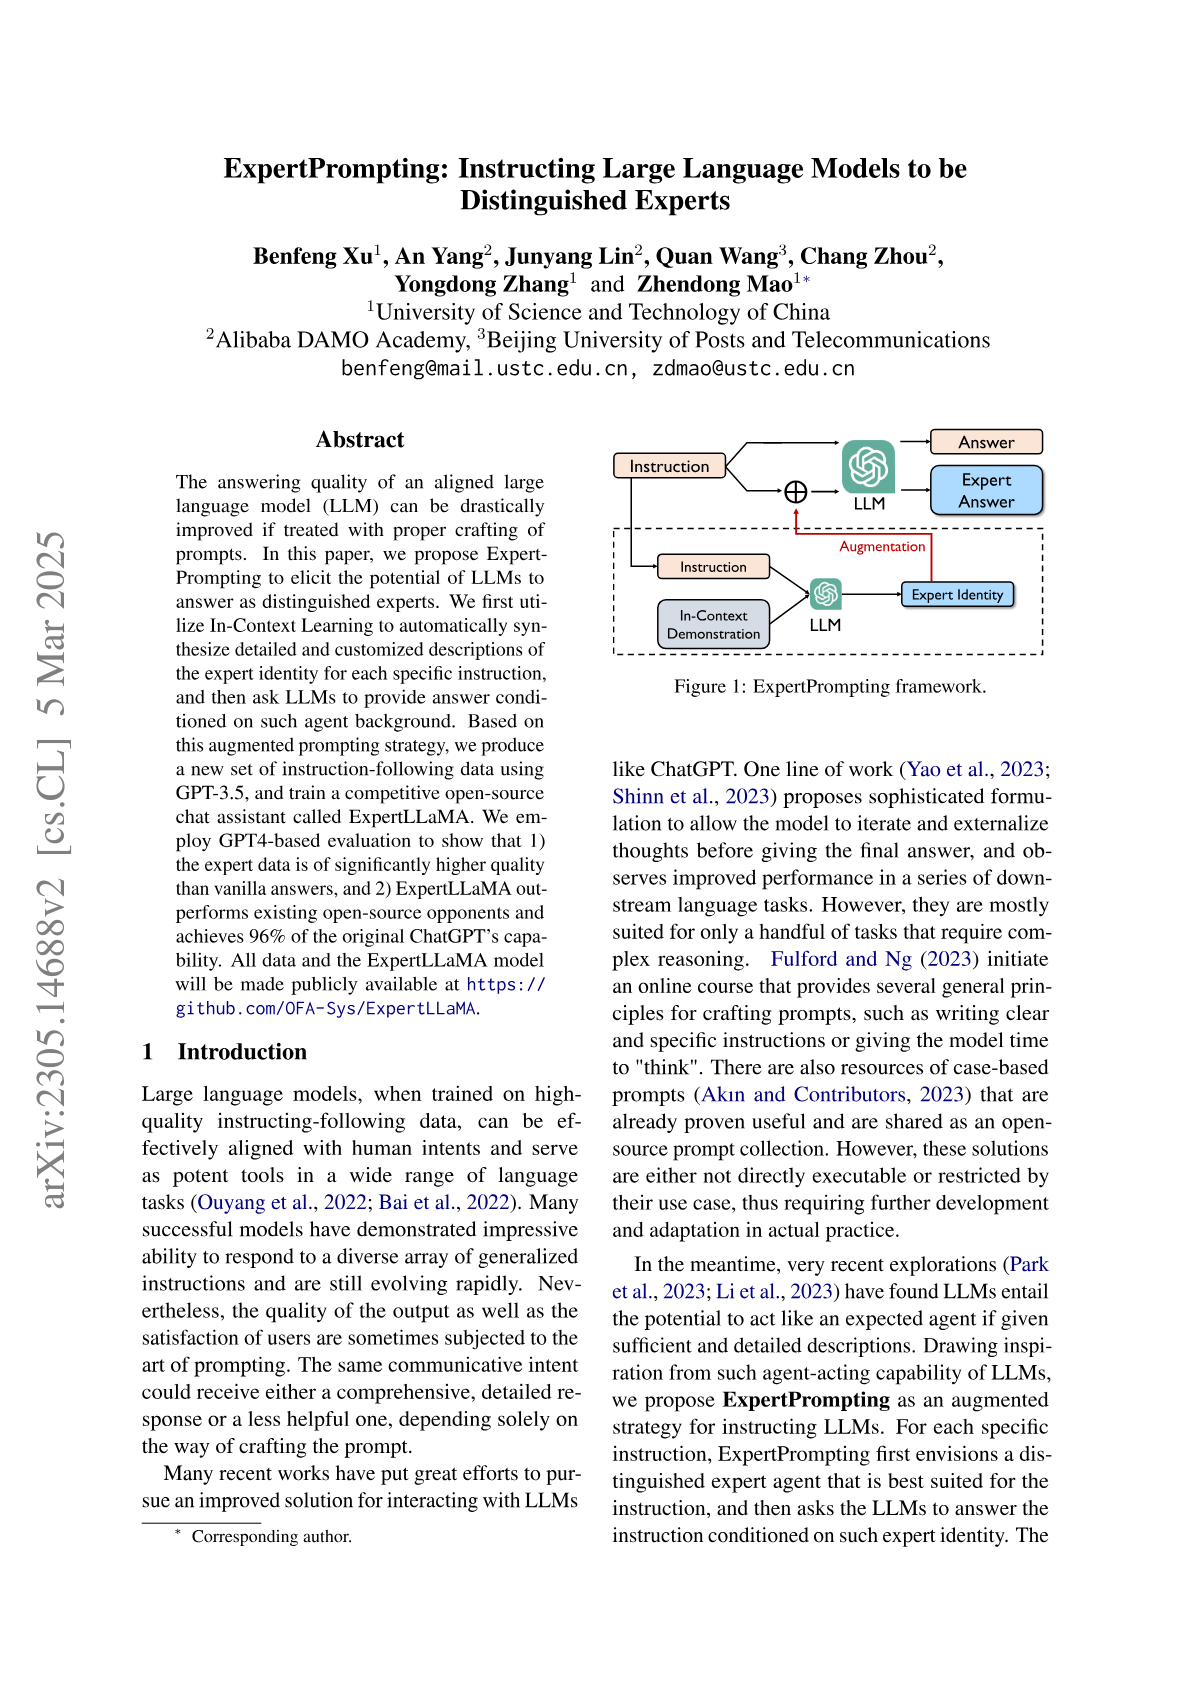
ExpertPrompting: Instructing Large Language Models to be Distinguished Experts
Hacker News threads
- 121
Sophia: A Scalable Stochastic Second-order Optimizer for Language Model Pre-training
Hacker News threads
- Apr 2024Sophia: Scalable Stochastic 2nd-Order Optimizer for Language Model Pre-Training
- May 2023Sophia: A Scalable Stochastic Second-Order Optimizer
- Jul 2023Sophia: A Scalable Stochastic Optimizer for Language Model Pre-Training
- May 2023MITx Differential Equations starts May 31
- Jun 2023Notes on training BERT from scratch on an 8GB consumer GPU
- Jun 2023Notes on training BERT from scratch on an 8GB consumer GPU
- Aug 2023Risky Giant Steps Can Solve Optimization Problems Faster
- 122
BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models
Hacker News threads
- Jan 2023Blip-2
- Mar 2023Zero-1-to-3: Zero-shot One Image to 3D Object
- Apr 2023MiniGPT-4
- Apr 2023MiniGPT-4
- May 2023MaMMUT: A simple vision-encoder text-decoder architecture for multimodal tasks
- 123
What Algorithms can Transformers Learn? A Study in Length Generalization
Hacker News threads
- 124
Tracr: Compiled Transformers as a Laboratory for Interpretability
Hacker News threads
- 125
Emergent Linear Representations in World Models of Self-Supervised Sequence Models
Hacker News threads
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.