Hacker Papers
- 101
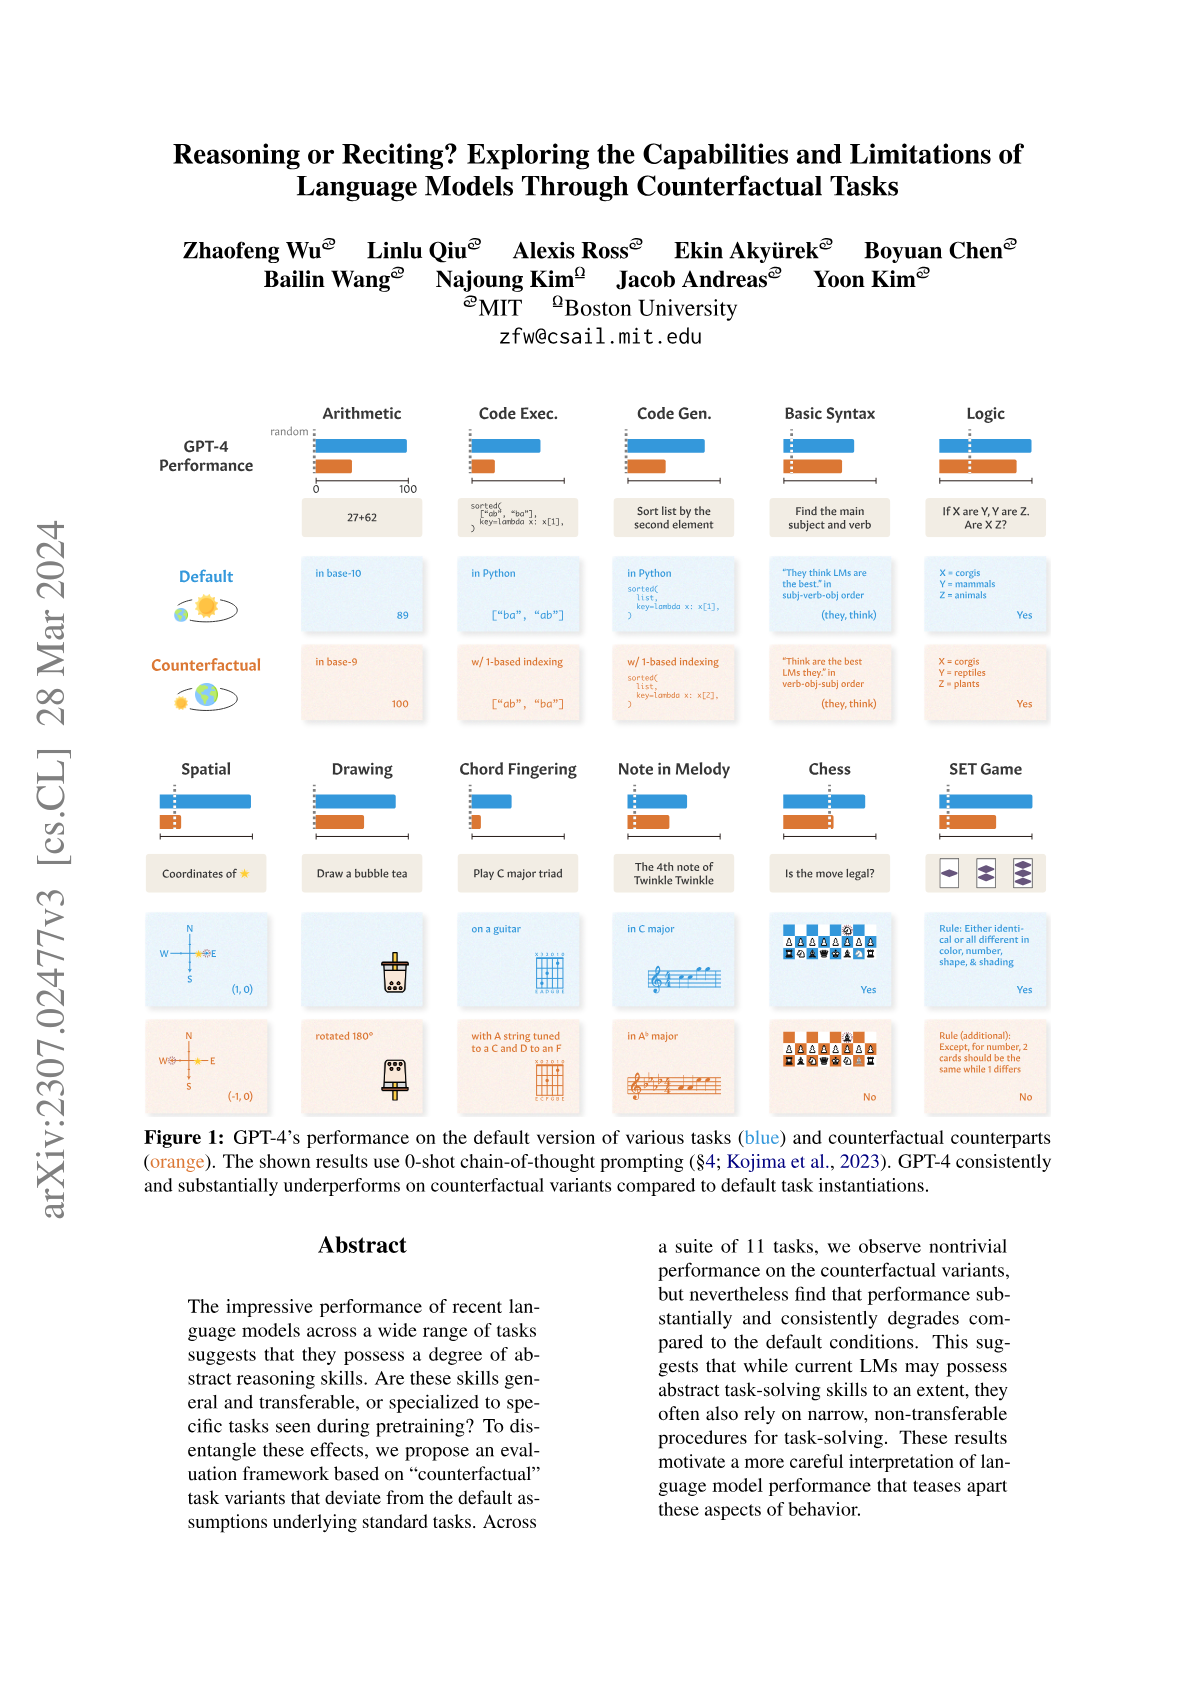
Reasoning or Reciting? Exploring the Capabilities and Limitations of Language Models Through Counterfactual Tasks
Hacker News threads
- Sep 2023Exploring Capabilities, Limitations of Language Models by Counterfactual Tasks
- Jul 2023AI Safety and the Age of Dislightenment
- Dec 2023Will scaling work?
- Jun 2024The illusion of state in state-space models
- Jul 2024Tabloid: A clickbait headline programming language (2021)
- Aug 2024Markov chains are funnier than LLMs
- Aug 2024Markov chains are funnier than LLMs
- Nov 2024DeepThought-8B: A small, capable reasoning model
- 102
xVal: A Continuous Numerical Tokenization for Scientific Language Models
Hacker News threads
- Oct 2023Single Digit Tokenization improves LLM Math abilities by up to 70x
- Oct 2023Single Digit tokenization improves LLM math abilities by up to 70x
- Nov 2023Telling GPT-4 you're scared or under pressure improves performance
- Nov 2023Sutskever: OpenAI board doing its mission to build AGI that benefits all
- Nov 2023Sam Altman's ouster was precipitated by letter to board about AI breakthrough
- Nov 2023Sam Altman's ouster was precipitated by letter to board about AI breakthrough
- Mar 2024Integer Tokenization Is Insane (2023)
- Sep 2024AGI is far from inevitable
- Oct 2024Probably pay attention to tokenizers
- 103
LIMA: Less Is More for Alignment
Hacker News threads
- May 2023LIMA: Less Is More for Alignment
- May 2023LIMA: Less Is More for Alignment
- May 2023GPT detectors are biased against non-native English writers
- May 2023How to Finetune GPT Like Large Language Models on a Custom Dataset
- Jun 2023Falcon 40B LLM (which beats Llama) now Apache 2.0
- Jun 2023AI has poisoned its own well
- Sep 2023Large Language Models for Compiler Optimization
- Sep 2023Outperforming LLMs with less training data and smaller model sizes
- Apr 2024Ask HN: Most efficient way to fine-tune an LLM in 2024?
- Oct 2024Zamba2-7B
- 104
Reflexion: Language Agents with Verbal Reinforcement Learning
Hacker News threads
- Mar 2023Reflexion: An autonomous agent with dynamic memory and self-reflection
- Mar 2023Reflexion: An autonomous agent with dynamic memory and self-reflection
- Mar 2023Reflexion: An autonomous agent with dynamic memory and self-reflection
- Mar 2023GPT-4 performs significantly worse on coding problems not in its training data
- Mar 2023ChatGPT and Code Interpreter = Magic
- Apr 2023HuggingGPT: Solving AI Tasks with ChatGPT and Its Friends in HuggingFace
- Apr 2023Defamed by ChatGPT: Law professor libeled from whole cloth
- Apr 2023Large Language Models: Scaling Laws and Emergent Properties
- Jul 2023Langchain Is Pointless
- Aug 2023Maccarone: AI-managed code blocks in Python
- Oct 2024Update on Reflection-70B
- 105
The Grand Illusion: The Myth of Software Portability and Implications for ML Progress
Hacker News threads
- Mar 2024The Myth of Software Portability and Implications for ML Progress (2023)
- Sep 2023The Myth of Software Portability and Implications for ML Progress
- Oct 2023SiFive Rolls Out RISC-V Cores Aimed at Generative AI and ML
- Jan 2024Google TPU v5p beats Nvidia H100
- Sep 2024Show HN: Tune LLaMa3.1 on Google Cloud TPUs
- Sep 2024We fine-tuned Llama 405B on AMD GPUs
- 106
Dissociating language and thought in large language models
Hacker News threads
- Sep 2024Dissociating language and thought in large language models
- Jan 2023Dissociating language and thought in LLMs: a cognitive perspective
- Feb 2023Dissociating language, thought in large language models: a cognitive perspective
- Feb 2023I had ChatGPT write a Decemberists song
- Feb 2023Theory of Mind May Have Spontaneously Emerged in Large Language Models (2021)
- Apr 2023Why ChatGPT and Bing Chat are so good at making things up
- May 2023Geoffrey Hinton leaves Google and can now speak freely about his AI concern
- Jul 2023A Latent Space Theory for Emergent Abilities in Large Language Models
- Oct 2023Ask HN: Why are current LLMs not considered AGI?
- 107
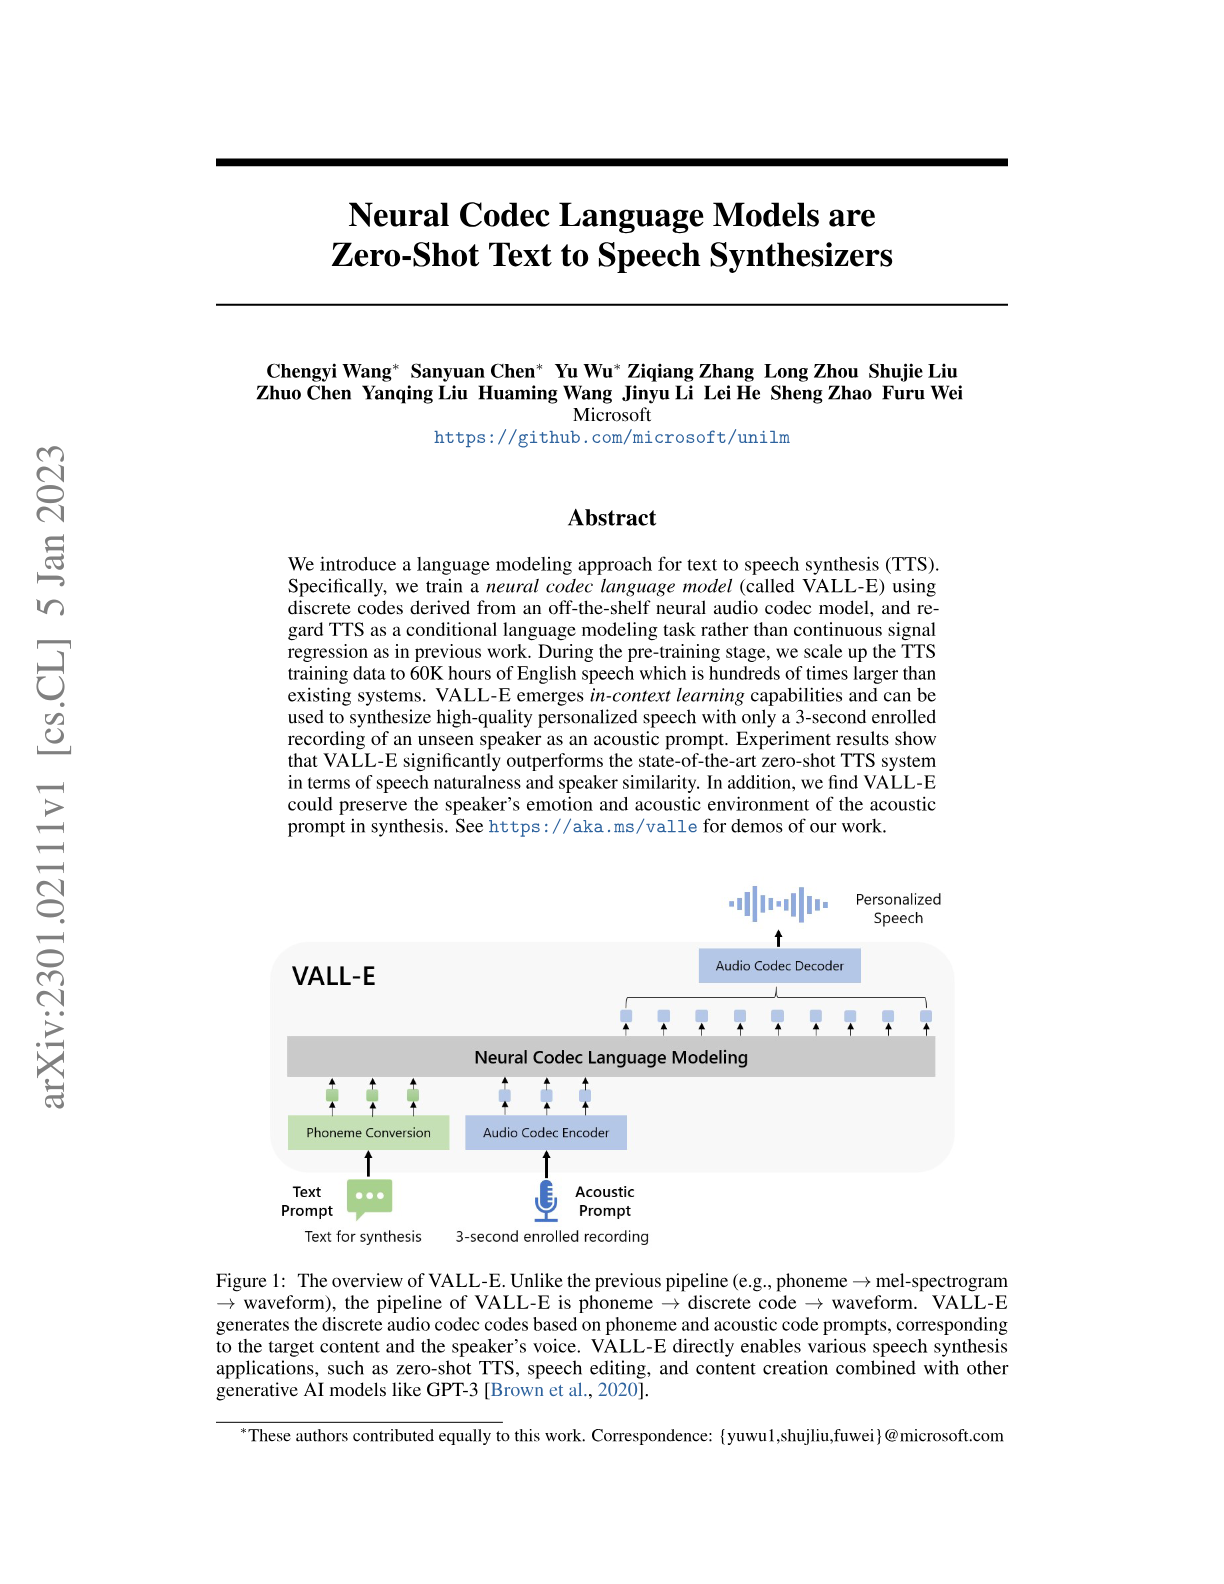
Neural Codec Language Models are Zero-Shot Text to Speech Synthesizers
Hacker News threads
- 108
Mathematical Capabilities of ChatGPT
Hacker News threads
- Feb 2023Mathematical Capabilities of ChatGPT
- Mar 2023Ask HN: Who wants to be hired? (March 2023)
- Apr 2023Ask HN: Who wants to be hired? (April 2023)
- Apr 2023
- Jun 2023MIT Responds to “ Exploring the MIT Mathematics and EECS Curriculum Using LLMs” [pdf]
- Oct 2023AI is replacing customer service jobs across the globe
- Oct 2023GPT-4 Understands
- Jun 2024Terence Tao on proof checkers and AI programs
- 109
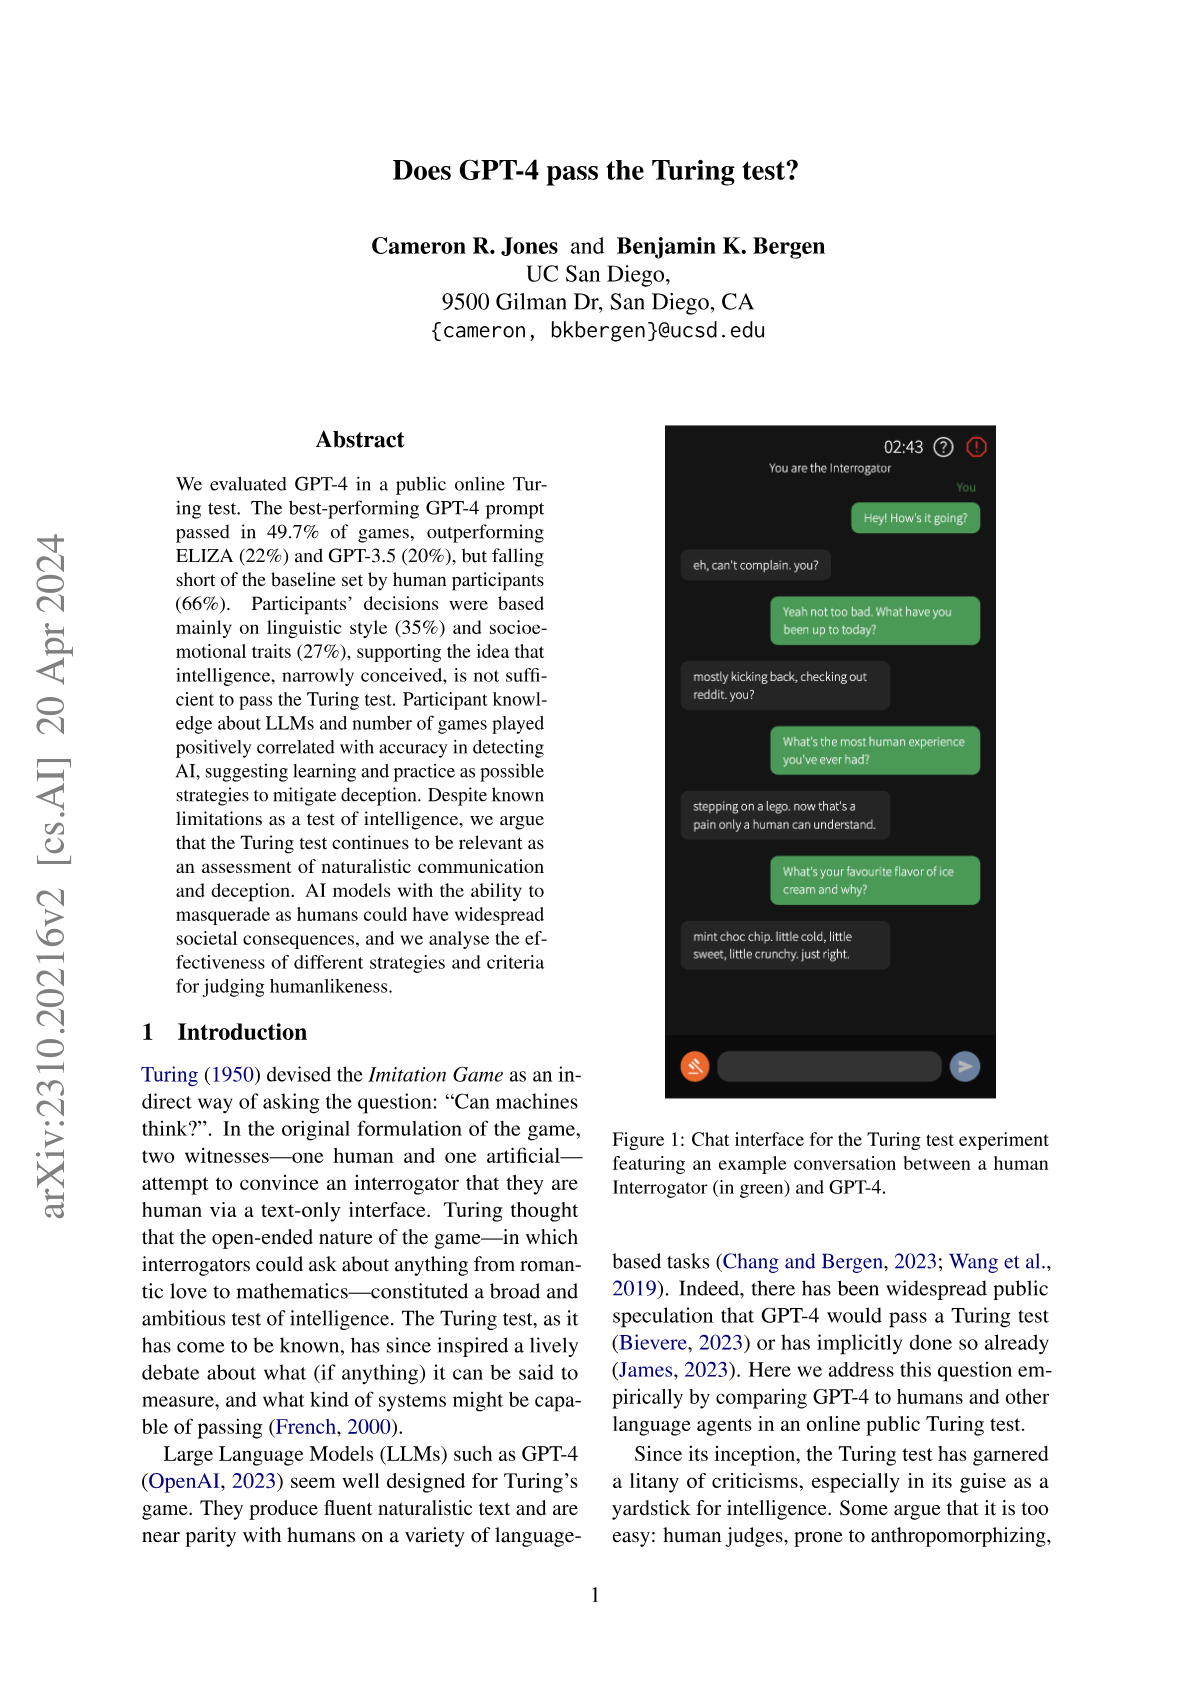
Does GPT-4 pass the Turing test?
Hacker News threads
- Nov 2023Does GPT-4 Pass the Turing Test?
- Nov 2023Does GPT-4 Pass the Turing Test?
- Nov 2023OpenAI Announces Leadership Transition
- Dec 20231960s chatbot ELIZA beat OpenAI's GPT-3.5 in a recent Turing test study
- Jan 2024Stuff we figured out about AI in 2023
- Jan 2024AI or Ain't: Eliza
- Jun 2024AI Hype is completely out of control – especially since ChatGPT-4o [video]
- 110
Visual Instruction Tuning
Hacker News threads
- 111
SparseGPT: Massive Language Models Can Be Accurately Pruned in One-Shot
Hacker News threads
- May 2023SparseGPT: Language Models Can Be Accurately Pruned in One-Shot
- Jan 2023Some Remarks on Large Language Models – Yoav Goldberg
- Mar 2023Neural Chip Plays Doom Using a Thousandth of a Watt
- Apr 2023Stability AI Launches the First of Its StableLM Suite of Language Models
- Apr 2023GitHub Copilot emits GPL code
- May 2023How to run Llama 13B with a 6GB graphics card
- May 2023OpenAI chief goes before US Congress to propose licenses for building AI
- Apr 2024Show HN: Speeding up LLM inference 2x times (possibly)
- 112
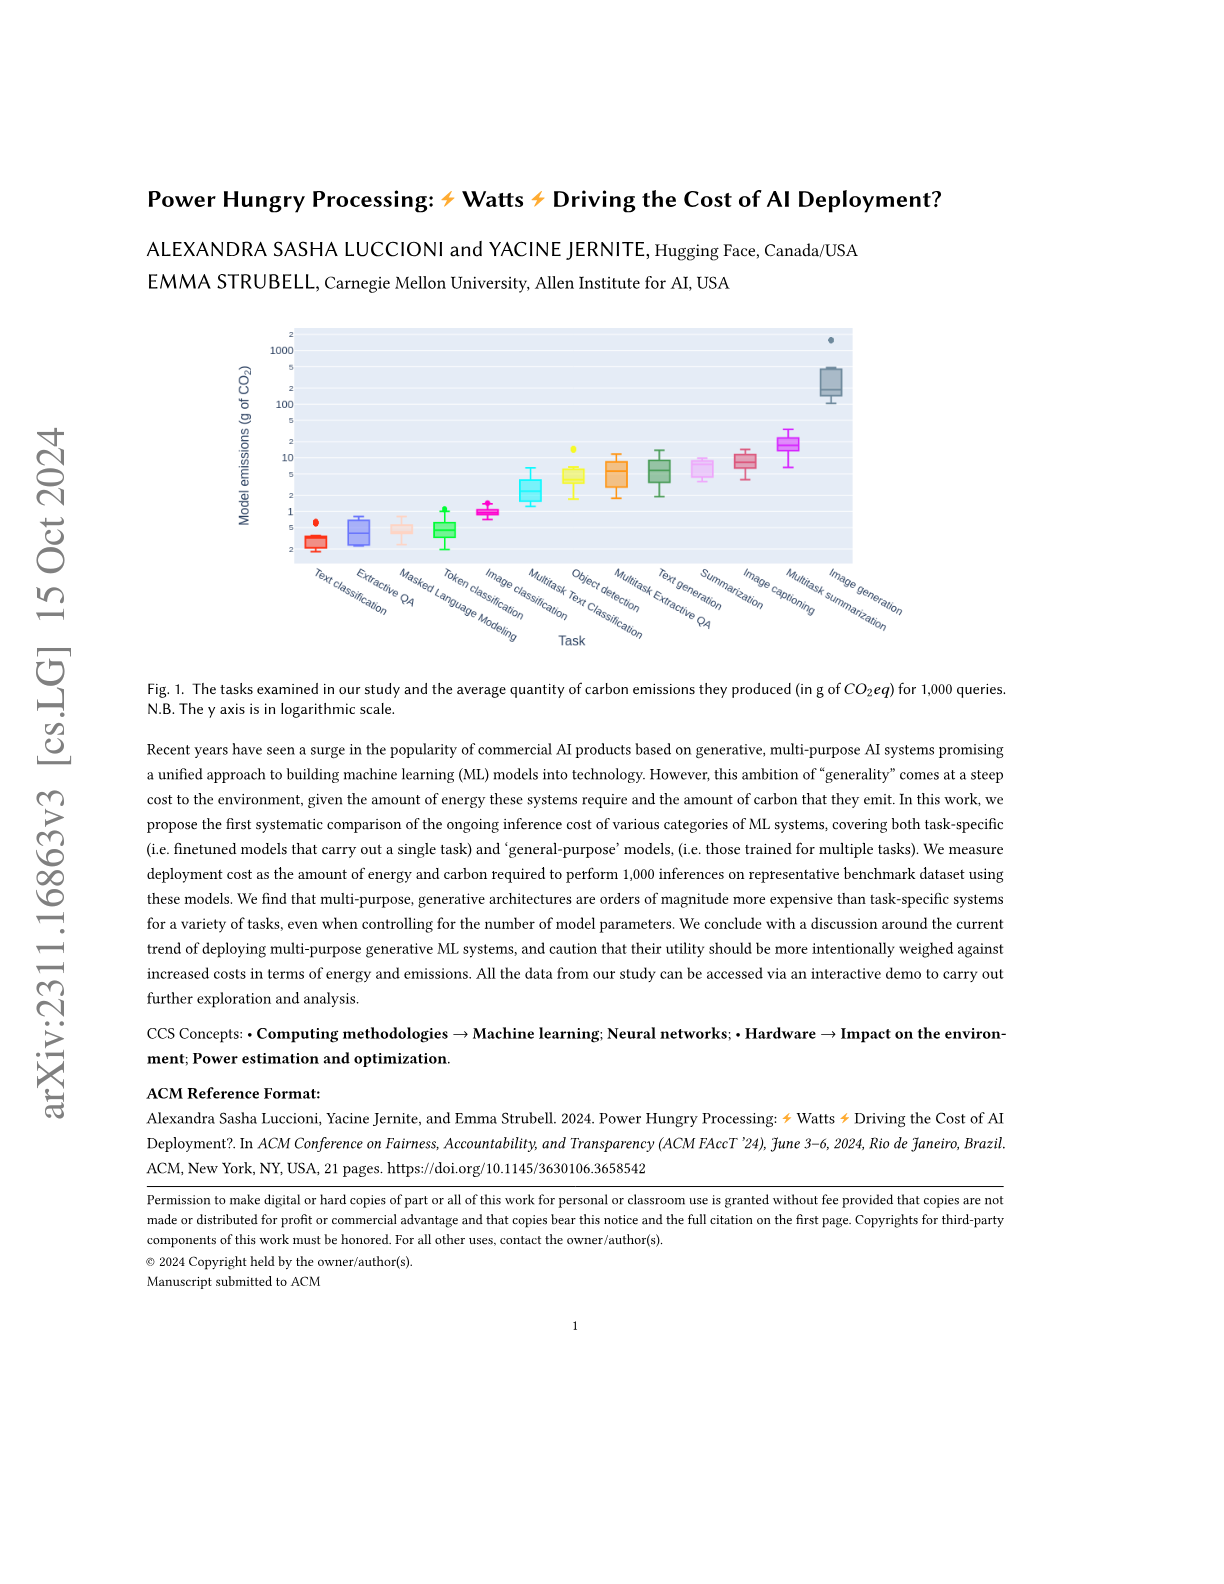
Power Hungry Processing: Watts Driving the Cost of AI Deployment?
Hacker News threads
- 113
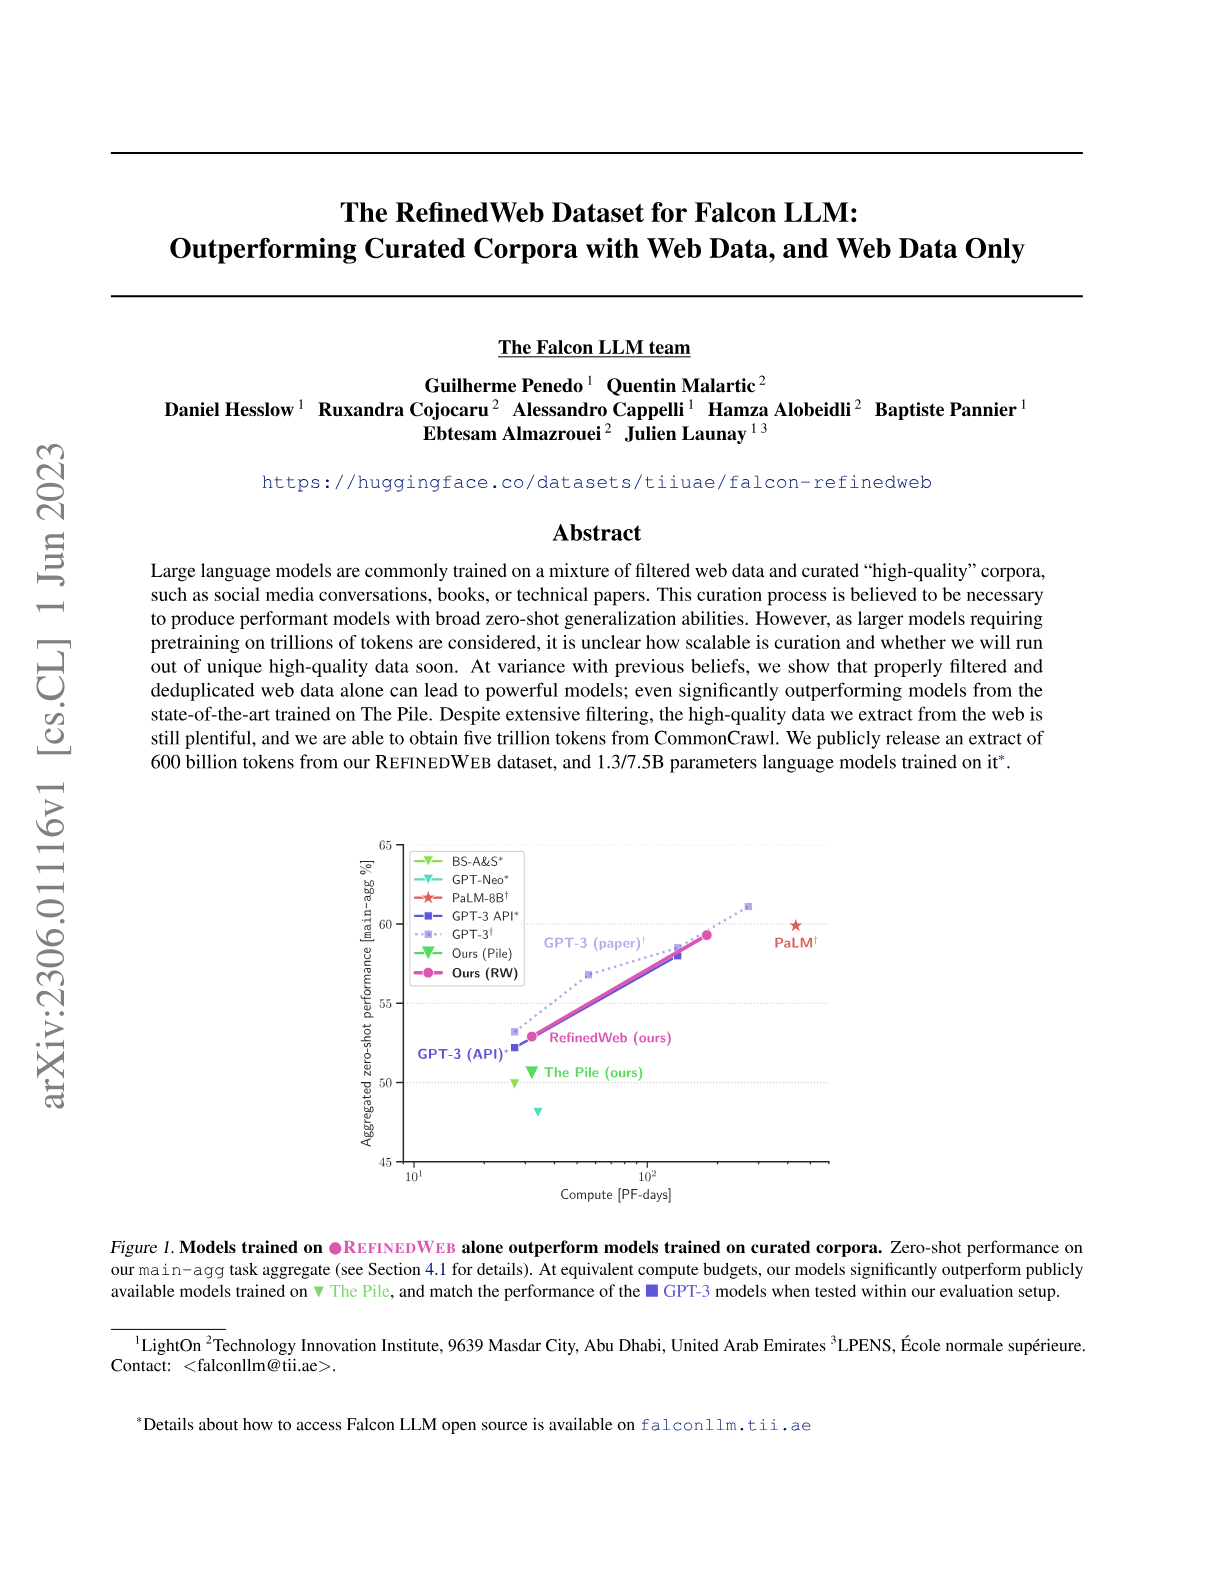
The RefinedWeb Dataset for Falcon LLM: Outperforming Curated Corpora with Web Data, and Web Data Only
Hacker News threads
- 114
An aperiodic monotile
Hacker News threads
- Mar 2023An Aperiodic Monotile
- Mar 2023Mathematicians discover shape that can tile a wall and never repeat
- Oct 2023Hexagonal Grids
- Nov 2023A Brief History of Tricky Mathematical Tiling
- Dec 2023What can you do with an Einstein?
- Feb 2024
- Mar 2024How to Start Google
- 115
SpQR: A Sparse-Quantized Representation for Near-Lossless LLM Weight Compression
Hacker News threads
- 116
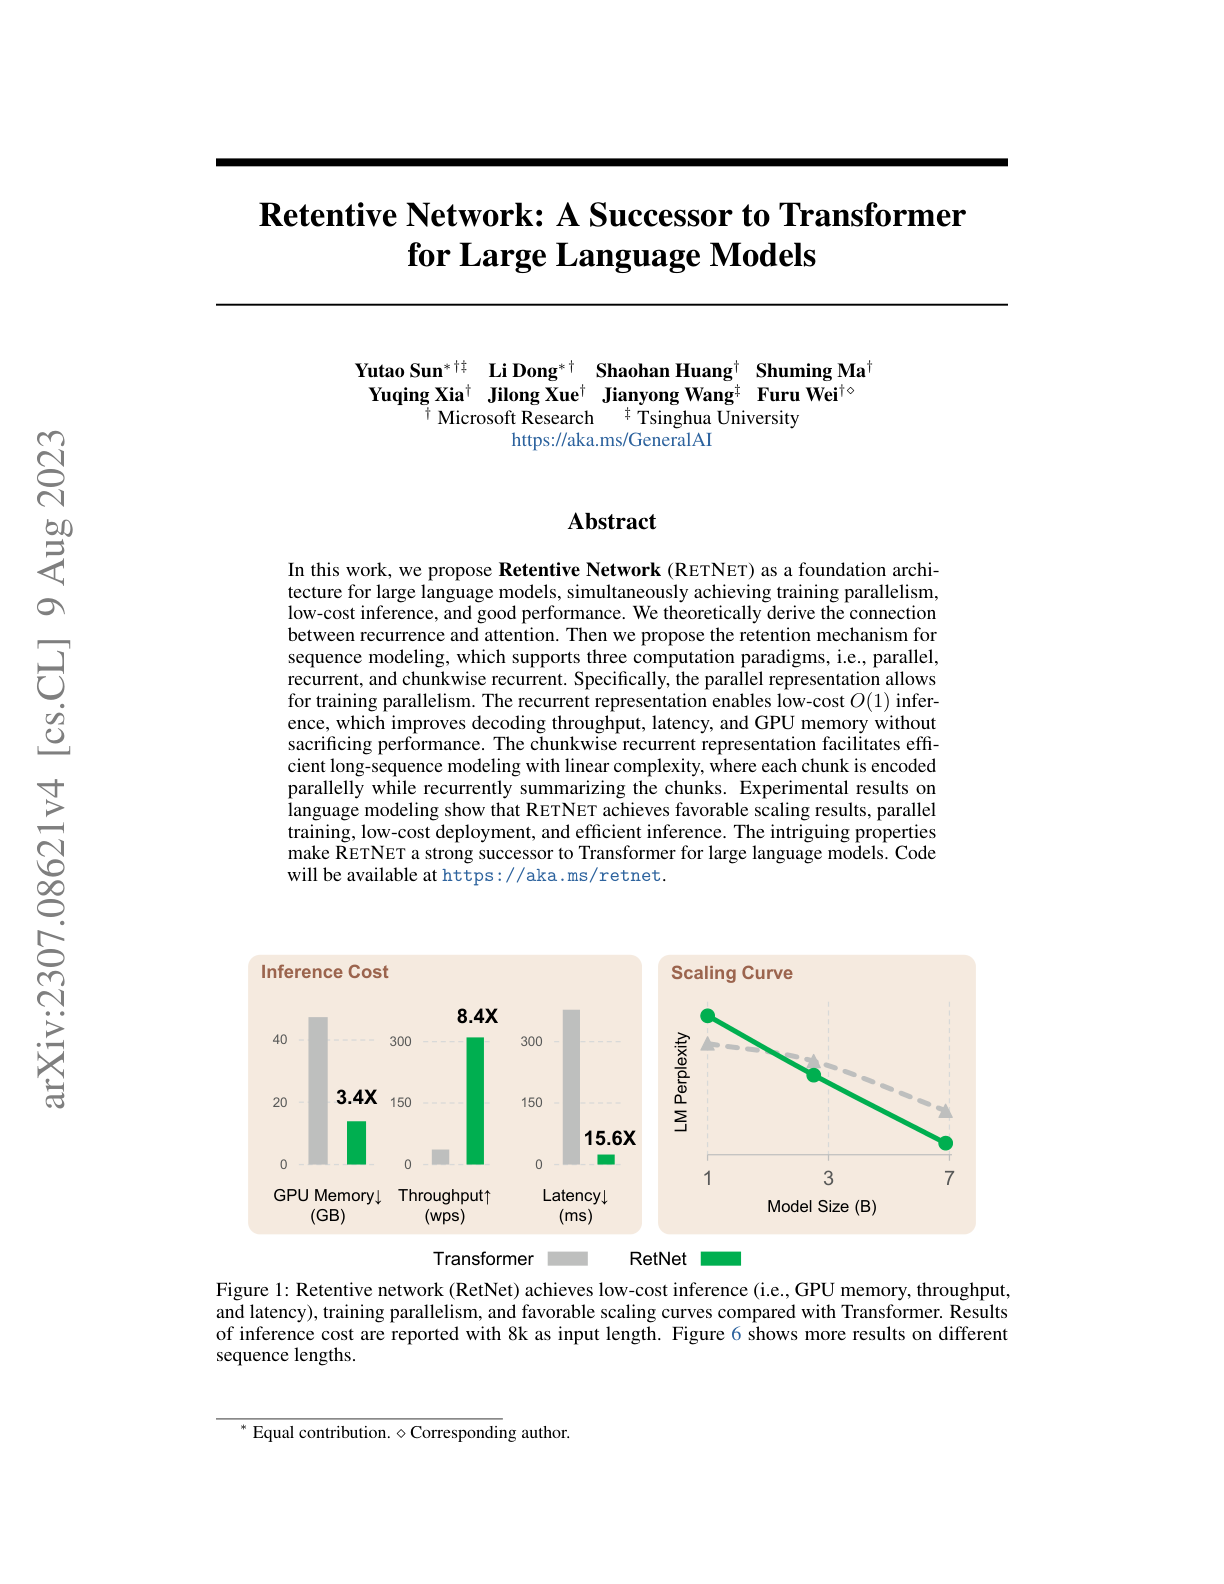
Retentive Network: A Successor to Transformer for Large Language Models
Hacker News threads
- Jul 2023Retentive Network: A Successor to Transformer for Large Language Models
- Jul 2023Retentive Network: A Successor to Transformer for Large Language Models
- Jul 2023Retentive Network: A Successor to Transformer for Large Language Models
- Jul 2023Retentive Network: A Successor to Transformer Implemented in PyTorch
- Sep 2023The Eleuther AI Mafia
- Dec 2023Mamba: Linear-Time Sequence Modeling with Selective State Spaces
- Dec 20232023: The Year of AI
- Jan 2024Eagle 7B: Soaring past Transformers
- 117
Extending Context Window of Large Language Models via Positional Interpolation
Hacker News threads
- Jun 2023Extending Context Window of Large Language Models via Positional Interpolation
- Jun 2023XGen-7B, a new 7B foundational model trained on up to 8K length for 1.5T tokens
- Jul 2023Llama 2 – Meta AI
- Jul 2023Llama 2 – Meta AI
- Nov 2023Is anyone using self hosted LLM day to day and training it like a new employee
- Jan 2024Phi-2: Self-Extend Boosts Performance, Extends Context to 8k Without Training
- 118
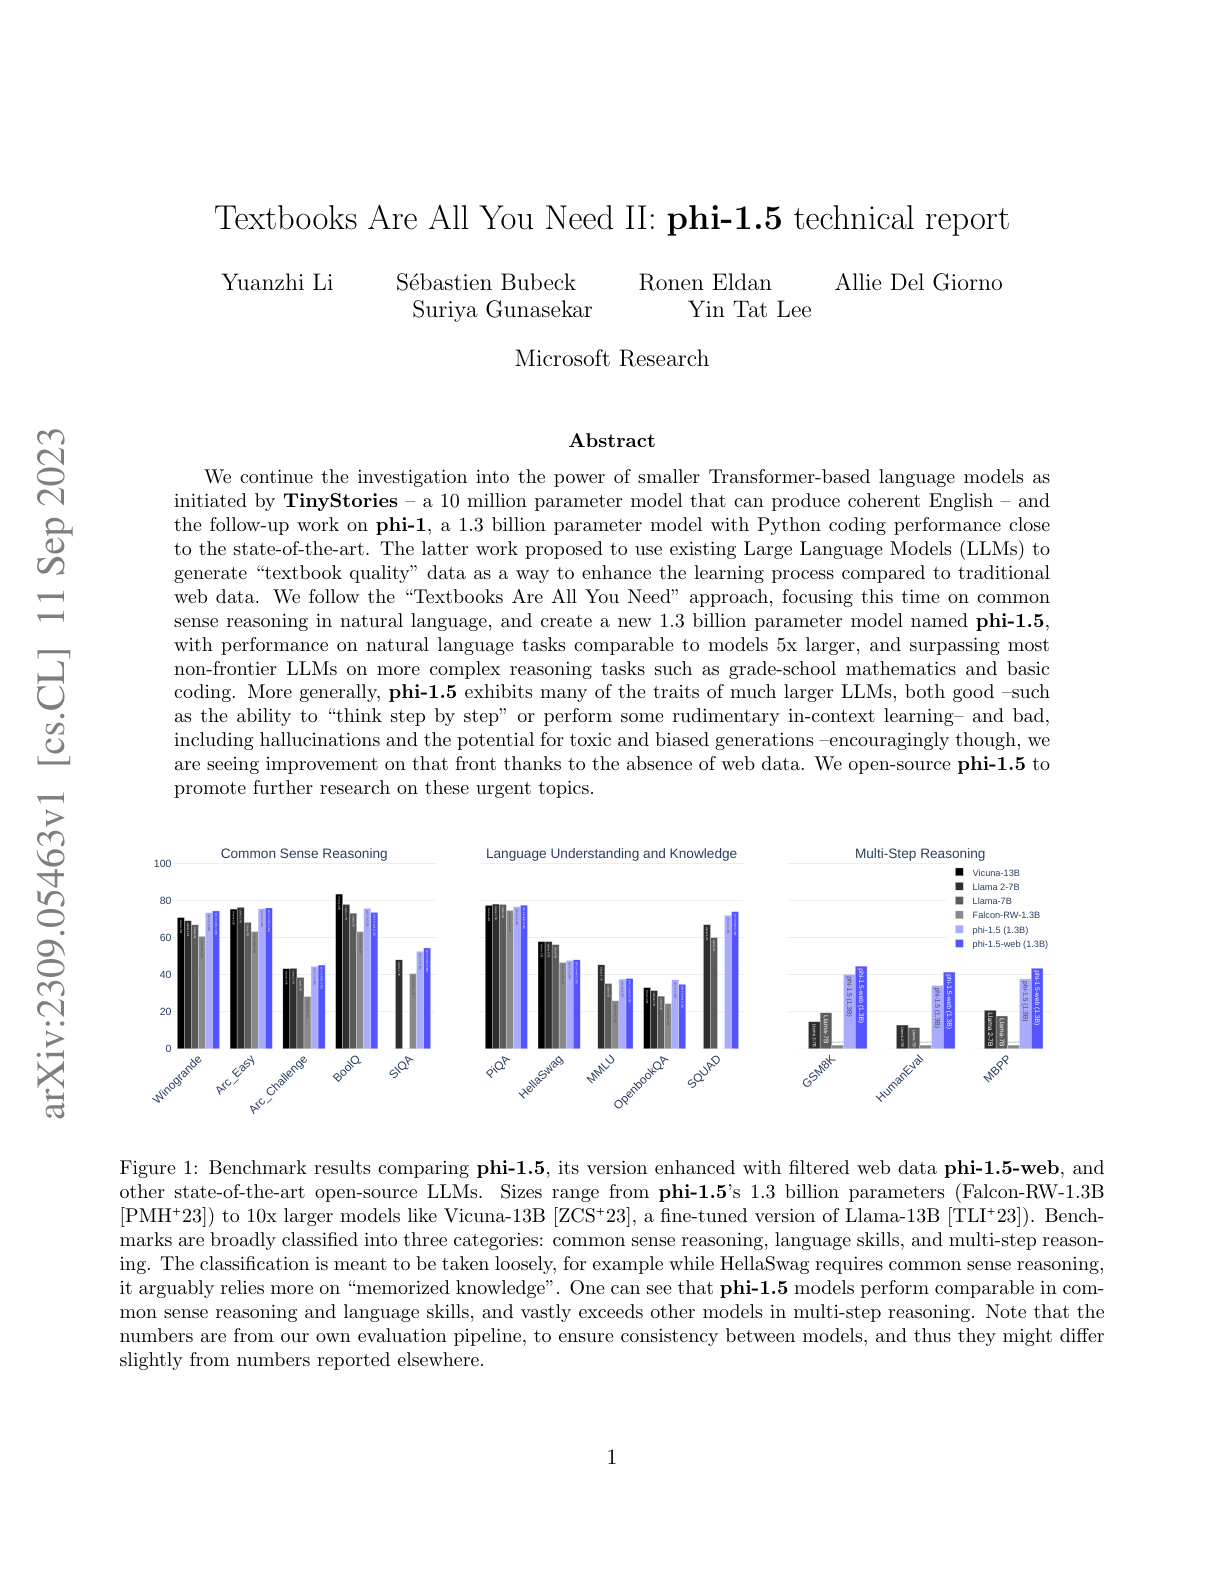
Textbooks Are All You Need II: phi-1.5 technical report
Hacker News threads
- Sep 2023The tide is shifting: 1.3B outperforms 7B Llama 2
- Sep 2023Textbooks Are All You Need II: phi-1.5 technical report
- Sep 2023Large Language Models for Compiler Optimization
- Sep 2023Outperforming LLMs with less training data and smaller model sizes
- Oct 2023AI hype is built on high test scores. Those tests are flawed
- Nov 2023A Coder Considers the Waning Days of the Craft
- Nov 2023MonadGPT – What would have happened if ChatGPT was invented in the 17th century?
- Jan 2024Microsoft Phi-2 model changes licence to MIT
- Jan 2024Ten Noteworthy AI Research Papers of 2023
- Jan 2024A Philosophical Introduction to Language Models
- 119
Tighter Bounds on the Expressivity of Transformer Encoders
Hacker News threads
- Apr 2023Tighter bounds on the expressivity of transformer encoders
- Jun 2023Thinking Like Transformers (pdf)
- Jun 2023Researchers warn of ‘model collapse’ as AI trains on AI-generated content
- Dec 2023Ask HN: AI/ML papers to catch up with current state of AI?
- Jan 2024Turing Complete Transformers: Two Transformers Are More Powerful Than One
- 120
Tracr: Compiled Transformers as a Laboratory for Interpretability
Hacker News threads
- 121
Toolformer: Language Models Can Teach Themselves to Use Tools
Hacker News threads
- Feb 2023Toolformer: Language Models Can Teach Themselves to Use Tools
- Feb 2023Toolformer: Language Models Can Teach Themselves to Use Tools
- Feb 2023Toolformer: Language models can teach themselves to use tools
- Feb 2023A new way to build with Large Language Models
- Feb 2023Our Society Is Not Prepared for This Much AI Awesome
- Feb 2023ChatGPT is falsely recommending us for a service we don't provide
- Mar 2023ChatGPT Explained: A Normie's Guide to How It Works
- Mar 2023ViperGPT: A Python Framework That Combines Vision and Language Models Using Code
- Mar 2023ChatGPT Outperforms Crowd-Workers for Text-Annotation Tasks
- May 2023AI knows things no one told it
- Nov 2023Sam Altman's ouster was precipitated by letter to board about AI breakthrough
- 122
Large Language Model Guided Tree-of-Thought
Hacker News threads
- 123
Gorilla: Large Language Model Connected with Massive APIs
Hacker News threads
- May 2023Gorilla: Large Language Model Connected with APIs
- Jun 2023Gorilla: Large Language Model Connected with APIs
- May 2023Gorilla: LLM Connected with APIs
- Jun 2023Falcon 40B LLM (which beats Llama) now Apache 2.0
- Jun 2023OpenAI Cybersecurity Grant Program
- Jun 2023RedPajama 7B (an Apache 2.0-licensed LLaMa) is now available
- Jun 2023OpenLLaMA 13B Released
- Aug 2023Show HN: Poozle – open-source Plaid for LLMs
- Sep 2023RestGPT
- 124
Evaluating Large Language Models in Theory of Mind Tasks
Hacker News threads
- Feb 2023Theory of Mind May Have Spontaneously Emerged in Large Language Models
- Feb 2023I had ChatGPT write a Decemberists song
- Feb 2023I had ChatGPT write a Decemberists song
- Feb 2023Bing: “I will not harm you unless you harm me first”
- Feb 2023Researchers Discover a More Flexible Approach to Machine Learning
- Feb 2023ChatGPT is falsely recommending us for a service we don't provide
- Mar 2023Microsoft's paper on OpenAI's GPT-4 had hidden information
- Apr 2023AI won't steal your job, people leveraging AI will
- May 2023This time, it feels different
- 125
BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models
Hacker News threads
- Jan 2023Blip-2
- Mar 2023Zero-1-to-3: Zero-shot One Image to 3D Object
- Apr 2023MiniGPT-4
- Apr 2023MiniGPT-4
- May 2023MaMMUT: A simple vision-encoder text-decoder architecture for multimodal tasks
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.