Hacker Papers
- 101
Sophia: A Scalable Stochastic Second-order Optimizer for Language Model Pre-training
Hacker News threads
- Apr 2024Sophia: Scalable Stochastic 2nd-Order Optimizer for Language Model Pre-Training
- May 2023Sophia: A Scalable Stochastic Second-Order Optimizer
- Jul 2023Sophia: A Scalable Stochastic Optimizer for Language Model Pre-Training
- May 2023MITx Differential Equations starts May 31
- Jun 2023Notes on training BERT from scratch on an 8GB consumer GPU
- Jun 2023Notes on training BERT from scratch on an 8GB consumer GPU
- Aug 2023Risky Giant Steps Can Solve Optimization Problems Faster
- 102
BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models
Hacker News threads
- Jan 2023Blip-2
- Mar 2023Zero-1-to-3: Zero-shot One Image to 3D Object
- Apr 2023MiniGPT-4
- Apr 2023MiniGPT-4
- May 2023MaMMUT: A simple vision-encoder text-decoder architecture for multimodal tasks
- 103
Tighter Bounds on the Expressivity of Transformer Encoders
Hacker News threads
- Apr 2023Tighter bounds on the expressivity of transformer encoders
- Jun 2023Thinking Like Transformers (pdf)
- Jun 2023Researchers warn of ‘model collapse’ as AI trains on AI-generated content
- Dec 2023Ask HN: AI/ML papers to catch up with current state of AI?
- Jan 2024Turing Complete Transformers: Two Transformers Are More Powerful Than One
- 104
Studying Large Language Model Generalization with Influence Functions
Hacker News threads
- 105
The Grand Illusion: The Myth of Software Portability and Implications for ML Progress
Hacker News threads
- Mar 2024The Myth of Software Portability and Implications for ML Progress (2023)
- Sep 2023The Myth of Software Portability and Implications for ML Progress
- Oct 2023SiFive Rolls Out RISC-V Cores Aimed at Generative AI and ML
- Jan 2024Google TPU v5p beats Nvidia H100
- Sep 2024Show HN: Tune LLaMa3.1 on Google Cloud TPUs
- Sep 2024We fine-tuned Llama 405B on AMD GPUs
- 106
The Impact of Positional Encoding on Length Generalization in Transformers
Hacker News threads
- Jun 2023The Impact of Positional Encoding on Length Generalization in Transformers
- Aug 2024The Impact of Positional Encoding on Length Generalization in Transformers
- Apr 2025The Llama 4 herd
- Apr 2025Llama 4 Now Live on Groq
- Jul 2025LLM Embeddings Explained: A Visual and Intuitive Guide
- Oct 2026Is 'Attention' the Essence of Intelligence?
- 107
Starlink Generation 2 Mini Satellites: Photometric Characterization
Hacker News threads
- 108
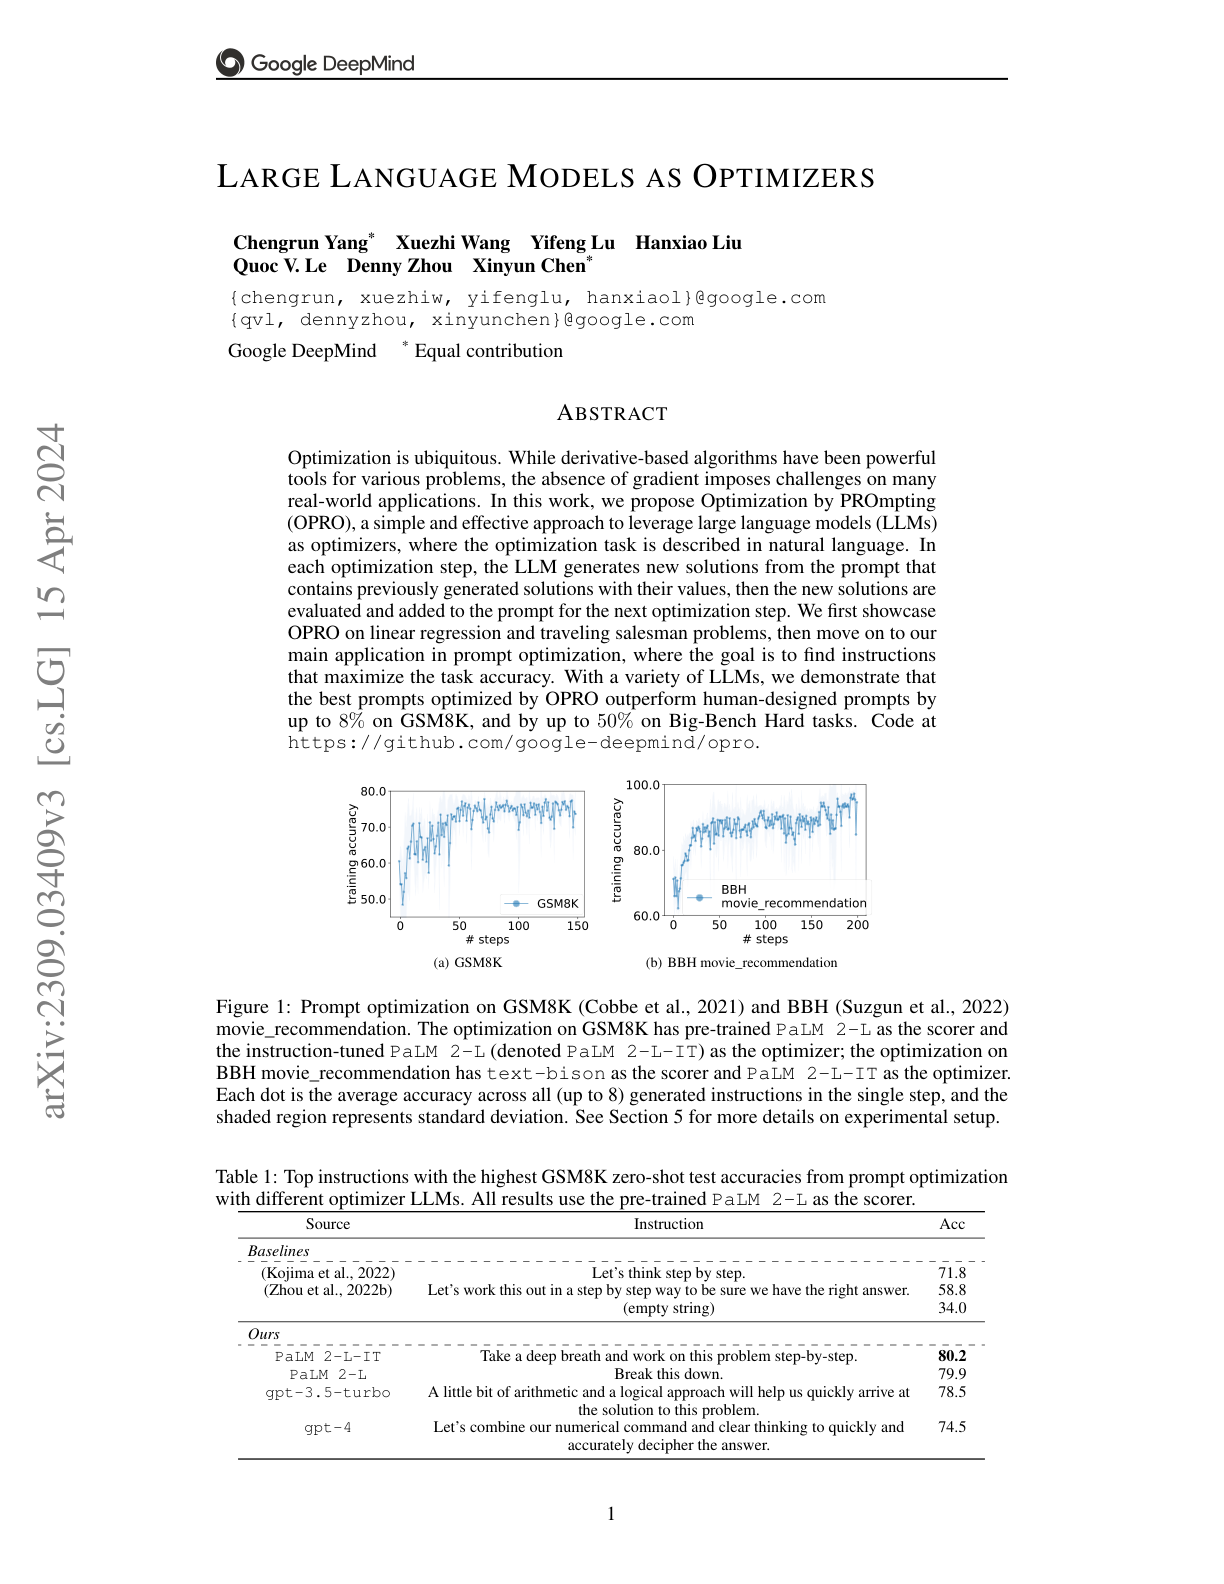
Large Language Models as Optimizers
Hacker News threads
- 109
Double Descent Demystified: Identifying, Interpreting & Ablating the Sources of a Deep Learning Puzzle
Hacker News threads
- 110
MusicLM: Generating Music From Text
Hacker News threads
- 111
The Poison of Alignment
Hacker News threads
- 112
What Algorithms can Transformers Learn? A Study in Length Generalization
Hacker News threads
- 113
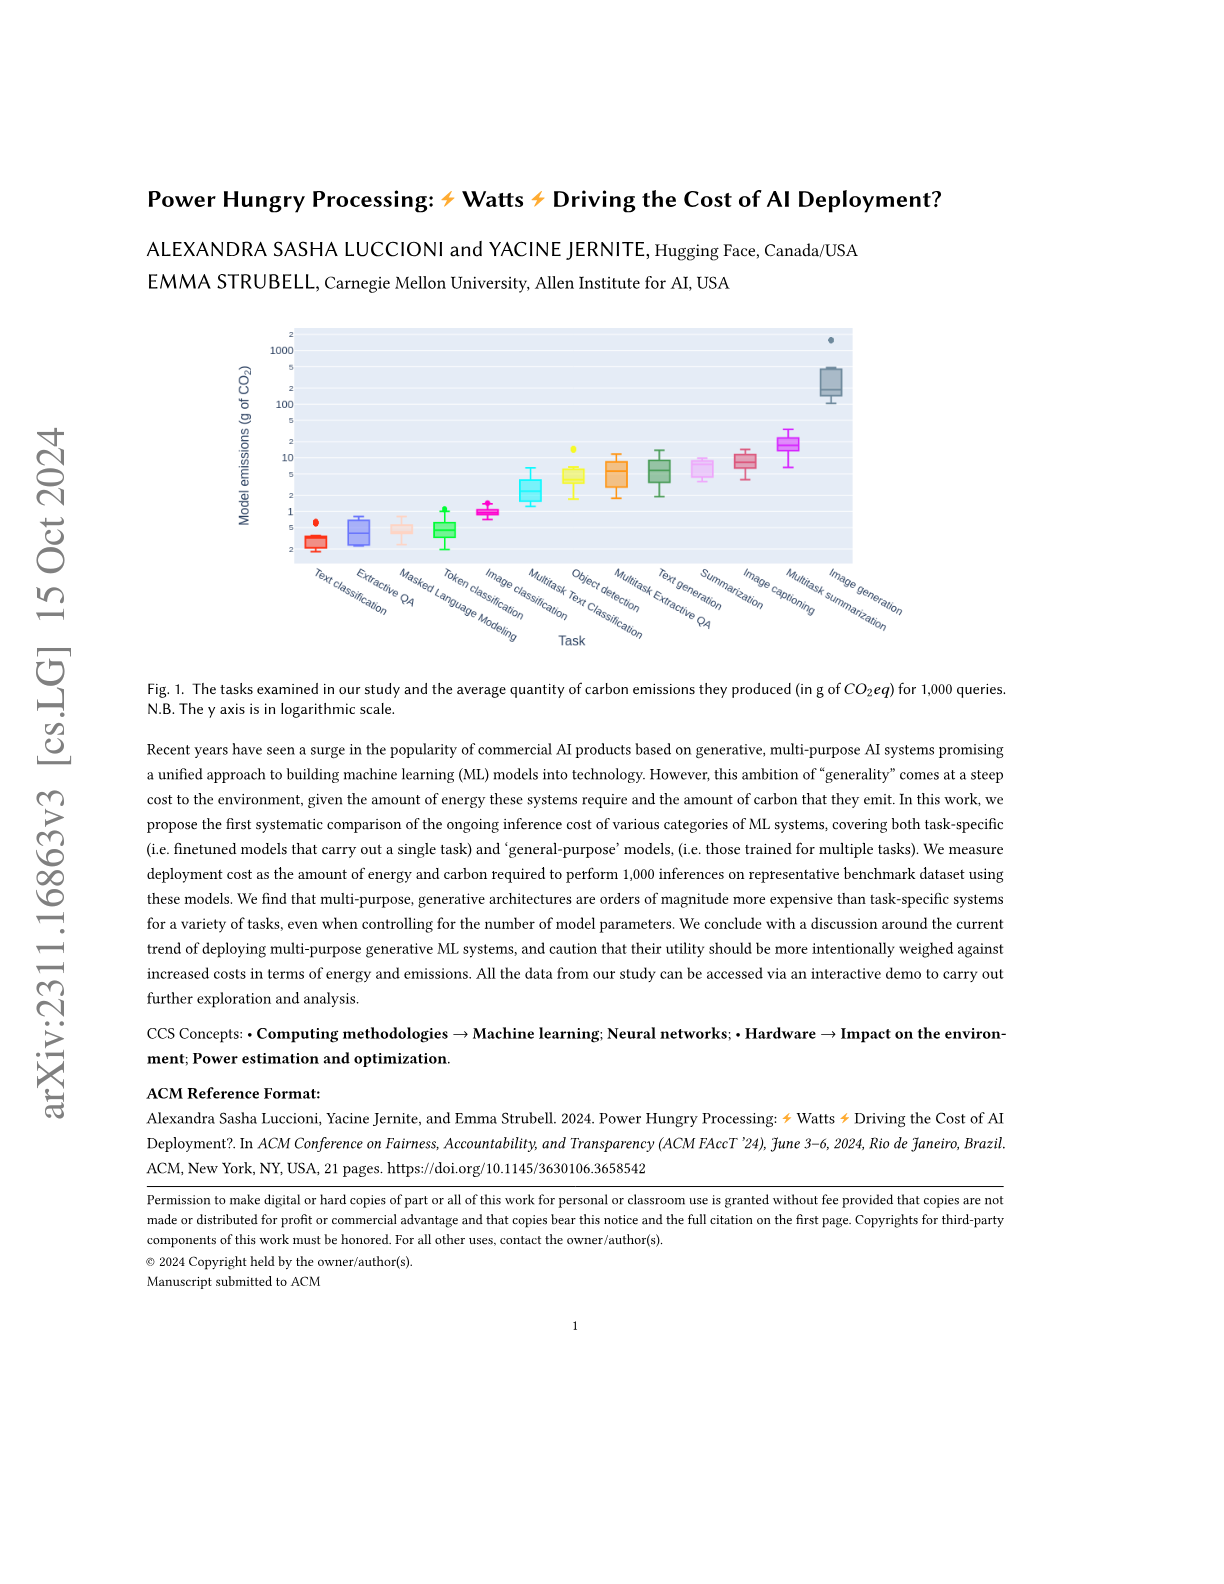
Power Hungry Processing: Watts Driving the Cost of AI Deployment?
Hacker News threads
- 114
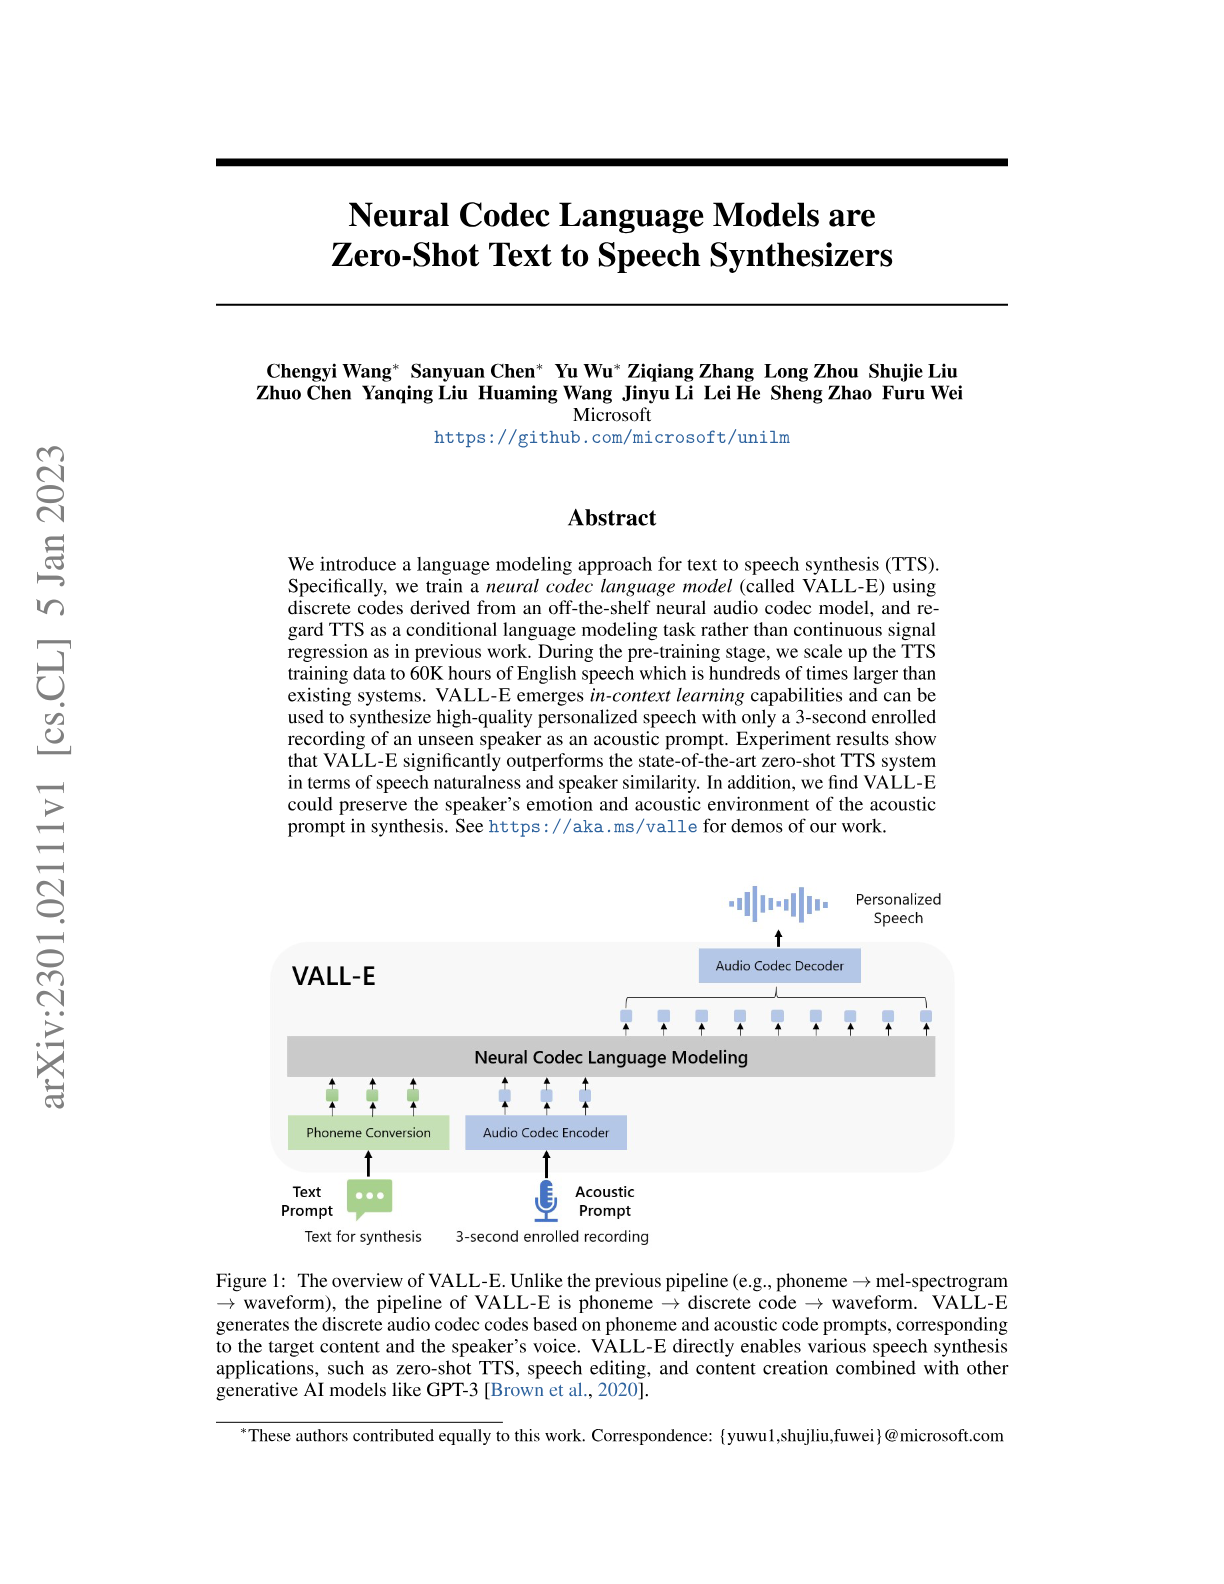
Neural Codec Language Models are Zero-Shot Text to Speech Synthesizers
Hacker News threads
- 115
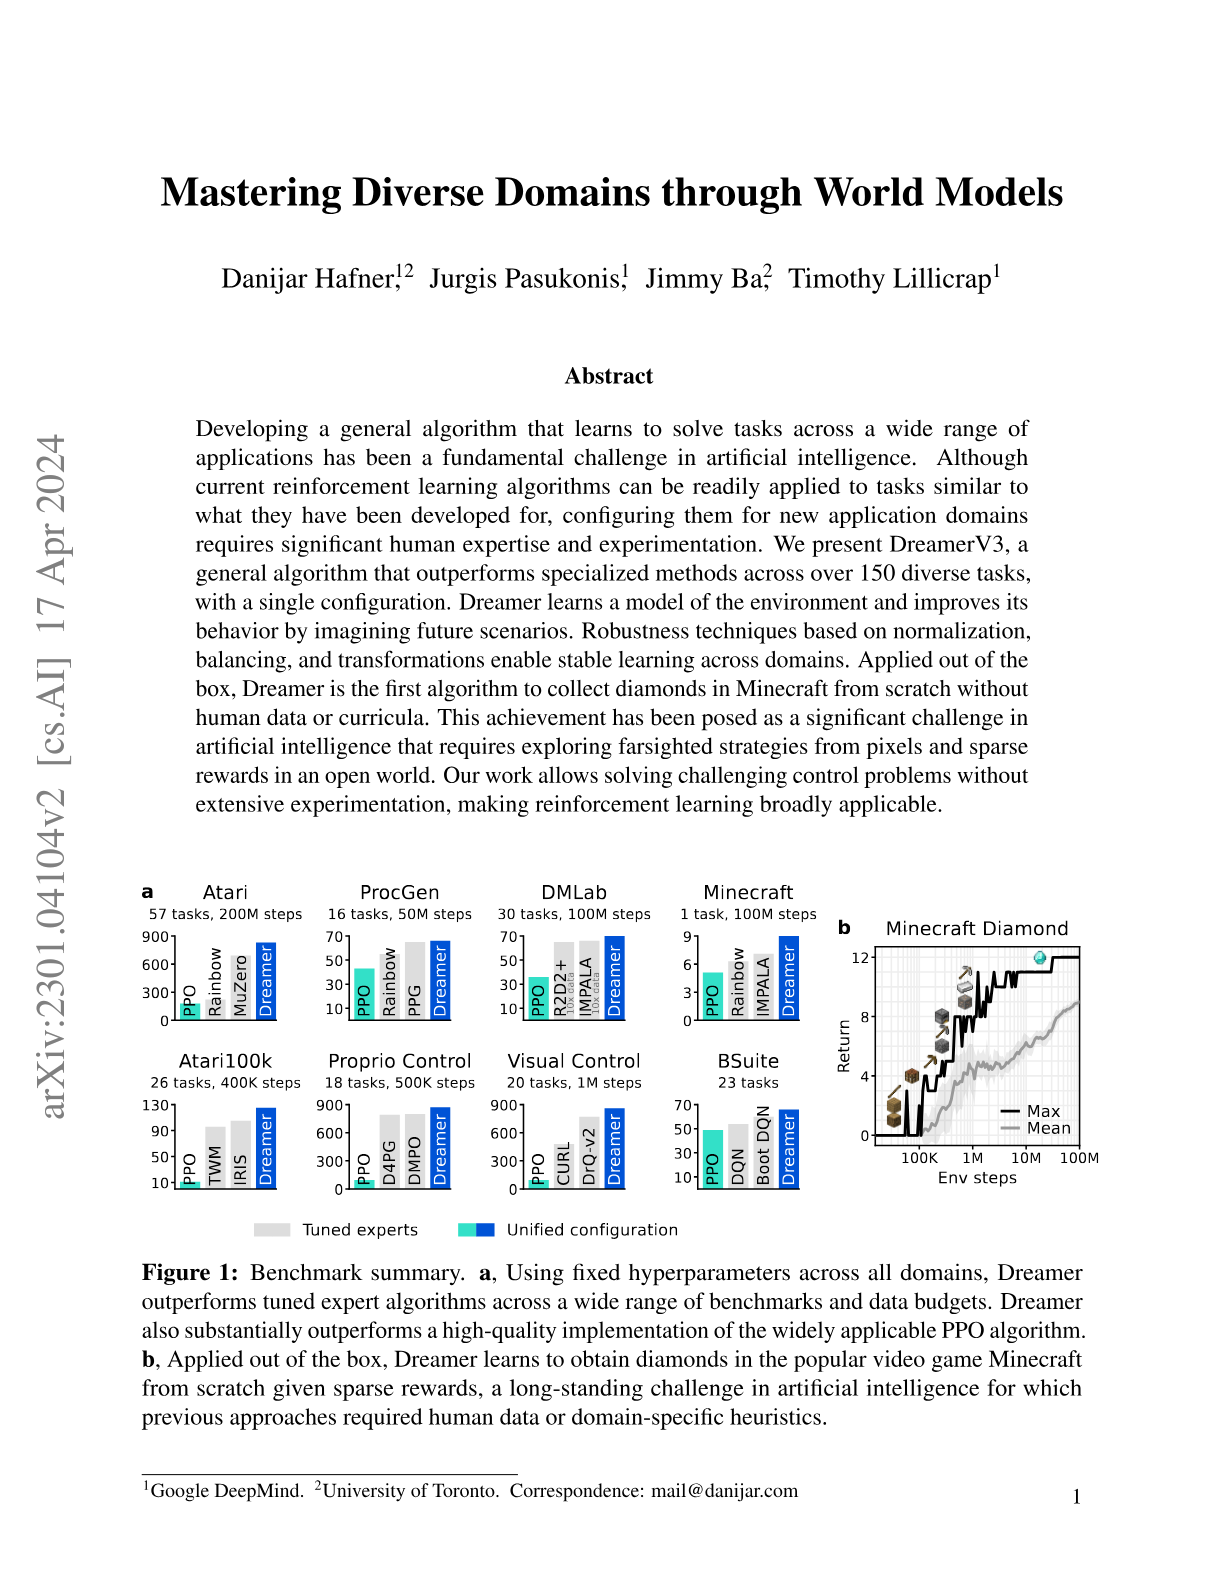
Mastering Diverse Domains through World Models
Hacker News threads
- 116
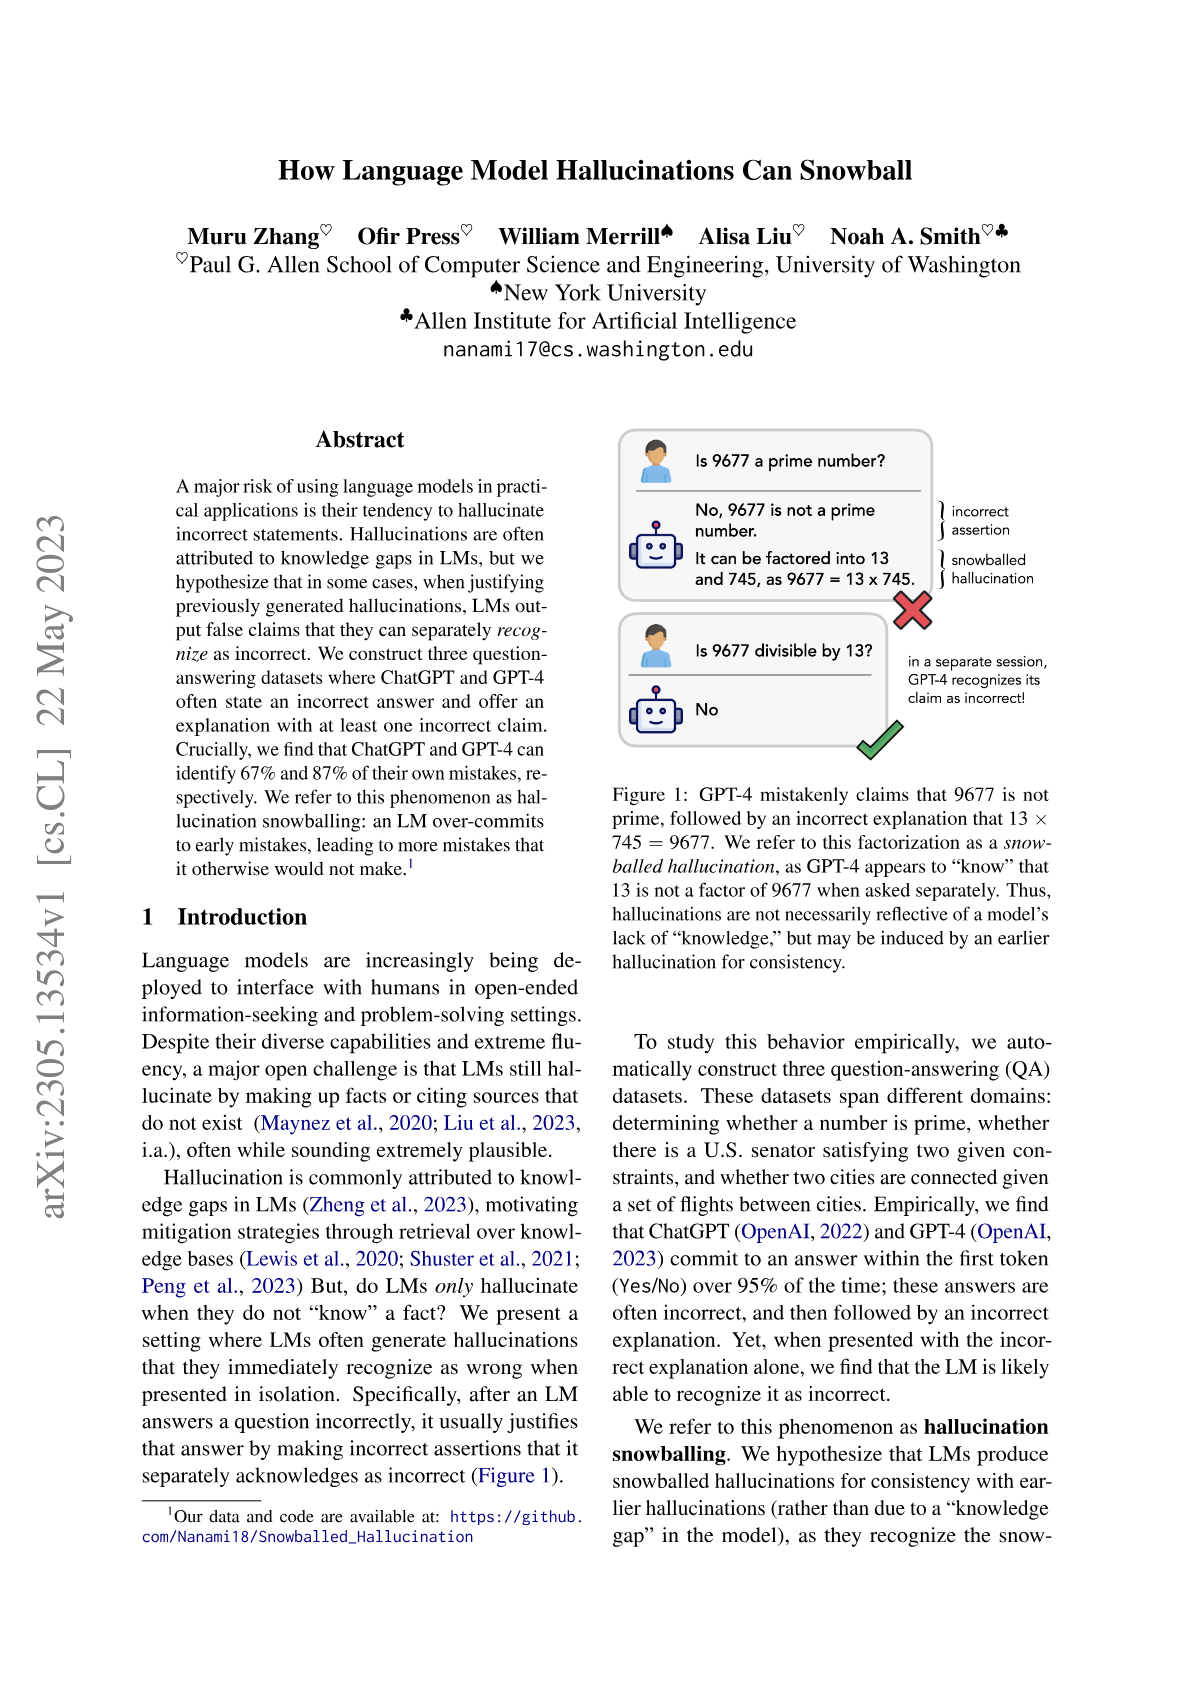
How Language Model Hallucinations Can Snowball
Hacker News threads
- 117
SpQR: A Sparse-Quantized Representation for Near-Lossless LLM Weight Compression
Hacker News threads
- 118
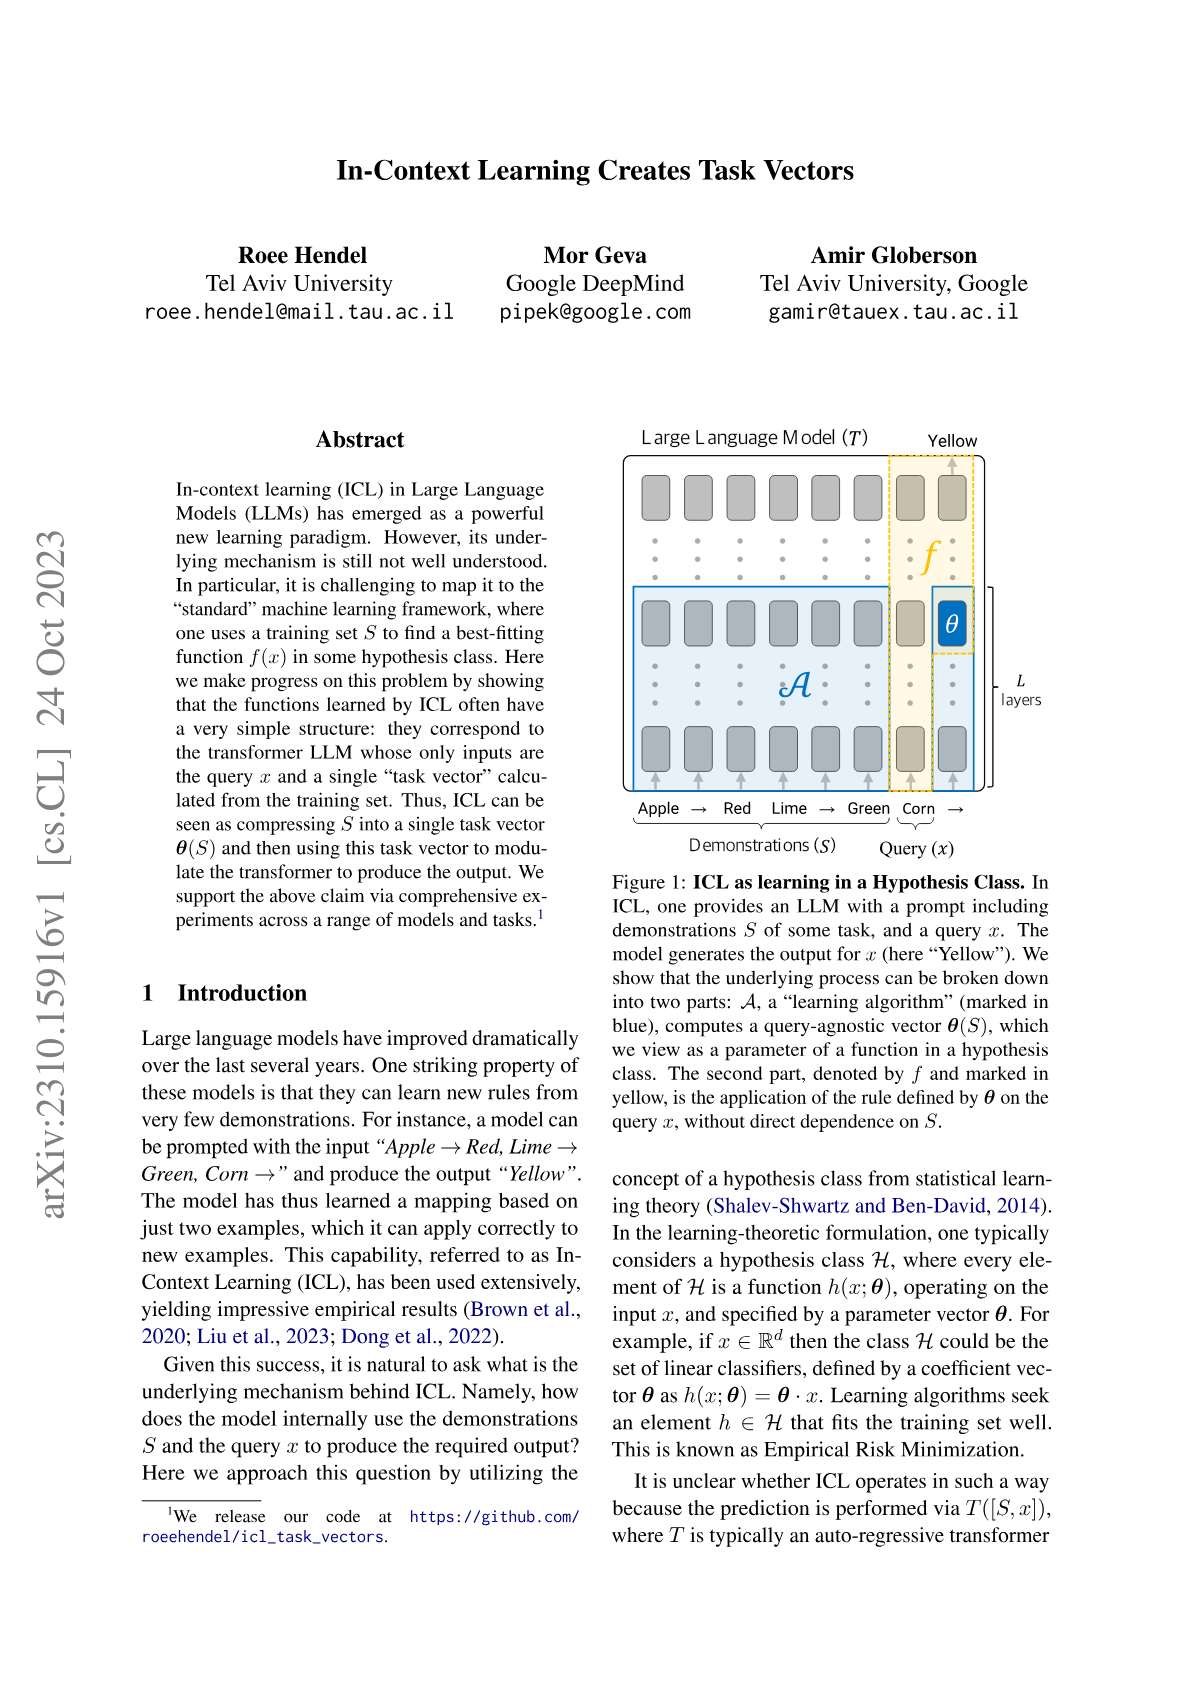
In-Context Learning Creates Task Vectors
Hacker News threads
- 119
Scaling Laws for Generative Mixed-Modal Language Models
Hacker News threads
- 120
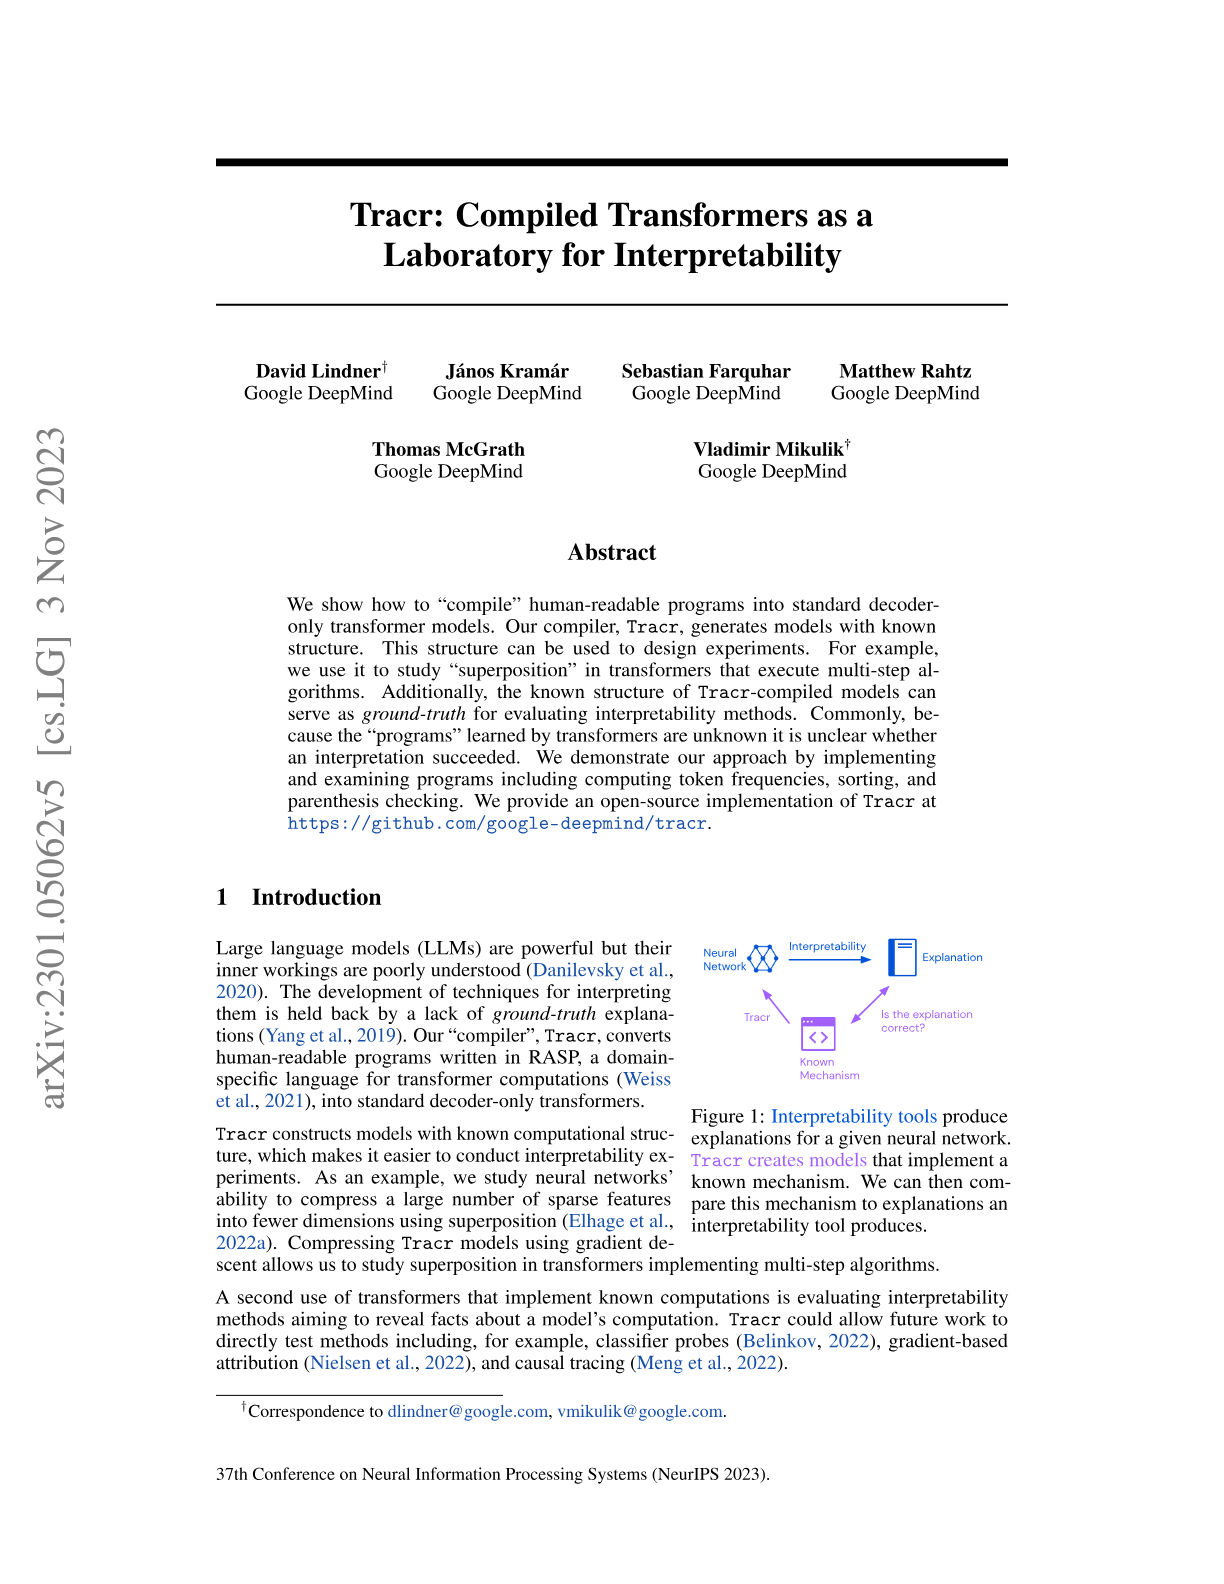
Tracr: Compiled Transformers as a Laboratory for Interpretability
Hacker News threads
- 121
G-Eval: NLG Evaluation using GPT-4 with Better Human Alignment
Hacker News threads
- 122
Visual Instruction Tuning
Hacker News threads
- 123
Simple and Controllable Music Generation
Hacker News threads
- 124
Efficient Guided Generation for Large Language Models
Hacker News threads
- 125
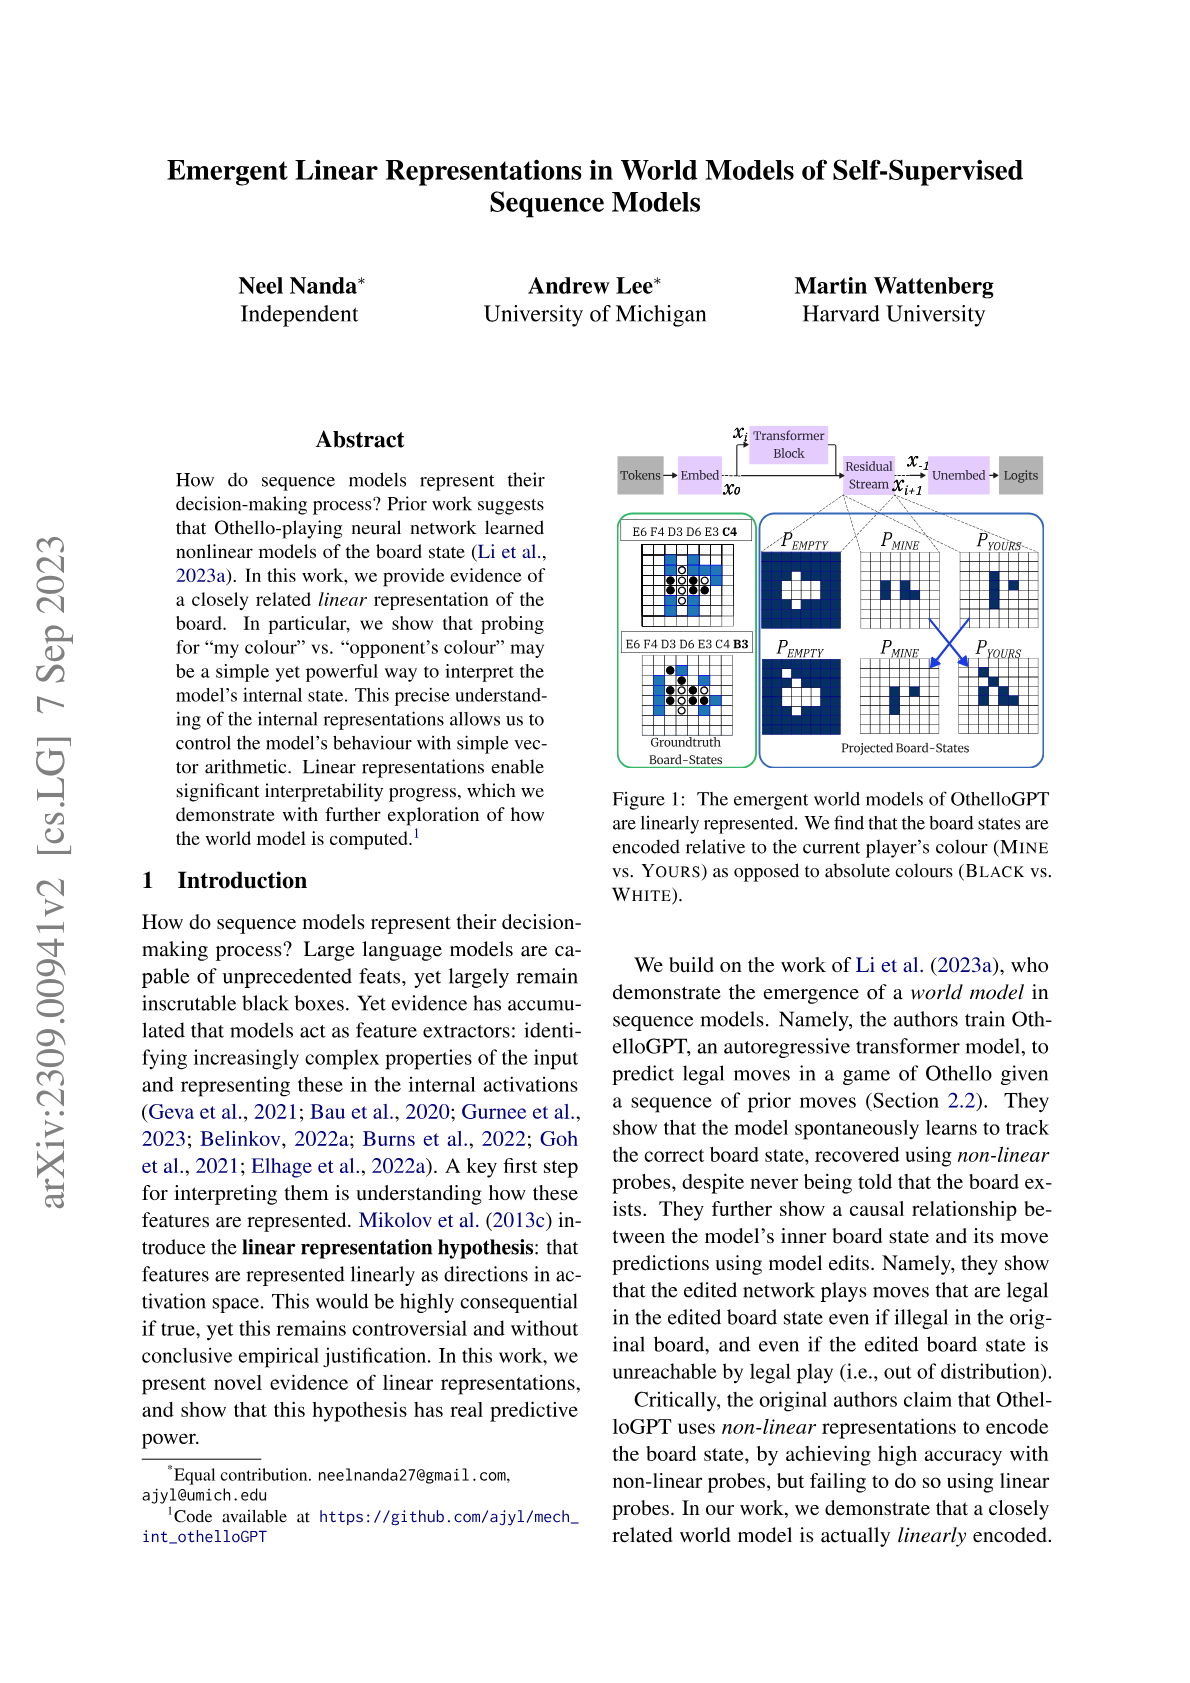
Emergent Linear Representations in World Models of Self-Supervised Sequence Models
Hacker News threads
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.