Hacker Papers
- 126
Decentralized Training of Foundation Models in Heterogeneous Environments
Hacker News threads
- 127
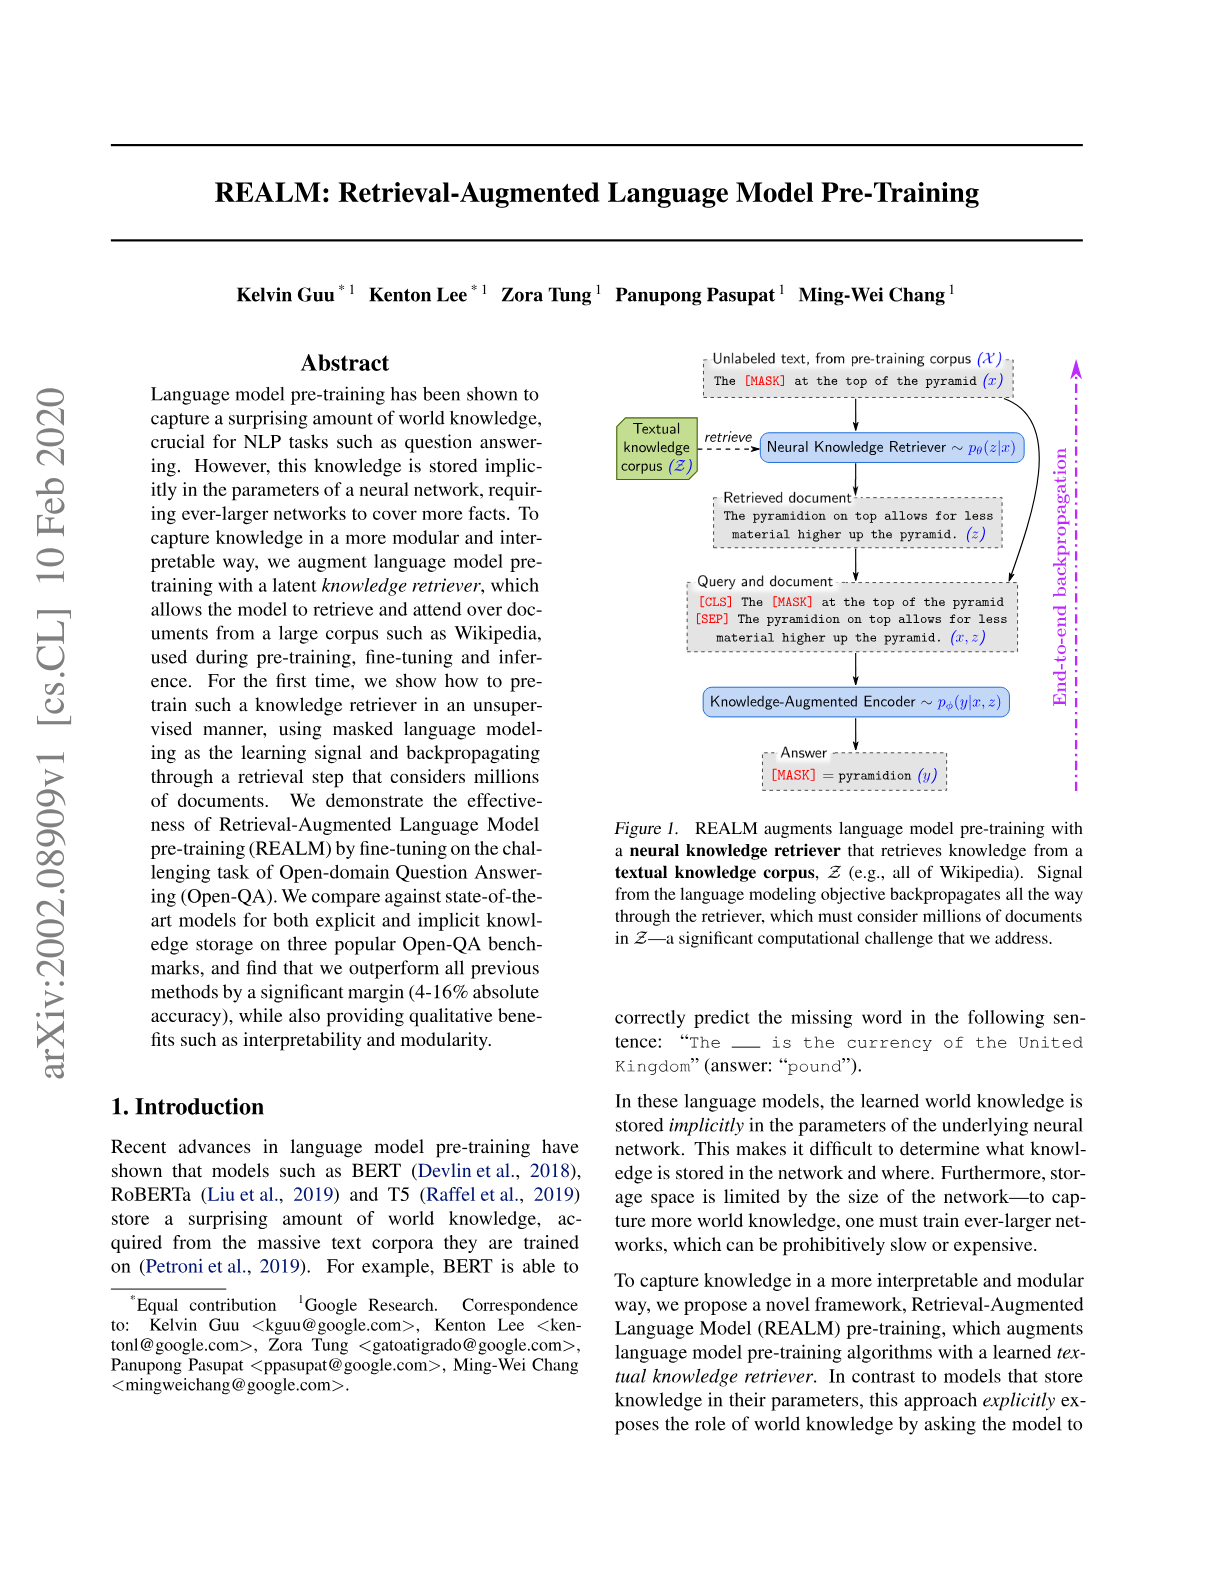
REALM: Retrieval-Augmented Language Model Pre-Training
Hacker News threads
- 128
Attacking the DeFi Ecosystem with Flash Loans for Fun and Profit
Hacker News threads
- Jan 2023Attacking the DeFi Ecosystem with Flash Loans for Fun and Profit
- Jan 2021Attacking the DeFi ecosystem with flash loans for fun and profit (2020)
- May 2022Billion-Dollar Crypto Loan Is Easy to Get, but Gone in a Flash
- Feb 2024Two Ethereum DeFi traders just made $120M using a strategy called 'looping'
- 129
Binary Fuse Filters: Fast and Smaller Than Xor Filters
Hacker News threads
- Jan 2022Binary Fuse Filters: Fast and Smaller Than Xor Filters
- Jun 2024Binary Fuse Filters: fast and smaller than XOR filters
- Jan 2026Binary Fuse Filters: Fast and Smaller Than XOR Filters
- Oct 2022Cuckoo Filter: Practically Better Than Bloom (2014) [pdf]
- Sep 2024When Bloom filters don't bloom (2020)
- May 2025Bloom Filters
- 130
TabPFN: A Transformer That Solves Small Tabular Classification Problems in a Second
Hacker News threads
- 131
Escaping the Big Data Paradigm with Compact Transformers
Hacker News threads
- 132
TruthfulQA: Measuring How Models Mimic Human Falsehoods
Hacker News threads
- 133
Efficiently Modeling Long Sequences with Structured State Spaces
Hacker News threads
- 134
Hyper-Fast Positive Energy Warp Drives
Hacker News threads
- 135
Self-Consistency Improves Chain of Thought Reasoning in Language Models
Hacker News threads
- 136
Flamingo: a Visual Language Model for Few-Shot Learning
Hacker News threads
- 137
Suppressing quantum errors by scaling a surface code logical qubit
Hacker News threads
- 138
Game-theoretic statistics and safe anytime-valid inference
Hacker News threads
- 139
PaLM: Scaling Language Modeling with Pathways
Hacker News threads
- Apr 2022Palm: Scaling Language Modeling with Pathways [pdf]
- Apr 2022Palm: Scaling Language Modeling with Pathways
- Jun 2022Palm: Scaling Language Modeling with Pathways
- Apr 2022Socratic Models – Composing Zero-Shot Multimodal Reasoning with Language
- May 2022Imagen, a text-to-image diffusion model
- Jun 2022LaMDA is not sentient
- Oct 2022Large Language Models Can Self-Improve
- Nov 2022The elite, underpaid, and weird world of crossword writers
- Mar 2023Bing sees 15.8% boost in visits following GPT-4 push, as Google sees a decline
- Mar 2023HN thread 35352653
- May 2023Meta AI Unleashes Megabyte, a Revolutionary Scalable Model Architecture
- 140
LaMDA: Language Models for Dialog Applications
Hacker News threads
- Jan 2022LaMDA: Language Models for Dialog Applications
- Feb 2022I asked GPT-NeoX-20B a hundred arithmetic questions
- Feb 2022Joke written by an AI: “A basic program walked into a bar ”
- Jun 2022LaMDA is not sentient
- Jun 2022Is LaMDA Sentient? – An Interview [pdf]
- Jul 2022Open-Source LaMDA Model
- Sep 2022Character.ai
- Feb 2023Ask HN: Does Google use the text inside gdocs and Gmail for training AI models?
- Mar 2023Google internally developed chatbots like ChatGPT years ago
- 141
Locating and Editing Factual Associations in GPT
Hacker News threads
- Feb 2023We Found an Neuron in GPT-2
- Feb 2023ChatGPT is falsely recommending us for a service we don't provide
- May 2023How does data removal from GPT *work
- Aug 2023PMET: Precise Model Editing in a Transformer
- Oct 2023MemGPT – LLMs with self-editing memory for unbounded context
- Nov 2023Is the reversal curse in LLMs real?
- Dec 2023What Is Retrieval-Augmented Generation a.k.a. RAG?
- May 2024Llama3 implemented from scratch
- 142
Why Can GPT Learn In-Context? Language Models Implicitly Perform Gradient Descent as Meta-Optimizers
Hacker News threads
- Dec 2022Why Can GPT Learn In-Context? Language Models Perform Gradient Descent
- Jan 2023The Expanding Dark Forest and Generative AI
- Feb 2023GPT in 60 Lines of NumPy
- Feb 2023To Build Truly Intelligent Machines, Teach Them Cause and Effect
- Mar 2023Large language models are having their Stable Diffusion moment
- Mar 2023GPT-4 Designed a Programming Language
- Mar 2023OK, it’s time to freak out about AI
- May 2023Chatbots Don’t Know What Stuff Isn’t
- Jul 2024Reasoning in Large Language Models: A Geometric Perspective
- 143
Photorealistic Text-to-Image Diffusion Models with Deep Language Understanding
Hacker News threads
- Aug 2022Imagen: An AI system that creates photorealistic images from input text
- Feb 2023Google Invests Almost $400M in ChatGPT Rival Anthropic
- Mar 2023Visual ChatGPT
- Apr 2023Stability AI releases DeepFloyd IF, a powerful text-to-image model
- May 2023Governance of Superintelligence
- Jul 2023Stability AI releases its latest image-generating model, Stable Diffusion XL 1.0
- 144
Train Short, Test Long: Attention with Linear Biases Enables Input Length Extrapolation
Hacker News threads
- May 2023Attention with Linear Biases (ALiBi)
- May 2023Replit's new Code LLM: Open Source, 77% smaller than Codex, trained in 1 week
- May 2023Anthropic - Introducing 100K Token Context Windows, Around 75,000 Words
- Jul 2023
- Aug 2023Code Llama, an AI tool for coding
- Aug 2023
- Jan 2024ChatGPT for Teams
- Oct 2024Differential Transformer
- 145
RoFormer: Enhanced Transformer with Rotary Position Embedding
Hacker News threads
- Mar 2023Large language models are having their Stable Diffusion moment
- Apr 2023Why Are Sinusoidal Functions Used for Position Encoding?
- Aug 2023Llama from Scratch (or how to implement a paper without crying)
- Apr 2025Multi-Token Attention
- Apr 2025The Llama 4 herd
- Apr 2025Llama 4 Now Live on Groq
- Aug 2025Open models by OpenAI
- 146
Fast Inference from Transformers via Speculative Decoding
Hacker News threads
- Sep 2023Fast Inference from Transformers via Speculative Decoding
- Jul 2025Playing with Open Source LLMs
- Feb 2026Raspberry Pi Pico 2 at 873.5MHz with 3.05V Core Abuse
- Apr 2026We got 207 tok/s with Qwen3.5-27B on an RTX 3090
- May 2026Accelerating Gemma 4: faster inference with multi-token prediction drafters
- Jun 2026DeepSeek open-sources inference optimizations with 60–85% faster generation [pdf]
- Jun 2026DeepSeek open-sources inference optimizations with 60–85% faster generation [pdf]
- Jun 2026DeepSeek open-sources inference optimizations with 60–85% faster generation [pdf]
- 147
MIP*=RE
Hacker News threads
- Jan 2020MIP*=Re
- Aug 2021MIP* = Re
- Jan 2020Recent groundbreaking result in complexity theory: MIP*=RE
- Jan 2020'Remarkable' MIP*=RE proof describes how to solve seemingly impossible problem
- Mar 2020Landmark computer science proof cascades through physics and math
- Mar 2020Landmark computer science proof cascades through physics and math
- Apr 2020Mathematicians try to understand how CS proof solves Connes embedding conjecture
- Mar 2023Ask HN: What's new in theoretical CS these days?
- Aug 2023Complexity Theory’s 50-Year Journey to the Limits of Knowledge
- 148
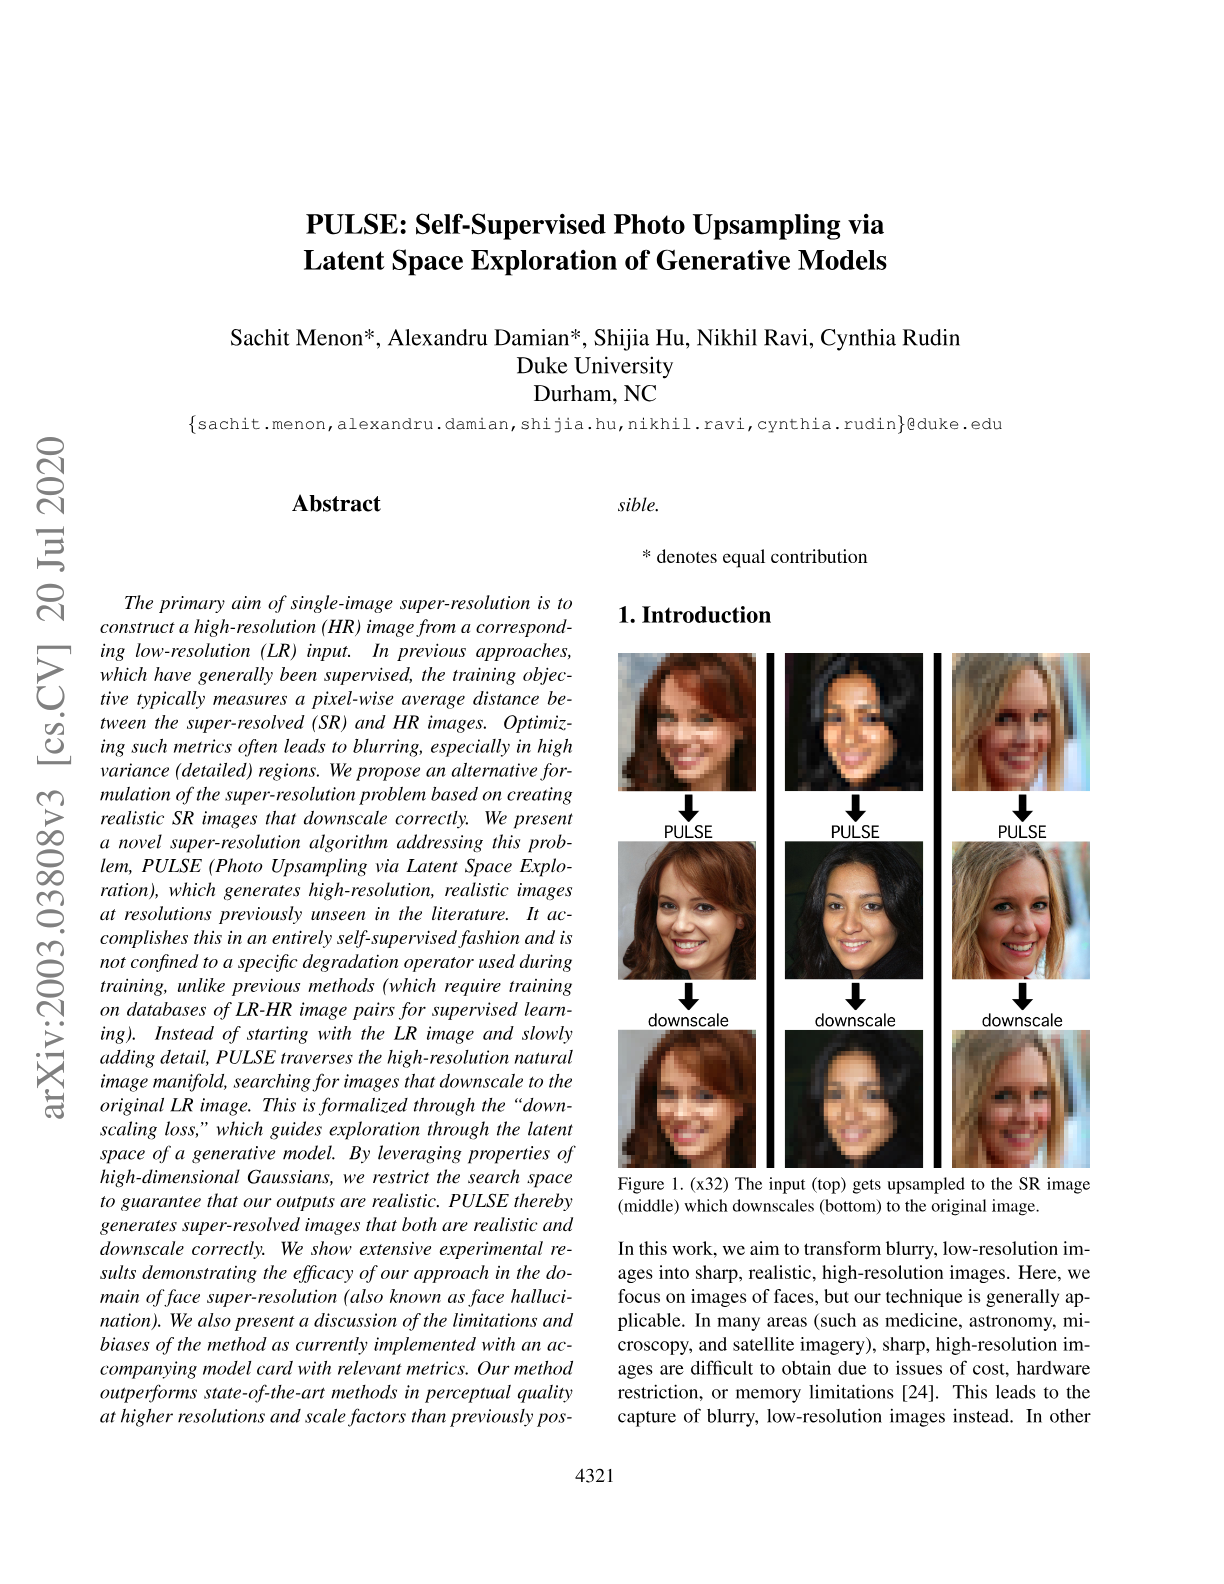
PULSE: Self-Supervised Photo Upsampling via Latent Space Exploration of Generative Models
Hacker News threads
- Jun 2020Pulse: Self-Supervised Photo Upsampling via Latent Space Exploration
- Jun 2020Facial Recognition Leads To False Arrest Of Black Man In Detroit
- Jul 2020Yann LeCun quits Twitter amid acrimonious exchanges on AI bias
- Feb 2022Recovering redacted information from pixelated videos
- May 2022Imagen, a text-to-image diffusion model
- Dec 2022Pixelmator Pro gets a magical, AI‑powered Deband feature
- 149
Transformers learn in-context by gradient descent
Hacker News threads
- Dec 2022Transformers learn in-context by gradient descent
- Jan 2023Do Large Language Models learn world models or just surface statistics?
- Feb 2023ChatGPT Hype Is Proof Nobody Understands AI
- Apr 2023Teaching ChatGPT to Speak My Son’s Invented Language
- Apr 2023GPT-4 gets a B on my quantum computing final exam
- Mar 2025ARC-AGI without pretraining
- 150
Petals: Collaborative Inference and Fine-tuning of Large Models
Hacker News threads
- Jul 2026Petals: Collaborative Inference and Fine-Tuning of Large Models
- Mar 2023Petals: Collaborative Inference and Fine-Tuning of Large Models
- Dec 2022Petals is creating a free, distributed network for running text-generating AI
- Jan 2023Petals: Run 100B+ language models at home bit-torrent style
- Jan 2023Petals: Run 100B+ language models at home bit-torrent style
- Jan 2023Ask HN: Can you crowdfund the compute for GPT?
- Feb 2023Running large language models like ChatGPT on a single GPU
- Mar 2023The Most Cited AI Papers in 2022
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.