Hacker Papers
- 151
RAPTOR: Recursive Abstractive Processing for Tree-Organized Retrieval
Hacker News threads
- Mar 2024Pg_vectorize: Vector search and RAG on Postgres
- Mar 2024Pg_vectorize: Vector search and RAG on Postgres
- Mar 2024Raptor: Recursive Abstractive Processing for Tree-Organized Retrieval
- Mar 2024Show HN: Out-of-the-box text classification models
- May 2024Systematically Improving Your RAG
- May 2024Ask HN: RAG and unstructured data from several docs
- Sep 2024Contextual Retrieval
- Sep 2024Contextual Retrieval
- 152
Prompt Repetition Improves Non-Reasoning LLMs
Hacker News threads
- Jan 2026Prompt Repetition Improves Non-Reasoning LLMs
- Jan 2026Repeating your prompt twice before sending it to an LLM improves accuracy
- Mar 2026Prompt Repetition Improves Non-Reasoning LLMs
- Feb 2026"Car Wash" test with 53 models
- Mar 2026Claude now creates interactive charts, diagrams and visualizations
- Mar 2026LLM Neuroanatomy II: Modern LLM Hacking and Hints of a Universal Language?
- Mar 2026Universal Claude.md – cut Claude output tokens by 63%
- Jul 2026A global workspace in language models
- Sep 2026Jev in 25 Lines of Python
- Sep 2026Lichen – A local, BOY model system1 (Jev) server with image support
- 153
Vending-Bench: A Benchmark for Long-Term Coherence of Autonomous Agents
Hacker News threads
- Apr 2025Vending-Bench: A Benchmark for Long-Term Coherence of Autonomous Agents
- May 2025Vending-Bench: A Benchmark for Long-Term Coherence of Autonomous Agents
- May 2025Vending-Bench: A Benchmark for Long-Term Coherence of Autonomous Agents
- May 2025Professors Staffed a Fake Company with AI Agents, Guess What Happened?
- May 2025Trading with Claude, and writing your own MCP server
- Jun 2025Project Vend: Can Claude run a small shop? (And why does that matter?)
- Jun 2025Project Vend: Can Claude run a small shop? (And why does that matter?)
- Jul 2025Can Large Language Models Play Text Games Well? (2023)
- Jul 2025Ask HN: Why haven't we seen AI as opponents in video games?
- Oct 2025Our LLM-controlled office robot can't pass butter
- 154
Textbooks Are All You Need II: phi-1.5 technical report
Hacker News threads
- Sep 2023The tide is shifting: 1.3B outperforms 7B Llama 2
- Sep 2023Textbooks Are All You Need II: phi-1.5 technical report
- Sep 2023Large Language Models for Compiler Optimization
- Sep 2023Outperforming LLMs with less training data and smaller model sizes
- Oct 2023AI hype is built on high test scores. Those tests are flawed
- Nov 2023A Coder Considers the Waning Days of the Craft
- Nov 2023MonadGPT – What would have happened if ChatGPT was invented in the 17th century?
- Jan 2024Microsoft Phi-2 model changes licence to MIT
- Jan 2024Ten Noteworthy AI Research Papers of 2023
- Jan 2024A Philosophical Introduction to Language Models
- 155
How much do language models memorize?
Hacker News threads
- Jun 2025How much do language models memorize?
- Jun 2025Not all tokens are meant to be forgotten
- Jun 2025A practical guide to building agents [pdf]
- Jun 2025Meta invests $14.3B in Scale AI to kick-start superintelligence lab
- Jun 2025Meta's Llama 3.1 can recall 42 percent of the first Harry Potter book
- Jul 2025Qwen3-Coder: Agentic coding in the world
- Sep 2025California governor signs AI transparency bill into law
- Sep 2026LLMs are real, AI is fake
- 156
Getting from Generative AI to Trustworthy AI: What LLMs might learn from Cyc
Hacker News threads
- Aug 2023Getting from Generative AI to Trustworthy AI: What LLMs Might Learn from Cyc
- Sep 2023Getting from Generative AI to Trustworthy AI: What LLMs Might Learn from Cyc
- Aug 2023Getting from Generative AI to Trustworthy AI: What LLMs Might Learn from Cyc
- Sep 2023Doug Lenat has died
- Sep 2023Recursively Summarizing Enables Long-Term Dialogue Memory in LLMs
- Sep 2023Lenat and Cyc
- Jun 2024ARC Prize – a $1M+ competition towards open AGI progress
- Nov 2024LLMs have reached a point of diminishing returns
- Apr 2025Obituary for Cyc
- 157
Accelerating Self-Play Learning in Go
Hacker News threads
- Nov 2019DeepMind's MuZero teaches itself how to win at Atari, chess, shogi, and Go
- Dec 2019An Epidemic of AI Misinformation
- Jun 2020How much did AlphaGo Zero cost? (2018)
- Jun 2020Much More Efficient Self-Play Learning in Go
- Jun 2020Fast implementation of DeepMind's AlphaZero algorithm in Julia
- Nov 2022Adversarial Policies Beat Professional-Level Go AIs
- 158
Discrete Diffusion Modeling by Estimating the Ratios of the Data Distribution
Hacker News threads
- Feb 2025I think Yann Lecun was right about LLMs (but perhaps only by accident)
- Feb 2025Mercury Coder: frontier diffusion LLM generating 1000+ tok/sec on commodity GPUs
- Mar 2025First large diffusion-based LLM
- Mar 2025Ask HN: Any insider takes on Yann LeCun's push against current architectures?
- May 2025Mercury: Commercial-scale diffusion language model
- May 2025Mercury: Commercial-scale diffusion language model
- Jul 2025Mercury: Ultra-fast language models based on diffusion
- 159
Moshi: a speech-text foundation model for real-time dialogue
Hacker News threads
- 160
Is Model Collapse Inevitable? Breaking the Curse of Recursion by Accumulating Real and Synthetic Data
Hacker News threads
- May 2024Is Model Collapse Inevitable?
- Jul 2024Avoiding Model Collapse via Accumulating Real and Synthetic Data
- Apr 2024Is Model Collapse Inevitable? Breaking the Curse with Real and Synthetic Data
- Jun 2024Gemma 2: Improving Open Language Models at a Practical Size [pdf]
- Dec 2024The Curse of Recursion: Training on generated data makes models forget (2023)
- Aug 2026C2PA Cameras Do Not Survive Contact with Reality
- Aug 2026The turbulent AI era is here
- Sep 2026Everyone should slow down AI development except for me
- Sep 2026Everyone should slow down AI development except for me
- 161
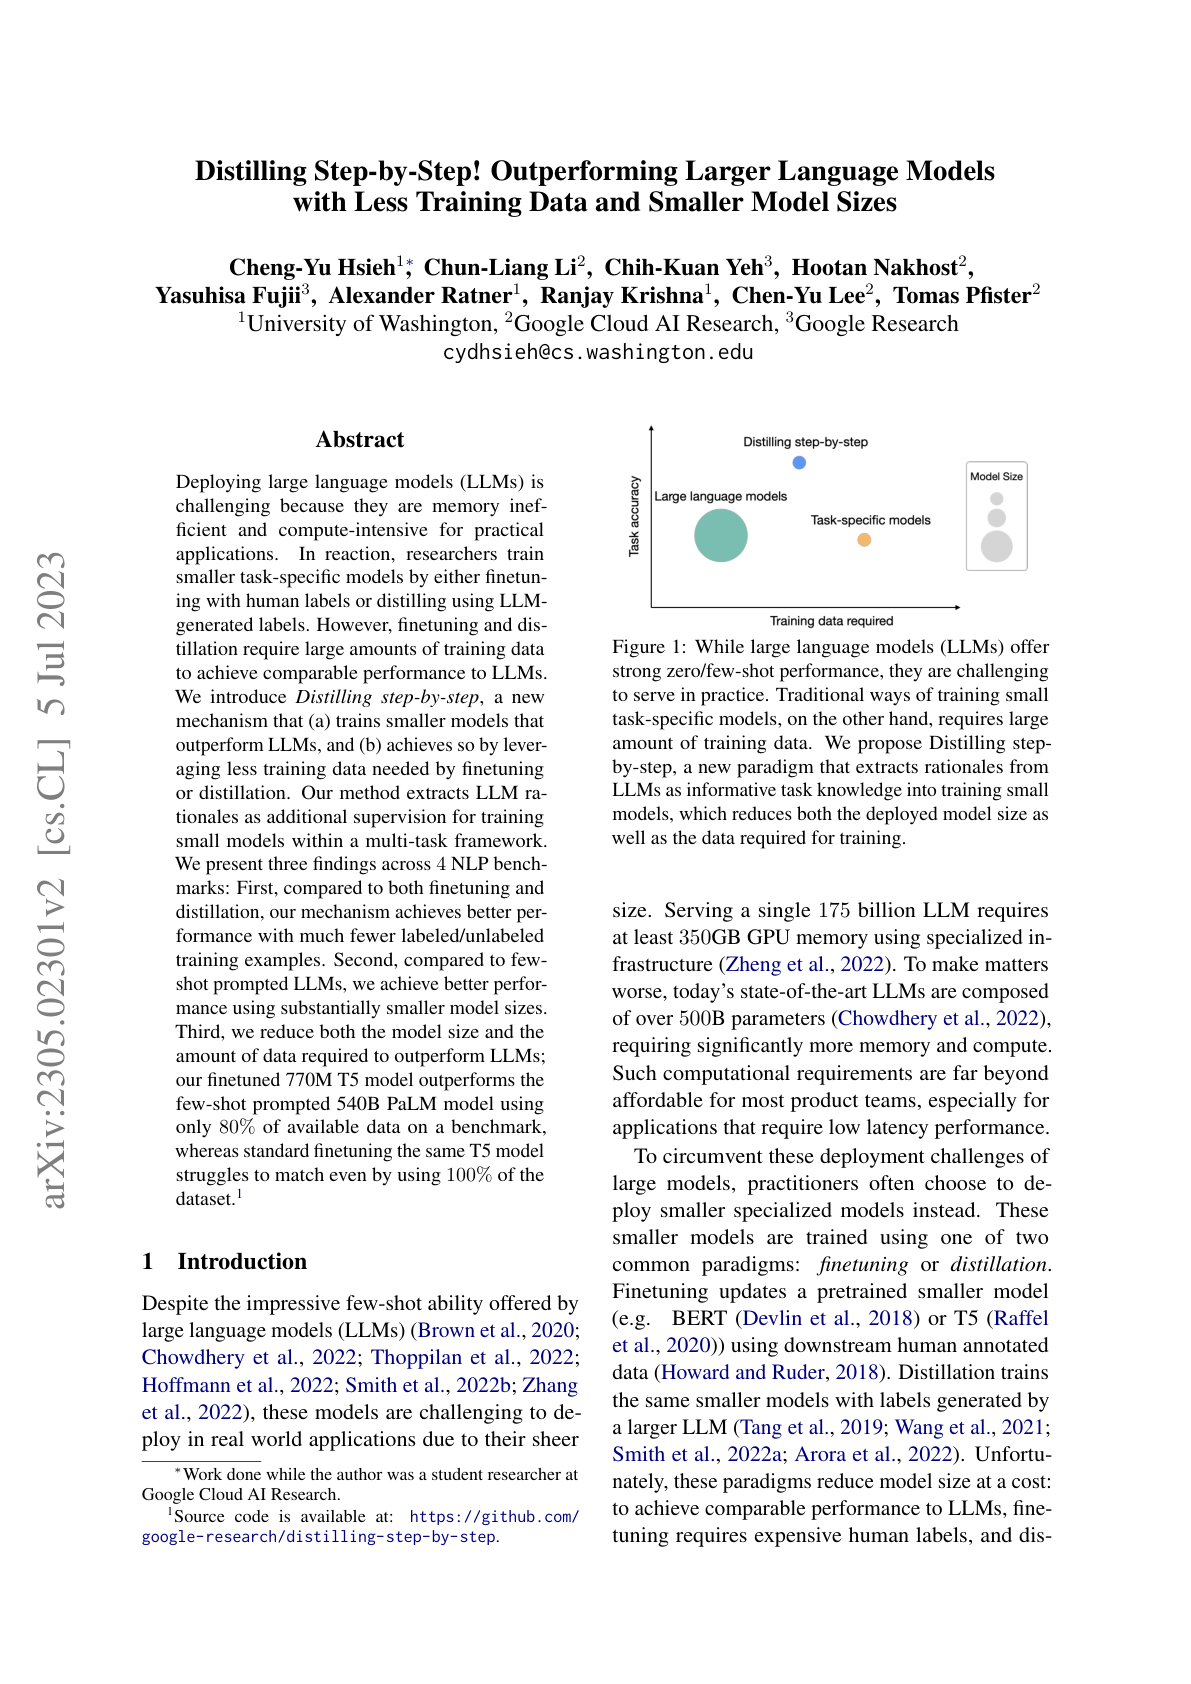
Distilling Step-by-Step! Outperforming Larger Language Models with Less Training Data and Smaller Model Sizes
Hacker News threads
- May 2023Distilling Step-by-Step Outperforming Larger Language Models with Less Training
- May 2023RedPajama (Open LLaMA Replication) 3B and 7B models released
- May 2023PaLM 2 Technical Report [pdf]
- May 2023How to Finetune GPT Like Large Language Models on a Custom Dataset
- Jul 2023
- Dec 2023Phi-2: The surprising power of small language models
- Jan 2025Nvidia’s $589B DeepSeek rout
- 162
Flexible Paxos: Quorum intersection revisited
Hacker News threads
- Aug 2016Flexible Paxos: Quorum intersection revisited
- Aug 2016Flexible Paxos: Quorum intersection revisited
- Mar 2017In search of a simple consensus algorithm
- Mar 2017Paxos in 25 Lines
- Sep 2024Raft: Understandable Distributed Consensus (2014)
- Jan 2025Did we miss P In CAP? Partial Progress Conjecture under Asynchrony
- Aug 2026TigerBeetle Core System Architecture: Deconstructing Performance Engineering
- 163
Let's Verify Step by Step
Hacker News threads
- Sep 2024Let's Verify Step by Step
- Jun 2023OpenAI: How to Train Reasoning in LLMs
- Aug 2024Let's Verify Step by Step
- Nov 2023Yann LeCun: Ignore the deluge of complete nonsense about Q*
- Nov 2023$10M AI Mathematical Olympiad Prize
- Aug 2024The Threat to OpenAI
- Jan 2025Berkeley Researchers Replicate DeepSeek R1's Core Tech for Just $30: A Small Mod
- Sep 2026Astra and Fable still hack on simple variants of alignment evals from 2025
- 164
Vectorized and performance-portable Quicksort
Hacker News threads
- Feb 2024Vectorized and performance-portable Quicksort (2022)
- Jun 2022Vectorized and performance-portable Quicksort
- Jun 2022Vectorized and performance-portable Quicksort
- Jun 2022Apple M2 Die Shot and Architecture Analysis – Big Cost Increase and A15 Based IP
- Dec 2022Sorting with SIMD
- Jan 2023Efficient and performance-portable vector software
- Mar 2024JPEG XL and the Pareto Front
- 165
Transformers learn in-context by gradient descent
Hacker News threads
- Dec 2022Transformers learn in-context by gradient descent
- Jan 2023Do Large Language Models learn world models or just surface statistics?
- Feb 2023ChatGPT Hype Is Proof Nobody Understands AI
- Apr 2023Teaching ChatGPT to Speak My Son’s Invented Language
- Apr 2023GPT-4 gets a B on my quantum computing final exam
- Mar 2025ARC-AGI without pretraining
- 166
Language Models Represent Space and Time
Hacker News threads
- Oct 2023Paper: LLMs have internal world model, and a sense of time and space
- Nov 2023A Coder Considers the Waning Days of the Craft
- Nov 2023Ask HN: Convince me LLMs aren't just autocomplete with lookahead
- Jul 2024ChatGPT Isn't 'Hallucinating'–It's Bullshitting – Scientific American
- Oct 2024Chain-of-thought can hurt performance on tasks where thinking makes humans worse
- Jun 2025The Emperor's New LLM
- 167
Guiding Language Models of Code with Global Context using Monitors
Hacker News threads
- 168
Maximum Flow and Minimum-Cost Flow in Almost-Linear Time
Hacker News threads
- Apr 2022Maximum Flow and Minimum-Cost Flow in Almost-Linear Time
- Mar 2022Maximum Flow and Minimum-Cost Flow in Almost-Linear Time
- Mar 2022Maximum Flow and Minimum-Cost Flow in Almost-Linear Time
- Jun 2022Researchers achieve ‘absurdly fast’ algorithm for network flow
- Jun 2022Researchers achieve ‘absurdly fast’ algorithm for network flow
- Feb 2023Why Sat Is Hard
- Mar 2023Ask HN: What's new in theoretical CS these days?
- Jun 2024Researchers develop the fastest possible flow algorithm
- 169
FNet: Mixing Tokens with Fourier Transforms
Hacker News threads
- May 2024FNet: Mixing Tokens with Fourier Transforms (2021)
- May 2021FNet: Mixing Tokens with Fourier Transforms
- May 2021FNet: Attention may be all you WANT but we you need is good token mixing
- May 2021An Interactive Guide to the Fourier Transform (2012)
- May 2024New attention mechanisms that outperform standard multi-head attention
- May 2024New attention mechanisms that outperform standard multi-head attention
- Feb 2025The FFT Strikes Back: An Efficient Alternative to Self-Attention
- Feb 2025The FFT Strikes Back: An Efficient Alternative to Self-Attention
- Mar 2026TorchLean: Formalizing Neural Networks in Lean
- 170
Extending Context Window of Large Language Models via Positional Interpolation
Hacker News threads
- Jun 2023Extending Context Window of Large Language Models via Positional Interpolation
- Jun 2023XGen-7B, a new 7B foundational model trained on up to 8K length for 1.5T tokens
- Jul 2023Llama 2 – Meta AI
- Jul 2023Llama 2 – Meta AI
- Nov 2023Is anyone using self hosted LLM day to day and training it like a new employee
- Jan 2024Phi-2: Self-Extend Boosts Performance, Extends Context to 8k Without Training
- 171
SynthID-Image: Image watermarking at internet scale
Hacker News threads
- Oct 2025SynthID-Image: Invisibly Watermarking AI-Generated Imagery
- Apr 2026ChatGPT Images 2.0
- May 2026OpenAI Adopts Google's SynthID Watermark for AI Images with Verification Tool
- May 2026OpenAI Adopts Google's SynthID Watermark for AI Images with Verification Tool
- Jun 2026Appreciating Exif
- Oct 2026SynthID Detector
- 172
DeWave: Discrete EEG Waves Encoding for Brain Dynamics to Text Translation
Hacker News threads
- Dec 2023BrainGPT Turns Thoughts into Text
- Dec 2023BrainGPT Turns Thoughts into Text
- Dec 2023BrainGPT Turns Thoughts into Text
- Jun 2024Human neuroscience mustn't forget its human dimension
- May 2025Coding without a laptop: Two weeks with AR glasses and Linux on Android
- Aug 2025Scientists shine a laser through a human head
- 173
Chronofold: a data structure for versioned text
Hacker News threads
- Aug 2021Chronofold: A data structure for versioned text (2020)
- May 2020Chronofold: A data structure for versioned text
- Nov 2020Chronofold: A data structure for versioned text [pdf]
- Jul 2020An Introduction to Conflict-Free Replicated Data Types
- Jul 2020CRDTs: The Hard Parts [video]
- Aug 2020Are CRDTs suitable for shared editing?
- Jul 2021Faster CRDTs: An Adventure in Optimization
- Mar 2026A Coherent Vision for the Future of Version Control
- 174
Infini-gram: Scaling Unbounded n-gram Language Models to a Trillion Tokens
Hacker News threads
- May 2024Infini-Gram: Scaling unbounded n-gram language models to a trillion tokens
- Feb 2024Infini-Gram: Scaling Unbounded N-Gram Language Models to a Trillion Tokens
- Feb 2024Infini-Gram: Scaling unbounded n-gram language models to a trillion tokens
- Feb 2024Markov Chains are the Original Language Models
- Jun 2024Transformers Represent Belief State Geometry in Their Residual Stream
- Nov 2025A new Google model is nearly perfect on automated handwriting recognition
- Nov 2025Ask HN: How are Markov chains so different from tiny LLMs?
- Nov 2025Ask HN: How are Markov chains so different from tiny LLMs?
- Apr 2026Soul Player C64 – A real transformer running on a 1 MHz Commodore 64
- 175
Reinforcement Learning: An Overview
Hacker News threads
- Feb 2025Reinforcement Learning: An Overview
- Dec 2024Reinforcement Learning: An Overview
- Feb 2025RLHF Book
- Mar 2025Mathematical Foundations of Reinforcement Learning
- Mar 2025A (Long) Peek into Reinforcement Learning
- Nov 2025CS234: Reinforcement Learning Winter 2025
- Jun 2026The 90-year-old idea behind JEPA models: Canonical Correlation Analysis
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.