Hacker Papers
- 201
Loss Surfaces, Mode Connectivity, and Fast Ensembling of DNNs
Hacker News threads
- 202
Model soups: averaging weights of multiple fine-tuned models improves accuracy without increasing inference time
Hacker News threads
- Dec 2024Beyond Gradient Averaging in Parallel Optimization
- Mar 2026NanoGPT Slowrun: Language Modeling with Limited Data, Infinite Compute
- Jun 2026Rio de Janeiro's "homegrown" LLM appears to be a merge of an existing model
- Jun 2026Rio de Janeiro's "homegrown" LLM appears to be a merge of an existing model
- 203
Magic: The Gathering is Turing Complete
Hacker News threads
- May 2019Magic: The Gathering is Turing Complete
- Dec 2023Magic: The Gathering Is Turing Complete (2019)
- Feb 2022Magic: The Gathering is Turing Complete (2019)
- Aug 2019Rediscovering rules for ancient board games
- Jun 2020How the Magic: The Gathering Color Wheel Explains Humanity
- Jun 2022AI Is Ushering in a New Scientific Revolution
- Dec 2022“Magic: The Gathering” is officially the world’s most complex game
- Jul 2023Show HN: Marsha – An LLM-Based Programming Language
- Dec 2023I Hacked Magic the Gathering: Arena for a 100% Win Rate
- Sep 2024Deal infinite damage for 4GRU, as long as the twin primes conjecture is true
- Jun 2026MTG Bench: Testing how well LLMs can play magic
- 204
Talent vs Luck: the role of randomness in success and failure
Hacker News threads
- Mar 2018Talent vs. Luck: the role of randomness in success and failure
- Jul 2018Talent vs. Luck: the role of randomness in success and failure
- Mar 2018Talent vs. Luck: the role of randomness in success and failure
- Mar 2018The Role of Luck in Life Is Still Misunderstood
- Apr 2018Show HN: AI Grant – Get $2,500 for your AI project in minutes
- Oct 2018The annoying habits of highly effective people
- Dec 2019Economists Are Rethinking the Numbers on Inequality
- Sep 2020Six Figures in 6 days
- Jun 2021Why Success is more Luck than Hard Work
- Oct 2023Private Equity Is Devouring the U.S. Economy
- Jun 2026Hacker News actively blocking SpaceX IPO submissions
- 205
Formal Algorithms for Transformers
Hacker News threads
- Jul 2022Formal Algorithms for Transformers
- Jan 2023The Transformer Family
- Apr 2023A Baby GPT
- Apr 2023What Are Transformer Models and How Do They Work?
- May 2023Ask HN: Can someone ELI5 Transformers and the “Attention is all we need” paper
- Jul 2023What We Know About LLMs (A Primer)
- Dec 2023"Attention", "Transformers", in Neural Network "Large Language Models"
- Jan 2024Relearning math as an adult
- Jun 2026Can I Buy Your KV Cache?
- 206
Making AI Less "Thirsty": Uncovering and Addressing the Secret Water Footprint of AI Models
Hacker News threads
- Jan 2025"GPT training in U.S. data centers can evaporate 700k L of freshwater"
- Mar 2025Making AI Less Thirsty: Uncovering and Addressing the Secret AI Water Footprint
- Mar 2024Uncovering and Addressing the Secret Water Footprint of AI Models
- Jun 2023ChatGPT requires half a liter of water to have a conversation
- Sep 2024A bottle of water per email: the hidden environmental costs of using AI chatbots
- Sep 2024A bottle of water per email: the hidden environmental costs of using AI chatbots
- Sep 2024A bottle of water per email: the hidden environmental costs of using AI chatbots
- Apr 2025Bored of It
- Nov 2025AGI fantasy is a blocker to actual engineering
- May 2026AI Uses Less Water Than the Public Thinks
- Jun 2026Amazon Says Its Data Centers Use 2.5B Gallons of Water
- 207
What Has a Foundation Model Found? Using Inductive Bias to Probe for World Models
Hacker News threads
- Jul 2025LLMs fail to demonstrate internal world model, according to Harvard/MIT study
- Jul 2025AGI Is Mathematically Impossible (3): Kolmogorov Complexity
- Aug 2025Persona vectors: Monitoring and controlling character traits in language models
- Oct 2025Andrej Karpathy – It will take a decade to work through the issues with agents
- Jun 2026ΠFS
- 208
Mission Apollo: Landing Optical Circuit Switching at Datacenter Scale
Hacker News threads
- 209
Model Cards for Model Reporting
Hacker News threads
- Jul 2020Yann LeCun quits Twitter amid acrimonious exchanges on AI bias
- Jul 2020Yann LeCun quits Twitter amid acrimonious exchanges on AI bias
- Aug 2023AI Nutrition Facts
- Dec 2023Will scaling work?
- Dec 2024OpenAI o1 system card
- Jul 2025ChatGPT agent System Card [pdf]
- May 2026Grok 4.3
- Jun 2026System Card: Claude Fable 5 and Claude Mythos 5 [pdf]
- 210
A Neural Conversational Model
Hacker News threads
- Jun 2015A Neural Conversational Model [pdf]
- Jun 2015A Neural Conversational Model [pdf]
- Jul 2015Getting closer to 'Ex Machina' – A Neural Conversational Model by Google[pdf]
- Jun 2015Artificial Intelligence Machine Gets Testy with Its Programmer
- Aug 2015A Beginner’s Guide to Restricted Boltzmann Machines
- Jan 2016BotLibre – Free Open Artificial Intelligence for Everyone
- Mar 2016Generating Factoid Questions with RNNs: The 30M Factoid Question-Answer Corpus
- Jun 2016The truth about deep learning
- Nov 2016Show HN: Spamnesty: Waste spammers' time
- Jan 2020Towards a conversational agent that can chat about anything
- Jun 2026What was your "Oh Shit" moment with GenAI?
- 211
Failure of Normalization in Impredicative Type Theory with Proof-Irrelevant Propositional Equality
Hacker News threads
- 212
The Hardware Lottery
Hacker News threads
- Sep 2020The Hardware Lottery
- Sep 2020The Hardware Lottery
- Sep 2020The Hardware Lottery
- Nov 2020Ride the Hardware Lottery
- Apr 2022Large-Scale Matrix Factorization on TPUs
- Jul 2023Ask HN: Which recently research paper blow your mind?
- Oct 2023Nvidia and Foxconn to build 'AI factories'
- Dec 2023A new old kind of R&D lab
- Apr 2025Multi-Token Attention
- May 2026A Eureka machine that thinks like nature and explores what AI cannot
- Jun 2026How LLMs Work
- 213
The SWE-Bench Illusion: When State-of-the-Art LLMs Remember Instead of Reason
Hacker News threads
- Sep 2025The SWE-Bench Illusion: When LLMs Remember Instead of Reason
- Feb 2026The SWE-Bench Illusion: When LLMs Remember Instead of Reason
- Jul 2025Principles for production AI agents
- Aug 2025Open models by OpenAI
- Sep 2025Using Claude Code to modernize a 25-year-old kernel driver
- Sep 2025Top model scores may be skewed by Git history leaks in SWE-bench
- Feb 2026Prediction: Claude 5 will be a major regression
- Mar 2026FSF Threatens Anthropic over Infringed Copyright: Share Your LLMs Freel
- Jun 2026Did Claude Increase Bugs in Rsync?
- 214
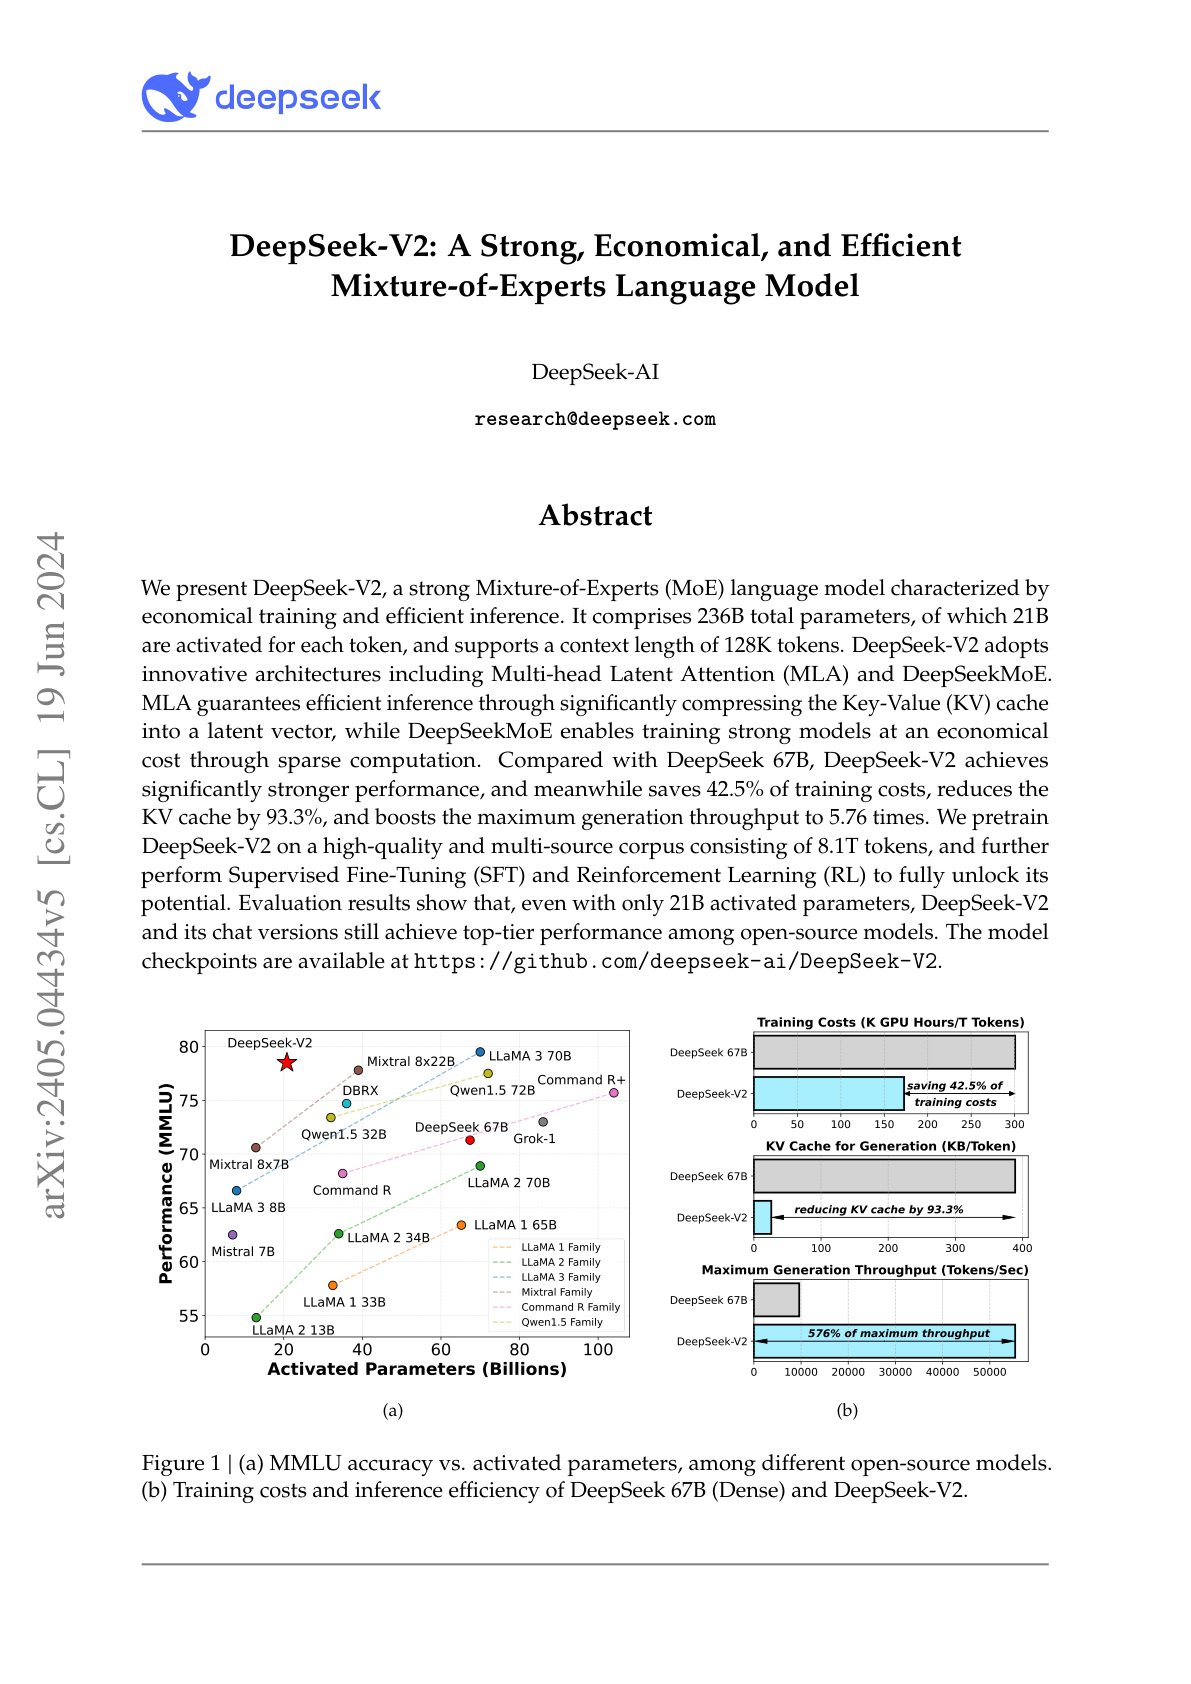
DeepSeek-V2: A Strong, Economical, and Efficient Mixture-of-Experts Language Model
Hacker News threads
- Jan 2025DeepSeek-V2: A Strong, Economical, and Efficient MOE Language Model
- Jan 2025DeepSeek's multi-head latent attention and other KV cache tricks
- Apr 2025Xiaomi MiMo Reasoning Model
- May 2025Attention Wasn't All We Needed
- Dec 2025Zebra-Llama – Towards efficient hybrid models
- Dec 2025Google Titans architecture, helping AI have long-term memory
- Jun 2026How LLMs Work
- 215
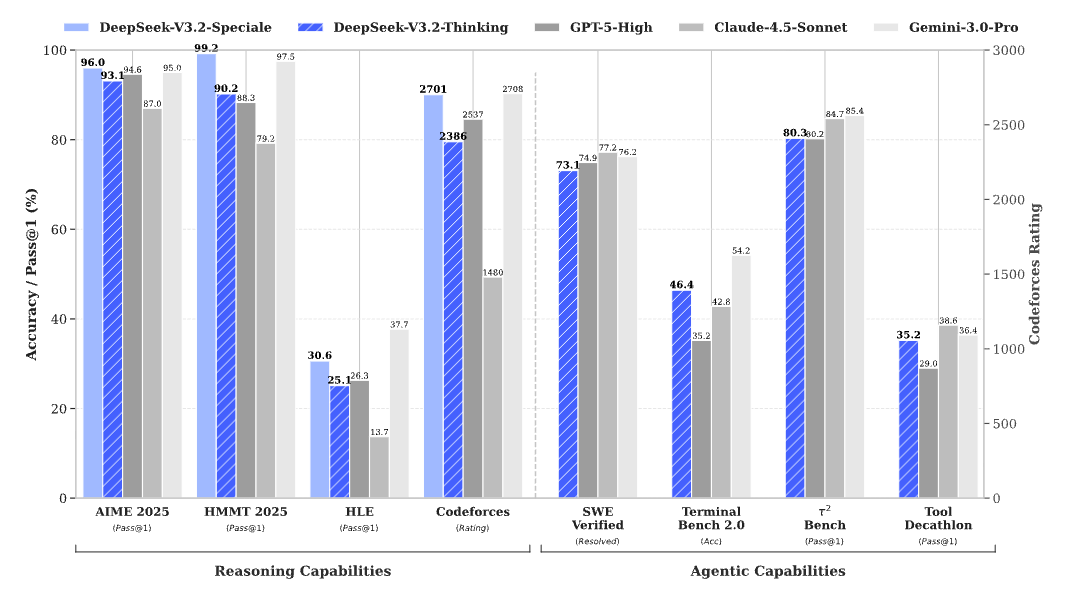
DeepSeek-V3.2: Pushing the Frontier of Open Large Language Models
Hacker News threads
- 216
MLP-Mixer: An all-MLP Architecture for Vision
Hacker News threads
- Sep 2021MLP-Mixer: An All-MLP Architecture for Vision
- May 2021MLP-Mixer: An All-MLP Architecture for Vision
- May 2021X-Transformers: A fully-featured transformer with experimental features
- Nov 2023MeshGPT: Generating Triangle Meshes with Decoder-Only Transformers
- Jun 2026Do transformers need three projections? Systematic study of QKV variants
- 217
The Case for Learned Index Structures
Hacker News threads
- Dec 2017The Case for Learned Index Structures
- Dec 2017The Case for Learned Index Structures
- Dec 2017The Case for Learned Index Structures
- Dec 2017Machine Learning for Systems and Systems for Machine Learning [pdf]
- Dec 2017My Favorite Papers of 2017
- Feb 2018Chip advances require fresh ideas, speakers say
- May 2018An O(N) Sorting Algorithm: Machine Learning Sorting
- Nov 2018Optimal Shard Placement in a Petabyte Scale Elasticsearch Cluster
- Oct 2020Using Lidar to Add Autofocus to a Manual Focus Lens
- Jul 2022Ask HN: What are some cool but obscure data structures you know about?
- Jun 2026"They're made out of weights"
- 218
Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
Hacker News threads
- Jul 2022Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- May 2023Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- Apr 2023Grokking: Generalization Beyond Overfitting on Small Algorithmic Datasets
- Feb 2022I asked GPT-NeoX-20B a hundred arithmetic questions
- Apr 2022Socratic Models – Composing Zero-Shot Multimodal Reasoning with Language
- Feb 2023Jailbreaking ChatGPT with Dan (Do Anything Now)
- Apr 2023DyLoRA: Parameter Efficient Tuning of Pre-Trained Models
- Aug 2023Do Machine Learning Models Memorize or Generalize?
- May 2024Groq surpasses 1,200 tokens/sec with Llama 3 8B
- Feb 2026Who discovered grokking and why is the name hard to find?
- Jun 2026"They're made out of weights"
- 219
Neural Networks and the Chomsky Hierarchy
Hacker News threads
- Jul 2022Neural Networks and the Chomsky Hierarchy by DeepMind
- Jan 2023Neural Networks and the Chomsky Hierarchy [DeepMind, 2022]
- Aug 2022Deep Learning Alone Isn’t Getting Us to Human-Like AI
- Feb 2023What Is ChatGPT Doing and Why Does It Work?
- Apr 2023Tighter bounds on the expressivity of transformer encoders
- May 2023Ask HN: Why can GPT4 en/decode base64?
- Jun 2023Bard is getting better at logic and reasoning
- Jun 2023Modern language models refute Chomsky’s approach to language
- Nov 2024Interview with gwern
- Jun 2026No, Artificial Intelligence is not Conscious - Ted Chiang
- 220
The Design Principles of the Elixir Type System
Hacker News threads
- Jun 2026The design principles of the Elixir type system
- Sep 2023The Design Principles of the Elixir Type System
- Oct 2023The Design Principles of the Elixir Type System
- Nov 2023Elixir at Ramp
- May 2024Elixir and Machine Learning in 2024 so far: MLIR, Arrow, structured LLM, etc.
- Jun 2024Elixir 1.17 released: set-theoretic types in patterns, durations, OTP 27
- Nov 2025Why we migrated from Python to Node.js
- 221
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Hacker News threads
- Oct 2018BERT: Pre-Training of Deep Bidirectional Transformers for Language Understanding
- Apr 2023Bert: Pre-Training of Deep Bidirectional Transformers for Language Understanding
- Nov 2018TensorFlow Code for Google Research's BERT: Pre-Training Method for NLP Tasks
- Feb 2019Microsoft’s New MT-DNN Outperforms Google BERT
- Mar 2019Yann LeCun, Geoffrey Hinton and Yoshua Bengio win Turing Award
- Sep 2019At Tech’s Leading Edge, Worry About a Concentration of Power
- Mar 2023Google internally developed chatbots like ChatGPT years ago
- Jul 2023Ask HN: How to Break into AI Engineering
- Oct 2023Ask HN: Why is OpenAI still called OpenAI?
- Jun 2026Superintelligence: The Idea That Eats Smart People (2016)
- 222
What is algebraic about algebraic effects and handlers?
Hacker News threads
- 223
Memory Augmented Large Language Models are Computationally Universal
Hacker News threads
- Jul 2023Memory Augmented Large Language Models Are Computationally Universal
- Feb 2023Memory Augmented Large Language Models Are Computationally Universal
- Mar 2023Memory Augmented Large Language Models Are Computationally Universal
- Feb 2023Our Society Is Not Prepared for This Much AI Awesome
- Mar 2023Show HN: Whatdoesthiscodedo.com – AI explanations for other people’s code
- Apr 2023Teaching ChatGPT to Speak My Son’s Invented Language
- Apr 2023Large Language Models: Scaling Laws and Emergent Properties
- May 2023Anthropic - Introducing 100K Token Context Windows, Around 75,000 Words
- Oct 2023Ask HN: Why are current LLMs not considered AGI?
- Sep 2025Markov chains are the original language models
- May 2026Claude Opus 4.8
- 224
Jewish Problems
Hacker News threads
- Oct 2011Jewish problems
- Oct 2017These problems were designed to prevent Jewish people from passing (2011)
- Jan 2016Jewish problems (2011)
- Feb 2012Harvard, Princeton Targeted in Asian Discrimination Probe
- Nov 2013Silicon Valley Isn’t a Meritocracy
- Jun 2018Harvard Is Wrong That Asians Have Terrible Personalities
- Jul 2020Ridiculous Math Problems
- Sep 2020Over 90% of Indian techies in the US are upper-caste Indians
- Jun 2022The case for expanding rather than eliminating gifted education programs (2021)
- Feb 2024David Hahn, the 'radioactive boy scout' who tried to build a nuclear reactor (2022)
- May 2026Why American Parents Send Their Kids to 'Russian Math' (2017)
- 225
DreamCoder: Growing generalizable, interpretable knowledge with wake-sleep Bayesian program learning
Hacker News threads
- Dec 2023DreamCoder: Growing Generalizable, Interpretable Knowledge
- Jun 2020DreamCoder: Growing generalizable, interpretable knowledge with program learning
- Feb 2021DreamCoder, a system that learns to solve problems by writing programs
- Dec 2020Ask HN: What's the best paper you've read in 2020?
- May 2021Kobra – visual programming language for machine learning
- Nov 2021GPT-3 is no longer the only game in town
- Feb 2022Competitive Programming with AlphaCode
- Feb 2022Competitive Programming with AlphaCode
- Jul 2022AI Coding with CodeRL: Toward Mastering Program Synthesis with Deep RL
- Sep 2023Doug Lenat has died
- May 2026Language Models Need Sleep
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.