Hacker Papers
- 201
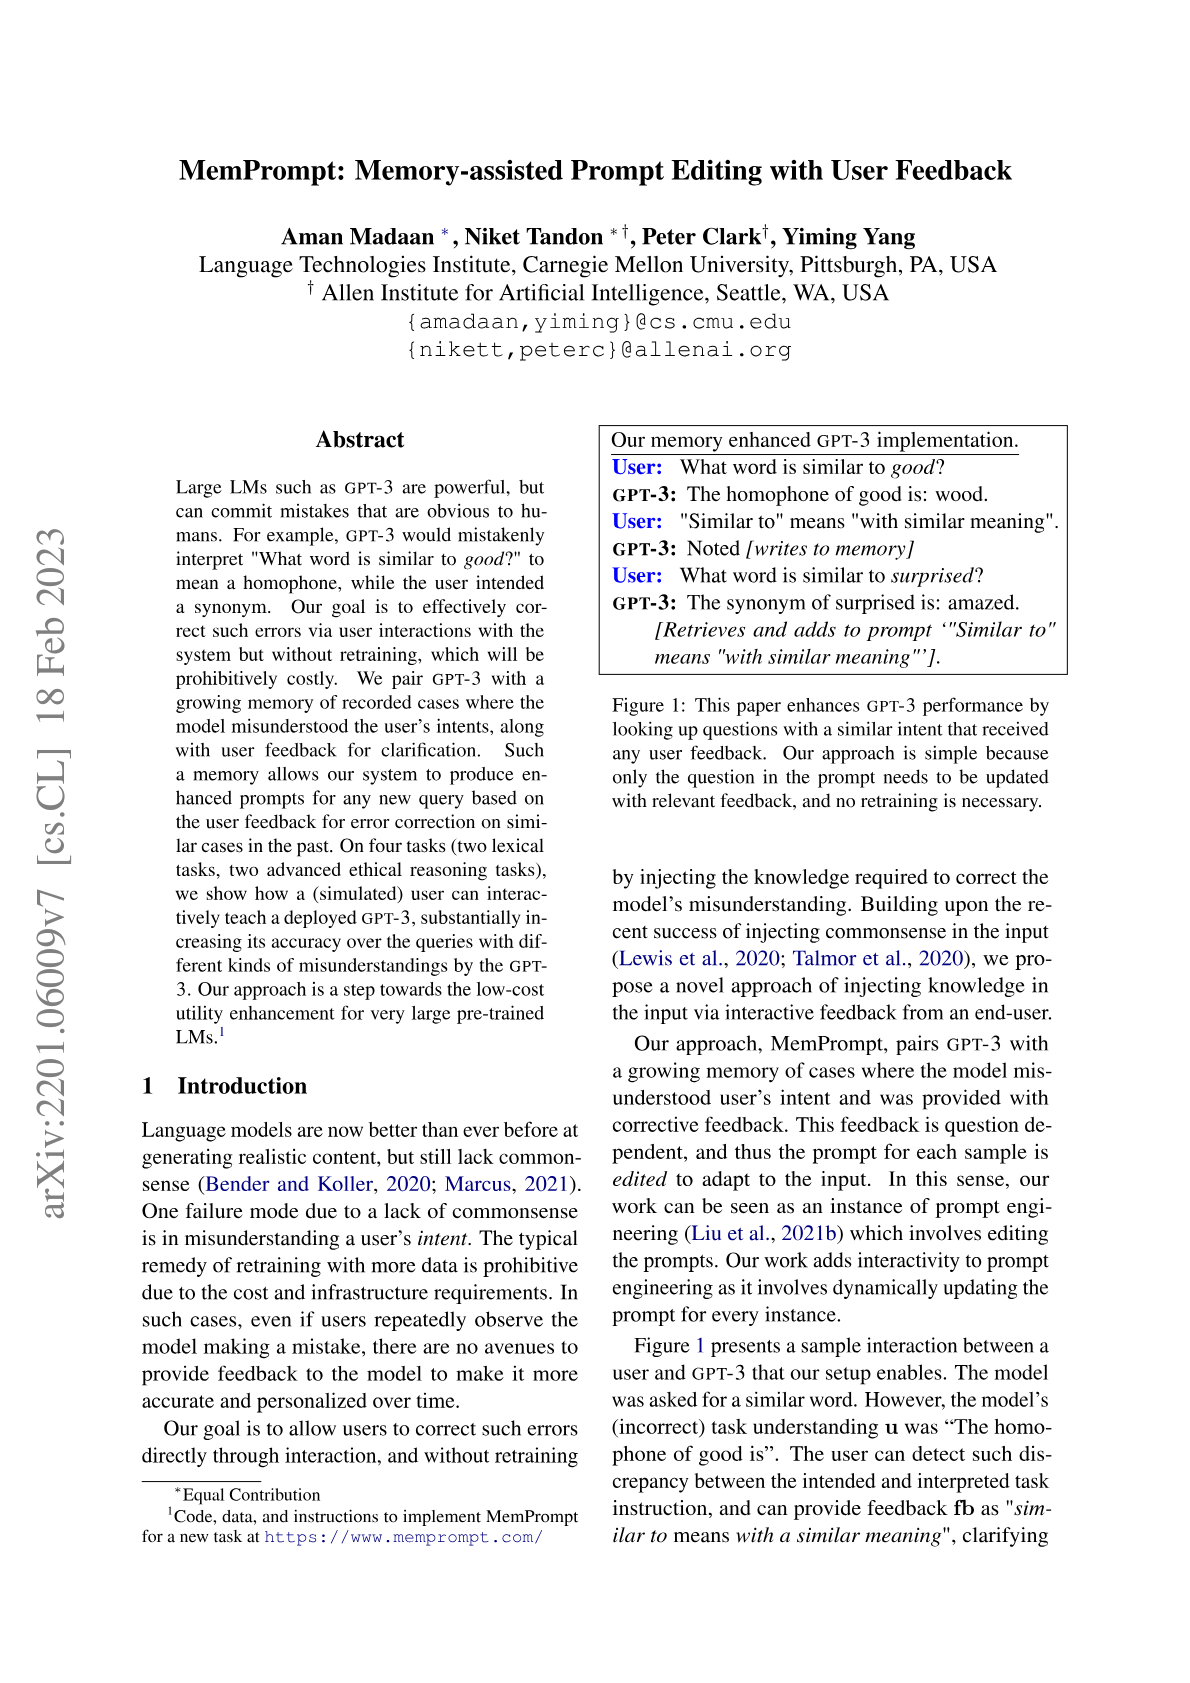
Memory-assisted prompt editing to improve GPT-3 after deployment
Hacker News threads
- Mar 2022GPT-3 can run code
- Dec 2022Building a Virtual Machine Inside ChatGPT
- Jan 2023What Is AGI-Hard
- 202
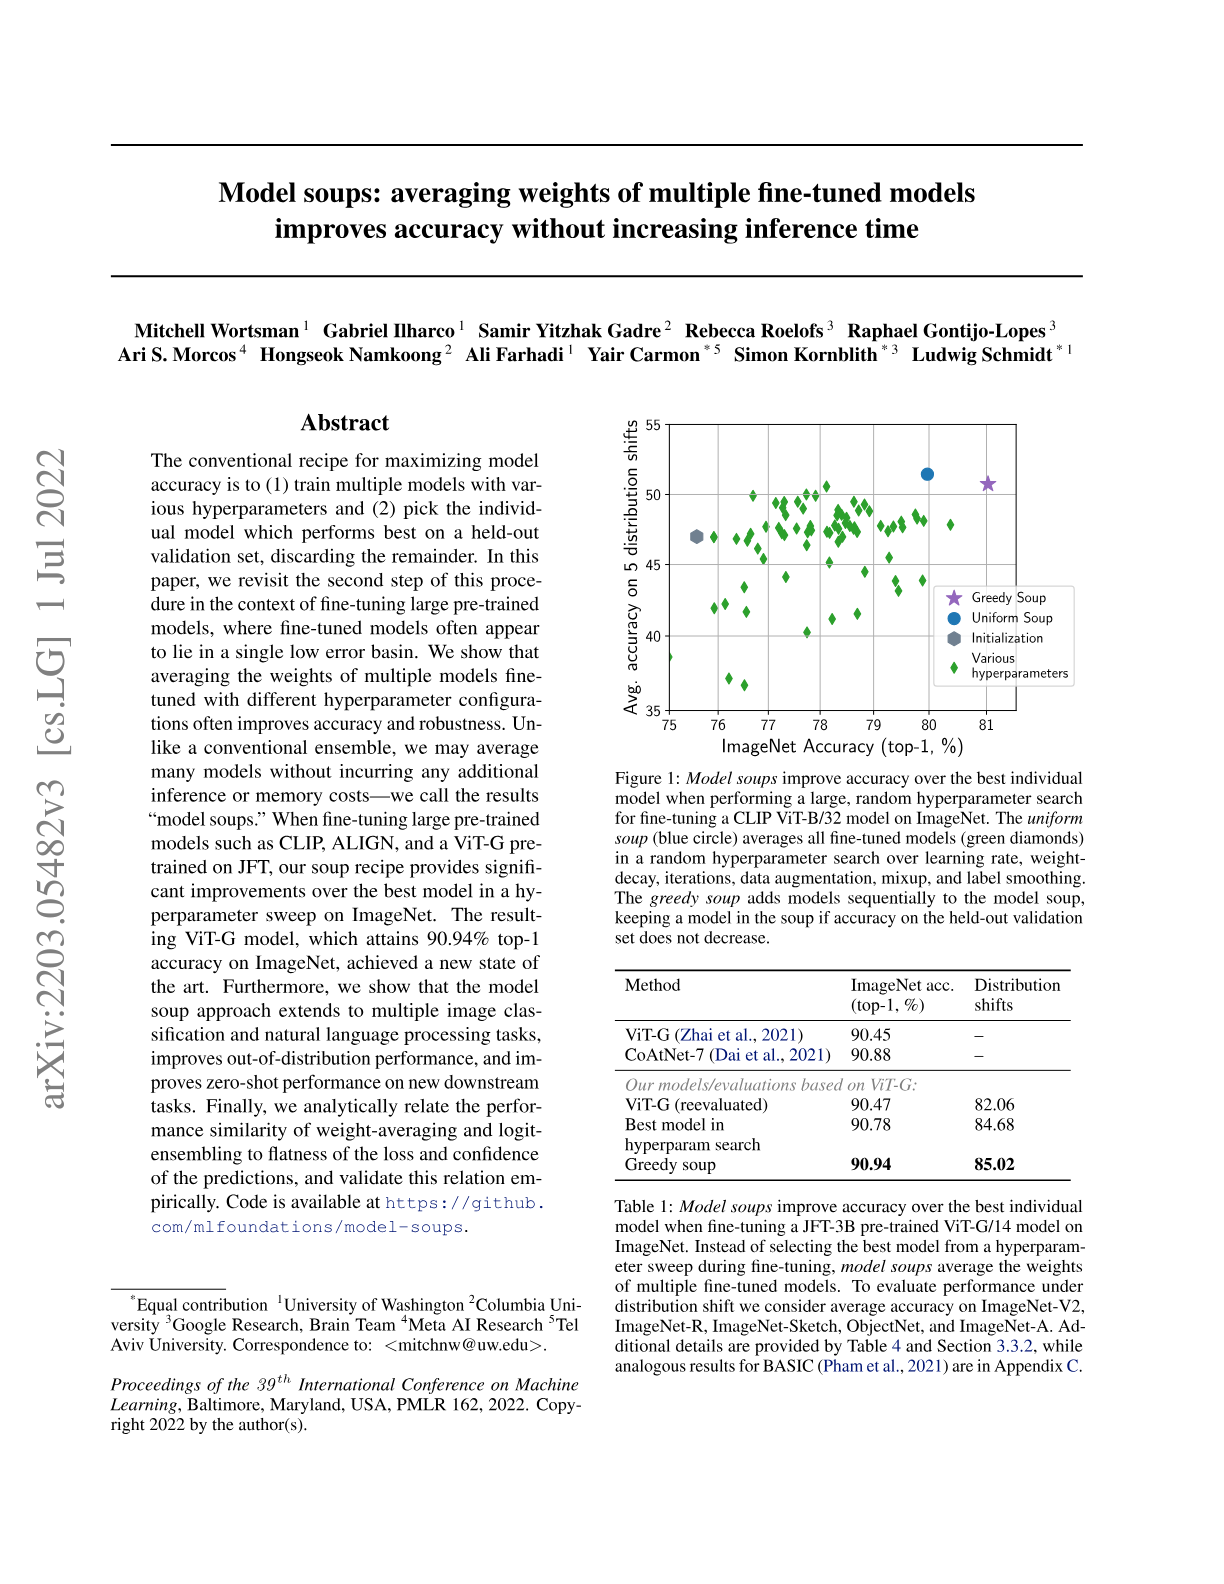
Model soups: averaging weights of multiple fine-tuned models improves accuracy without increasing inference time
Hacker News threads
- Dec 2024Beyond Gradient Averaging in Parallel Optimization
- Mar 2026NanoGPT Slowrun: Language Modeling with Limited Data, Infinite Compute
- Jun 2026Rio de Janeiro's "homegrown" LLM appears to be a merge of an existing model
- Jun 2026Rio de Janeiro's "homegrown" LLM appears to be a merge of an existing model
- 203
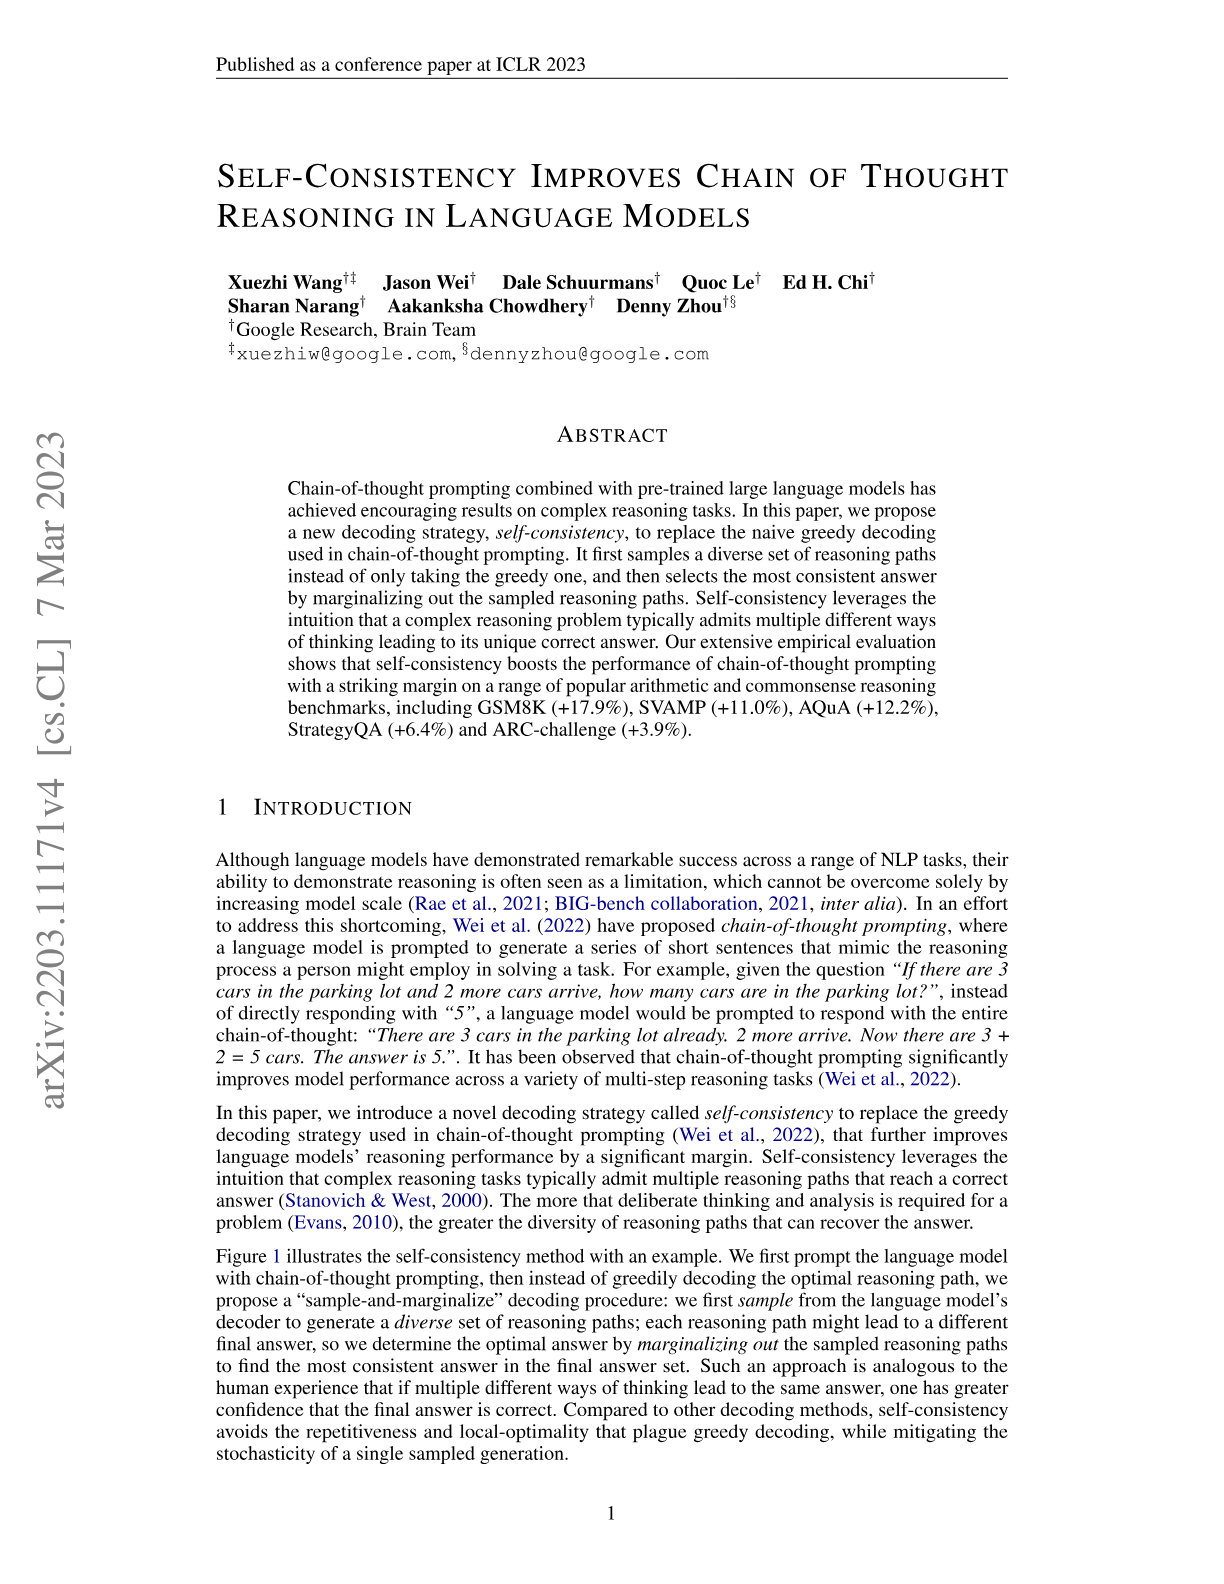
Self-Consistency Improves Chain of Thought Reasoning in Language Models
Hacker News threads
- 204
Flamingo: a Visual Language Model for Few-Shot Learning
Hacker News threads
- 205
Suppressing quantum errors by scaling a surface code logical qubit
Hacker News threads
- 206
Game-theoretic statistics and safe anytime-valid inference
Hacker News threads
- 207
Flow Matching for Generative Modeling
Hacker News threads
- 208
Efficiently Scaling Transformer Inference
Hacker News threads
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.