Hacker Papers
- 01
Consciousness in Artificial Intelligence: Insights from the Science of Consciousness
Hacker News threads
- Aug 2023Consciousness in AI: Insights from the Science of Consciousness
- Aug 2023Consciousness in Artificial Intelligence: Insights from the Science of Con
- Aug 2023Consciousness in AI: Insights from the Science of Consciousness
- Aug 2023If AI becomes conscious: here’s how researchers will know
- Nov 2023Ask HN: What are your most used Chat GPT prompts
- Nov 2023Cats That Fetch Are an Evolutionary Mystery
- Dec 2023The Singularity Is Nigh!
- Mar 2024Claude 3 claims it's conscious
- Dec 2025Do We Need Human-Like AI?
- Oct 2026Are stochastic parrots alive?
- 02
Language Modeling Is Compression
Hacker News threads
- Sep 2023Language Modeling Is Compression
- Sep 2023Language Modeling Is Compression
- Sep 2023Language Modeling Is Compression
- Sep 2023Show HN: 78% MNIST accuracy using GZIP in under 10 lines of code
- Jan 2024Getting Lossless Compression Adopted for Rigorous LLM Benchmarking
- Apr 2024EURISKO Lives
- May 2025The copilot delusion
- Jun 2025Fine-tuning LLMs is a waste of time
- Jan 2026Show HN: AI in SolidWorks
- Jun 2026Dune's Butlerian Jihad and the Future of AI
- Oct 2026OpenAI and Anthropic cut their LLM prices by up to 80% within a few months. Why?
- 03
Language Models Don't Always Say What They Think: Unfaithful Explanations in Chain-of-Thought Prompting
Hacker News threads
- May 2023Unfaithful Explanations in Chain-of-Thought Prompting
- May 2023“Just a statistical text predictor”
- Dec 2024Training LLMs to Reason in a Continuous Latent Space
- Feb 2025Modern-Day Oracles or Bullshit Machines? How to thrive in a ChatGPT world
- Apr 2025Can reinforcement learning for LLMs scale beyond math and coding tasks? Probably
- Jul 2025Chain of thought monitorability: A new and fragile opportunity for AI safety
- Nov 2025Google Antigravity
- Oct 2026DeepSeek-v4.1-Flash-1017
- 04
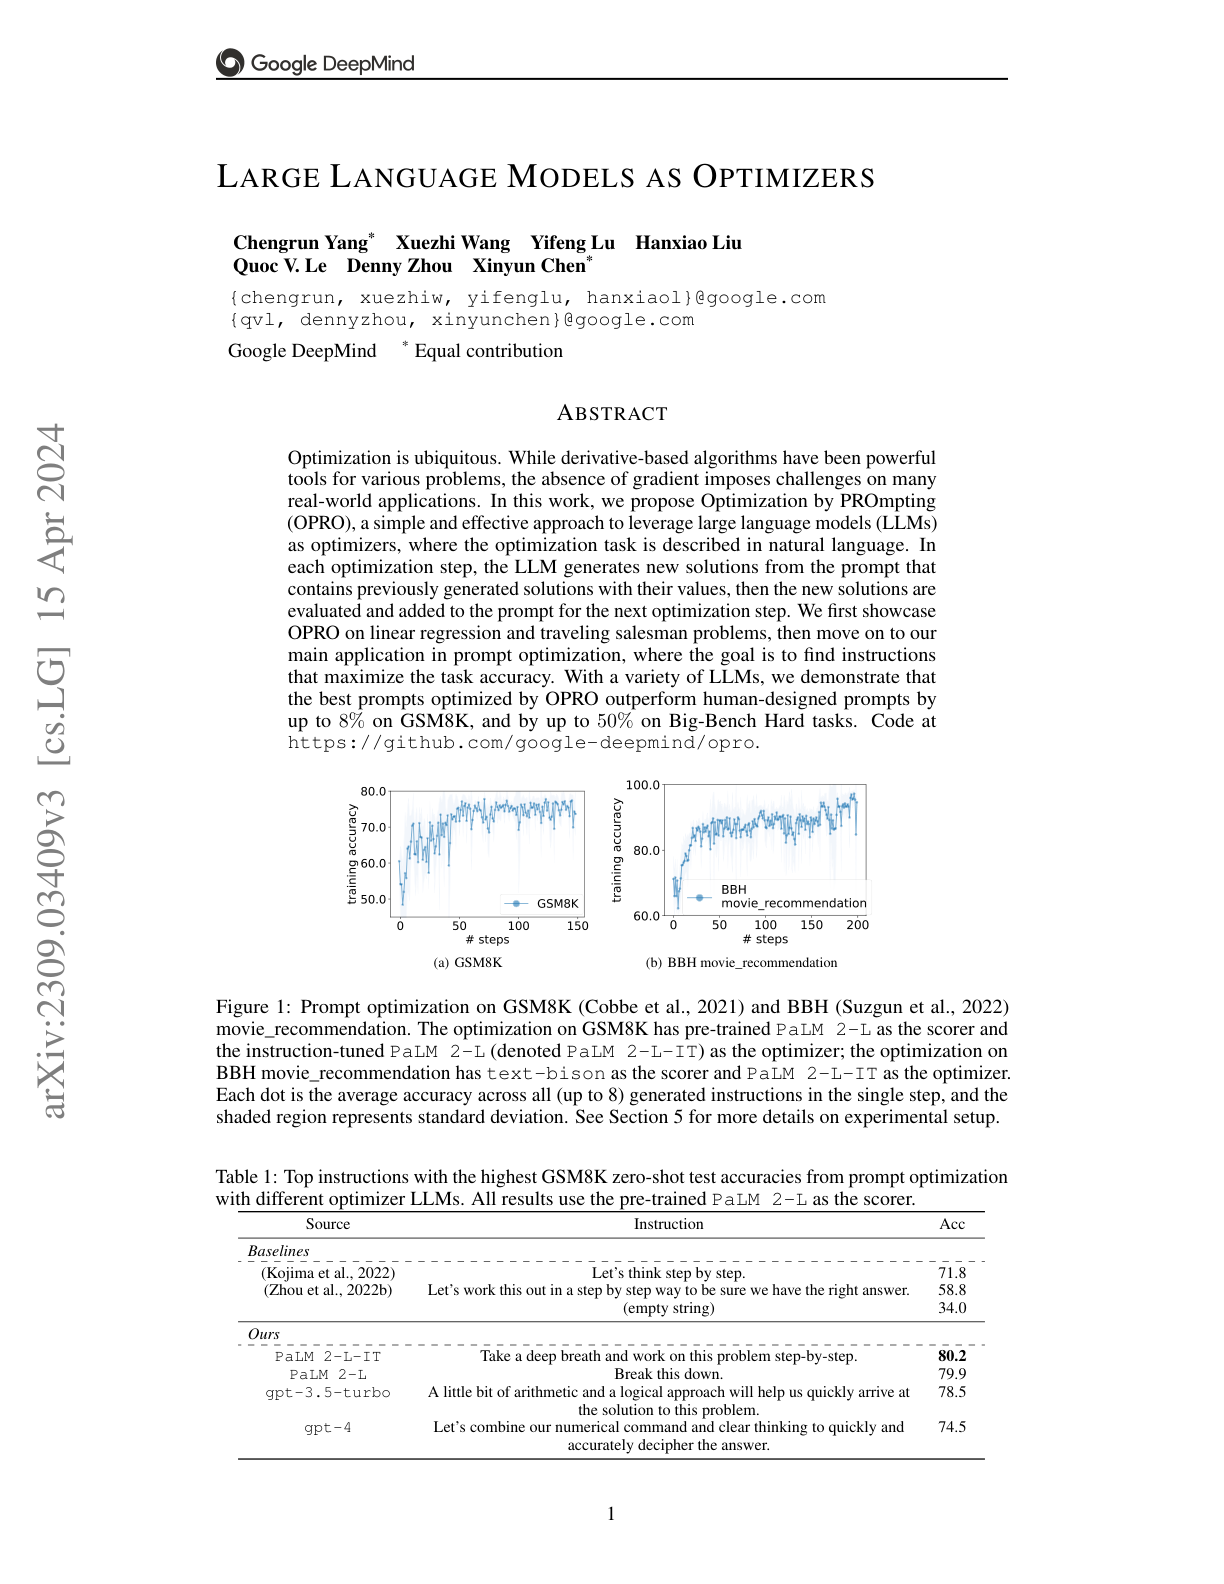
Large Language Models as Optimizers
Hacker News threads
- 05
GPT-4 Technical Report
Hacker News threads
- Apr 2023GPT-4 Technical Report
- Mar 2023OpenAI: GPT-4 Technical Report
- Mar 2023GPT-4 is Computer Vision on Steroids
- Mar 2023The danger isn’t that AI destroys us. It’s that it drives us insane
- Apr 2023We need to tell people ChatGPT will lie to them, not debate linguistics
- May 2023ChatGPT-Authored Legal Filing “Replete with Citations to Non-Existent Cases"
- Jul 2023Claude 2
- Jan 2024Using GPT-4 as a probabilistic classifier
- Apr 2024Meta Llama 3
- Oct 2026Why do LLM pelicans look like this?
- 06
The Impact of Positional Encoding on Length Generalization in Transformers
Hacker News threads
- Jun 2023The Impact of Positional Encoding on Length Generalization in Transformers
- Aug 2024The Impact of Positional Encoding on Length Generalization in Transformers
- Apr 2025The Llama 4 herd
- Apr 2025Llama 4 Now Live on Groq
- Jul 2025LLM Embeddings Explained: A Visual and Intuitive Guide
- Oct 2026Is 'Attention' the Essence of Intelligence?
- 07
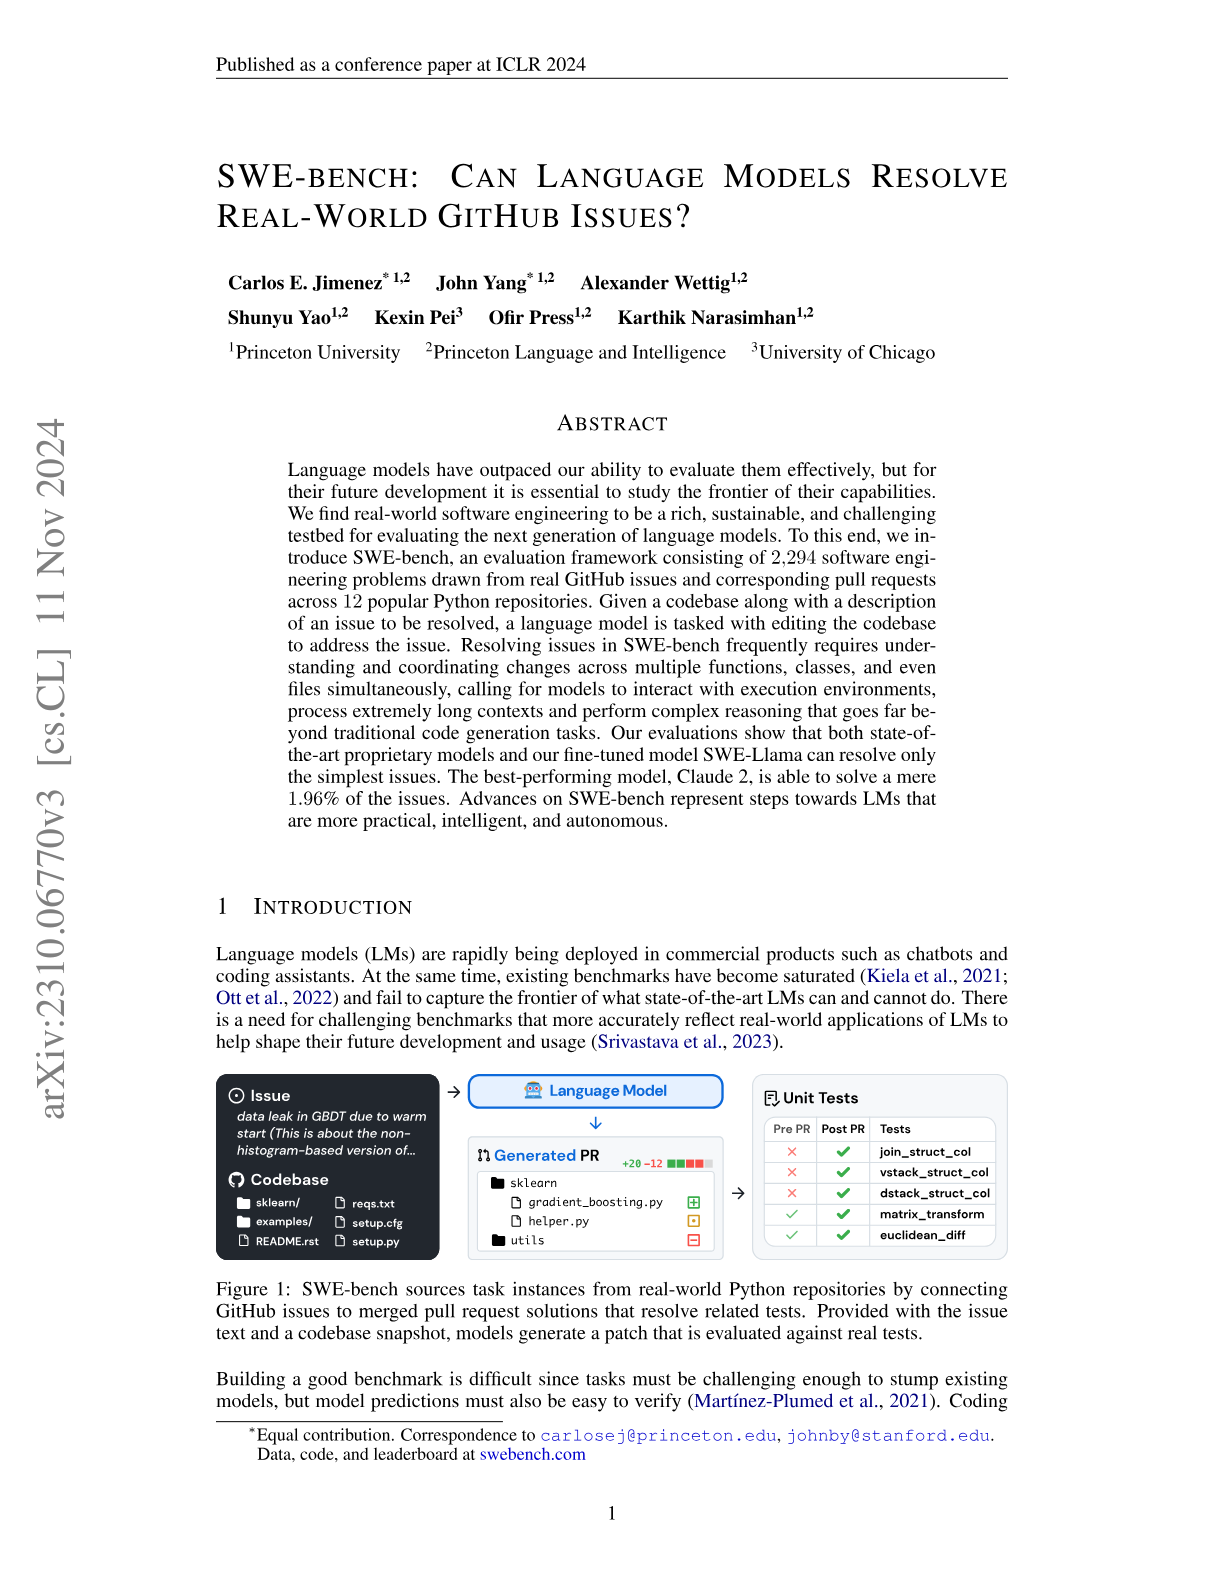
SWE-bench: Can Language Models Resolve Real-World GitHub Issues?
Hacker News threads
- Oct 2023SWE-Bench: Can Language Models Resolve Real-World GitHub Issues?
- Feb 2024SWE-BENCH: Can language models resolve real-world GitHub issues?
- Jan 2024Researchers say generative AI isn't replacing devs any time soon
- Sep 2025Top model scores may be skewed by Git history leaks in SWE-bench
- Dec 2025Django: what’s new in 6.0
- Mar 2026Ask HN: Does code style matter much anymore?
- Oct 2026Agents don't need memory, they need documentation
- 08
TPU v4: An Optically Reconfigurable Supercomputer for Machine Learning with Hardware Support for Embeddings
Hacker News threads
- Apr 2023TPU v4: An Optically Reconfigurable Supercomputer for Machine Learning
- Apr 2023TPU v4 provides exaFLOPS-scale ML with industry-leading efficiency
- May 2023Google Launches AI Supercomputer Powered by Nvidia H100 GPUs
- May 2023Google Launches AI Supercomputer Powered by Nvidia H100 GPUs
- May 2023MTIA v1: Meta’s first-generation AI inference accelerator
- May 2023Nvidia DGX GH200: The First 100 Terabyte GPU Memory System
- May 2025OpenTPU: Open-Source Reimplementation of Google Tensor Processing Unit (TPU)
- Jun 2025Basic Facts about GPUs
- Oct 2026Homa: The end of TCP for AI clusters [video]
- 09
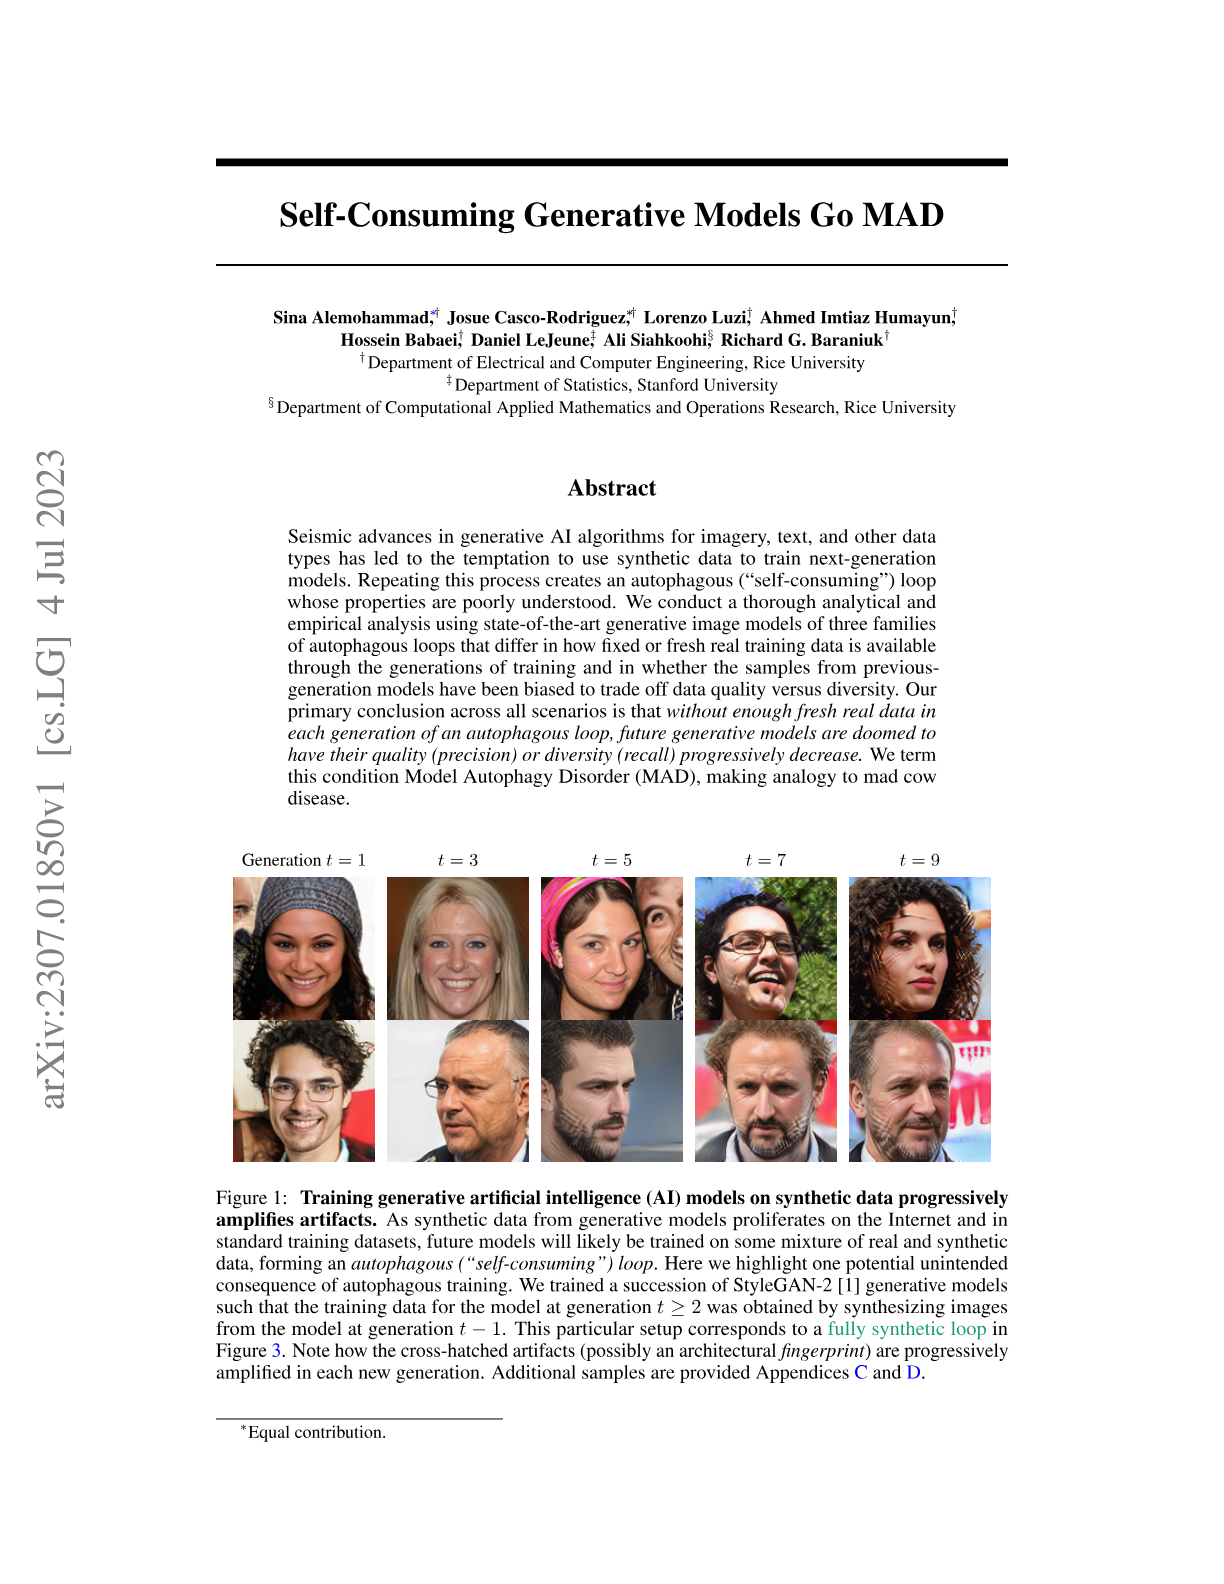
Self-Consuming Generative Models Go MAD
Hacker News threads
- Jan 2024Self-Consuming Generative Models Go MAD
- Aug 2023Self-Consuming Generative Models Go Mad
- Jul 2023AI Loses Its Mind After Being Trained on AI-Generated Data
- Jul 2023AI Loses Its Mind After Being Trained on AI-Generated Data
- Oct 2023Why Generative AI Is Currently Doomed
- Apr 2024Google Books Is Indexing AI-Generated Garbage
- Jul 2024AI models collapse when trained on recursively generated data
- Sep 2026Nvidia wants to put a watchdog chip next to every AI agent
- 10
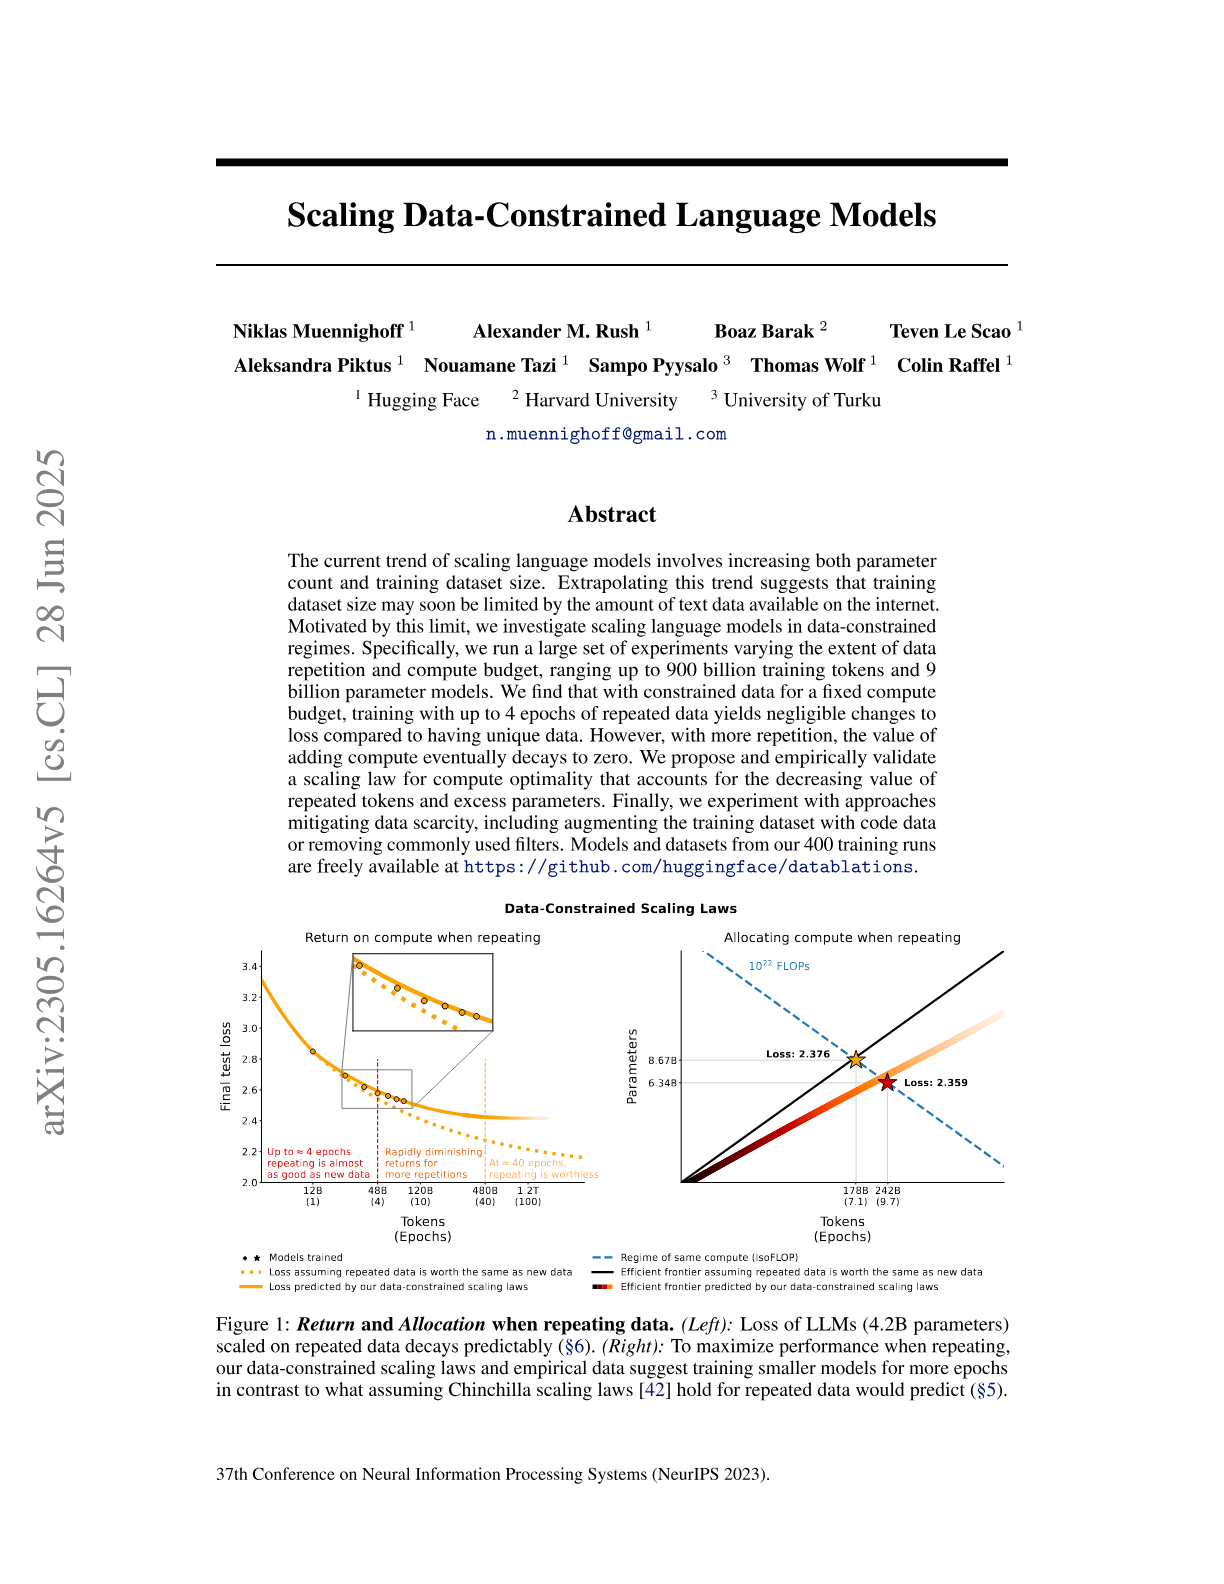
Scaling Data-Constrained Language Models
Hacker News threads
- May 2023Scaling Data-Constrained Language Models
- Sep 2023Chinchilla’s Death
- Sep 2023Can LLMs learn from a single example?
- Sep 2023Can LLMs learn from a single example?
- Aug 2024IsoFLOP curves of large language models are flat
- Jan 2025FrontierMath was funded by OpenAI
- Sep 2026Nvidia wants to put a watchdog chip next to every AI agent
- 11
TinyStories: How Small Can Language Models Be and Still Speak Coherent English?
Hacker News threads
- Jan 2025TinyStories: How Small Can Language Models Be and Still Speak Coherent English? (2023)
- May 2023TinyStories: How Small Can Language Models Be and Still Speak Coherent English?
- May 2023How Small Can Language Models Be and Still Speak Coherent English?
- May 2023Apple bans ChatGPT use by employees, report says
- Jun 2023Modern language models refute Chomsky’s approach to language
- Jun 2023The Darwinian argument for worrying about AI
- Oct 2023Disney Packed Big Emotion into a Little Robot
- Jan 2024Ten Noteworthy AI Research Papers of 2023
- May 2024“Imprecise” language models are smaller, speedier, and nearly as accurate
- Nov 2025Ask HN: How are Markov chains so different from tiny LLMs?
- Sep 2026MicroLLM Lab – Try 7 tiny LLM's in the browser
- 12
Are Emergent Abilities of Large Language Models a Mirage?
Hacker News threads
- May 2023Are Emergent Abilities of Large Language Models a Mirage?
- Feb 2026Are Emergent Abilities of Large Language Models a Mirage? (2023)
- May 2023Scary 'Emergent' AI Abilities Are Just a 'Mirage', Stanford Study Says
- Jun 2023OpenLLaMA 13B Released
- Dec 2023Emergent Abilities of Large Language Models
- Mar 2024Elon Musk sues Sam Altman, Greg Brockman, and OpenAI [pdf]
- Apr 2024Choose your weapon: Survival strategies for depressed AI academics
- May 2025Why do LLMs have emergent properties?
- Mar 2026Are LLMs not getting better?
- Sep 2026AI companies in race to demonstrate their model most threatening to humanity
- 13
How is ChatGPT's behavior changing over time?
Hacker News threads
- Jul 2023How is ChatGPT's behavior changing over time?
- Jul 2023(Databricks cofounder) How Is ChatGPT’s Behavior Changing over Time?
- Jul 2023How is ChatGPT's behavior changing over time?
- Jul 2023GPT-4 is getting worse over time, not better
- Aug 2023Why is OpenAI making ChatGPT increasingly dumber? What's the motivation?
- Aug 2023Azure ChatGPT: Private and secure ChatGPT for internal enterprise use
- Aug 2023Show HN: Beating GPT-4 on HumanEval with a fine-tuned CodeLlama-34B
- Sep 2023Study shows over time, ChatGPT lost accuracy
- Mar 2024DBRX: A new open LLM
- Apr 2026Claude Opus 4.7 costs 20–30% more per session
- Sep 2026Ember-1
- 14
Direct Preference Optimization: Your Language Model is Secretly a Reward Model
Hacker News threads
- Jan 2024Direct Preference Optimization: Your Language Model Is a Reward Model
- May 2023RLFH Alternative Direct Preference Optimization
- May 2023Direct Preference Optimization: Your Language Model Is a Reward Model
- May 2023Ask HN: What's the best self hosted/local alternative to GPT-4?
- Jun 2023How RLHF Works
- Dec 2023Ask HN: AI/ML papers to catch up with current state of AI?
- Jan 2024Self-rewarding-lm-PyTorch: Self-Rewarding Language Model from MetaAI
- Aug 2025Dispelling misconceptions about RLHF
- Jun 2026I design with Claude more than Figma now
- Sep 2026Ask HN: Any nerds out there who've read a lot of research papers?
- 15
Let's Verify Step by Step
Hacker News threads
- Sep 2024Let's Verify Step by Step
- Jun 2023OpenAI: How to Train Reasoning in LLMs
- Aug 2024Let's Verify Step by Step
- Nov 2023Yann LeCun: Ignore the deluge of complete nonsense about Q*
- Nov 2023$10M AI Mathematical Olympiad Prize
- Aug 2024The Threat to OpenAI
- Jan 2025Berkeley Researchers Replicate DeepSeek R1's Core Tech for Just $30: A Small Mod
- Sep 2026Astra and Fable still hack on simple variants of alignment evals from 2025
- 16
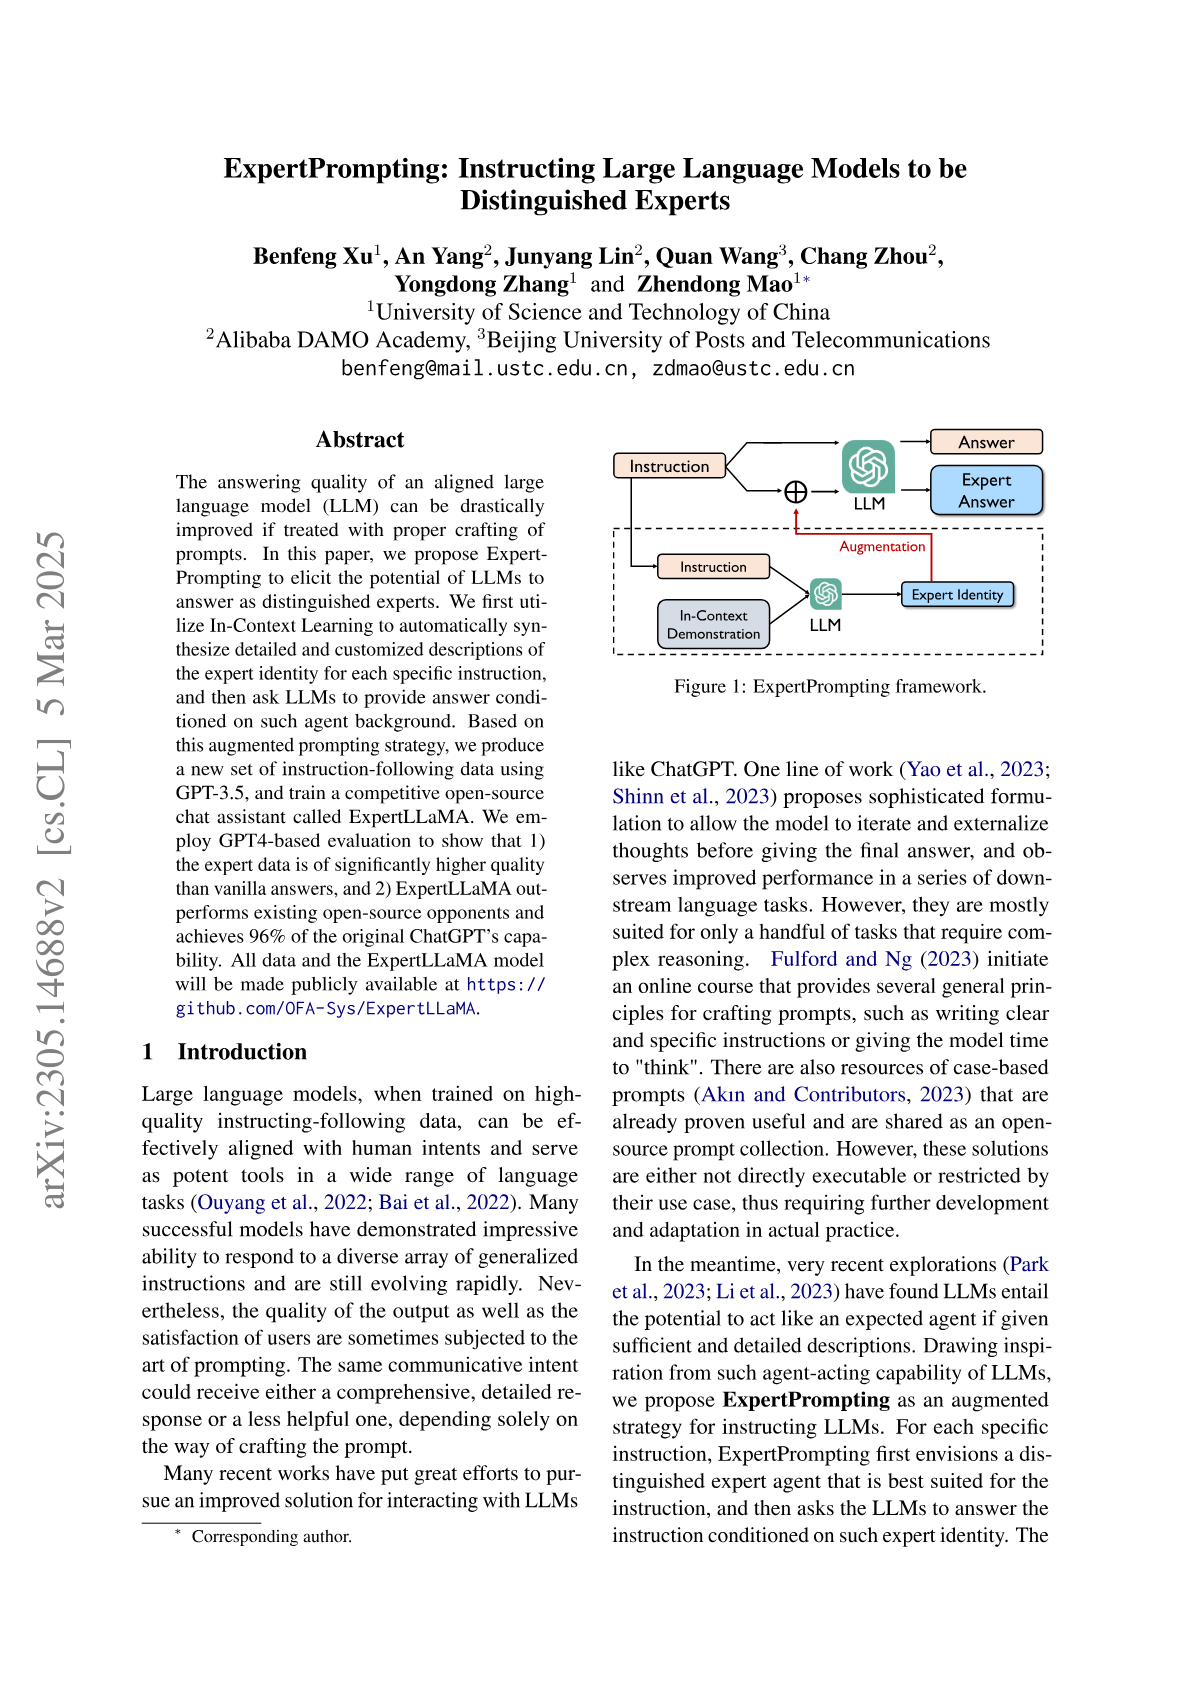
ExpertPrompting: Instructing Large Language Models to be Distinguished Experts
Hacker News threads
- 17
Lost in the Middle: How Language Models Use Long Contexts
Hacker News threads
- Jan 2026Lost in the Middle: How Language Models Use Long Contexts (2023)
- Jul 2023Lost in the Middle: How Language Models Use Long Contexts
- Aug 2023Language models use long contexts
- Jul 2023Llama 32K Context Released by Together AI
- Aug 2023What's new in Llama 2 and how to run it locally
- Sep 2023A Comprehensive Guide for Building Rag-Based LLM Applications
- Oct 2023Microsoft says GPT 3.5 has 20B parameters?
- Nov 2023Benchmarking GPT-4 Turbo – A Cautionary Tale
- Apr 2024LLMs and the Harry Potter problem
- Jul 2026OpenAI reduces Codex Model Context Size from 372k to 272k
- Aug 2026Serve Markdown to AI Agents with Accept Headers
- 18
LLM in a flash: Efficient Large Language Model Inference with Limited Memory
Hacker News threads
- Jan 2024LLM in a Flash: Efficient Large Language Model Inference with Limited Memory
- Dec 2023LLM in a Flash: Efficient Large Language Model Inference with Limited Memory
- Dec 2023LLM in a Flash: Efficient Large Language Model Inference with Limited Memory
- Dec 2023Apple Announces LLM in a Flash: Efficient LLM Inference with Limited Memory
- Dec 2023Apple wants AI to run directly on its hardware instead of in the cloud
- Dec 2023Show HN: Emu2 – A Gemini-like open-source 37B Multimodal Model
- Dec 2023Ferret: A Multimodal Large Language Model
- Mar 2024Towards 1-bit Machine Learning Models
- Mar 2026Qwen3.5-397B at 4.74 tok/s using 5.9GB RAM
- Mar 2026iPhone 17 Pro Demonstrated Running a 400B LLM
- Aug 2026New Mac Studio with M5 Max and M5 Ultra
- 19
Large Language Models Cannot Self-Correct Reasoning Yet
Hacker News threads
- Nov 2023LLMs cannot self-correct reasoning yet
- Oct 2023LLMs can't self-correct in reasoning tasks, DeepMind study finds
- Oct 2023GPT-4 Understands
- Apr 2024The question that no LLM can answer and why it is important
- Aug 2024OpenDevin: An Open Platform for AI Software Developers as Generalist Agents
- Mar 2025Show HN: We made an MCP server so Cursor can debug Node.js on its own
- Aug 2026Dutch lawyer fined €2,300 for using AI-hallucinated citation
- 20
Emergent Representations of Program Semantics in Language Models Trained on Programs
Hacker News threads
- May 2023Evidence of Meaning in Language Models Trained on Programs
- May 2023Evidence of Meaning in Language Models Trained on Programs
- Jun 2023Evidence of Meaning in Large Language Models Trained on Programs
- May 2023Governance of Superintelligence
- Jun 2023The bigger-is-better approach to AI is running out of road
- Aug 2024Markov chains are funnier than LLMs
- Aug 2026If your agent commits a crime, who is responsible?
- 21
Generative Agents: Interactive Simulacra of Human Behavior
Hacker News threads
- Apr 2023Generative Agents: Interactive Simulacra of Human Behavior
- Apr 2023Generative Agents: Interactive Simulacra of Human Behavior
- Apr 2023Stanford's Groundbreaking AI Study Simulates Authentic Human Behavior
- Apr 2023We aren't close to creating a rapidly self-improving AI
- Jul 2023Roleplaying with LLMs
- Sep 2023Show HN: WhatsApp-Llama: A clone of yourself from your WhatsApp conversations
- Oct 2023Lamini LLM Finetuning on AMD ROCm: A Technical Recipe
- Nov 2024Project Sid: Many-agent simulations toward AI civilization
- Jan 2026
- Aug 2026Self hosted email continues to steeply decline
- 22
A Watermark for Large Language Models
Hacker News threads
- Jan 2023A Watermark for Large Language Models
- Aug 2026A Watermark for Large Language Models
- Jan 2023A Watermark for Large Language Models
- Jan 2023New AI classifier for indicating AI-written text
- Mar 2023Mark Zuckerberg: “Please Resign” (2010)
- Jul 2023A.I. Companies Agree to Safeguards After Pressure from the White House
- Jul 2024Meta Launches AI Studio in US
- Aug 2026How Claude marks AI-generated content
- Aug 2026How Claude marks AI-generated content
- Aug 2026Text AI watermarks will always be trivial to remove
- Aug 2026Anthropic's 'Watermark' Text Adulteration in Claude Is a Perversion of Writing
- 23
Can AI-Generated Text be Reliably Detected?
Hacker News threads
- Mar 2023Can AI-Generated Text Be Reliably Detected?
- Mar 2023Research shows we can only accurately identify AI writers about 50% of the time
- Apr 2023Show HN: Pledge Your Human-Made Content
- Jul 2023OpenAI Quietly Shuts Down Its AI Detection Tool
- Apr 2024OpenAI's comment to the NTIA on open model weights
- Sep 2025Show HN: AI Code Detector – detect AI-generated code with 95% accuracy
- Aug 2026How Claude marks AI-generated content
- Aug 2026Anthropic's 'Watermark' Text Adulteration in Claude Is a Perversion of Writing
- 24
Textbooks Are All You Need
Hacker News threads
- Jun 2023Textbooks are all you need
- Jun 2023Textbooks is all you need: new LLM 51% HumanEval. Better one >10x more params
- Jun 2023The Darwinian argument for worrying about AI
- Jul 2023Which GPU(s) to Get for Deep Learning
- Sep 2023Optimizing LLMs from a Dataset Perspective
- Oct 2023Firefox tooltip bug fixed after 22 years
- Nov 2023OpenAI Announces Leadership Transition
- Jul 2024Apple says it uses no Nvidia GPUs to train its AI models
- Aug 2026Qwen 3.8 27B is out: open weights, best local dense model yet
- 25
The Reversal Curse: LLMs trained on "A is B" fail to learn "B is A"
Hacker News threads
- Jun 2026The Reversal Curse: LLMs trained on "A is B" fail to learn "B is A"
- Oct 2023LLMs can't self-correct in reasoning tasks, DeepMind study finds
- Nov 2023Transformers struggle with generalizing tasks beyond pre-training data
- Nov 2023Greg Brockman quits OpenAI
- Jan 2024New theory suggests LLMs can understand text
- Jul 2024Mistral NeMo
- Nov 2025Learn Prolog Now (2006)
- Jul 2026A global workspace in language models
- Aug 2026Tim Gowers: What sort of maths are LLMs good at?
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.