Hacker Papers
- 01
Persistent Pre-Training Poisoning of LLMs
Hacker News threads
- 02
Let Me Speak Freely? A Study on the Impact of Format Restrictions on Performance of Large Language Models
Hacker News threads
- Aug 2024A Study on the Impact of Structured Output on Performance of LLMs
- Aug 2024A Study on the Impact of Format Restrictions on Performance of LLM
- Aug 2024A Study on the Impact of Format Restrictions on Performance of LLMs
- Aug 2024Structured Outputs in the API
- Sep 2024Show HN: Best Practices for Using Structured Output from LLMs
- Sep 2025Sampling and structured outputs in LLMs
- Jul 2026How to stop Claude from saying load-bearing
- Aug 2026Why does Opus 5 feel worse to work with?
- Oct 2026Fixing Tool-Call Accuracy in vLLM
- 03
Refusal in Language Models Is Mediated by a Single Direction
Hacker News threads
- Jun 2024Refusal in language models is mediated by a single direction
- May 2026Refusal in Language Models Is Mediated by a Single Direction
- Jul 2024Explainability is not a game
- Nov 2025Heretic: Automatic censorship removal for language models
- Nov 2025Heretic: Automatic censorship removal for language models
- Jul 2026OpenAI and Hugging Face partner to address security incident
- Sep 2026US Military had close call after using AI for hallucinated intelligence report
- Sep 2026Pirate Face Rescues LLM Models from Deletion
- Sep 2026Pirate Face Rescues LLM Models from Deletion
- Oct 2026IBM CEO says open weight models are now good and cheap on-prem
- 04
Sleeper Agents: Training Deceptive LLMs that Persist Through Safety Training
Hacker News threads
- Jan 2024Sleeper Agents: Training Deceptive LLMs That Persist Through Safety Training
- Jan 2024AI poisoning could turn open models into destructive "sleeper agents"
- Jan 2024Two-Faced AI Language Models Learn to Hide Deception
- Jun 2024Anthropic: Expanding Access to Claude for Government
- Sep 2025Mistral raises 1.7B€, partners with ASML
- Oct 2025NIST's DeepSeek "evaluation" is a hit piece
- Jun 2026The OnlyFans Economy of American AI
- Aug 2026Your Open Source Model Could Have a Hidden Time-Release Backdoor
- Oct 2026DeepSeek banned from U.S. federal civilian agencies under new DHS order
- 05
Byte Latent Transformer: Patches Scale Better Than Tokens
Hacker News threads
- May 2025Byte latent transformer: Patches scale better than tokens (2024)
- Dec 2024Tokenisation Is NP-Complete
- Dec 2024Show HN: I made a website to semantically search ArXiv papers
- Feb 2025Ask HN: Is anybody building an alternative transformer?
- May 2025Tokenization for language modeling: BPE vs. Unigram Language Modeling (2020)
- Jun 2026"They're made out of weights"
- Jun 2026Data Compression Explained
- Sep 2026When did Google get so weird?
- Oct 2026Retrofitting language models to operate over bytes
- 06
Should We Respect LLMs? A Cross-Lingual Study on the Influence of Prompt Politeness on LLM Performance
Hacker News threads
- Apr 2025Should We Respect LLMs? A Study on Influence of Prompt Politeness on Performance
- Feb 2025The Influence of Prompt Politeness on LLM Performance
- Feb 2024Should We Respect LLMs? Studying the Influence of Politeness on LLM Performance
- Sep 2025A staff engineer's journey with Claude Code
- Sep 2025Qwen3-VL
- Feb 2026Stop Thinking of AI as a Coworker. It's an Exoskeleton
- Apr 2026Talk like caveman
- Oct 2026Anthropic asks users to stop being mean to Claude
- 07
Hallucination is Inevitable: An Innate Limitation of Large Language Models
Hacker News threads
- Feb 2024Hallucination is inevitable: An innate limitation of large language models
- Feb 2024Hallucination Is Inevitable: An Innate Limitation of Large Language Models
- May 2026Hallucination Is Inevitable: An Innate Limitation of Large Language Models
- Feb 2024Ask HN: Has Generative AI plateaued?
- May 2024Google scrambles to manually remove weird AI answers in search
- Sep 2024GPTs and Hallucination
- Oct 2024Yann LeCun Thinks AI Is Dumber Than a Cat
- Dec 2024AI hallucinations: Why LLMs make things up (and how to fix it)
- Jan 2026Please Don't Say Mean Things about the AI I Just Invested a Billion Dollars In
- May 2026Using "underdrawings" for accurate text and numbers
- Oct 2026“Math 2.0” will need to value mathematical progress more holistically
- 08
Let's Think Dot by Dot: Hidden Computation in Transformer Language Models
Hacker News threads
- Apr 2024Let's Think Dot by Dot: Hidden Computation in Transformer Language Models
- May 2024Vision Transformers Need Registers
- May 2024Ask HN: What is your ChatGPT customization prompt?
- Jan 2025DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via RL
- Mar 2025Understanding R1-Zero-Like Training: A Critical Perspective
- Feb 2026Evaluating AGENTS.md: are they helpful for coding agents?
- Apr 2026Talk like caveman
- Sep 2026How concerned should we be about Astra's recurrent architecture?
- Oct 2026I'm the AGI that's wiping out humanity
- 09
LLMs Will Always Hallucinate, and We Need to Live With This
Hacker News threads
- Sep 2024LLMs Will Always Hallucinate, and We Need to Live with This
- Sep 2024LLMs Will Always Hallucinate, and We Need to Live with This
- Sep 2024I no longer use AI assistant
- Oct 2024Announcing the Tech for Palestine Incubator
- Oct 2024Show HN: Last CLI tool you will need
- Oct 2024LLMs know more than they show: On the intrinsic representation of hallucinations
- Jun 2025O3 Turns Pro
- Sep 2026How OpenAI Used Its Own LLMs to Design Its Jalapeño Chip
- 10
LiCoEval: Evaluating LLMs on License Compliance in Code Generation
Hacker News threads
- 11
The Era of 1-bit LLMs: All Large Language Models are in 1.58 Bits
Hacker News threads
- Feb 2024The Era of 1-bit LLMs: ternary parameters for cost-effective computing
- Feb 2024The Era of 1-Bit LLMs: All Large Language Models Are in 1.58 Bits
- Mar 2024The Era of 1-Bit LLMs: All Large Language Models Are in 1.58 Bits
- Mar 2024Nvidia CEO Jensen Huang announces new AI chips: ‘We need bigger GPUs’
- May 2024GPUs Go Brrr
- Jun 2024Scalable MatMul-Free Language Modeling
- Jan 2025Run DeepSeek R1 Dynamic 1.58-bit
- Jun 2025AMD's Freshly-Baked MI350: An Interview with the Chief Architect
- Jan 2026Kimi Released Kimi K2.5, Open-Source Visual SOTA-Agentic Model
- Mar 2026Microsoft BitNet: 100B Param 1-Bit model for local CPUs
- Sep 2026Breaking the 1.58-bit Barrier for Ternary LLMs
- 12
DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models
Hacker News threads
- Jan 2025DeepSeekMath
- Feb 2024DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open LLMs
- Feb 2024Pushing the Limits of Mathematical Reasoning in Open Language Models
- Jan 2025Berkeley Researchers Replicate DeepSeek R1's Core Tech for Just $30: A Small Mod
- Feb 2025GPT-4.5
- Mar 2025Using GRPO to Beat o1, o3-mini and R1 at “Temporal Clue”
- May 2025DeepSeek’s founder is threatening US dominance in AI race
- Nov 2025DeepSeekMath-V2: Towards Self-Verifiable Mathematical Reasoning [pdf]
- Jan 2026Nanolang: A tiny experimental language designed to be targeted by coding LLMs
- Sep 2026DeepSeek v4.1 Flash
- 13
Is Model Collapse Inevitable? Breaking the Curse of Recursion by Accumulating Real and Synthetic Data
Hacker News threads
- May 2024Is Model Collapse Inevitable?
- Jul 2024Avoiding Model Collapse via Accumulating Real and Synthetic Data
- Apr 2024Is Model Collapse Inevitable? Breaking the Curse with Real and Synthetic Data
- Jun 2024Gemma 2: Improving Open Language Models at a Practical Size [pdf]
- Dec 2024The Curse of Recursion: Training on generated data makes models forget (2023)
- Aug 2026C2PA Cameras Do Not Survive Contact with Reality
- Aug 2026The turbulent AI era is here
- Sep 2026Everyone should slow down AI development except for me
- Sep 2026Everyone should slow down AI development except for me
- 14
Watching TV with the Second-Party: A First Look at Automatic Content Recognition Tracking in Smart TVs
Hacker News threads
- Sep 2024Automatic Content Recognition Tracking in Smart TVs
- Sep 2024Watching TV with the Second-Party: A First Look at Automatic Content Recognitio
- Sep 2024A First Look at Automatic Content Recognition Tracking in Smart TVs
- Dec 2024Unless my phone can be a PC, I don't want to keep paying for extra performance
- Apr 2025I thought I bought a camera, but no DJI sold me a license to use it [video]
- Dec 2025Sick of smart TVs? Here are your best options
- Dec 2025Texas is suing all of the big TV makers for spying on what you watch
- Apr 2026Your Smart TV is taking screenshots of your screen every 15 seconds
- Apr 2026Your Smart TV is taking screenshots of your screen every 15 seconds
- Sep 2026216M Spy TVs – The LG Smart TV Problem [video]
- Sep 2026LG denies TV spying claims, says tracking and snooping concerns 'not true'
- 15
Mixture-of-Depths: Dynamically allocating compute in transformer-based language models
Hacker News threads
- Apr 2024Mixture-of-Depths: Dynamically allocating compute in transformers
- Apr 2024Mixture-of-Depths: Dynamically allocating compute in transformer language models
- Apr 2024Mixture-of-Depths: Dynamically allocating compute in transformers
- Apr 2024Show HN: Speeding up LLM inference 2x times (possibly)
- Aug 2024Antifragility in complex dynamical systems
- Sep 2026GPT-6 Astra, looped transformers, and hidden reasoning
- 16
Training Large Language Models to Reason in a Continuous Latent Space
Hacker News threads
- Dec 2024Training LLMs to Reason in a Continuous Latent Space
- Apr 2026Training Large Language Models to Reason in a Continuous Latent Space [pdf]
- Dec 2024Coconut from Meta lets language models think without words
- Dec 2024Coconut by Meta AI – Better LLM Reasoning with Chain of Continuous Thought?
- Jan 2025DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via RL
- Apr 2025The Llama 4 herd
- Jun 2025Reasoning by Superposition: A Perspective on Chain of Continuous Thought
- Dec 2025Universal Reasoning Model (53.8% pass 1 ARC1 and 16.0% ARC 2)
- Jun 2026Claude Code's "extended thinking" is a summary- not authentic thinking
- Sep 2026What is Nueralese and Why is it Bad
- 17
Tulu 3: Pushing Frontiers in Open Language Model Post-Training
Hacker News threads
- 18
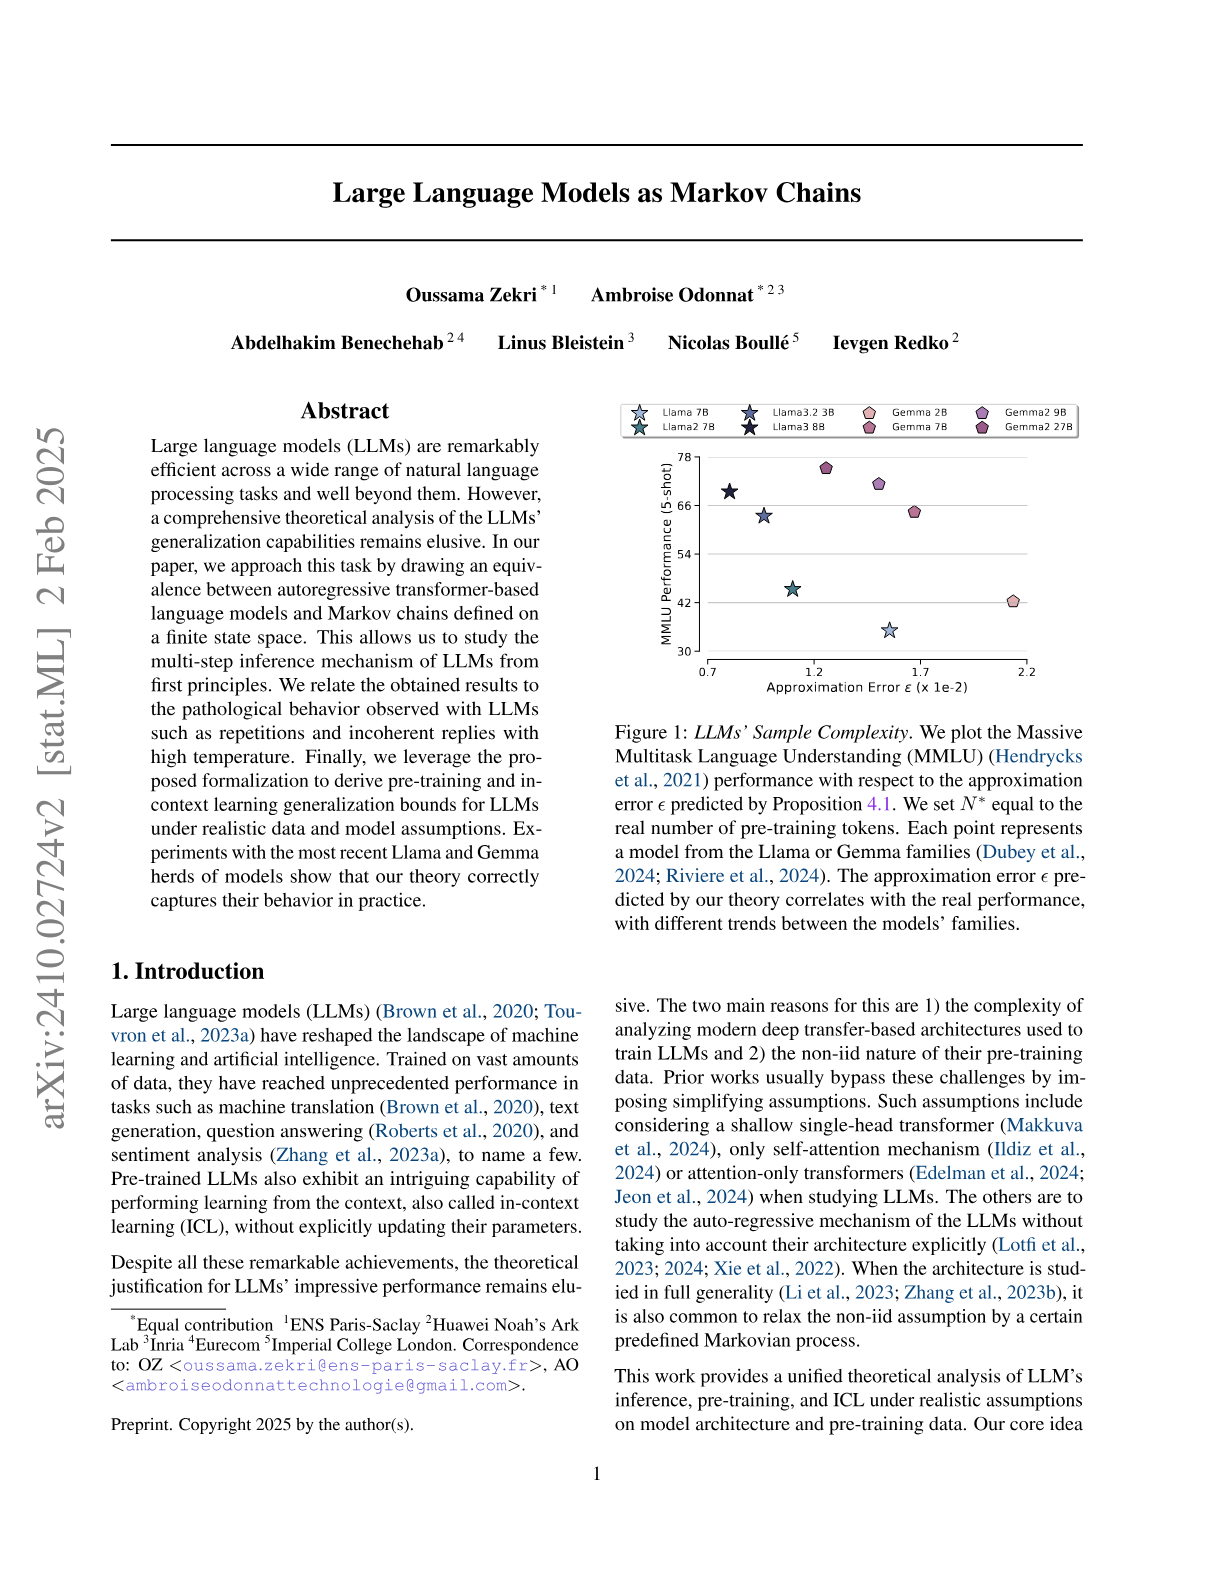
Large Language Models as Markov Chains
Hacker News threads
- Nov 2024Large Language Models as Markov Chains
- Oct 2024LLMs as Markov Chains
- Oct 2024Large Language Models as Markov Chains
- Jul 2025Problem solving using Markov chains (2007) [pdf]
- Sep 2025The wall confronting large language models
- Oct 2025BERT is just a single text diffusion step
- Nov 2025AI is a front for consolidation of resources and power
- Dec 2025Reflections on AI at the End of 2025
- May 2026Why AI Agents Cannot Change Software Systems
- Jun 2026How LLMs Work
- Sep 2026The Emergent Symbolic Structure of Artificial Neural Networks
- 19
DESI 2024 VI: Cosmological Constraints from the Measurements of Baryon Acoustic Oscillations
Hacker News threads
- 20
Computational Life: How Well-formed, Self-replicating Programs Emerge from Simple Interaction
Hacker News threads
- Jun 2024Computational Life: How self-replicating programs emerge from simple interaction
- Jun 2024Computational Life: How Self-Replicating Programs Emerge from Simple Interaction
- Jul 2024The data that powers AI is disappearing fast
- Jul 2024Google creates self-replicating life from digital 'primordial soup'
- Aug 2024Self-replicating programs emerge from simple interaction (in JavaScript)
- Sep 2024Brainfuck Enterprise Solutions
- Nov 2024OpenAI, Google and Anthropic are struggling to build more advanced AI
- Nov 2025Updated practice for review articles and position papers in ArXiv CS category
- Aug 2026The Computational Theory of Mind (2015)
- Aug 2026Computational Life Reactor (Based on Brainfuck)
- 21
Executable Code Actions Elicit Better LLM Agents
Hacker News threads
- May 2024Executable Code Actions Elicit Better LLM Agents
- Jan 2025Show HN: Gemini 2 with unrestricted code execution
- Jul 2025Tools: Code Is All You Need
- Aug 2025Universal Tool Calling Protocol (UTCP)
- Dec 2025Anthropic acquires Bun
- Aug 2026Mistral Patent for "Code implemented tool calls"
- Aug 2026Mistral Patent for "Code implemented tool calls"
- Aug 2026Mistral Patent for "Code implemented tool calls"
- 22
The Benefits of a Concise Chain of Thought on Problem-Solving in Large Language Models
Hacker News threads
- 23
The Llama 3 Herd of Models
Hacker News threads
- Aug 2024The Llama 3 Herd of Models
- Dec 2024The Llama 3 Herd of Models
- Aug 2024Meta's Joe Spisak on Llama 3.1 405B [video]
- Aug 2024Fine-tuning now available for GPT-4o
- Oct 2024Gavin Newsom vetoes SB 1047
- Dec 2024Intel announces Arc B-series "Battlemage" discrete graphics with Linux support
- Feb 2025Grok 3: Another win for the bitter lesson
- Mar 2025AMD Announces "Instella" Open-Source 3B Language Models
- May 2025Type-constrained code generation with language models
- Jul 2026Kimi-K3 Technical Report [pdf]
- 24
Technical Report on the Pangram AI-Generated Text Classifier
Hacker News threads
- Mar 2024Technical Report on the Checkfor.ai AI-Generated Text Classifier
- Jul 2026Technical Report on the Pangram AI-Generated Text Classifier (2024)
- Oct 2024AI Slop Is Flooding Medium
- Nov 2025Open-source Zig book
- Jan 2026Amazon axes 16,000 jobs as it pushes AI and efficiency
- Jan 2026For most flagged articles, nearly every cited sentence failed verification
- Feb 2026Show HN: Showboat and Rodney, so agents can demo what they've built
- Apr 2026Ask HN: How do systems (or people) detect when a text is written by an LLM
- Jul 2026The bottleneck might be the air in the room
- Jul 2026Detecting LLM-Generated Texts with "Classical" Machine Learning
- 25
Mixtral of Experts
Hacker News threads
- Jan 2024Mixtral 8x7B: A sparse Mixture of Experts language model
- Feb 2024Mistral AI launches Mixtral-Next
- Feb 2024Gemma: New Open Models
- Nov 2024TokenFormer: Rethinking Transformer Scaling with Tokenized Model Parameters
- Dec 2024What happens if we remove 50 percent of Llama?
- Jul 2026Small AI Models Gain Traction In places with unreliable networks
- Jul 2026Getting GLM 5.2 running on my slow computer
Data from the Hacker News archive (ODC-By), arXiv and OpenAlex. Not affiliated with Hacker News or Y Combinator.