Consistent Middle Enhancement in LLMs
First page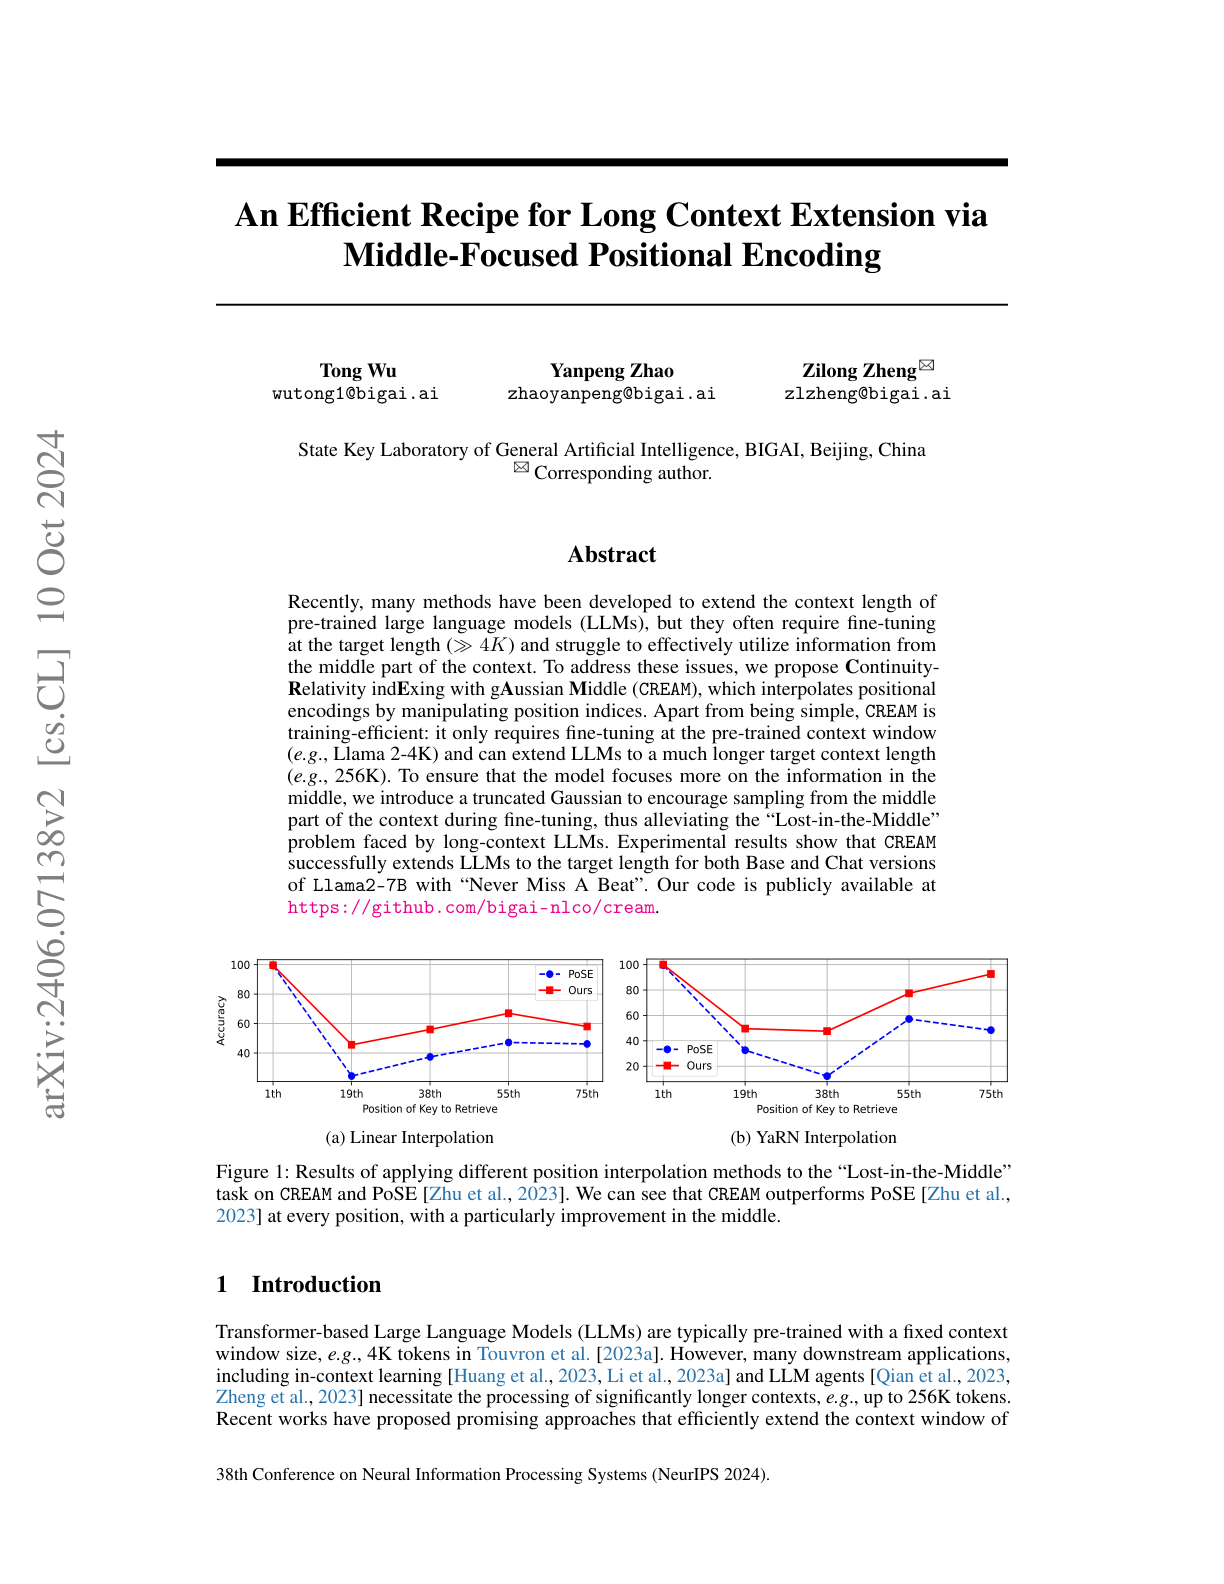
Paper summary
proposes an approach to tune an LLM to effectively utilize information from the middle part of the context; it first proposes a training-efficient method to extend LLMs to longer context lengths (e.g., 4K -> 256K); it uses a truncated Gaussian to encourage sampling from the middle part of the context during fine-tuning; the approach helps to alleviate the so-called "Lost-in-the-Middle" problem in long-context LLMs.