DeepSeekMath
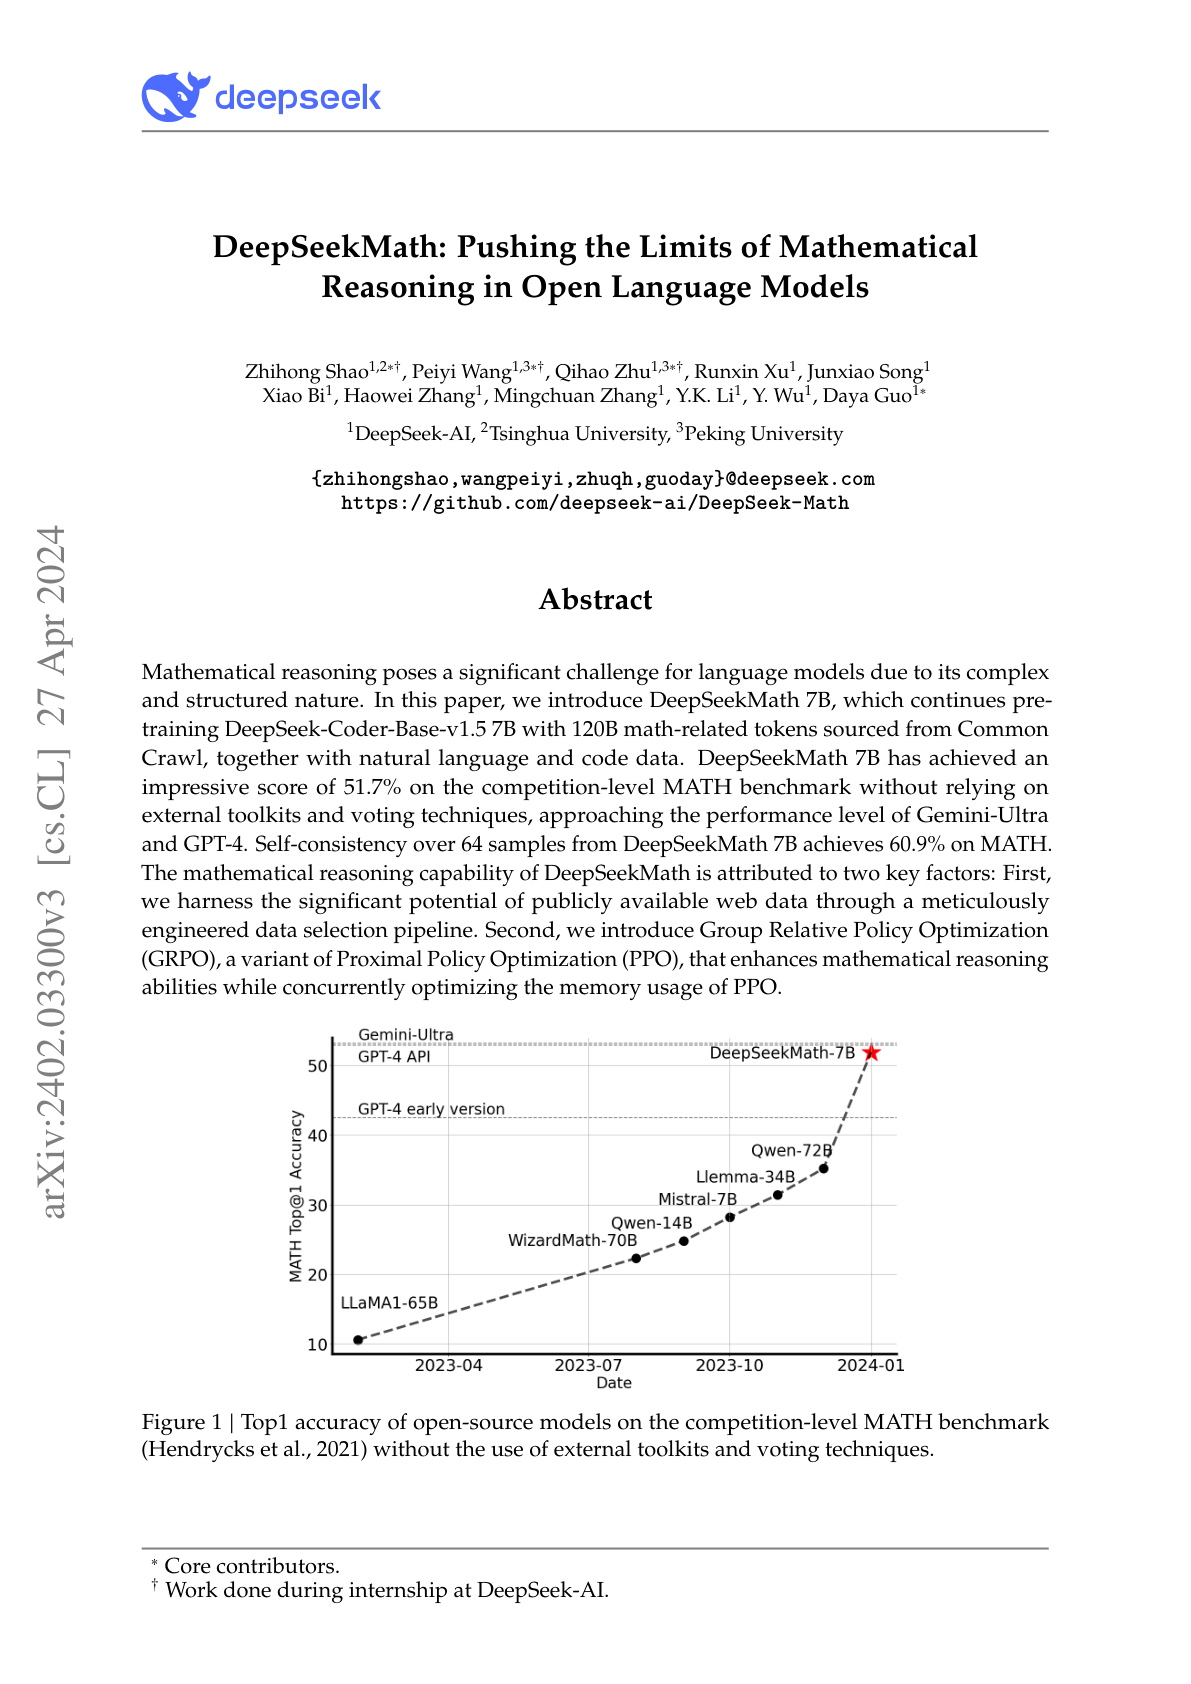
DeepSeek releases DeepSeekMath 7B, a math-specialized LLM that closes much of the gap to GPT-4 and Gemini-Ultra on MATH by combining better data and a new RL objective.
Ask this paper
120B math pretraining: Continues pretraining a DeepSeek-Coder base on 120B math-related tokens mined from Common Crawl, plus natural language and code, so that math-relevant skills and knowledge sit at the foundation.
GRPO objective: Introduces Group Relative Policy Optimization, a PPO variant that drops the value network and estimates advantage via within-group comparisons, reducing memory with strong reasoning results.
Close to frontier: DeepSeekMath 7B reaches 51.7% on MATH, approaching Gemini-Ultra (53.2%) and GPT-4 (52.9%) without any external tools.
Self-consistency boost: Combining DeepSeekMath 7B with self-consistency over 64 samples pushes performance to 60.9%, beating frontier API models on MATH.