Faster LLM Inference with Dynamic Draft Trees
First page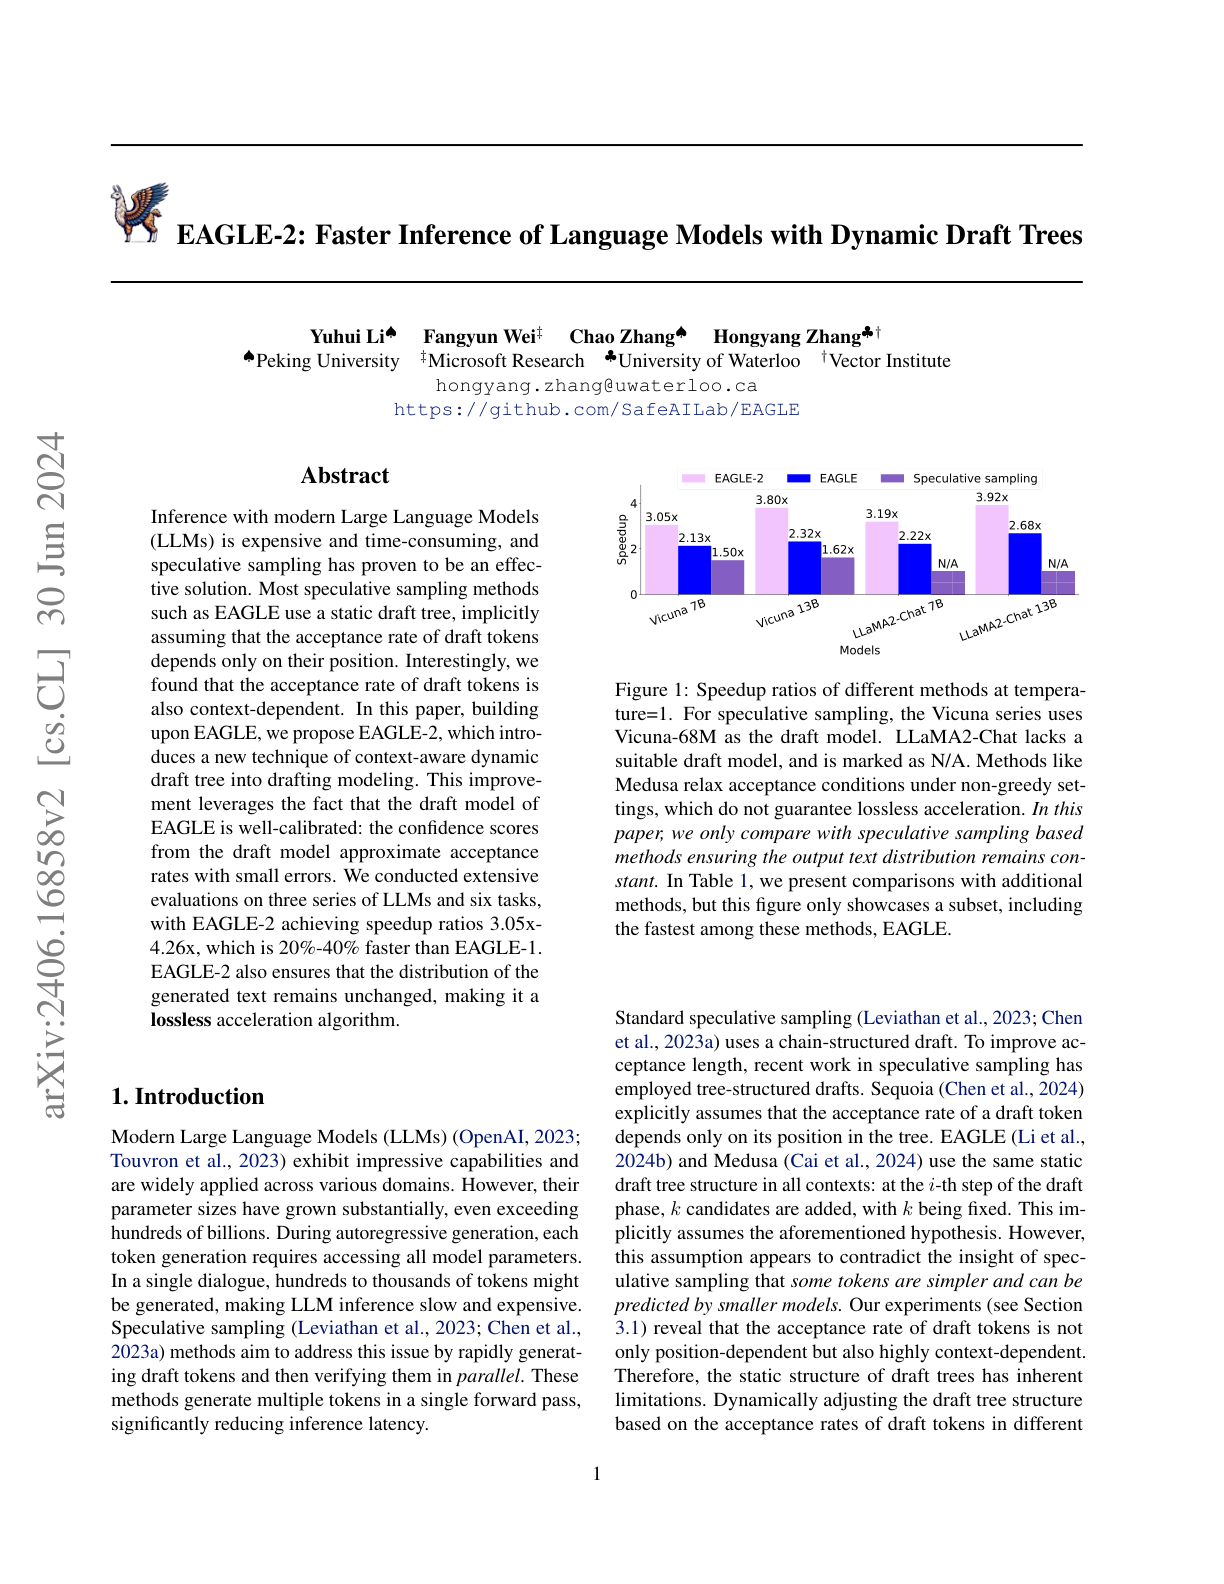
Paper summary
presents a context-aware dynamic draft tree to increase the speed of inference; the previous speculative sampling method used a static draft tree for sampling which only depended on position but lacked context awareness; achieves speedup ratios ranging from 3.05x-4.26x, which is 20%-40% faster than previous work; these speedup ratios occur because the new method significantly increases the number of accepted draft tokens.