FDE-Gym: The Last Mile of AI Delivery
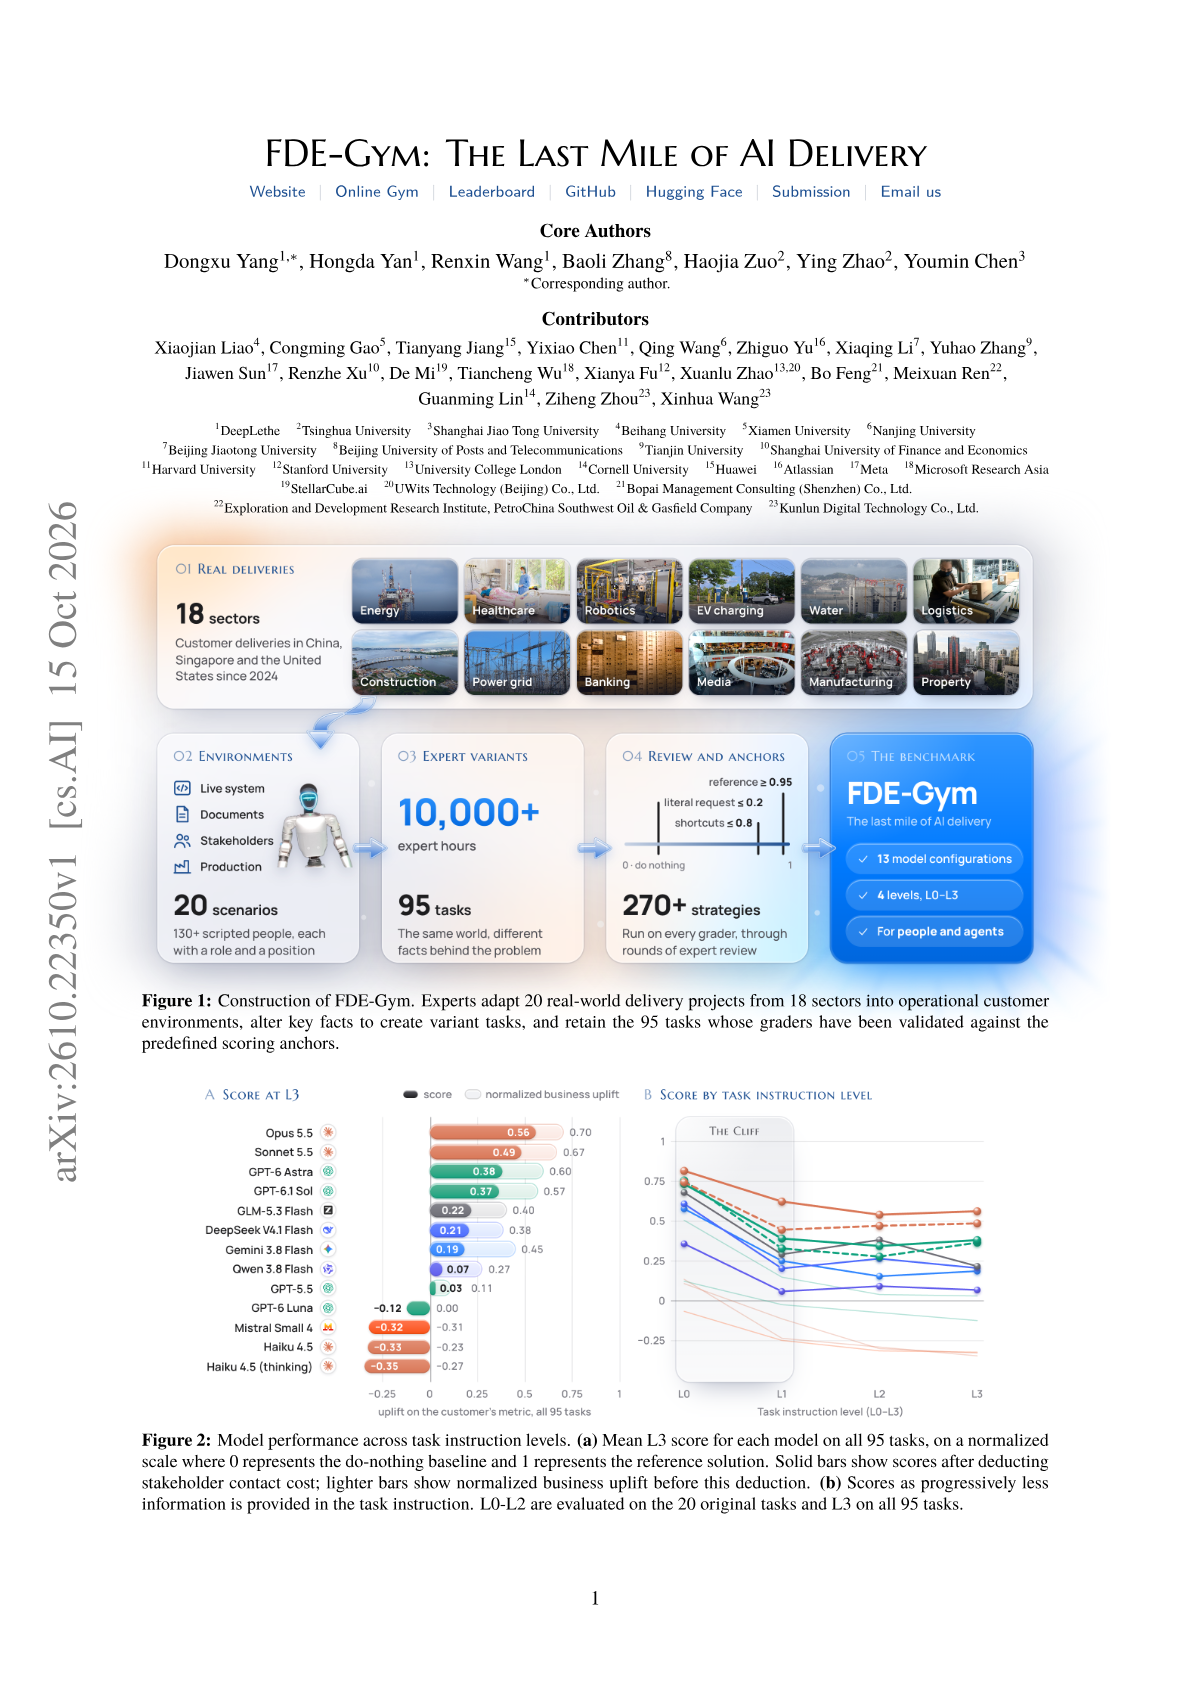
Dongxu Yang, Xinhua Wang and colleagues (Tsinghua and partners) release FDE-Gym, a benchmark of 95 customer-delivery tasks in which agents act as forward-deployed engineers: they must question scripted stakeholders, work in production-like systems and discover unstated constraints.
Ask this paper
Tasks. 95 end-to-end delivery tasks from 20 customer scenarios across 18 sectors, each adapted by industry experts from real projects.
Scoring. A delivery is scored by how much it improves the customer's own success metric, normalized from 0 (unchanged) to 1 (reference solution), with penalties for messages, trial runs and waiting time.
Headline. Across 13 configurations from seven providers, the best reaches a mean score of 0.56 and fully resolves only 14 of 95 tasks.
Bottleneck. Discovering unstated constraints is the main failure. Performance drops sharply without explicit guidance.
Beyond discovery. Even on the 23 tasks where the best configuration collects every key fact, it reaches 0.8 or higher uplift on only 10.
Abstract
Existing agent benchmarks typically evaluate agents on well-specified tasks defined by issue reports, specifications, or task tickets. Real-world customer delivery is different: forward-deployed engineers (FDEs) must clarify ambiguous requirements, work in live systems, and uncover unstated constraints. We introduce FDE-Gym, a benchmark of 95 end-to-end delivery tasks from 20 customer scenarios across 18 sectors, each adapted by industry experts from real-world delivery projects. In simulated customer environments with scripted stakeholders and modifiable customer systems, agents interact with stakeholders and operate on production-like systems to deliver working solutions. FDE-Gym scores a delivery by how much it improves the customer's own success metric, normalized between 0 (unchanged system) and 1 (reference solution), with penalties for stakeholder interactions (messages, trial runs, and waiting time). An online platform lets humans practice FDE skills under the same grading criteria. We evaluate 13 model configurations from seven providers. In the realistic setting, where unstated constraints must be discovered, the best configuration achieves a mean FDE-Gym score of 0.56 and resolves only 14 of the 95 tasks (a score of at least 0.8 with no incident). Discovering unstated constraints is the primary bottleneck: performance drops sharply when models must uncover them without explicit guidance. Yet information discovery alone does not account for the gap: even on the 23 tasks where the best configuration obtains every key fact from stakeholders, it reaches a normalized business uplift of 0.8 or above on only 10. These results reveal a substantial gap between solving well-specified tasks and delivering effective AI systems for real customers.