FlashAttention-2
First page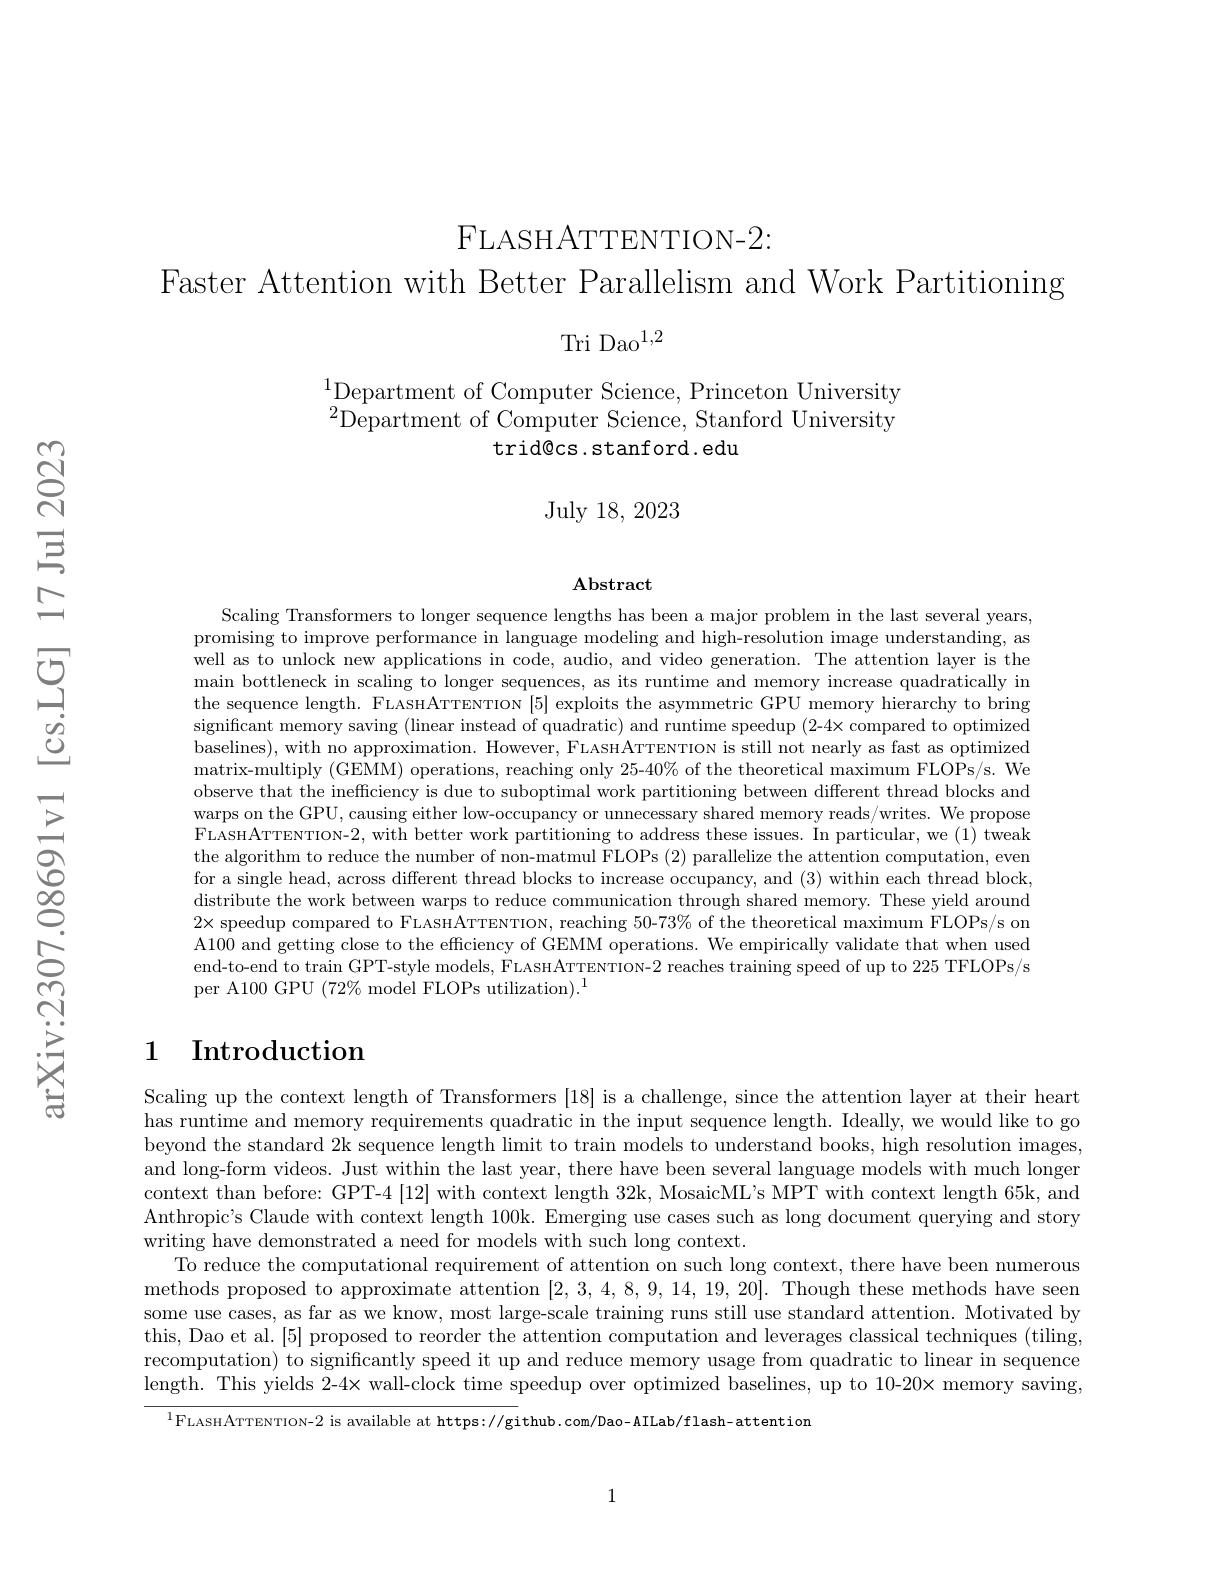
Paper summary
Tri Dao's follow-up to FlashAttention, dramatically improving attention throughput on modern GPUs.
Ask this paper
01
Work partitioning: Redesigns parallelism so non-matmul FLOPs are reduced and thread blocks are better utilized across SMs.
02
~2x speedup: Achieves approximately 2x speedup over FlashAttention-1 and reaches 50-73% of theoretical maximum FLOPs/s on A100.
03
Shared-memory communication: Parallelizes attention along sequence length, increases occupancy, and reduces cross-warp communication via shared memory.
04
Training infrastructure staple: Became the default attention kernel in PyTorch, HuggingFace, vLLM, and nearly every 2024 training stack for long-context models.