GRIT
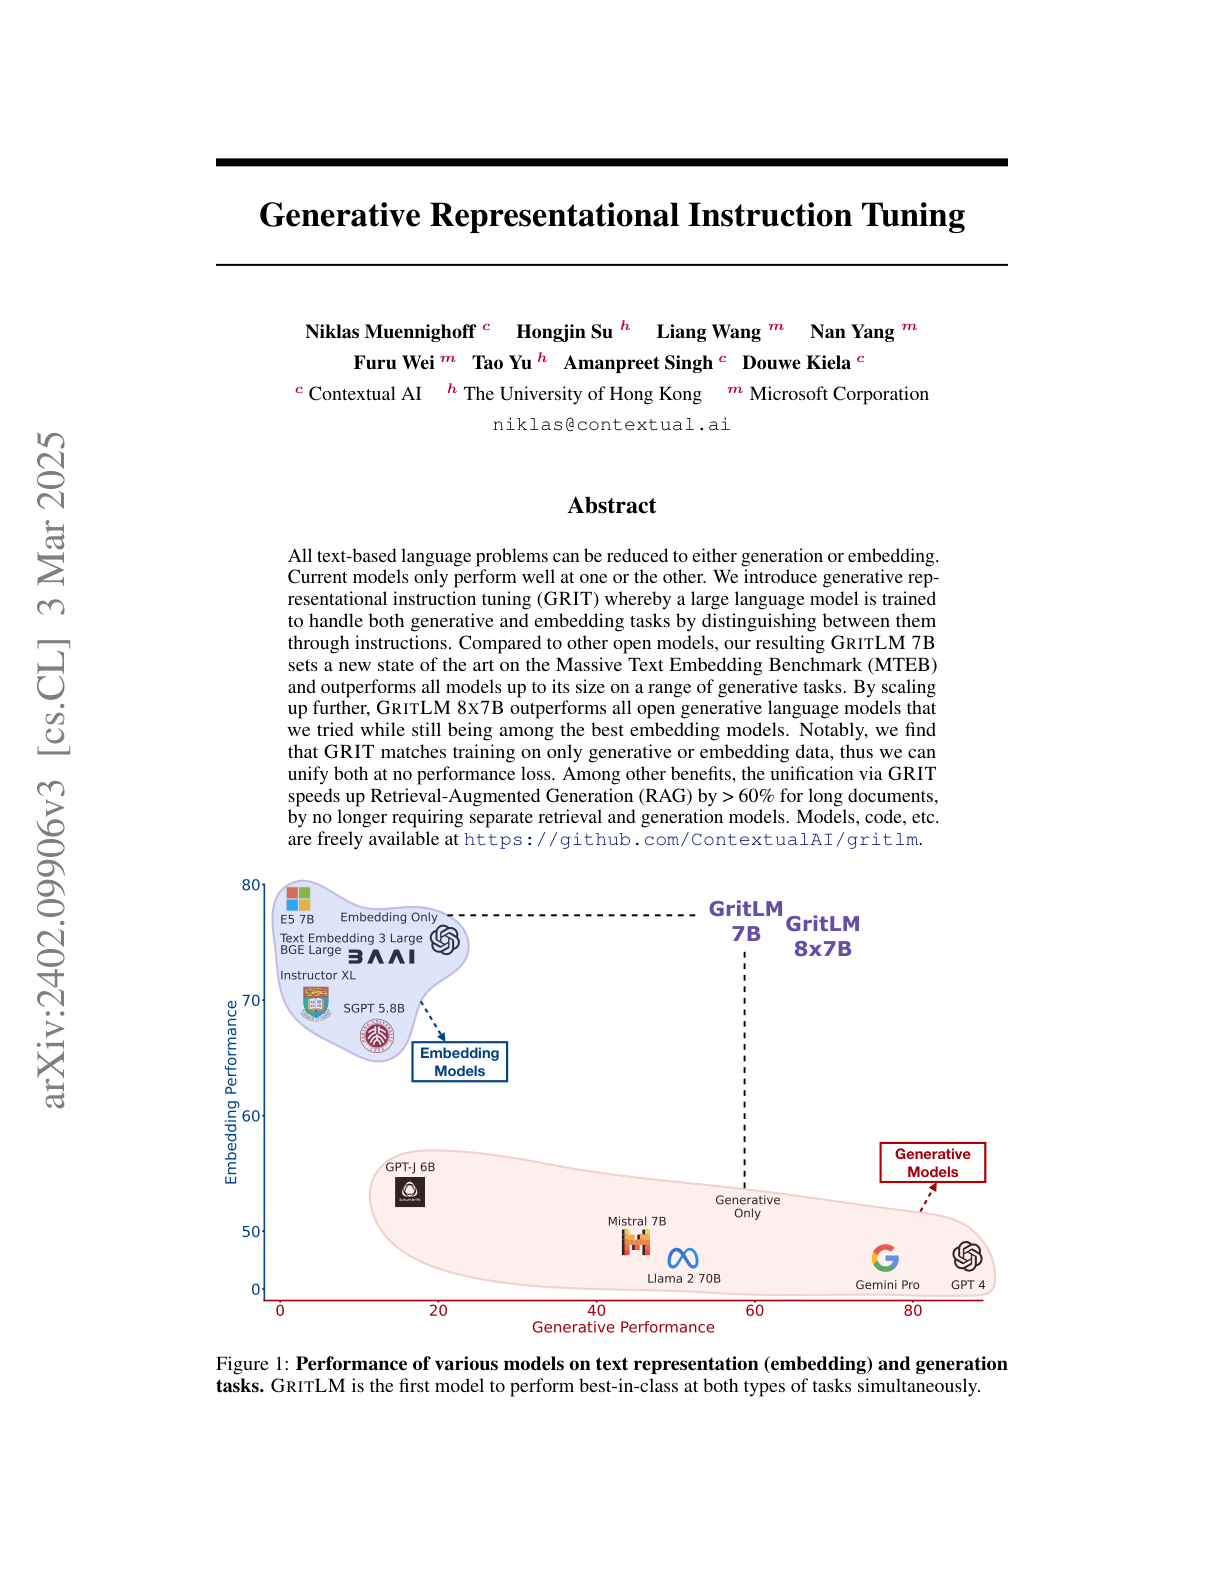
GRIT (Generative Representational Instruction Tuning) trains a single LLM to handle both generative and embedding tasks, switching behavior based on instructions.
Ask this paper
Dual-task training: A shared backbone is trained jointly on generation and embedding objectives, with instructions disambiguating which head to use at inference.
MTEB SoTA: GritLM 7B sets a new state of the art on the Massive Text Embedding Benchmark (MTEB) while matching specialized generative models on generation tasks.
Scales cleanly: An 8x7B variant outperforms specialized generative models while also retaining top-tier embedding quality, showing the unification doesn't hurt either side.
RAG speedup: Because the same model serves both retrieval and generation, long-document RAG pipelines run 60%+ faster by eliminating a separate encoder pass.