Hierarchical Vision Transformer (Hiera)
First page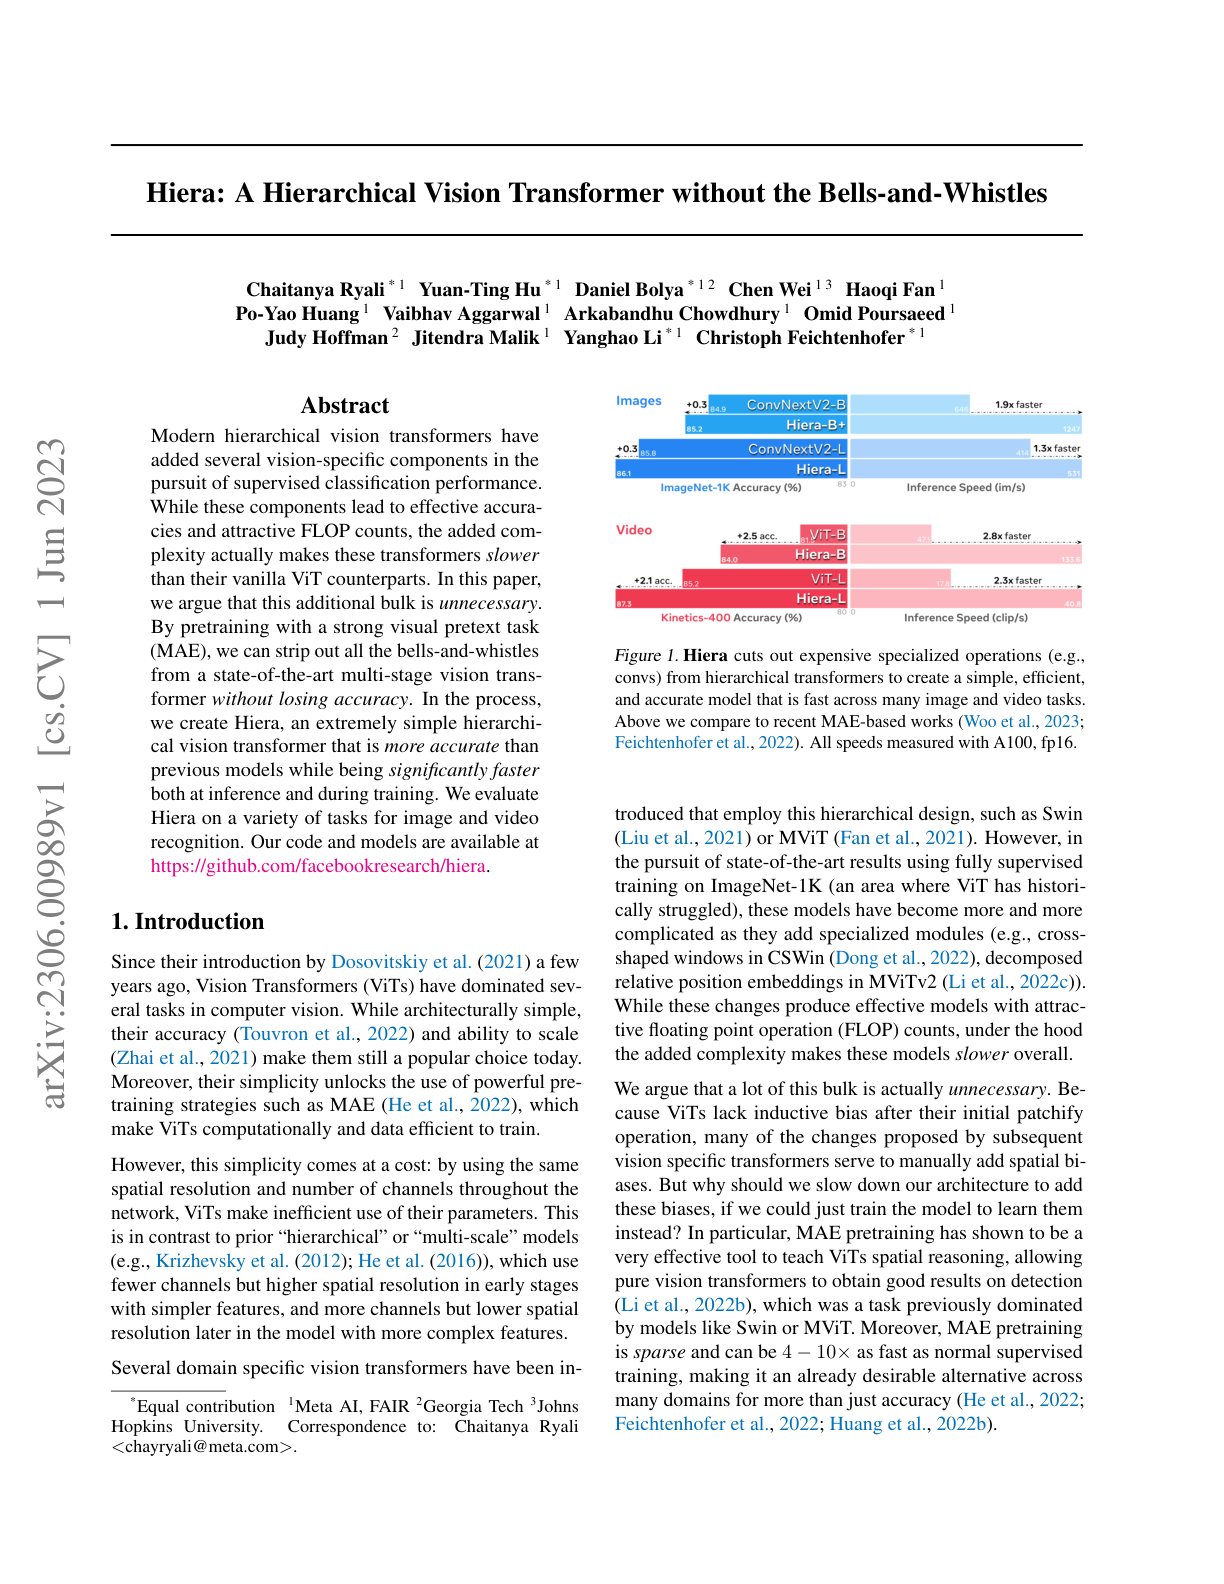
Paper summary
Pretrains ViTs with MAE while removing unnecessary multi-stage complexity.
Ask this paper
01
Simplified architecture: Strips away hand-designed components (shifted windows, relative position biases) from hierarchical ViTs like Swin.
02
MAE pretraining: Leverages masked autoencoder pretraining to compensate for reduced inductive bias.
03
Faster and more accurate: Achieves better accuracy and faster inference/training than prior hierarchical ViTs.
04
Architecture minimalism: Reinforces the "bitter lesson" direction - simpler architectures with better pretraining beat complex hand-designed ones.