LLM in a Flash
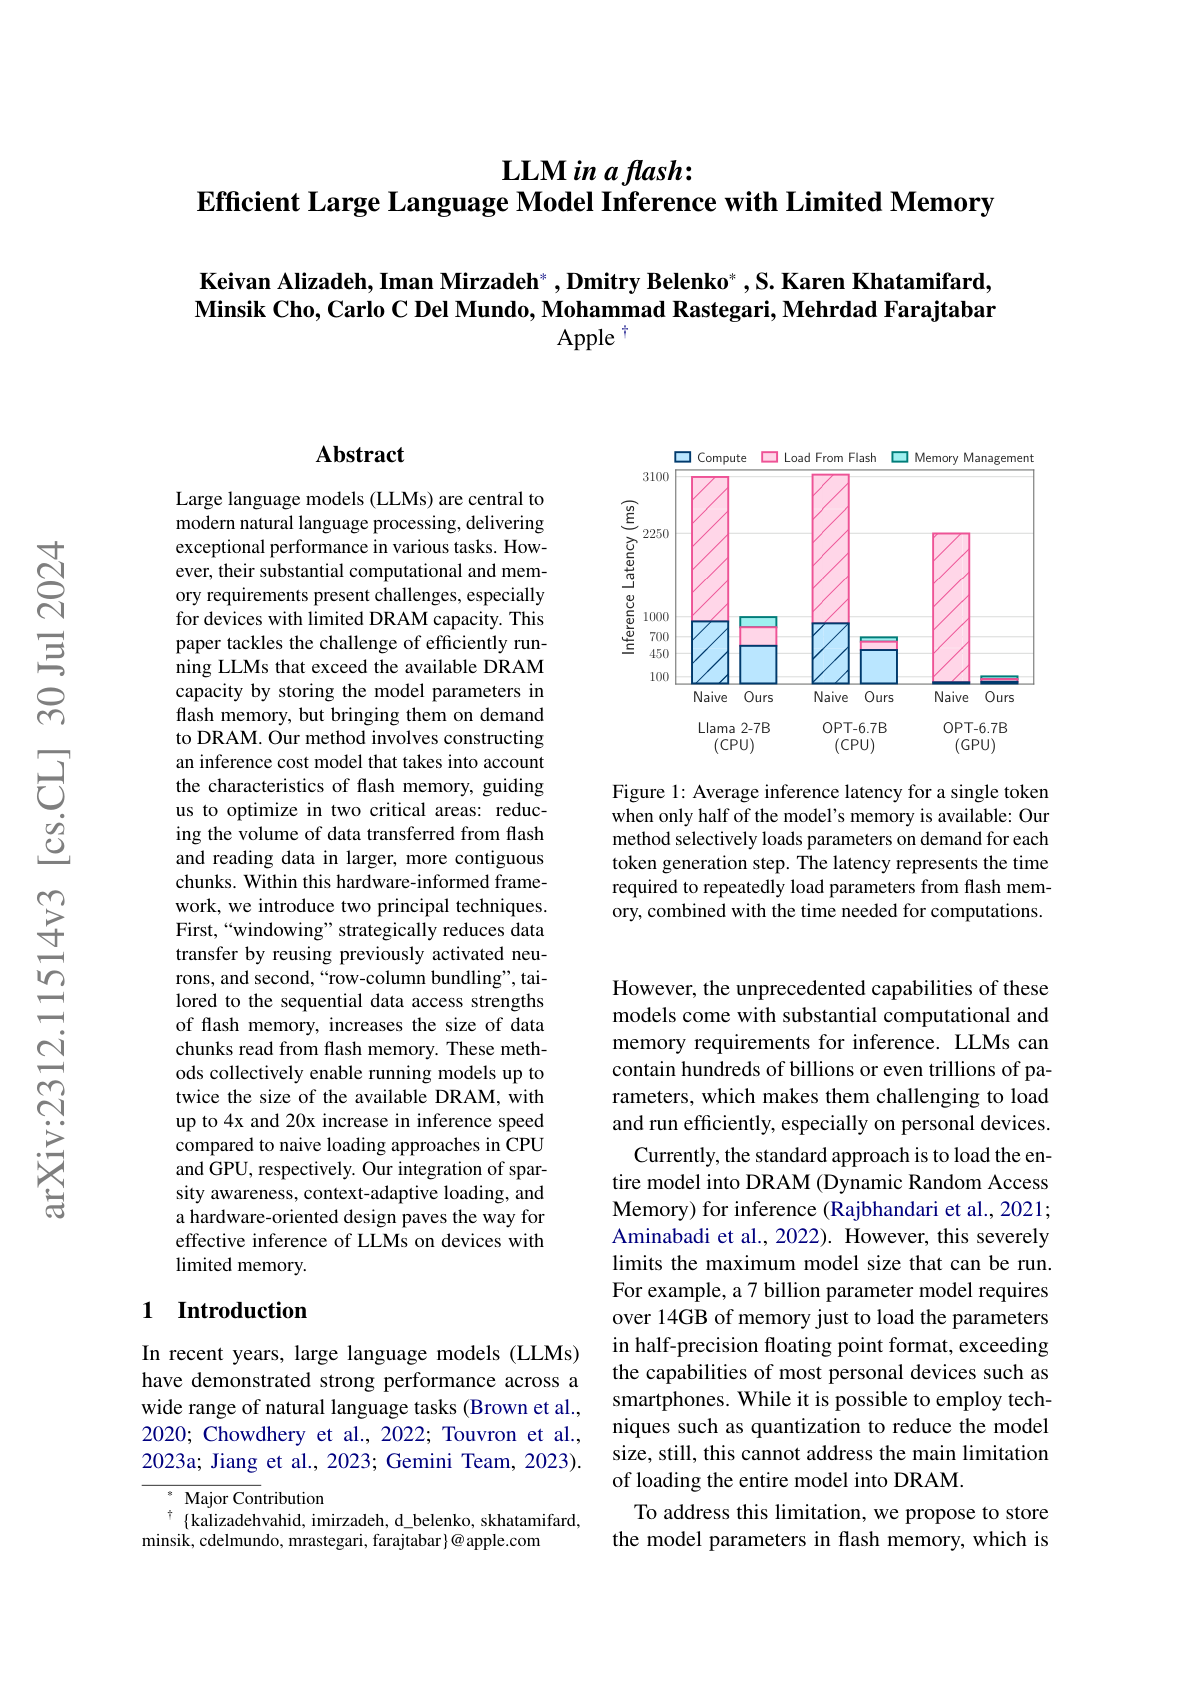
Apple researchers show how to run LLMs larger than available DRAM by streaming weights from flash storage on demand.
Ask this paper
Flash as swap: Stores model weights on flash and streams only the rows/columns needed per forward pass into DRAM, exploiting the sparsity of relevant parameters.
2x DRAM headroom: Enables running models up to 2x the size of available DRAM without catastrophic slowdown, critical for on-device deployment where memory is tight.
Major speedups vs. naive loading: 4-5x faster on CPU and 20-25x faster on GPU compared to naive parameter loading, thanks to selective transfer and row-column bundling.
On-device LLM groundwork: Directly enabled Apple's later on-device LLM plans by showing that flash-based streaming can make phone-scale LLM inference practical.