LongCat-DeepResearch Technical Report
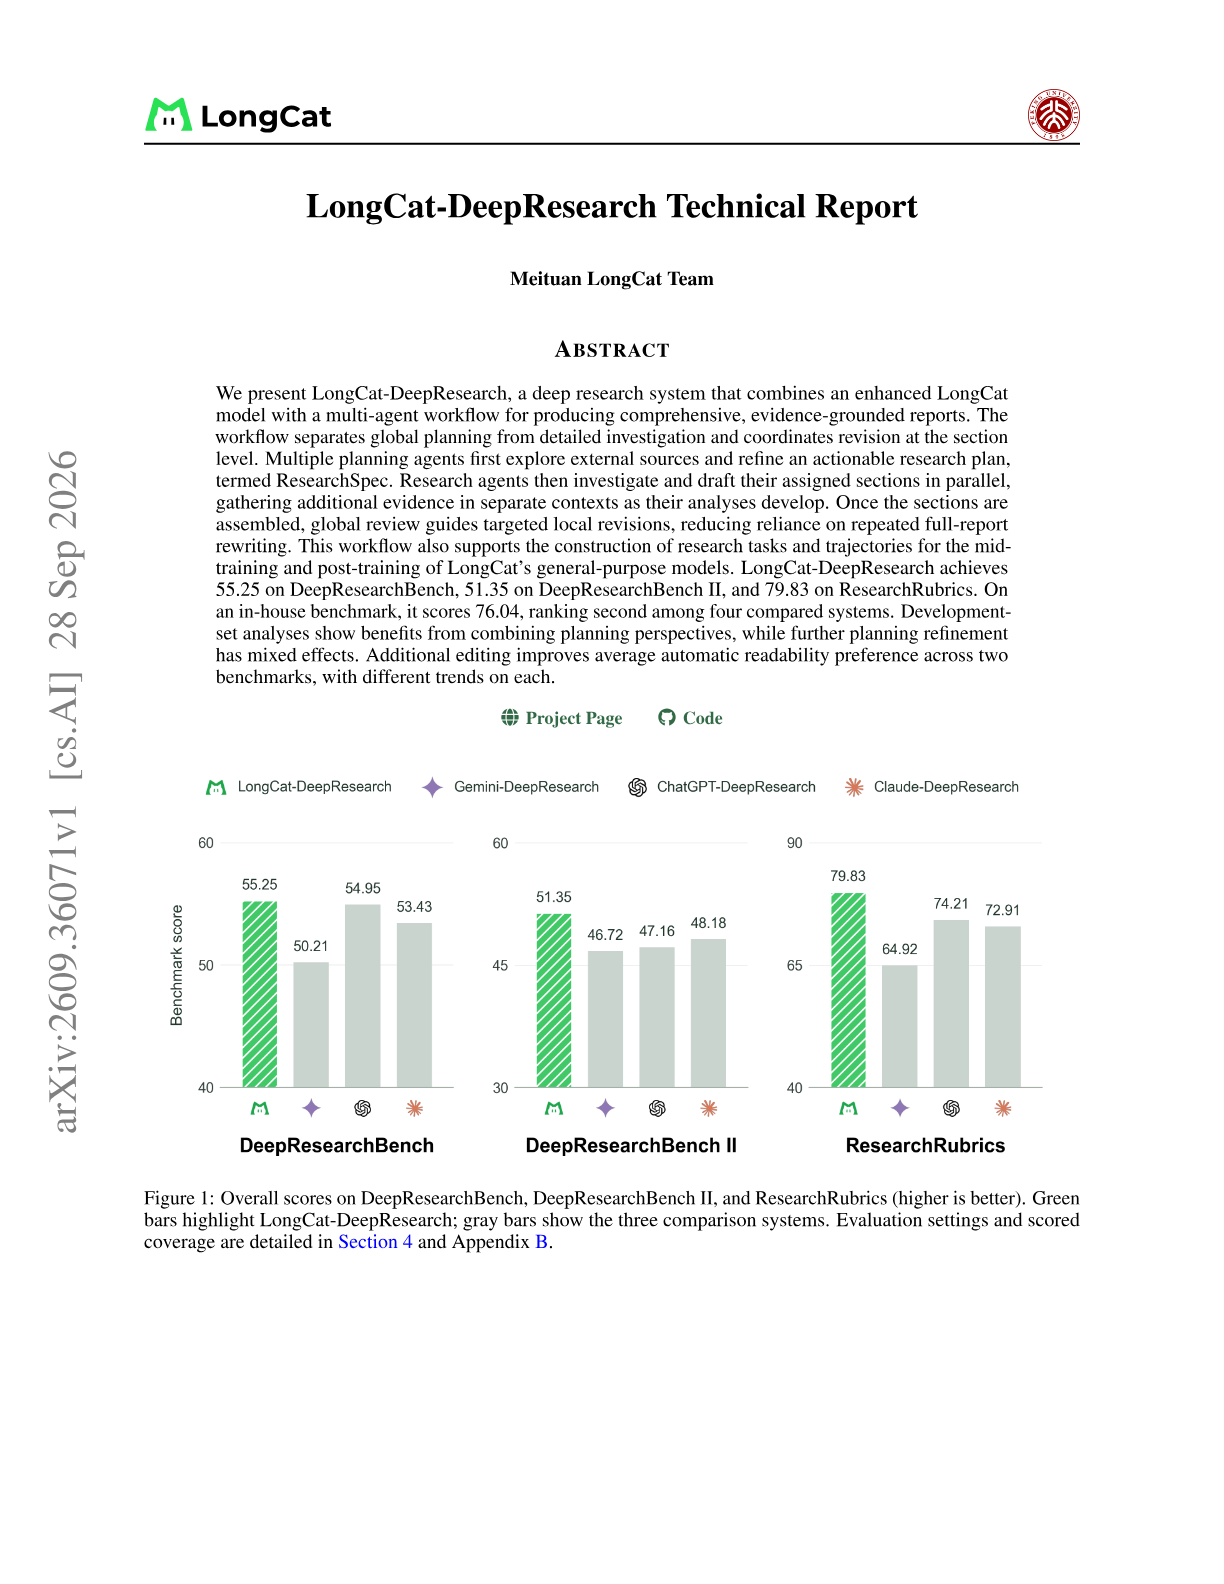
The Meituan LongCat Team describes LongCat-DeepResearch, a deep research system that pairs an enhanced LongCat model with a multi-agent workflow built around a compact research plan, ResearchSpec, instead of repeated full-report rewrites.
Ask this paper
Workflow. Several planning agents search independently and their proposals are merged into ResearchSpec, which lists questions, evidence requirements and section responsibilities. Research agents then write their sections in parallel in separate contexts, and a Global Editor plus Local Editors revise the assembled draft.
Benchmarks. 55.25 on DeepResearchBench, 51.35 on DeepResearchBench II and 79.83 on ResearchRubrics, ahead of the strongest of three compared deep-research products by 0.30, 3.17 and 5.62 points.
In-house benchmark. It scores 76.04, second of four, 0.55 points behind ChatGPT-DeepResearch (76.59) and well ahead of Claude-DeepResearch (61.42) and Gemini-DeepResearch (42.49).
Training data. The same workflow generates research tasks and trajectories used in mid-training and post-training of LongCat's general models.
Mixed findings. Combining planning perspectives helps, further planning refinement has mixed category-level effects, and extra editing rounds improve readability preference unevenly across benchmarks.
Abstract
We present LongCat-DeepResearch, a deep research system that combines an enhanced LongCat model with a multi-agent workflow for producing comprehensive, evidence-grounded reports. The workflow separates global planning from detailed investigation and coordinates revision at the section level. Multiple planning agents first explore external sources and refine an actionable research plan, termed ResearchSpec. Research agents then investigate and draft their assigned sections in parallel, gathering additional evidence in separate contexts as their analyses develop. Once the sections are assembled, global review guides targeted local revisions, reducing reliance on repeated full-report rewriting. This workflow also supports the construction of research tasks and trajectories for the mid-training and post-training of LongCat's general-purpose models. LongCat-DeepResearch achieves 55.25 on DeepResearchBench, 51.35 on DeepResearchBench II, and 79.83 on ResearchRubrics. On an in-house benchmark, it scores 76.04, ranking second among four compared systems. Development-set analyses show benefits from combining planning perspectives, while further planning refinement has mixed effects. Additional editing improves average automatic readability preference across two benchmarks, with different trends on each.