LoraHub
First page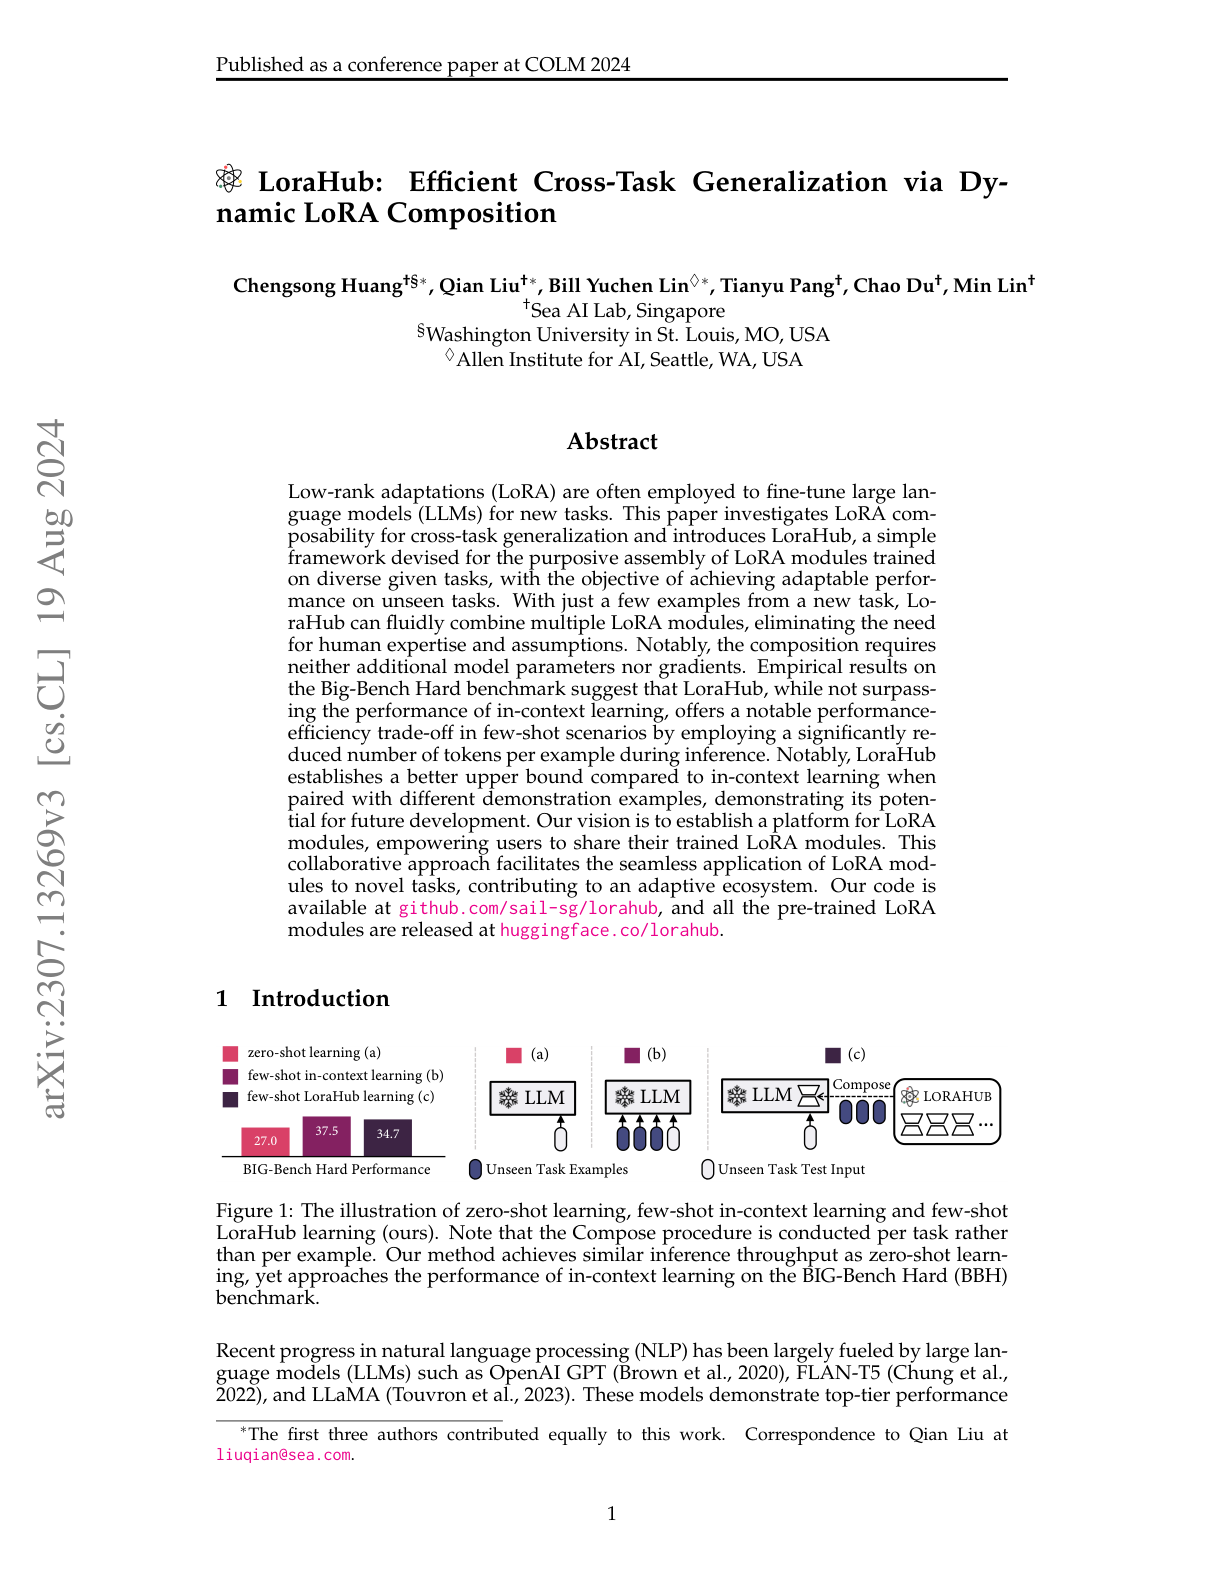
Paper summary
Enables efficient cross-task generalization via dynamic LoRA composition.
Ask this paper
01
Dynamic composition: Combines pre-trained LoRA modules via learned weights without human expertise or additional parameters/gradient updates.
02
Gradient-free optimization: Uses gradient-free algorithms like Nelder-Mead to find optimal LoRA weightings on a handful of examples.
03
ICL-matching performance: Matches the performance of in-context learning in few-shot settings while using much less inference compute.
04
Modular LLMs vision: Part of the broader push toward modular, composable adapter ecosystems - a direction still actively developed in 2024's MoE-of-LoRAs work.