MemAgent
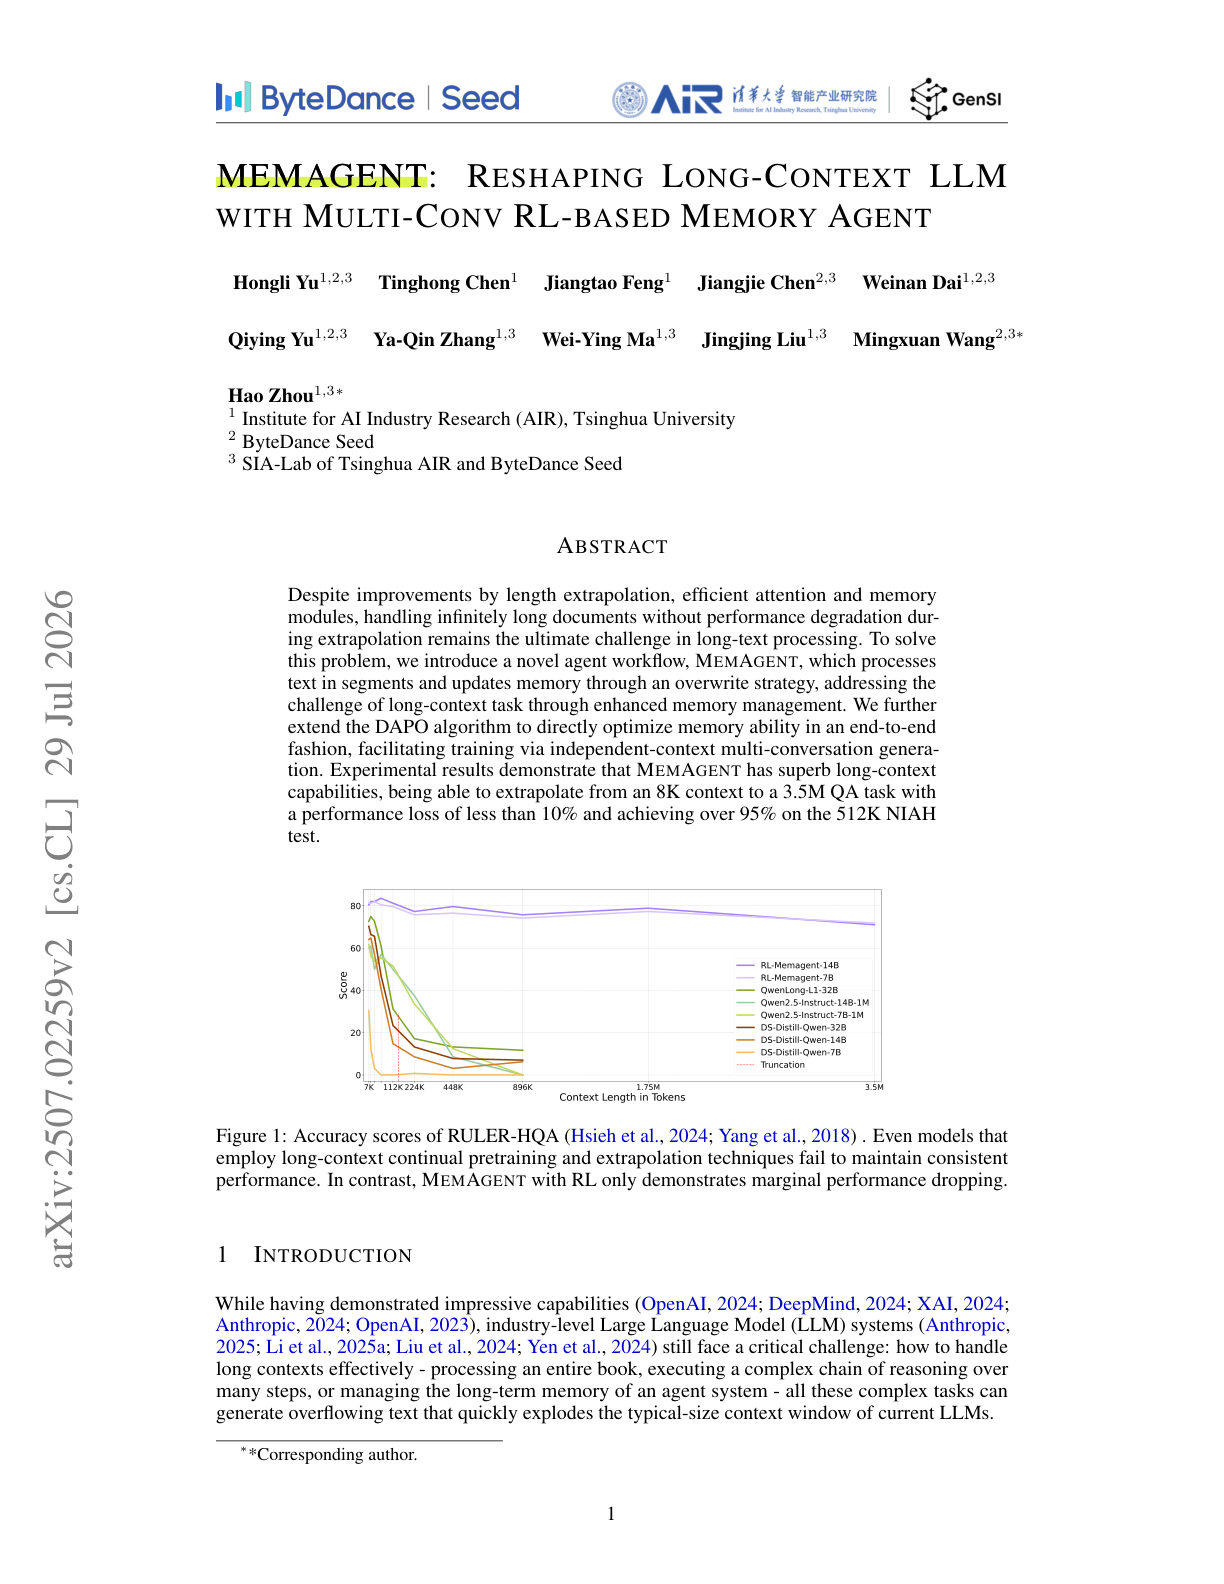
Introduces an RL–driven memory agent that enables transformer-based LLMs to handle documents up to 3.5 million tokens with near lossless performance, linear complexity, and no need for architectural modifications.
Ask this paper
RL-shaped fixed-length memory: MemAgent reads documents in segments and maintains a fixed-size memory updated via an overwrite mechanism. This lets it process arbitrarily long inputs with O(N) inference cost while avoiding context window overflows.
Multi-conversation RL training (Multi-Conv DAPO): Unlike standard RL pipelines, MemAgent generates multiple independent memory-update conversations per input. It uses a modified GRPO objective to optimize all steps via final-answer reward signals.
Strong long-context extrapolation: Despite being trained on 32K-length documents with an 8K context window, MemAgent-14B achieves >76% accuracy even at 3.5M tokens, outperforming baselines like Qwen2.5 and DeepSeek, which degrade severely beyond 112K tokens.
Generalizes to diverse long-context tasks: On the RULER benchmark, it excels in multi-hop QA, variable tracking, frequent word extraction, and NIAH retrieval, even outperforming larger 32B baselines without RL. Its memory updates are interpretable and resilient to distractors.