Patchscopes
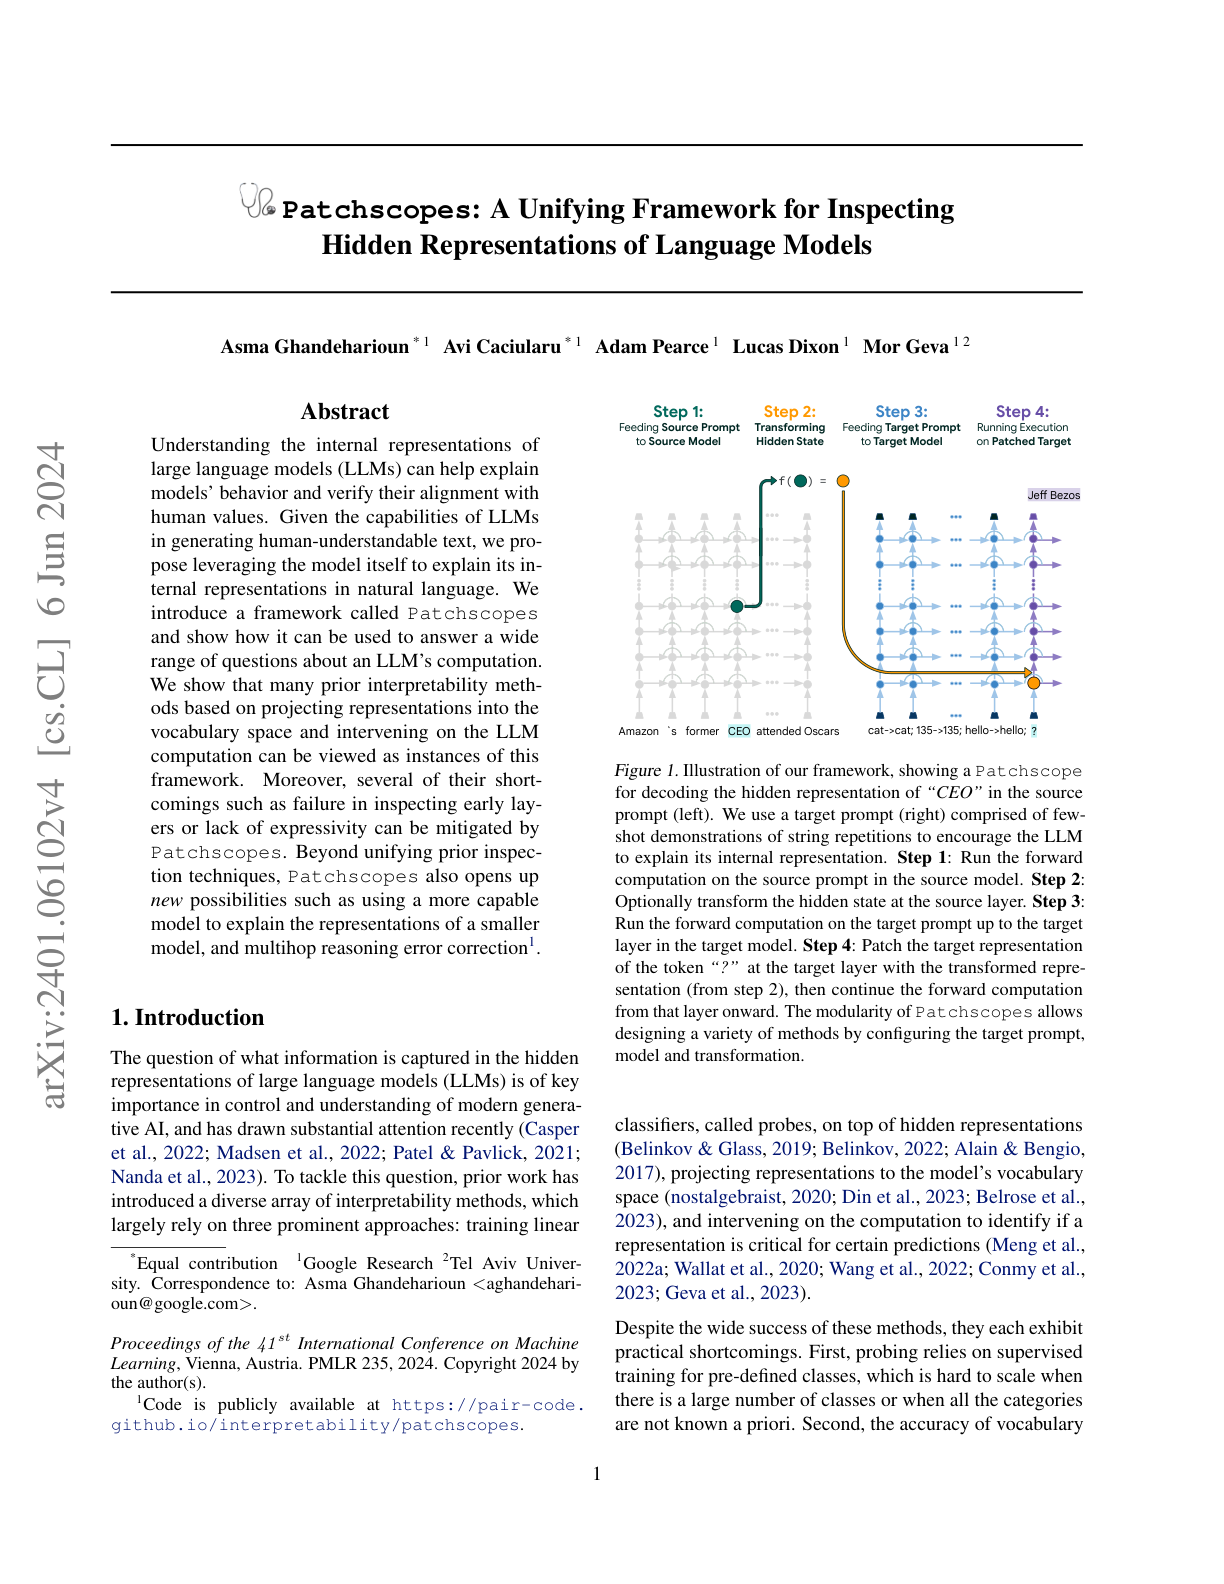
Patchscopes is a general framework for inspecting and intervening on LLM internals by "patching" hidden representations into a second inference pass.
Ask this paper
Patch-and-decode: Takes a hidden state from one forward pass, patches it into a second LLM call with an auxiliary prompt, and reads back natural-language descriptions of what that state encodes.
Unifies prior methods: Subsumes a wide range of existing interpretability techniques (logit lens, activation patching, probing) as special cases of its patching/decoding pattern.
Answers computational questions: Can answer questions about the role of specific layers, attribute representations, or the flow of information within the model.
Fixes latent reasoning: Demonstrates that patching in corrected intermediate representations can actually fix latent multi-hop reasoning errors at inference time - interpretability moving into a practical intervention.