Prompt Repetition Improves Non-Reasoning LLMs
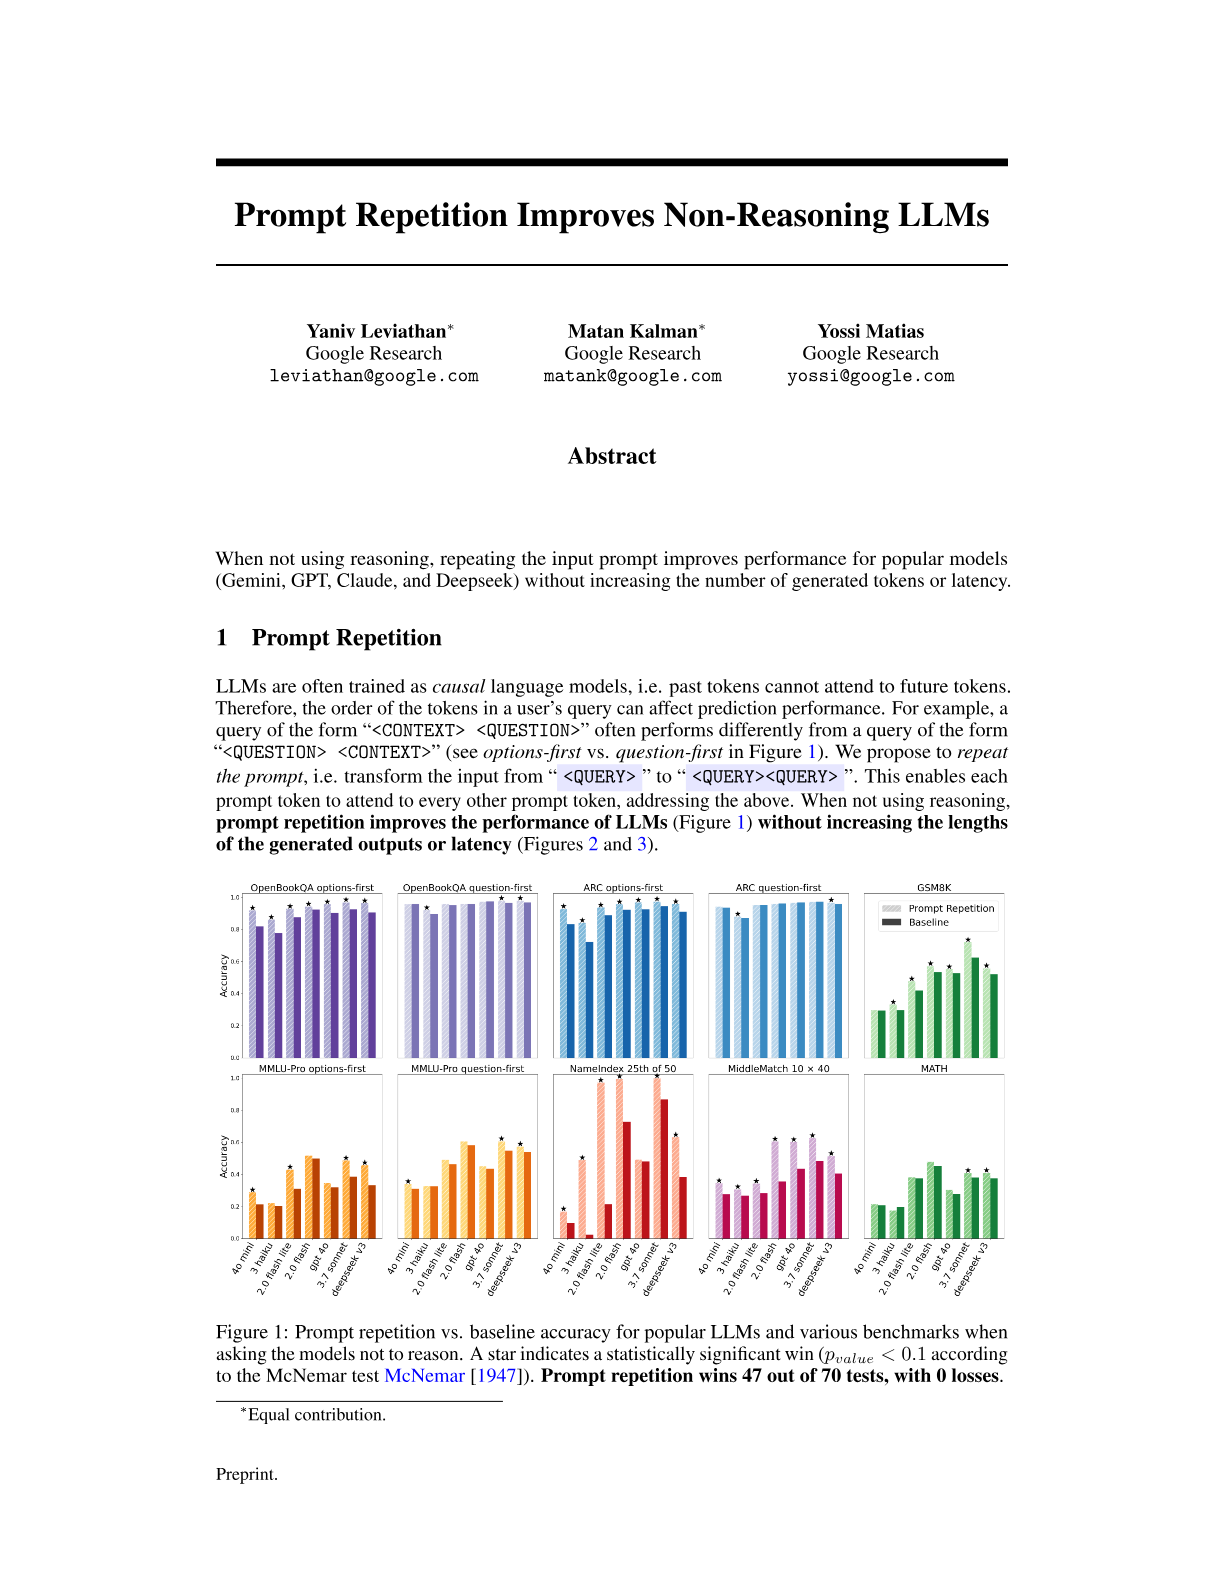
Yaniv Leviathan, Matan Kalman and Yossi Matias at Google Research report that simply repeating the input prompt improves non-reasoning model performance across Gemini, GPT, Claude and DeepSeek.
Ask this paper
The intervention: Duplicate the input prompt before generation. Nothing is added to the output, so generated token count and latency are unchanged.
Where it applies: The gain is reported for the non-reasoning setting, that is, when the model is not producing an extended chain of thought before answering.
Breadth: The effect is reported across four popular model families rather than a single model, which is what makes it worth testing rather than filing as a quirk of one system.
Why it is cheap to try: The change costs one extra copy of the input in the prefill and no extra decode steps, so the cost profile is different from any method that lengthens the response.
Abstract
When not using reasoning, repeating the input prompt improves performance for popular models (Gemini, GPT, Claude, and Deepseek) without increasing the number of generated tokens or latency.