Qwen2.5-1M
First page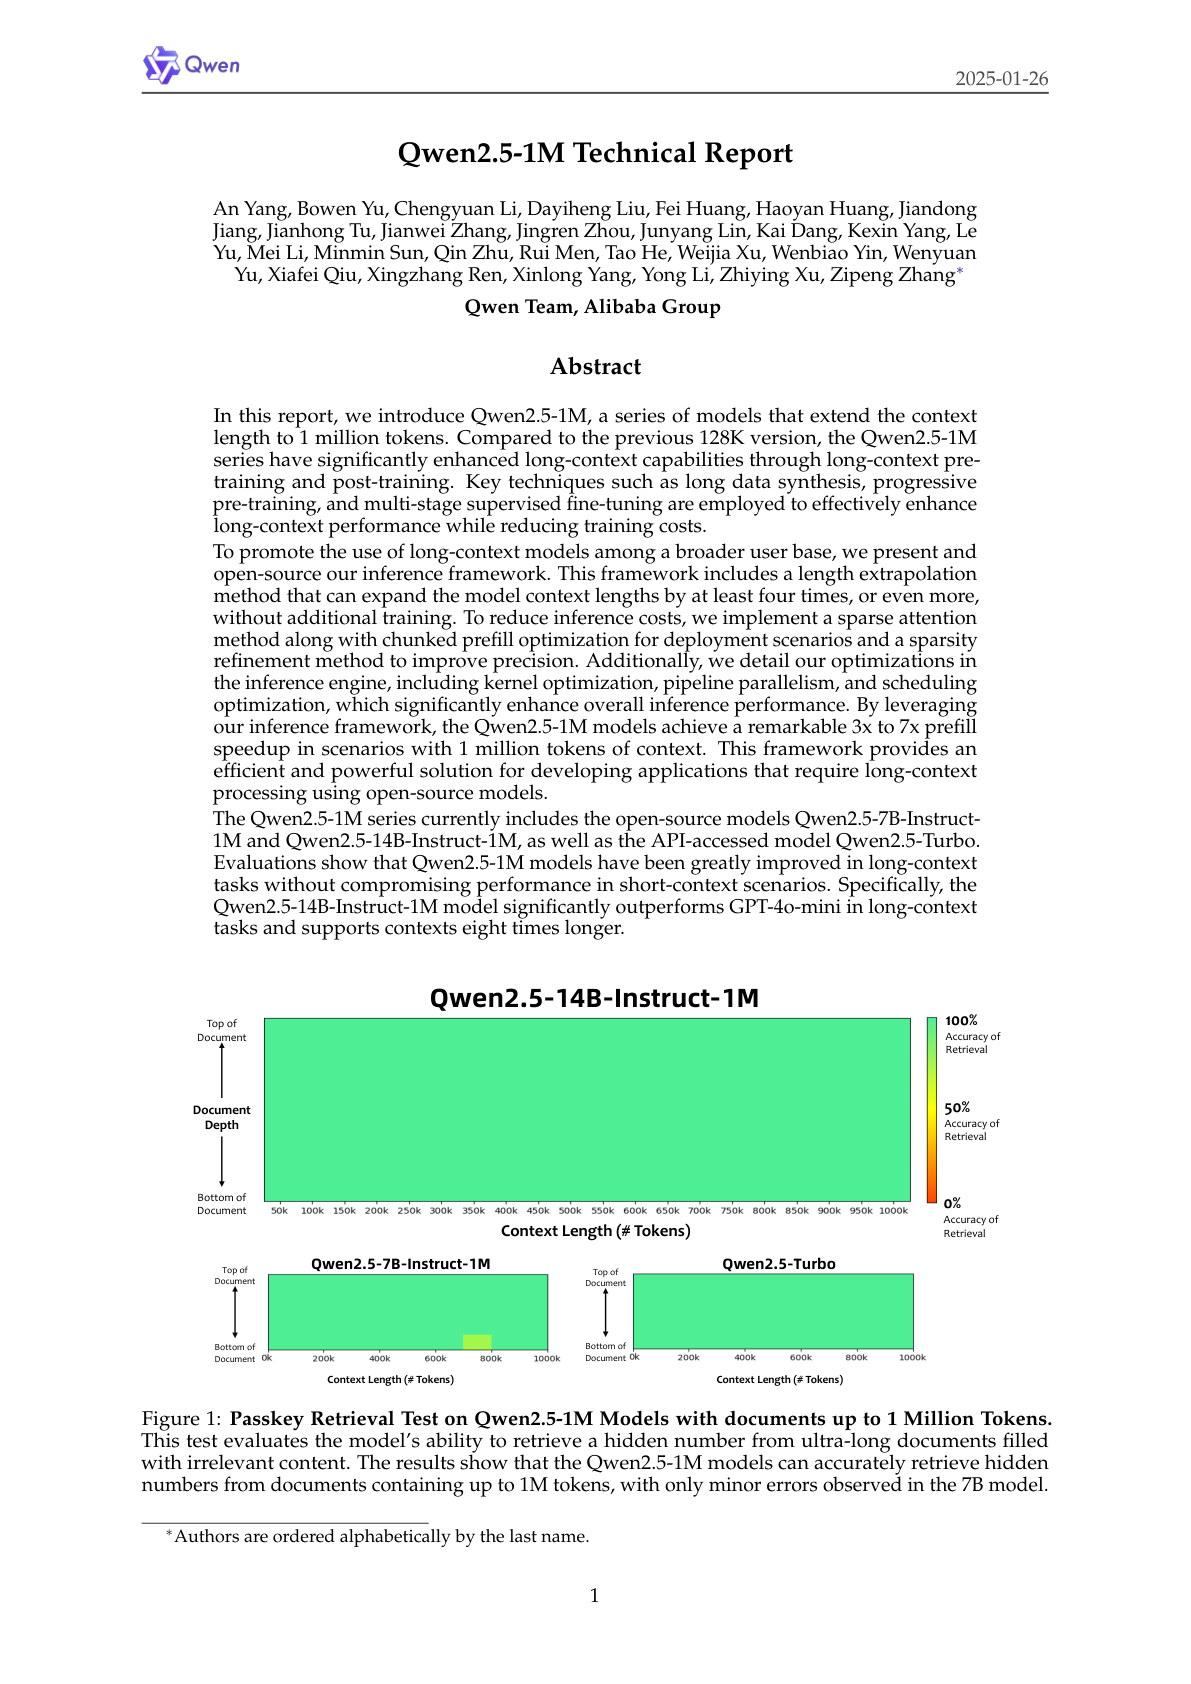
Paper summary
Qwen releases two open-source LLMs, Qwen2.5-7B-Instruct-1M and Qwen2.5-14B-Instruct-1M, that can handle context lengths of up to 1 million tokens. The models are built on a progressive training approach, starting with 4K tokens and gradually increasing to 256K tokens, then using length extrapolation techniques to reach 1M tokens. They've also released an inference framework based on vLLM that processes long inputs 3-7x faster through sparse attention methods. The models show strong performance on both long-context and short-text tasks. The 14B model outperforms GPT-4o-mini across multiple long-context datasets while maintaining similar performance on shorter tasks.