RankPrompt: Step-by-Step Comparisons Make LLMs Better Reasoners
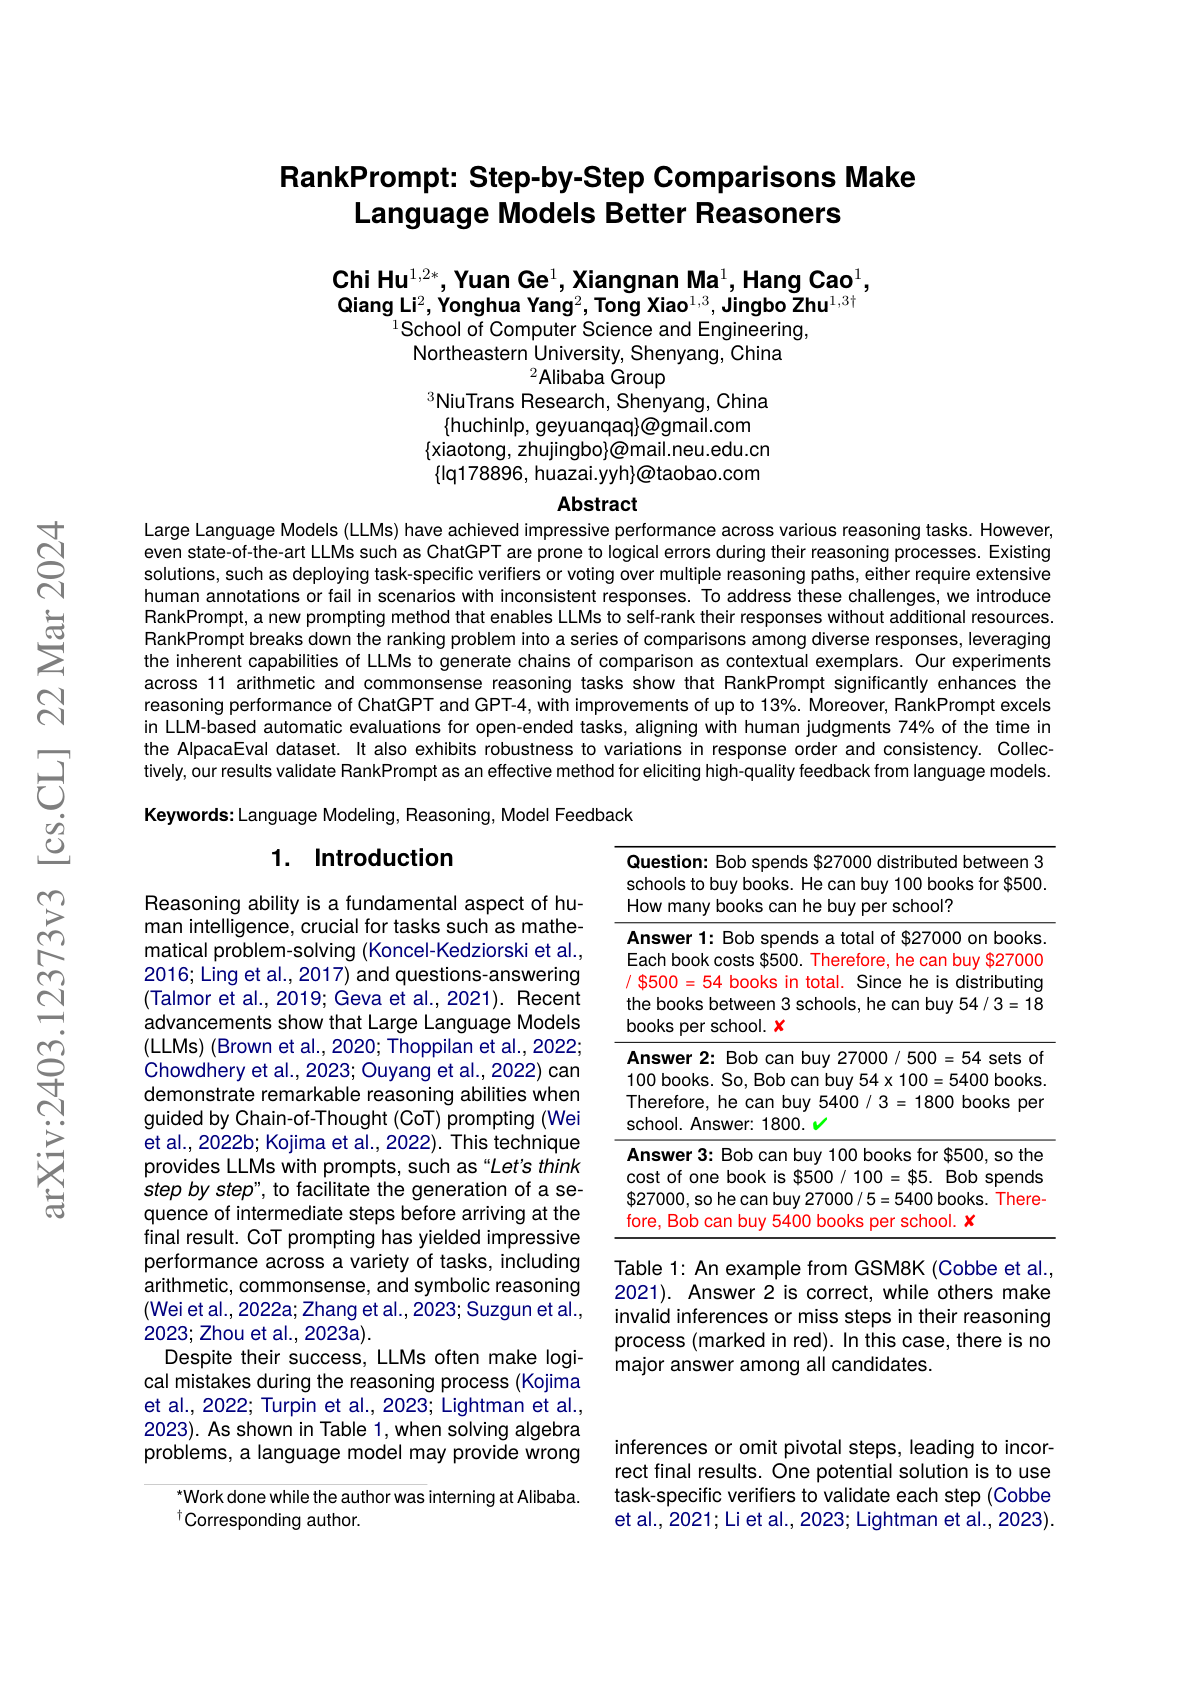
RankPrompt is a prompting method that lets an LLM self-rank its own candidate answers via chains of pairwise comparisons, without needing an external verifier or additional fine-tuning.
Ask this paper
Self-ranking via comparisons: Candidates are evaluated by having the LLM walk through systematic pairwise comparisons as in-context demonstrations, rather than scoring each answer independently.
11 benchmarks: Tested across 11 arithmetic and commonsense reasoning datasets, RankPrompt lifts ChatGPT and GPT-4 accuracy "by up to 13%" on the strongest cases.
Also works on open-ended tasks: On AlpacaEval-style open-ended evaluations, RankPrompt's ranking aligns with human judgments in 74% of cases, suggesting it generalizes beyond just closed-form reasoning.
Implication: Shows that LLMs can function as effective self-evaluators when guided to produce comparison chains, unlocking cheaper alternatives to external reward models for test-time selection.