ReFT (Reinforced Fine-Tuning)
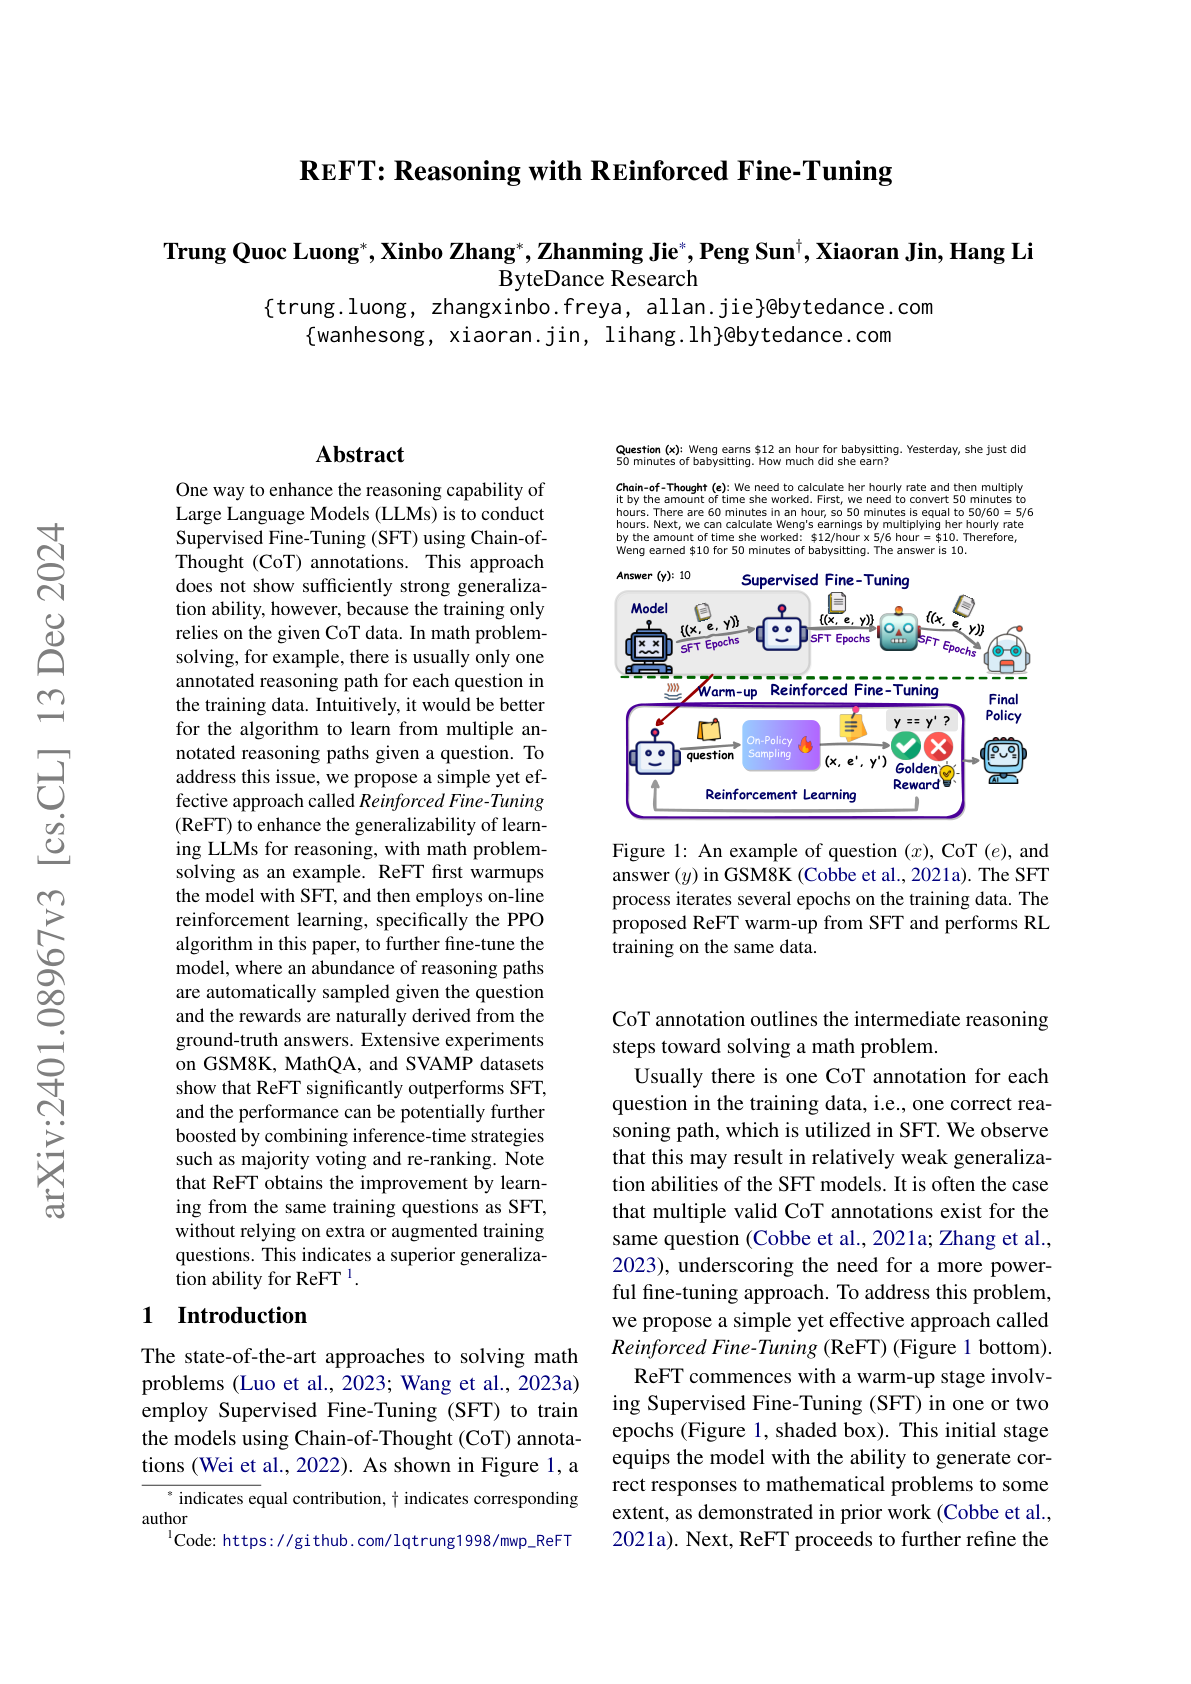
ByteDance's ReFT enhances LLM reasoning by combining supervised fine-tuning with online RL that samples alternative reasoning paths, without a learned reward model.
Ask this paper
Two-stage recipe: Standard SFT gives the model a reasonable starting policy; an online RL phase then refines it by sampling reasoning paths and rewarding those that yield correct final answers.
No reward model needed: Unlike RLHF, ReFT uses the ground-truth answer itself as the reward signal, avoiding the cost and instability of training a separate reward model.
Math problem-solving wins: Strong gains on GSM8K and MATH, with better out-of-distribution generalization than pure SFT at the same compute.
Simple conceptual lesson: The paper is an early demonstration that online RL from verifiable signals can outperform supervised recipes on reasoning - a theme that would dominate the subsequent year's research.