Reinventing RNNs for the Transformer Era (RWKV)
First page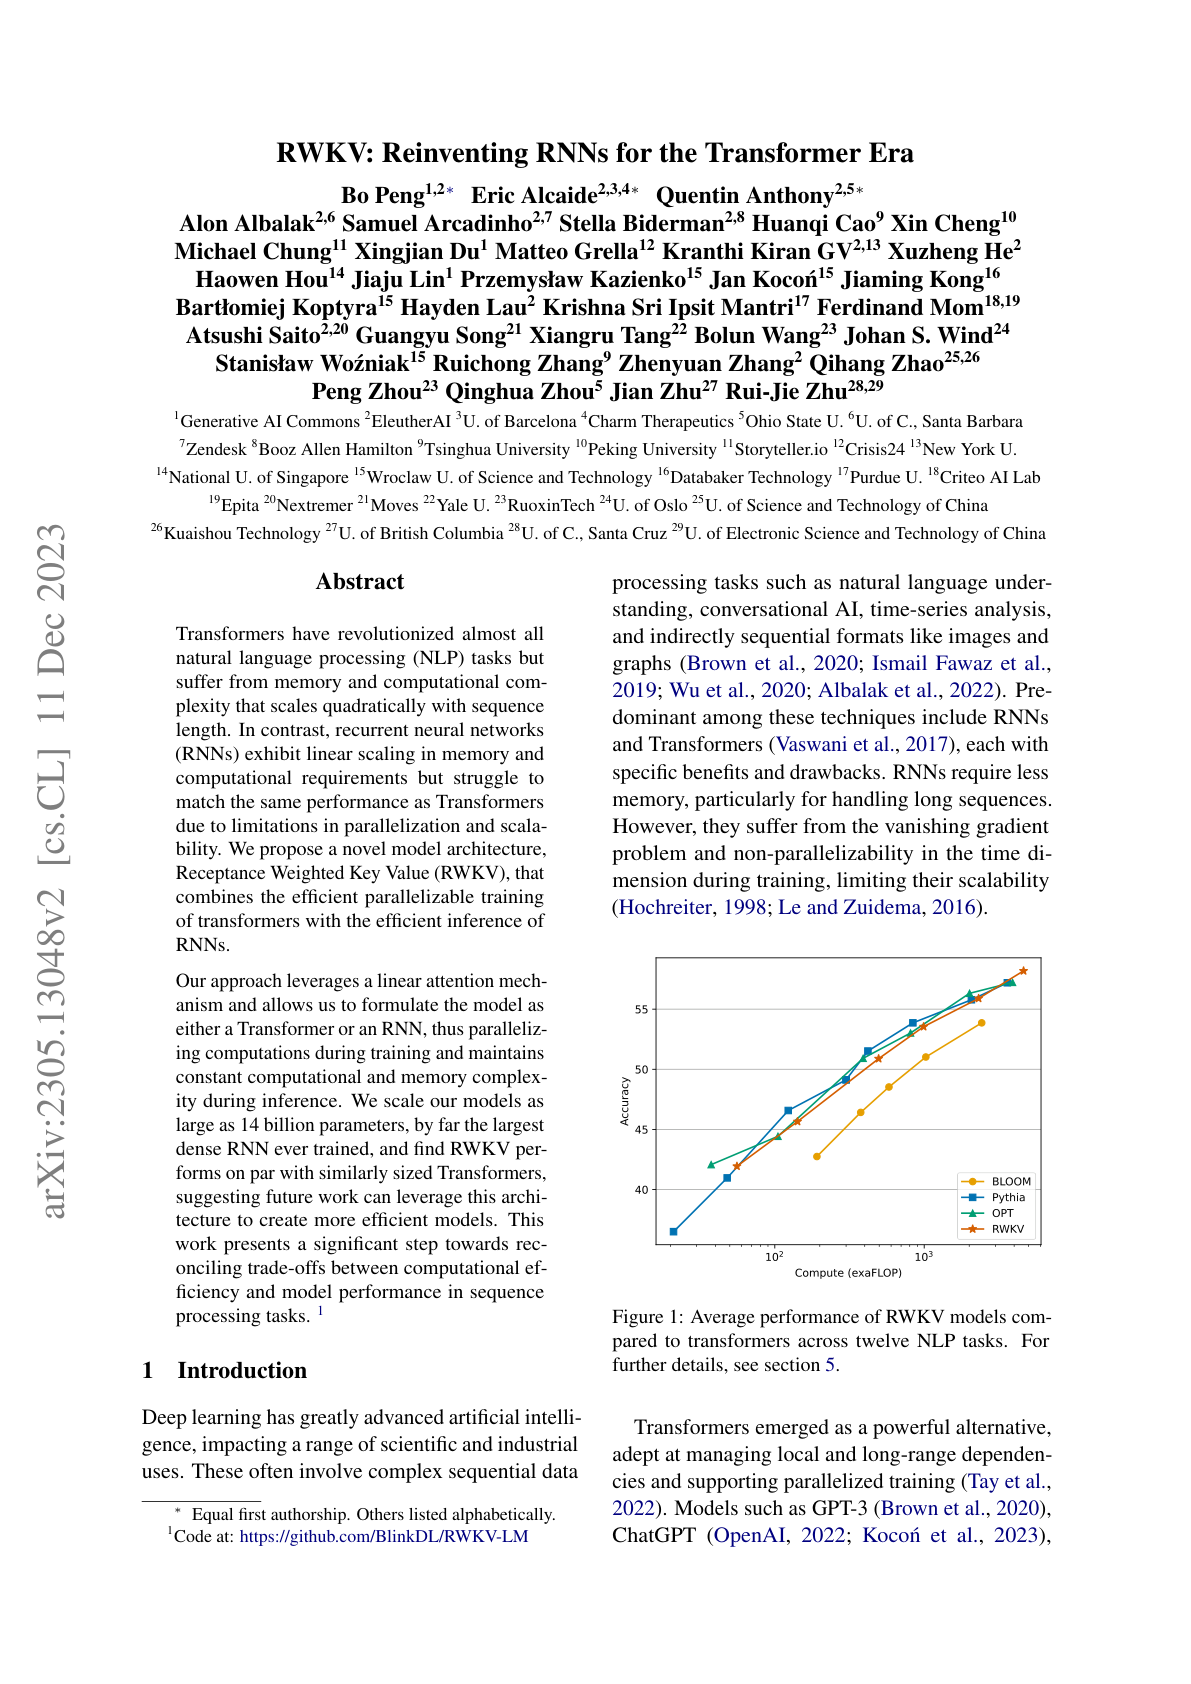
Paper summary
Combines parallelizable training of Transformers with efficient RNN inference.
Ask this paper
01
Hybrid design: Achieves Transformer-style parallelizable training with RNN-style O(1) inference memory - best of both worlds.
02
Transformer-parity performance: Matches similarly-sized Transformers on language modeling benchmarks while being dramatically cheaper at inference.
03
Open community: Developed as an open-community project with releases spanning multiple scales and substantial community fine-tuning.
04
Post-Transformer contender: Alongside Mamba and RetNet, positioned as one of the credible attempts to dethrone attention for efficient long-context inference.