ReST Meets ReAct
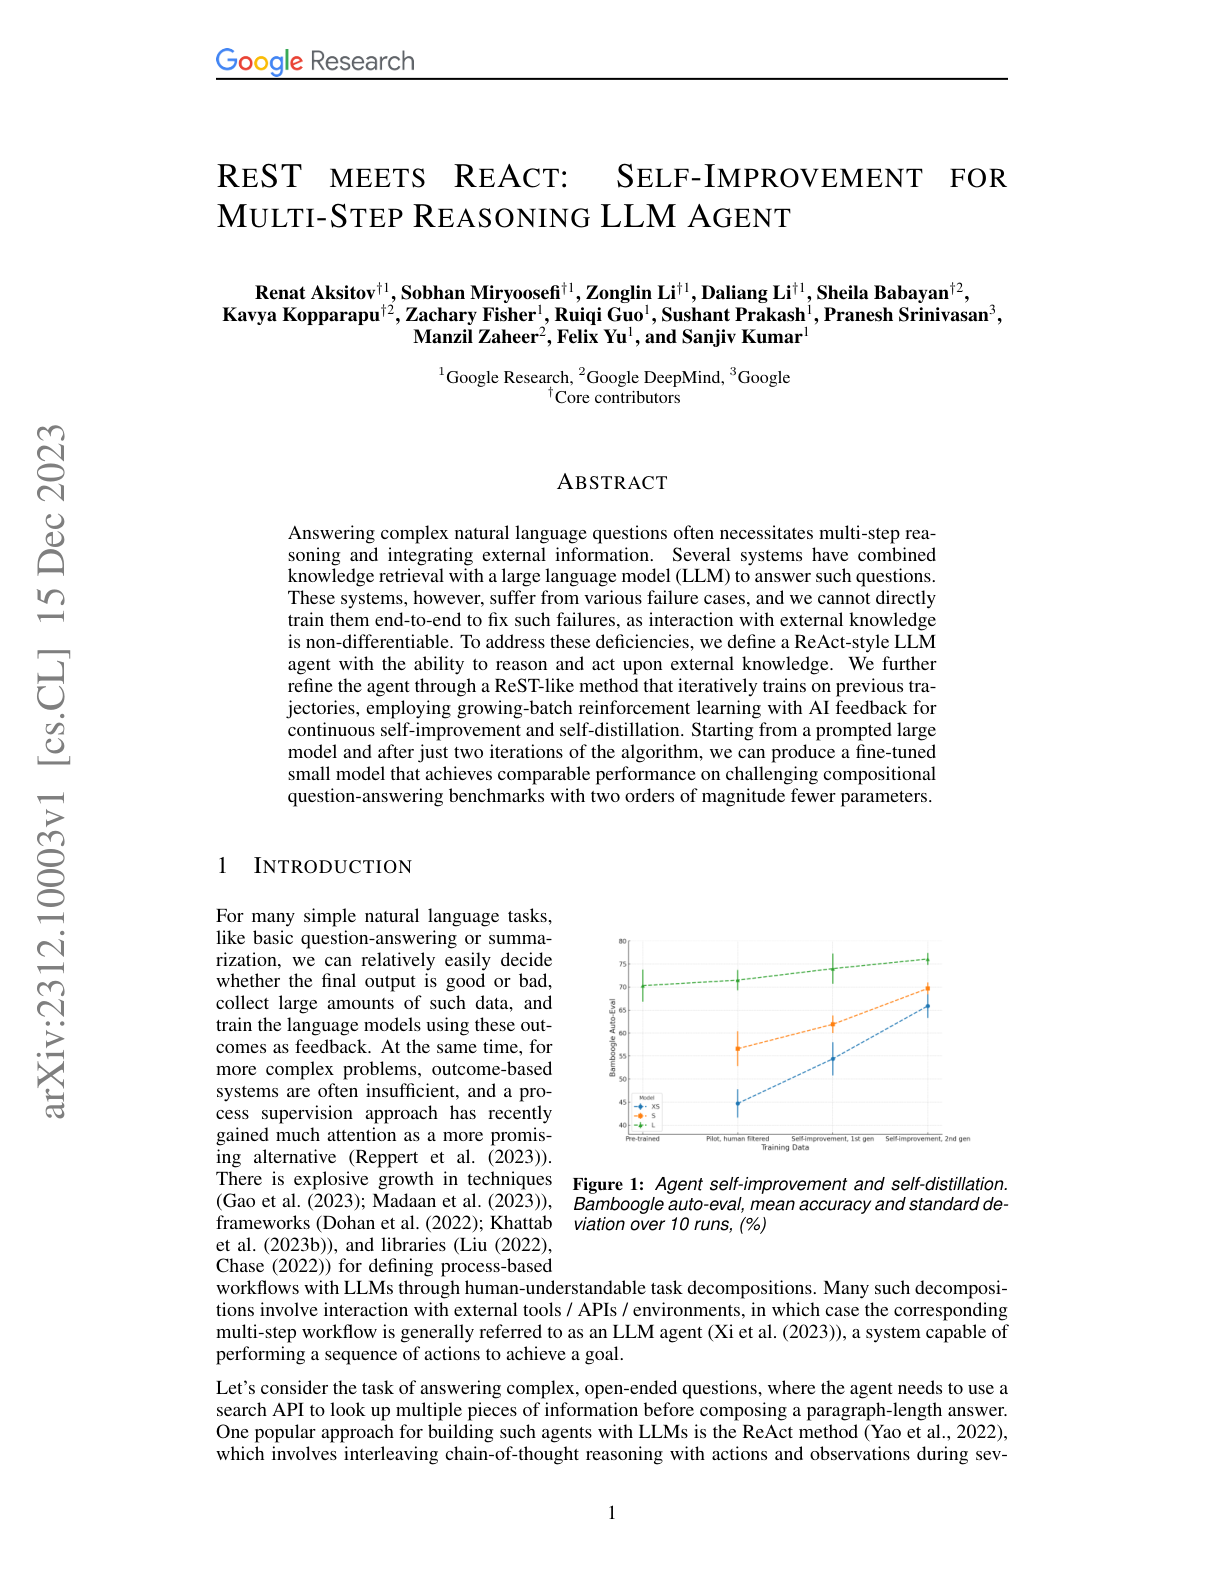
Proposes a ReAct-style agent that improves itself via reinforced self-training on its own reasoning traces.
Ask this paper
Self-critique ReAct: A ReAct-style agent with a self-critique step that evaluates its own reasoning and answers, generating a filterable trace dataset.
ReST-style iterative RL: Uses growing-batch RL from AI feedback to iteratively fine-tune on the agent's successful reasoning traces, improving over rounds without human labels.
Human-label-free: Minimizes human involvement; synthetic data with self-improvement from AI feedback is the primary training signal throughout.
Distillation to small models: The improved agent can be distilled into models 1-2 orders of magnitude smaller with comparable performance, dramatically cutting inference cost.