RetireOPD: Self-Retiring On-Policy Distillation for Agentic Reinforcement Learning
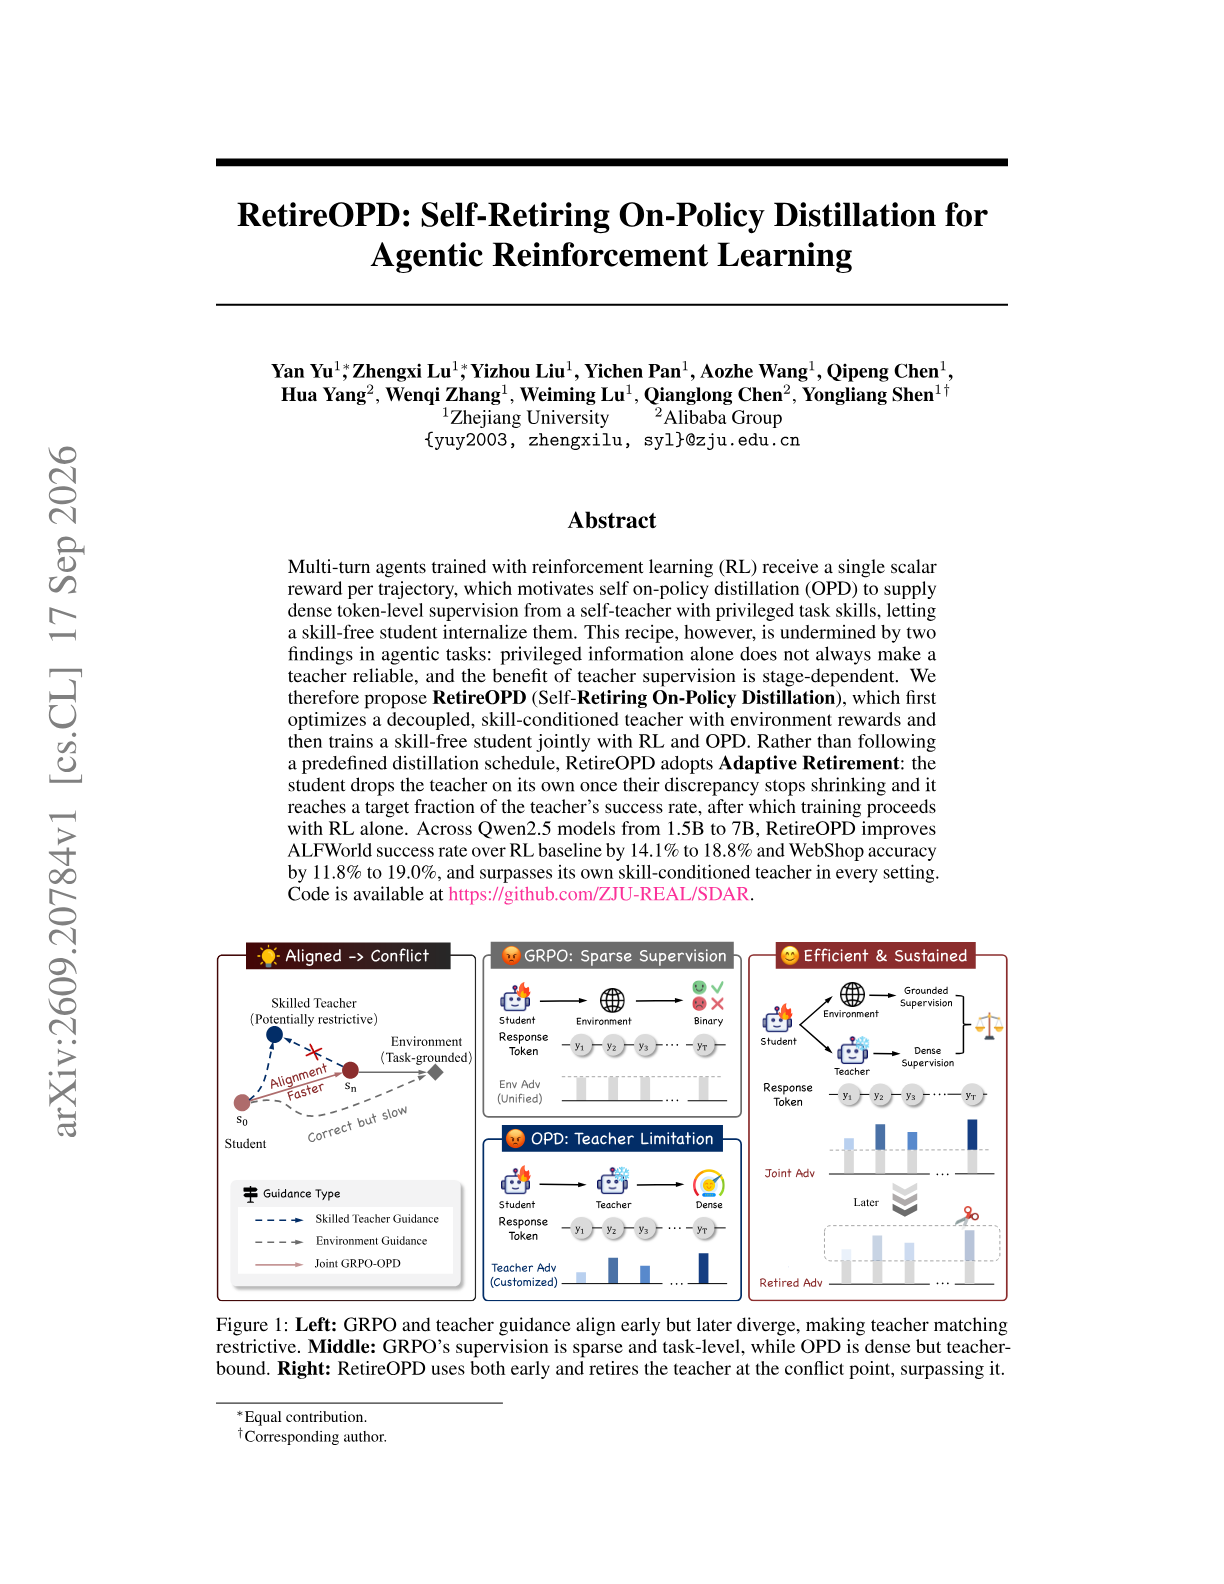
Yan Yu and colleagues find that a privileged teacher is not always reliable and that teacher supervision helps only at certain training stages, and propose RetireOPD, where the student drops the teacher on its own.
Ask this paper
Adaptive Retirement replaces a fixed schedule. The student stops distilling once the teacher-student discrepancy stops shrinking and it reaches a target fraction of the teacher's success rate, after which training continues with RL alone.
The teacher is trained separately first. A decoupled, skill-conditioned teacher is optimized with environment rewards before the skill-free student trains jointly with RL and on-policy distillation.
14.1 to 18.8 percent gain on ALFWorld. Over the RL baseline across Qwen2.5 models from 1.5B to 7B, and 11.8 to 19.0 percent on WebShop.
The student passes its own teacher. In every setting, which is the result that justifies retiring the teacher rather than distilling to convergence.
Abstract
Multi-turn agents trained with reinforcement learning (RL) receive a single scalar reward per trajectory, which motivates self on-policy distillation (OPD) to supply dense token-level supervision from a self-teacher with privileged task skills, letting a skill-free student internalize them. This recipe, however, is undermined by two findings in agentic tasks: privileged information alone does not always make a teacher reliable, and the benefit of teacher supervision is stage-dependent. We therefore propose RetireOPD (Self-Retiring On-Policy Distillation), which first optimizes a decoupled, skill-conditioned teacher with environment rewards and then trains a skill-free student jointly with RL and OPD. Rather than following a predefined distillation schedule, RetireOPD adopts Adaptive Retirement: the student drops the teacher on its own once their discrepancy stops shrinking and it reaches a target fraction of the teacher's success rate, after which training proceeds with RL alone. Across Qwen2.5 models from 1.5B to 7B, RetireOPD improves ALFWorld success rate over RL baseline by 14.1% to 18.8% and WebShop accuracy by 11.8% to 19.0%, and surpasses its own skill-conditioned teacher in every setting.