SkillLift: Learning Dense Rubrics from Sparse Oracles for Efficient Skill Evolution
Kang (independent) and Wen (Fudan University) propose SkillLift, which reduces the number of expensive agent rollouts needed to evolve reusable skill prompts by learning a rubric that ranks candidate skills in place of the rollout oracle.
Ask this paper
Bottleneck. Existing skill self-evolution methods need a full agent rollout to score each revision, which limits search to patching observed failures.
Ranking target. The authors argue that deciding which of two skills is better needs fewer oracle calls than predicting each skill's absolute score, so the rubric is trained for rank agreement.
Bilevel loop. An inner loop revises skills against the frozen rubric at no oracle cost; an outer loop spends a few real rollouts to re-align the rubric by rank correlation.
Result. On complex agent benchmarks SkillLift outperforms existing auto-skill methods while using 40 to 70% fewer tokens than frontier skill-evolution methods.
Abstract
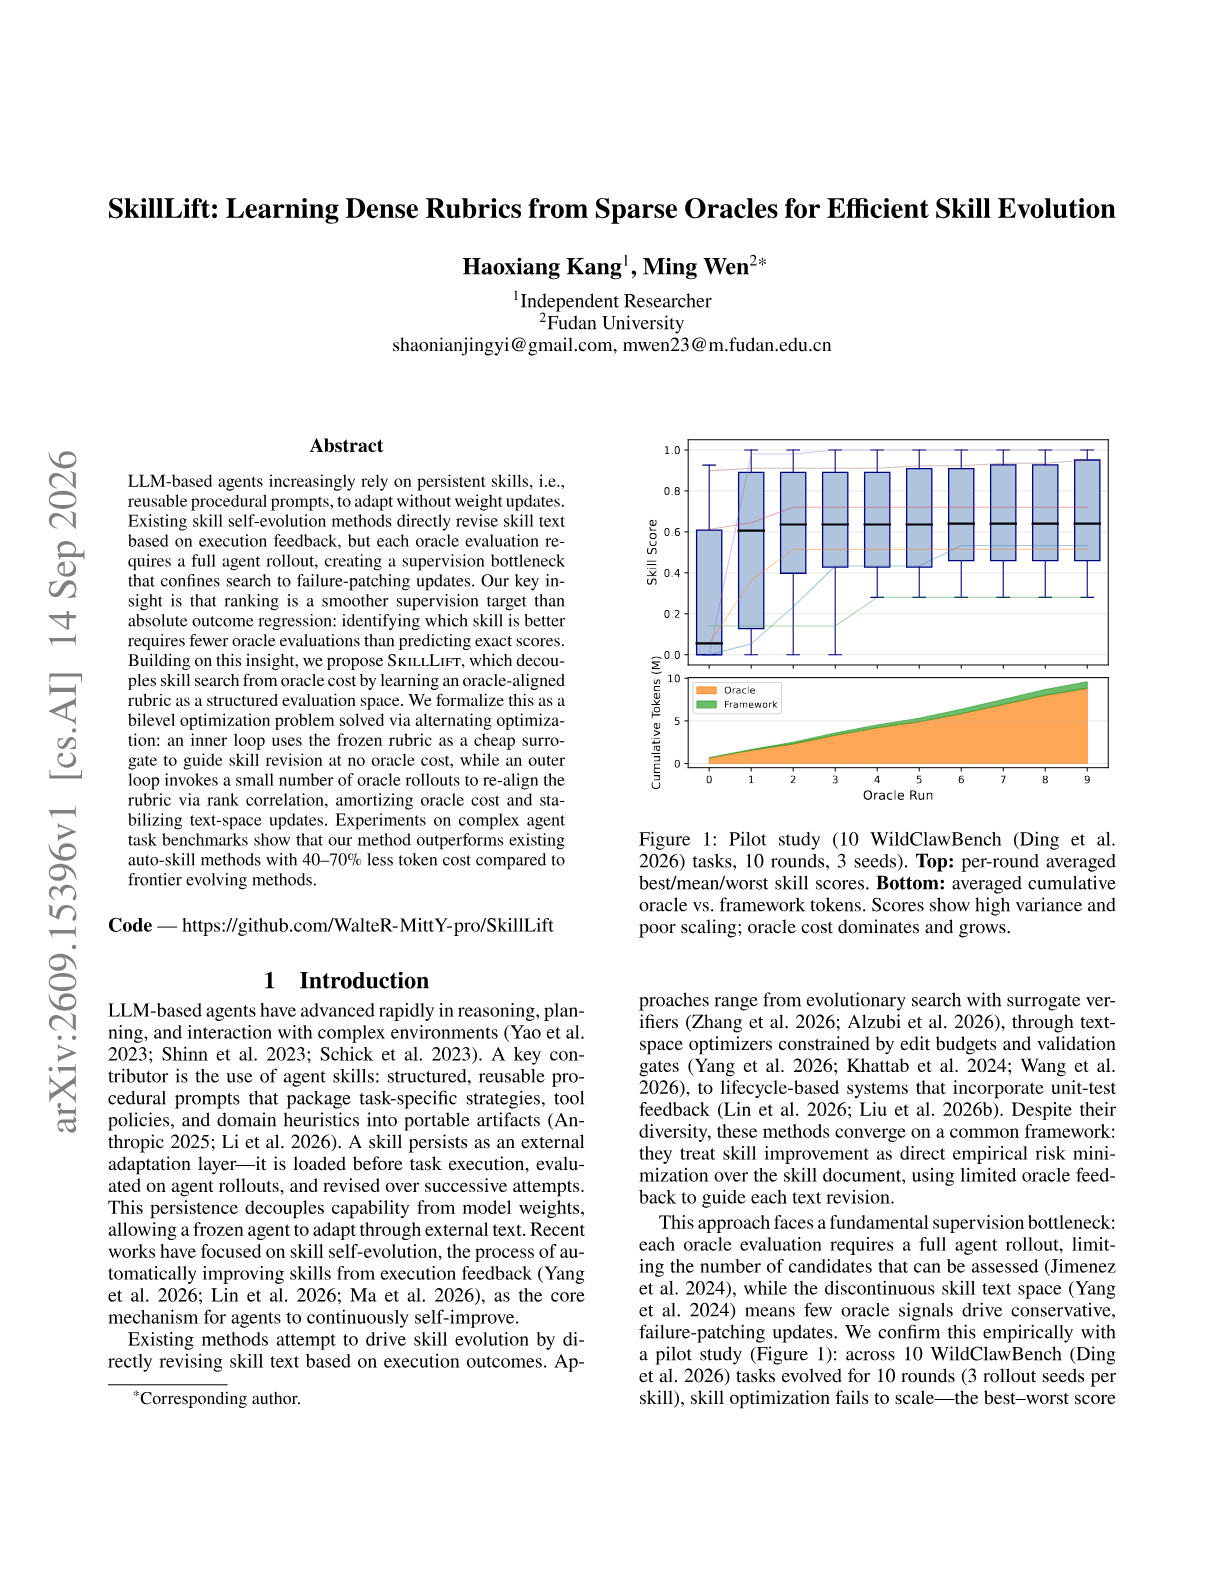
LLM-based agents increasingly rely on persistent skills, i.e., reusable procedural prompts, to adapt without weight updates. Existing skill self-evolution methods directly revise skill text based on execution feedback, but each oracle evaluation requires a full agent rollout, creating a supervision bottleneck that confines search to failure-patching updates. Our key insight is that ranking is a smoother supervision target than absolute outcome regression: identifying which skill is better requires fewer oracle evaluations than predicting exact scores. Building on this insight, we propose SkillLift, which decouples skill search from oracle cost by learning an oracle-aligned rubric as a structured evaluation space. We formalize this as a bilevel optimization problem solved via alternating optimization: an inner loop uses the frozen rubric as a cheap surrogate to guide skill revision at no oracle cost, while an outer loop invokes a small number of oracle rollouts to re-align the rubric via rank correlation, amortizing oracle cost and stabilizing text-space updates. Experiments on complex agent task benchmarks show that our method outperforms existing auto-skill methods with 40--70\% less token cost compared to frontier evolving methods. Codes are available at https://github.com/WalteR-MittY-pro/SkillLift.