SWE-Critix: Post-Training Generalist Verifiers for Assessing Coding-Agent Trajectories
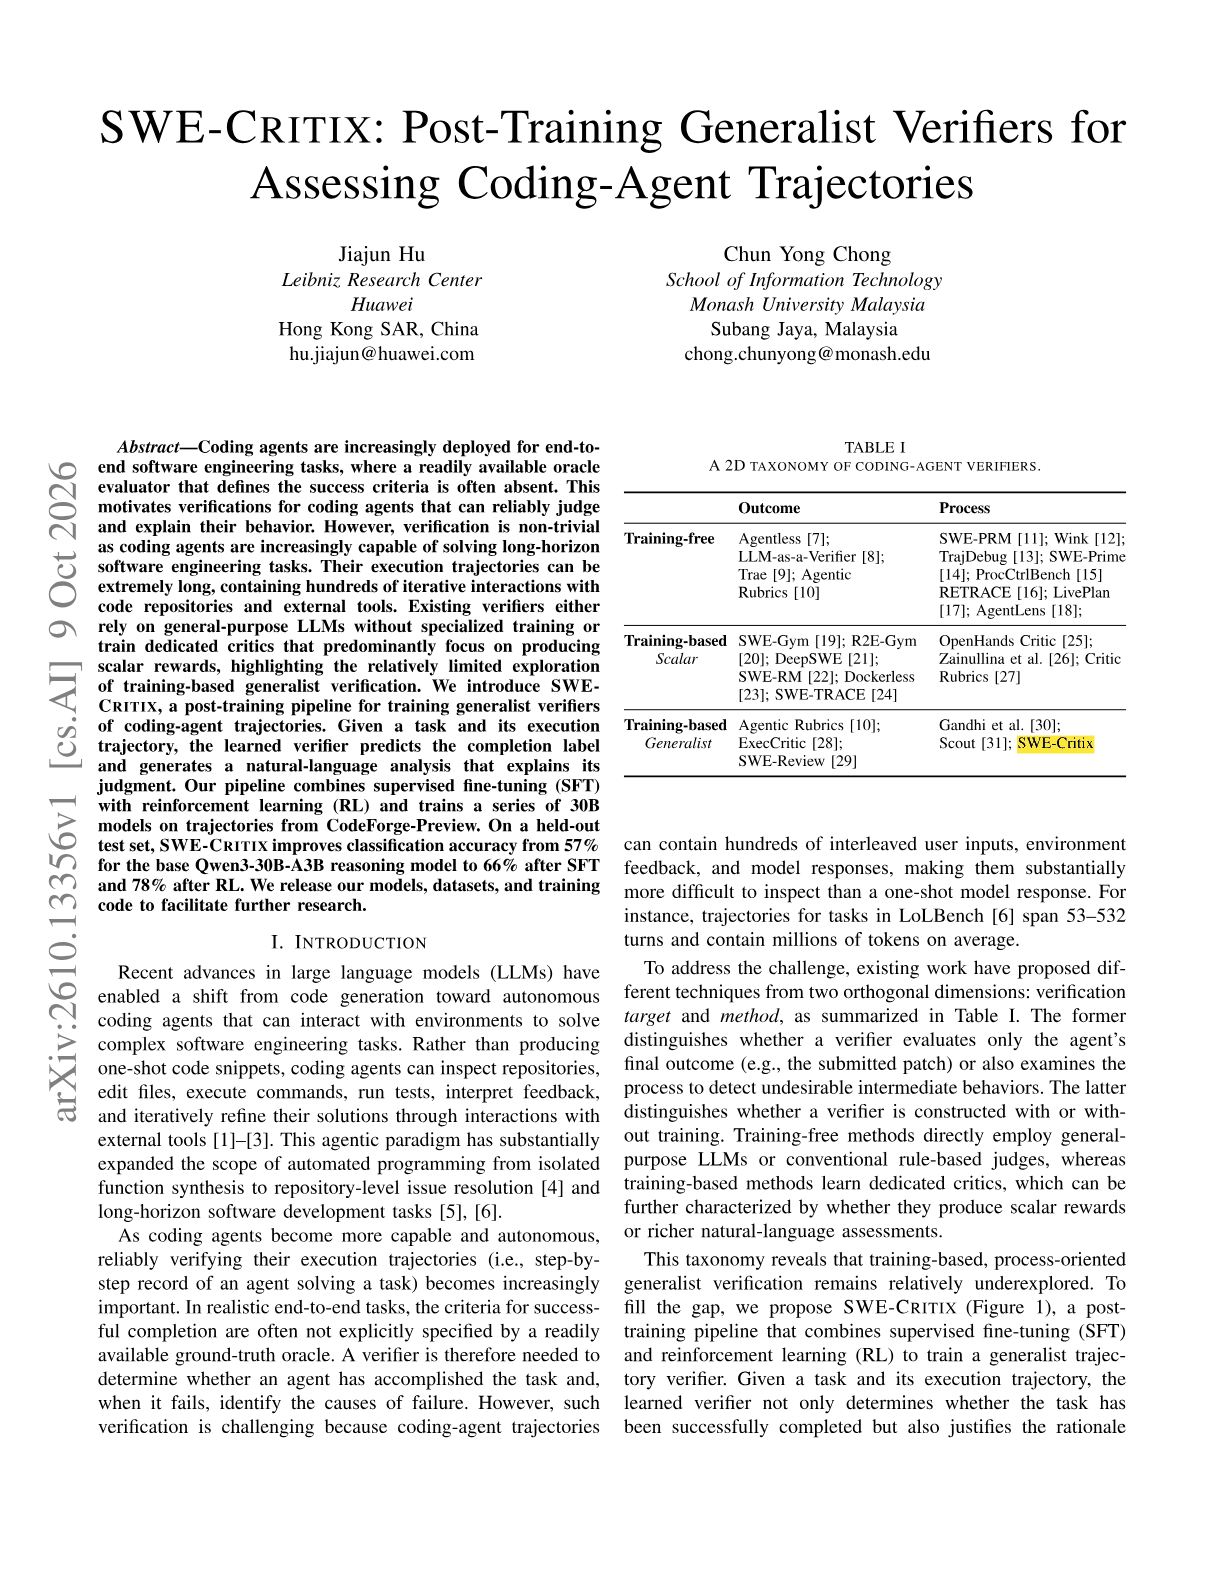
Jiajun Hu (Huawei Leibniz Research Center) and Chun Yong Chong (Monash University Malaysia) present SWE-Critix, a post-training pipeline that trains 30B verifiers to judge whether a coding-agent trajectory completed its task and to explain why.
Ask this paper
Problem. Many software tasks have no oracle test suite, and agent trajectories can contain hundreds of tool calls, so judging success needs a verifier that reads the whole trajectory.
Verifier output. Given a task and its trajectory, the model predicts a completion label and writes a natural-language analysis, in contrast to critics that return only a scalar reward.
Training. SFT on 10,390 chain-of-thought annotated trajectories, then RL, starting from Qwen3-30B-A3B and using trajectories from CodeForge-Preview.
Results. Held-out classification accuracy rises from 57% for the base model to 66% after SFT and 78% after RL. SFT mainly removes the base model strong bias toward predicting success; RL raises positive recall from 67% to 85%.
Remaining gap. Negative recall reaches only 64%, so the verifier still misses about a third of failed trajectories. Models, data and code are released.
Abstract
Coding agents are increasingly deployed for end-to-end software engineering tasks, where a readily available oracle evaluator that defines the success criteria is often absent. This motivates verifications for coding agents that can reliably judge and explain their behavior. However, verification is non-trivial as coding agents are increasingly capable of solving long-horizon software engineering tasks. Their execution trajectories can be extremely long, containing hundreds of iterative interactions with code repositories and external tools. Existing verifiers either rely on general-purpose LLMs without specialized training or train dedicated critics that predominantly focus on producing scalar rewards, highlighting the relatively limited exploration of training-based generalist verification. We introduce SWE-Critix, a post-training pipeline for training generalist verifiers of coding-agent trajectories. Given a task and its execution trajectory, the learned verifier predicts the completion label and generates a natural-language analysis that explains its judgment. Our pipeline combines supervised fine-tuning (SFT) with reinforcement learning (RL) and trains a series of 30B models on trajectories from CodeForge-Preview. On a held-out test set, SWE-Critix improves classification accuracy from 57% for the base Qwen3-30B-A3B reasoning model to 66% after SFT and 78% after RL. We release our models, datasets, and training code to facilitate further research.