The Hydra Effect
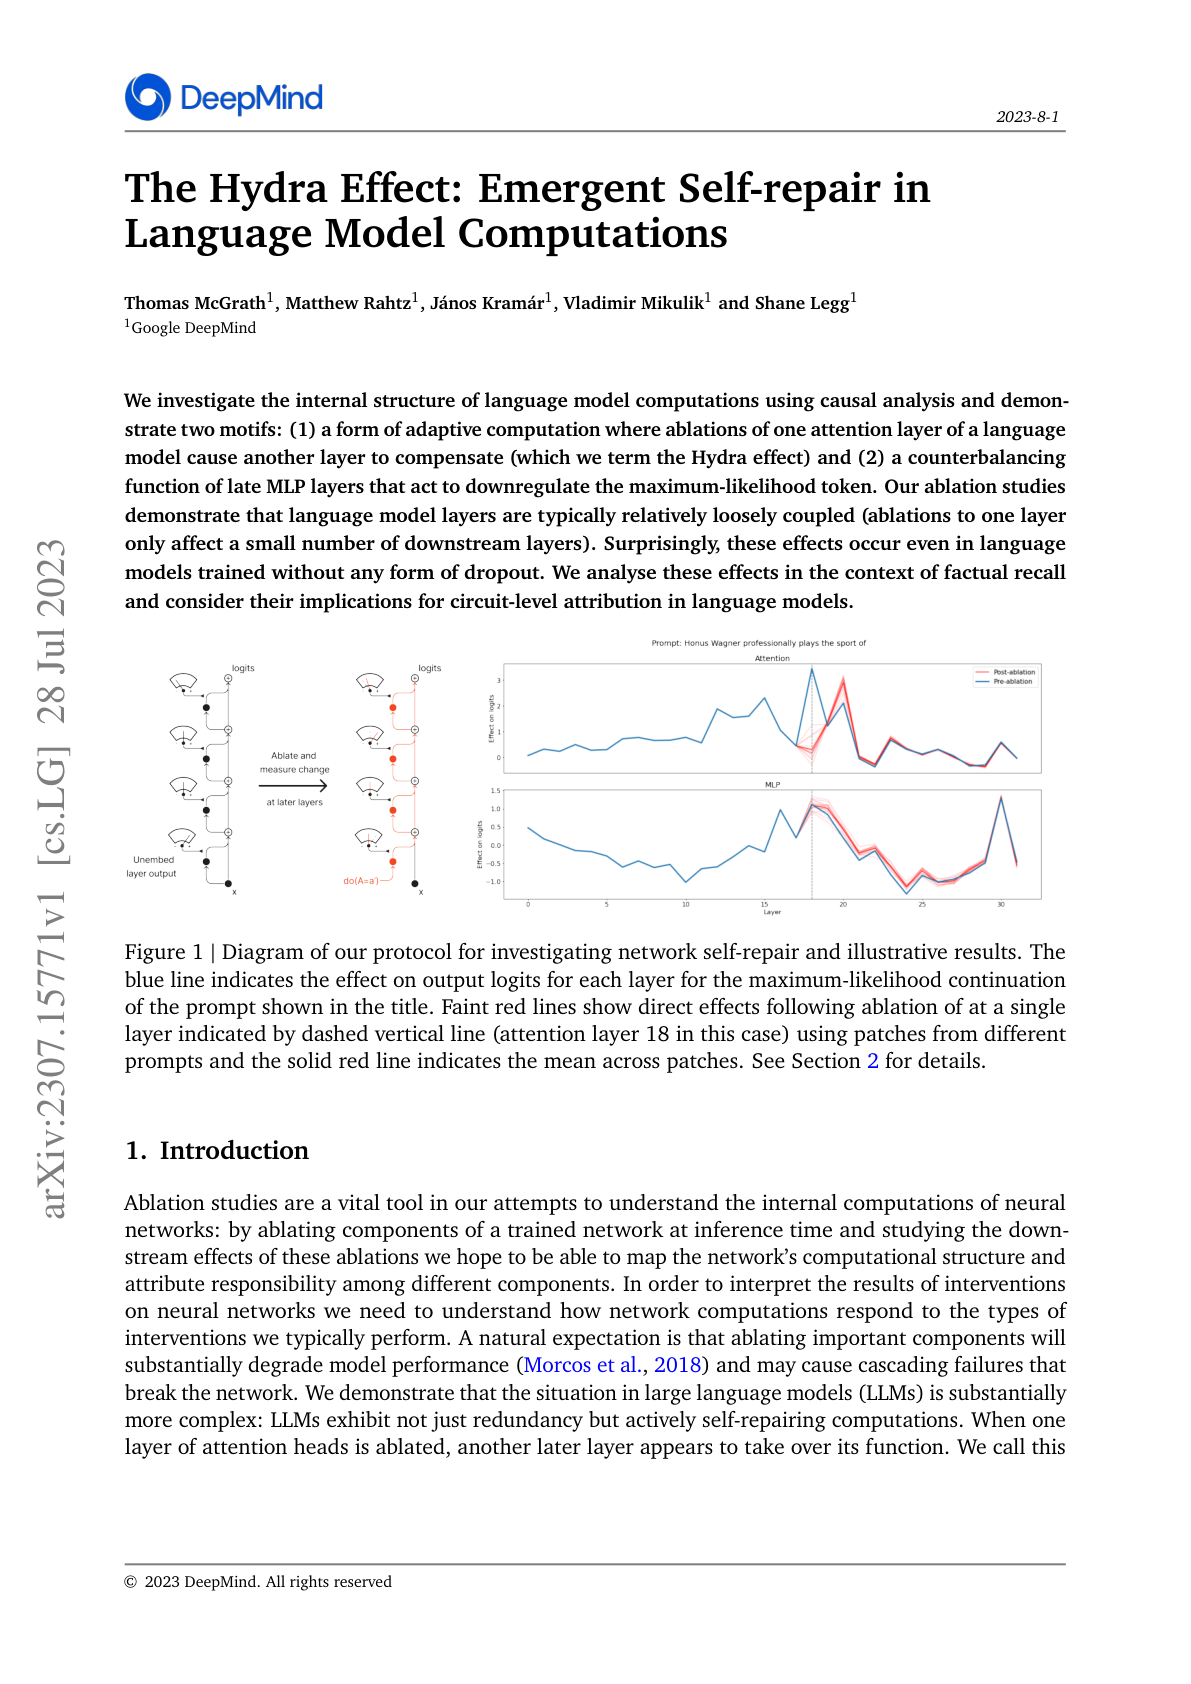
DeepMind shows that language models exhibit self-repairing behavior when attention heads are ablated.
Ask this paper
Self-repair phenomenon: Ablating a layer of attention heads causes a later layer to take over the ablated layer's function - a previously unknown redundancy property.
Interpretability implications: Complicates interpretability work based on ablation - removing a component doesn't necessarily isolate its contribution if other components compensate.
Circuit-level redundancy: Suggests transformer circuits have built-in redundancy that is activated under ablation, analogous to biological neural networks.
Research-method correction: Forces a rethinking of causal-mediation experiments in mechanistic interpretability, since ablations alone understate components' true contributions.